Repository navigation
feat: migrate to tanstack start and add all dashboard pages - #1
Merged
Merged
Conversation


steebchen
approved these changes
Apr 13, 2025


9 tasks
smakosh
added a commit
that referenced
this pull request
May 8, 2026

## Summary

- Adds a public `/apps` page that lists tools and coding agents using
LLM Gateway, ranked by tokens processed (similar to openrouter.ai/apps)
- Aggregation comes from a new public endpoint `GET /public/apps` that
groups `log.source` and sums `total_tokens`
- Seed data expanded with popular coding agents — Claude Code, Cursor,
Cline, Codex, OpenCode, Aider, Continue, Windsurf, Roo, Kilo, Zed, Bolt,
v0, Lovable, Autohand, SoulForge, OpenClaw, n8n — and log volume bumped
so the leaderboard has realistic ranks
- Page features a top-3 podium with blue-accented #1, a top-12 grid, a
table-style long-tail list, search + category filters, and a DevPass
upsell as the closing section

## Design notes

Aesthetic intentionally matches the existing landing-page DNA in
`apps/ui/src/components/landing/*`: `font-display` headlines,
`AnimatedGroup blur-slide` reveals, atmospheric blue radial blobs,
gradient hairline separators, single `ShimmerButton` primary CTA. No
purple-gradient AI-template tropes.

The DevPass upsell uses logo-stack social proof from the leaderboard
above (Claude Code, Cursor, Cline, OpenCode) and loss-aversion framing
("Stop juggling nine separate subscriptions") rather than generic
feature bullets.

## Test plan

- [ ] `pnpm run setup` to reseed; visit `http://localhost:3002/apps`
- [ ] Verify the top 3 podium shows the highest-volume seeded agents
- [ ] Verify the search box filters by display name and source slug
- [ ] Verify the category pills (All / Coding agents / Automation /
Other) filter correctly
- [ ] Verify the long-tail list collapses below the top 12
- [ ] Verify `GET /public/apps` returns aggregated stats without auth
- [ ] Verify `GET /public/apps?limit=5` respects the limit
- [ ] Verify the DevPass upsell links to https://devpass.llmgateway.io
- [ ] Verify dark mode looks correct (atmospheric glow, podium accent)

🤖 Generated with [Claude Code](https://claude.com/claude-code)

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Public "Apps" page with hero metrics (apps tracked, tokens processed,
requests routed), ISR, and "Read the docs" link.
* Searchable, category-filterable apps leaderboard with top-3 podium,
results grid, and ranked list.
* Public API endpoint providing aggregated app traffic metrics for the
UI.
* App metadata for richer app cards (names, descriptions, icons/links).
  * DevPass upsell hero with CTAs and example setup snippet.
* **Chores**
* Seed data expanded to generate richer, higher-volume demo activity for
public metrics.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Co-authored-by: Claude Opus 4.7 (1M context) <noreply@anthropic.com>
Co-authored-by: Luca Steeb (bot) <contact@luca-steeb.com>
This was referenced Jun 20, 2026
huangyingting
pushed a commit
to repomesh/llmgateway
that referenced
this pull request
Jun 28, 2026
## Why

Diagnosed why the **chat plans** offer (Starter $9 / Plus $19 / Pro $49,
shipped Jun 8) wasn't converting. Real data (PostHog, LLMGateway
project): **7 conversions in ~3 weeks — 4 Plus, 3 Starter, 0 Pro**
against ~106 monthly active playground users.

Running the value equation, the binding constraint was **perceived
likelihood**: the offer asked buyers to value abstract "credits / 2.5×
multiplier" with no proof, no guarantee, and use-it-or-lose-it expiry
framing. The funnel was also **blind** — chat pricing clicks and paywall
impressions weren't tracked, so there was no way to see *where* it
leaked.

## What changed

**Make the value believable (the theopenco#1 lever)**
- Translate each plan's credit allowance into concrete **"≈ N
messages"** on frontier and fast models, e.g. Plus ≈ 3,000 frontier /
9,000 fast; Pro ≈ 9,300 / 28,000. New `estimateChatPlanMessages()` in
`@llmgateway/shared`.
- Estimates are **conservative**: anchored to the priciest model in each
class (Claude Sonnet for frontier, Haiku for fast), so GPT-5 / Gemini /
Flash all yield *more* messages than shown — never overstated.
- Add a **"Replaces ~$60/mo of ChatGPT Plus + Claude Pro + Gemini"**
anchor on frontier tiers; lead the page/paywall copy with the dream
outcome instead of "credits."

**Risk reversal + expiry reframe**
- **7-day money-back guarantee** (refund if the plan is barely used —
conditioned to avoid credit arbitrage, since credits are worth more than
the price).
- Reframe credit expiry from "don't roll over" → **"your allowance
refills in full every cycle."**

**Sharpen the tier ladder**
- Starter copy is now **accurate**: it advertises the fast models it
actually allows (Claude Sonnet, Haiku, Gemini Flash) and no longer
claims GPT-5-mini, which is gated. Pro now has a tangible differentiator
— the message-count jump over Plus.

**Instrument the funnel**
- Fire `pricing_plan_clicked` with `app: "chat"` on CTA clicks (mirrors
the existing dev-plans event, so chat joins the same funnel).
- New `chat_pricing_viewed` event on pricing-page and paywall views
(`source` distinguishes them), making paywall impressions measurable for
the first time.

## Out of scope (flagged for a product decision)
- **Credit rollover** — reframed in copy, but the actual cycle-boundary
mechanic is a billing change left untouched.
- **Dropping / repricing tiers** — positioning only; no price or
entitlement changes.
- **Starter `gpt-5-mini` gating** — the blocked-pattern `"gpt-5"` also
blocks `gpt-5-mini`/`gpt-5-nano` by substring. Copy is now accurate;
whether to grant those cheap models to Starter is a product call.

## Testing
- `turbo run build --filter=playground` ✅ (builds `@llmgateway/shared`
first)
- `pnpm format` ✅ · pre-commit lint-staged ✅

🤖 Generated with [Claude Code](https://claude.com/claude-code)

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Refreshed pricing and paywall copy with clearer “one subscription”
positioning for frontier models.
  * Added “≈ messages/mo” allowances and updated plan coverage wording.
  * Introduced a visible 7-day money-back guarantee.

* **Analytics**
* Enhanced pricing-page and plan interaction tracking for viewing and
tier selection.

* **Bug Fixes**
* Updated “How it works” allowance language (fresh cycle/credit
behavior) and revised plan details to better match the current offering.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com>

steebchen
added a commit
that referenced
this pull request
Aug 2, 2026

Stacked on #3234 (follows #3370, which merged into the same base).

## Problem

The Provider Credentials page could not tell an operator that a
credential had burned through its spend cap and was no longer eligible
for selection:

- A key the billing worker auto-disabled rendered as a plain `inactive`
badge — indistinguishable from one an admin switched off by hand.
- Every row was numbered by its position in the list, so a shut-off key
read as `#1` in the rotation while the gateway was silently serving from
the one below it.
- There was no warning before a cap tripped, only after.
- Org BYOK provider keys showed no spend information at all.

## Changes

Spend-limit state is derived in one place
(`ee/admin/src/lib/provider-key-spend.ts`) and shared by the
managed-credentials page and the per-organization BYOK table:

- **`limit reached` badge** no longer requires the status flip to have
landed. Enforcement lags by one worker batch, and the key keeps serving
traffic in that window, so an over-cap key that is still active renders
as `limit reached · disabling` rather than a reassuring `active`.
- **Usage bar** with an amber tint from 80% of the cap, so a key
approaching its limit is visible before it trips.
- **Rotation positions count only selectable keys.** Provider-key
selection filters on `status = 'active'`, so out-of-rotation rows now
show `—` with an explanatory tooltip and a de-emphasised background
instead of a misleading rank.

## Verification

- `pnpm format`, `pnpm build` — clean.
- 62 tests pass across `provider-key-spend.spec.ts` (13 new, covering
the state machine including the lag window and a zero/malformed cap),
`provider-key-stats.spec.ts`, and `admin-provider-credentials.spec.ts`.
- Driven in a real browser against the dev stack with all four states
seeded (at-cap/inactive, 85% warning, over-cap/still-active, uncapped).
Confirmed the badges, tooltips, usage bars and rotation numbering render
as intended, and that the spend dialog reconciles: window total
`$14.5125` matched the database, split across `FinTech Global $10.75`
and `Test Organization $3.7625`. Both bucket granularities (hourly for
24h, daily for 7d) verified. Dev data restored afterwards.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Co-authored-by: Claude <noreply@anthropic.com>
Co-authored-by: AYOUB BENDARSI <137005356+RATCHAW@users.noreply.github.com>
smakosh
added a commit
that referenced
this pull request
Aug 8, 2026
Converts the changelog entry into a blog post -- this is SEO/
marketing content, not a release note for a shipped feature.

- new post at /blog/ai-gateway-benchmark, category Engineering,
  targeting "AI gateway benchmark"; adds an FAQ section and CTA
  block per the blog house style
- OG image regenerated with the top-left reserved and the real
  logo-with-name-white.svg composited in, per the blog skill
  (gpt-image-2 cannot draw the mark correctly)
- removes the changelog entry and its image

Carries over the verified framing: leads with the #1 result,
attributes it to tail latency rather than median speed, and keeps
the caveats -- one run, tightly packed field, public history of
lower placements. Still makes no causal claim for the week-over-
week move, and the new FAQ states outright that a gateway adds a
hop (our warm TTFT median is slower than the direct baseline).

Claude-Session: https://claude.ai/code/session_018n5hdRdydty6rdPEhzPdrb
steebchen
added a commit
that referenced
this pull request
Aug 13, 2026
## Problem

The [computesdk AI-gateway
benchmark](https://github.com/computesdk/benchmarks/actions/runs/31716766465)
(2026-08-13) dropped LLM Gateway from #1 (90.84, Aug 7) to #4 (88.80).
The regression is entirely in cold-start probes: 3 of 10 stalled at
1.1–1.3s inside the gateway→provider hop while the remaining probes ran
~620ms, with edge DNS/TCP/TLS all under 10ms.

A stall of that size is not a handshake. TCP+TLS to a provider's anycast
edge is two round trips — measured at ~10ms against `api.anthropic.com`
from a nearby vantage, and tens of ms at worst. 1.1s is a DNS
retransmit: in-cluster an uncached lookup goes through `ndots:5` search
expansion, where a single dropped UDP packet stalls for seconds.

The dispatcher already caches DNS, but at a 30s TTL the entry expires
between requests on a quiet pod, so an idle pod pays resolution again on
its next request — exactly the cold-start case the probes measure.

## Approach

- Default `UPSTREAM_DNS_CACHE_TTL_MS` 30s → 300s. Provider hostnames
resolve to CDN/anycast addresses that are stable over minutes, and a
connect failure on a stale address is already retried by provider
fallback, so a long TTL is safe while a short one only puts DNS back on
the TTFT path.
- Plumb `upstreamDnsCacheTtlMs` and `upstreamKeepaliveTimeoutMs` through
the Helm chart. Neither was settable without a code edit before; both
stay unset in `values.yaml` so the code defaults apply, following the
existing `terminationGracePeriodSeconds` pattern.

This is the reduced form of #3595. That PR paired the TTL bump with a
prewarm pinger that HEAD-pings provider origins to hold a pooled
connection open. Measured against undici 8.9.0 with the same Agent
config, every `HEAD` to both configured origins is answered `Connection:
close`, so the ping opens a connection and has it torn down immediately
— it cannot keep anything pooled:

```
HEAD https://api.openai.com/               421  connection=close       6 connects / 3 req   pooled=NO
GET  https://api.openai.com/               421  connection=keep-alive  2 connects / 3 req   pooled=NO
HEAD https://api.openai.com/v1/models      401  connection=close       3 connects / 3 req   pooled=NO
GET  https://api.openai.com/v1/models      401  connection=keep-alive  2 connects / 3 req   pooled=NO
HEAD https://api.anthropic.com/            404  connection=close       3 connects / 3 req   pooled=NO
GET  https://api.anthropic.com/            404  connection=keep-alive  1 connect  / 3 req   pooled=YES
HEAD https://api.anthropic.com/v1/messages 405  connection=close       3 connects / 3 req   pooled=NO
GET  https://api.anthropic.com/v1/messages 405  connection=keep-alive  1 connect  / 3 req   pooled=YES
```

It is the method, not the path. Since the stall being chased is DNS
rather than connection setup, the TTL change is the part that addresses
it; a corrected pinger (`GET`, and preserving the configured path, which
`new URL(x).origin` currently strips) can be revisited separately if
connection setup turns out to matter.

## Verification

- `pnpm vitest run apps/gateway/src/lib/upstream-dispatcher.spec.ts` —
3/3 passing
- `helm template` with `gateway.config.upstreamDnsCacheTtlMs=600000`
emits the var; with defaults it emits nothing
- `pnpm build` — 17/17 tasks pass

🤖 Generated with [Claude Code](https://claude.com/claude-code)

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->

## Summary by CodeRabbit

* **New Features**
* Added configurable upstream DNS cache TTL and keep-alive timeout
settings for gateway deployments.
* Deployment configuration can now override the default upstream
connection behavior.

* **Improvements**
* Increased the default upstream DNS cache duration from 30 seconds to
300 seconds.
* DNS caching remains disabled when explicitly configured with a
zero-second TTL.

<!-- end of auto-generated comment: release notes by coderabbit.ai -->

Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
SeyedHashtag
pushed a commit
to SeyedHashtag/llmgateway
that referenced
this pull request
Aug 15, 2026
## Problem

The July traffic report showed revenue concentrating in two places we
under-serve:

1. **The DevPass dashboard is the theopenco#1 converting surface** (354 payers
last month), and Reset Passes sold 42 units in month one with zero
targeting — but the agreed follow-up from theopenco#3093 (a real cap-hit
analytics event) never shipped, and the dashboard shows the same
ResetPassCard at 0% and 100% usage. No contextual offer exists at the
moment of highest intent.
2. **Compliance content converts payers at ~5%** (soc2-type-ii: 158
readers → 8 payers) but enterprise leads are flat at 4/month — the post
never presents the enterprise path. Meanwhile the weekly report shows
organic momentum fading, with the proven "[X] alternatives" and Kimi K3
playbooks sitting unshipped.

## What this ships

### DevPass: cap-hit funnel + contextual offer

- **`devpass_premium_cap_rejected`** captured server-side in the gateway
when the weekly premium-cap 402 fires
(`assertDevPlanPremiumCapNotExceeded`), with `devPlan`, `model`,
`msUntilReset`, and org group. This is the follow-up agreed in theopenco#3093:
`devpass_weekly_cap_hit_viewed` only counts users who open the
dashboard, but most cap hits happen inside coding agents that swallow
the 402 — demand was undercounted. Adds a `posthog-node` client to
`apps/gateway` (mirrors `apps/api/src/posthog.ts`; disabled without env,
no hot-path cost).
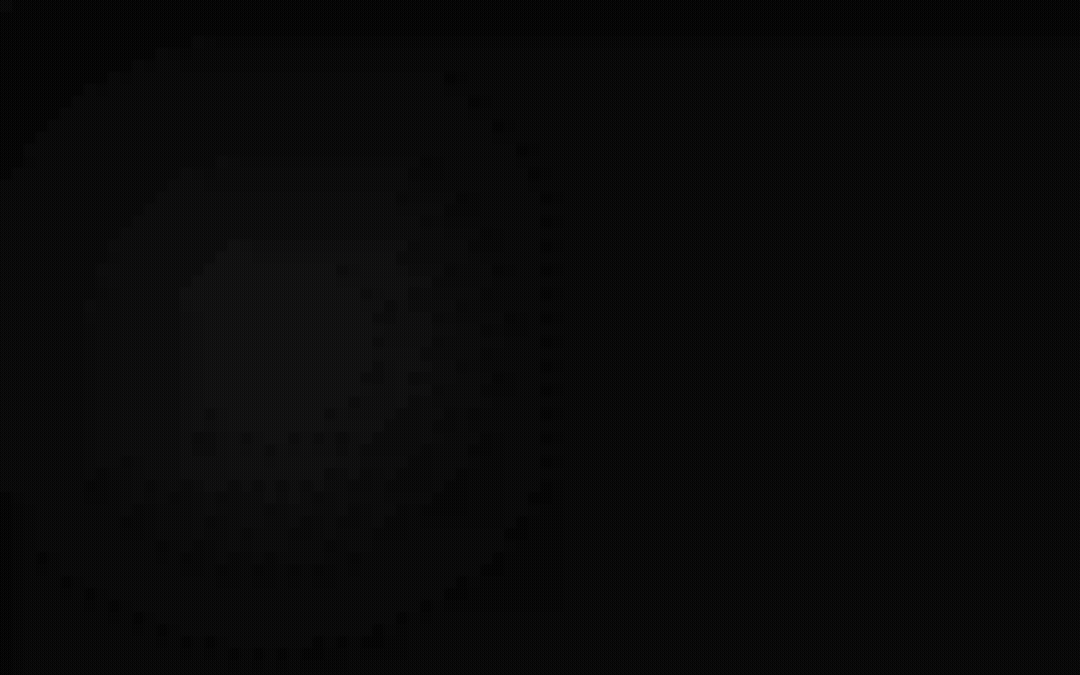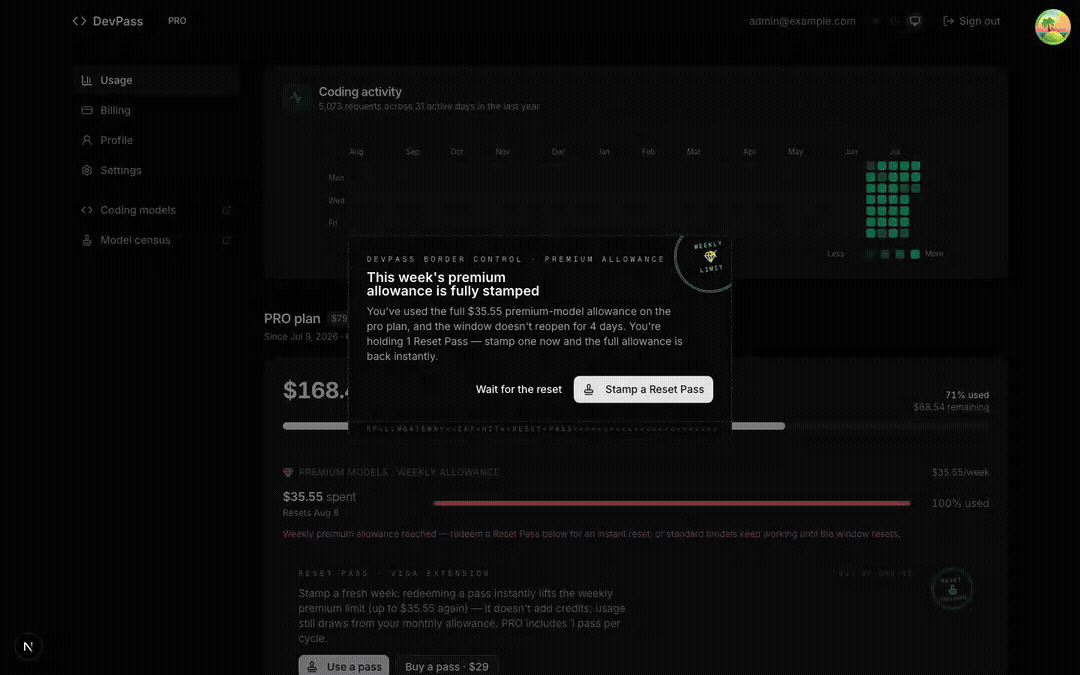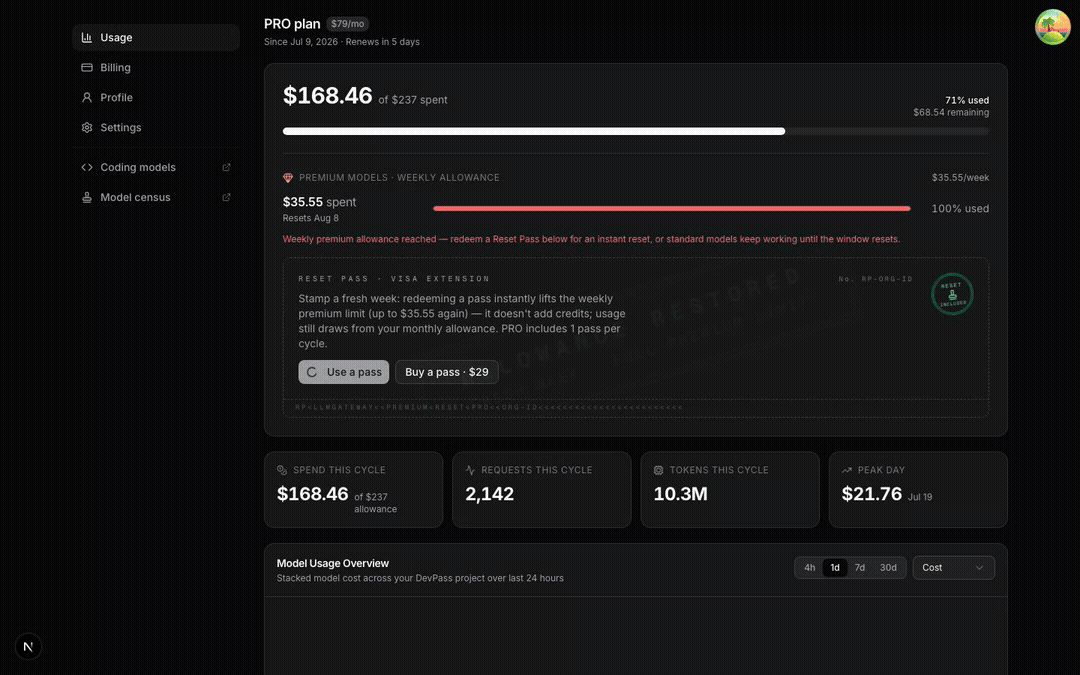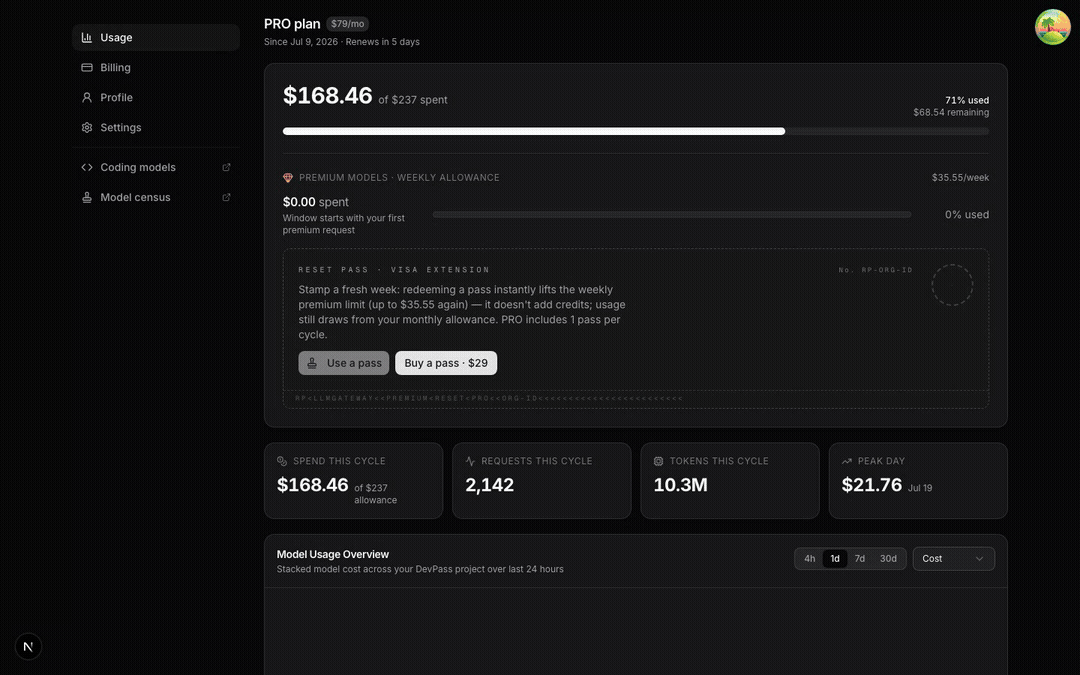
- **`CapHitResetOfferDialog`** on the DevPass dashboard: a visa-stamp
dialog (border-control stamp, MRZ strip — house DevPass brand) that
appears the moment the weekly premium cap is hit, driven by the existing
5s status poll. It mirrors the server's purchase/redeem gates (never
offers an action the API would 400), stays quiet when the monthly pool
is exhausted (that state belongs to `AllowanceExhaustedCard`), snoozes
per cap-window via cookie, and emits
`devpass_cap_hit_offer_shown/dismissed/clicked`. The CTA scrolls to the
ResetPassCard rather than duplicating the purchase surface.
- **`/ingest` PostHog proxy for `apps/code`** (mirroring apps/ui and
apps/playground) — DevPass dashboard events were ad-blocker-droppable
until now, so July's 500 cap-hit views were an undercount. Expect an
event step-up after deploy.

<img width="1080" alt="Cap-hit Reset Pass offer demo: dialog appears at
100% weekly usage, CTA scrolls to the ResetPassCard, redeem restores the
allowance"
src="https://raw.githubusercontent.com/theopenco/llmgateway/cc22b375431e6148e4889e403c4635327095fc0c/cap-hit-reset-pass-demo.gif"
/>

([MP4
version](https://raw.githubusercontent.com/theopenco/llmgateway/cc22b375431e6148e4889e403c4635327095fc0c/cap-hit-reset-pass-demo.mp4))

### Compliance/enterprise content cluster

- `soc2-type-ii` gains a **provider compliance policies** section (the
theopenco#3339 policy-aware picker, fail-closed requirements, 403-before-egress),
a proper enterprise CTA block, and links into the new cluster.
- Three sibling posts feeding the same funnel: **`llm-data-retention`**,
**`gdpr-compliant-llm-routing`**, and **`llm-compliance-checklist`** —
all fact-checked against
`apps/docs/content/features/{data-retention,compliance}.mdx` and the
routing docs (region example uses a real catalogue mapping,
`aws-bedrock/claude-sonnet-4-6:eu-west-2`).
- New **`BlogCta variant="enterprise"`** (→ `/enterprise#contact` +
`/enterprise/compliance`) used by all three.

### Organic pipeline refill

- **`portkey-alternatives`** and **`helicone-alternatives`** listicles —
the two SERP gaps left open after the litellm/openrouter/copilot
listicles proved the pattern. Facts per the verified June-2026
competitor landscape (Portkey→Palo Alto/Prisma AIRS; Helicone→Mintlify
maintenance mode; Langfuse/LangSmith claims re-verified this week).
Internal links added from `/compare/portkey`, the vs-Portkey post,
best-ai-gateways, and both existing listicles' "skip" sections.
- **Kimi K3 spokes**: `kimi-k3-open-weights` (weights shipped Jul 26 on
HF under a custom **"Kimi K3 License"** — not the Modified MIT press
predicted, so the post and pillar deliberately point at the LICENSE file
instead of summarizing terms) and `kimi-k3-api` (the "kimi k3 api"
query; reasoning_effort semantics, cached-input economics, sticky
sessions). Pillar updated: weights-release facts corrected, spokes
interlinked.
- **`/rankings` interlinks** from the `/models` SEO copy and `llms.txt`
(it had no entry there).
- 7 OG images generated in the house circuit-board style with the
composited wordmark.

## Verification

- `pnpm format`, full `pnpm build`, and `dev-plans-reset-passes.spec.ts`
(32/32) pass.
- Demo recorded against the local stack with the real seed org: staged
cap-hit via SQL (millisecond-truncated `dev_plan_premium_week_start` for
the CAS), dialog fired, CTA scrolled to the card, redeem zeroed
`devPlanPremiumCreditsUsed` and consumed the included pass server-side.

## Notes for review / follow-ups

- The census dialog and the new cap-hit dialog can theoretically stack
(both Radix dialogs; census mounts globally, cap-hit on the main
dashboard page). In the wild both firing together should be rare; if we
care, a simple priority gate in `DashboardShell` would fix it.
- The premium-cap 402 still has no machine-readable `code`
distinguishing it from out-of-credits — agents can't react
programmatically. Left out deliberately (error-shape compatibility);
worth its own PR.
- Blog listicles ship FAQ sections but blog posts emit no FAQPage
JSON-LD (model pages do). Separate SEO follow-up.
- dev.to syndication for the new listicles is intentionally not part of
this PR (staggering per the syndication policy).

🤖 Generated with [Claude Code](https://claude.com/claude-code)

https://claude.ai/code/session_018NeUff4XEsqAVuJRZ8KuvS

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

- **New Features**
- Added a dashboard offer for eligible users who exhaust weekly premium
usage, including reset-pass redemption and purchase options.
- Added links to live model rankings and expanded enterprise compliance
calls to action.
- Added guidance for Kimi K3, GDPR-compliant routing, LLM compliance,
data retention, and gateway alternatives.

- **Documentation**
- Updated model, compliance, licensing, and comparison content with new
articles, refreshed links, and recommendations.

- **Bug Fixes**
- Improved analytics loading, routing reliability, and shutdown
handling.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Co-authored-by: Luca Steeb <contact@luca-steeb.com>
SeyedHashtag
pushed a commit
to SeyedHashtag/llmgateway
that referenced
this pull request
Aug 15, 2026
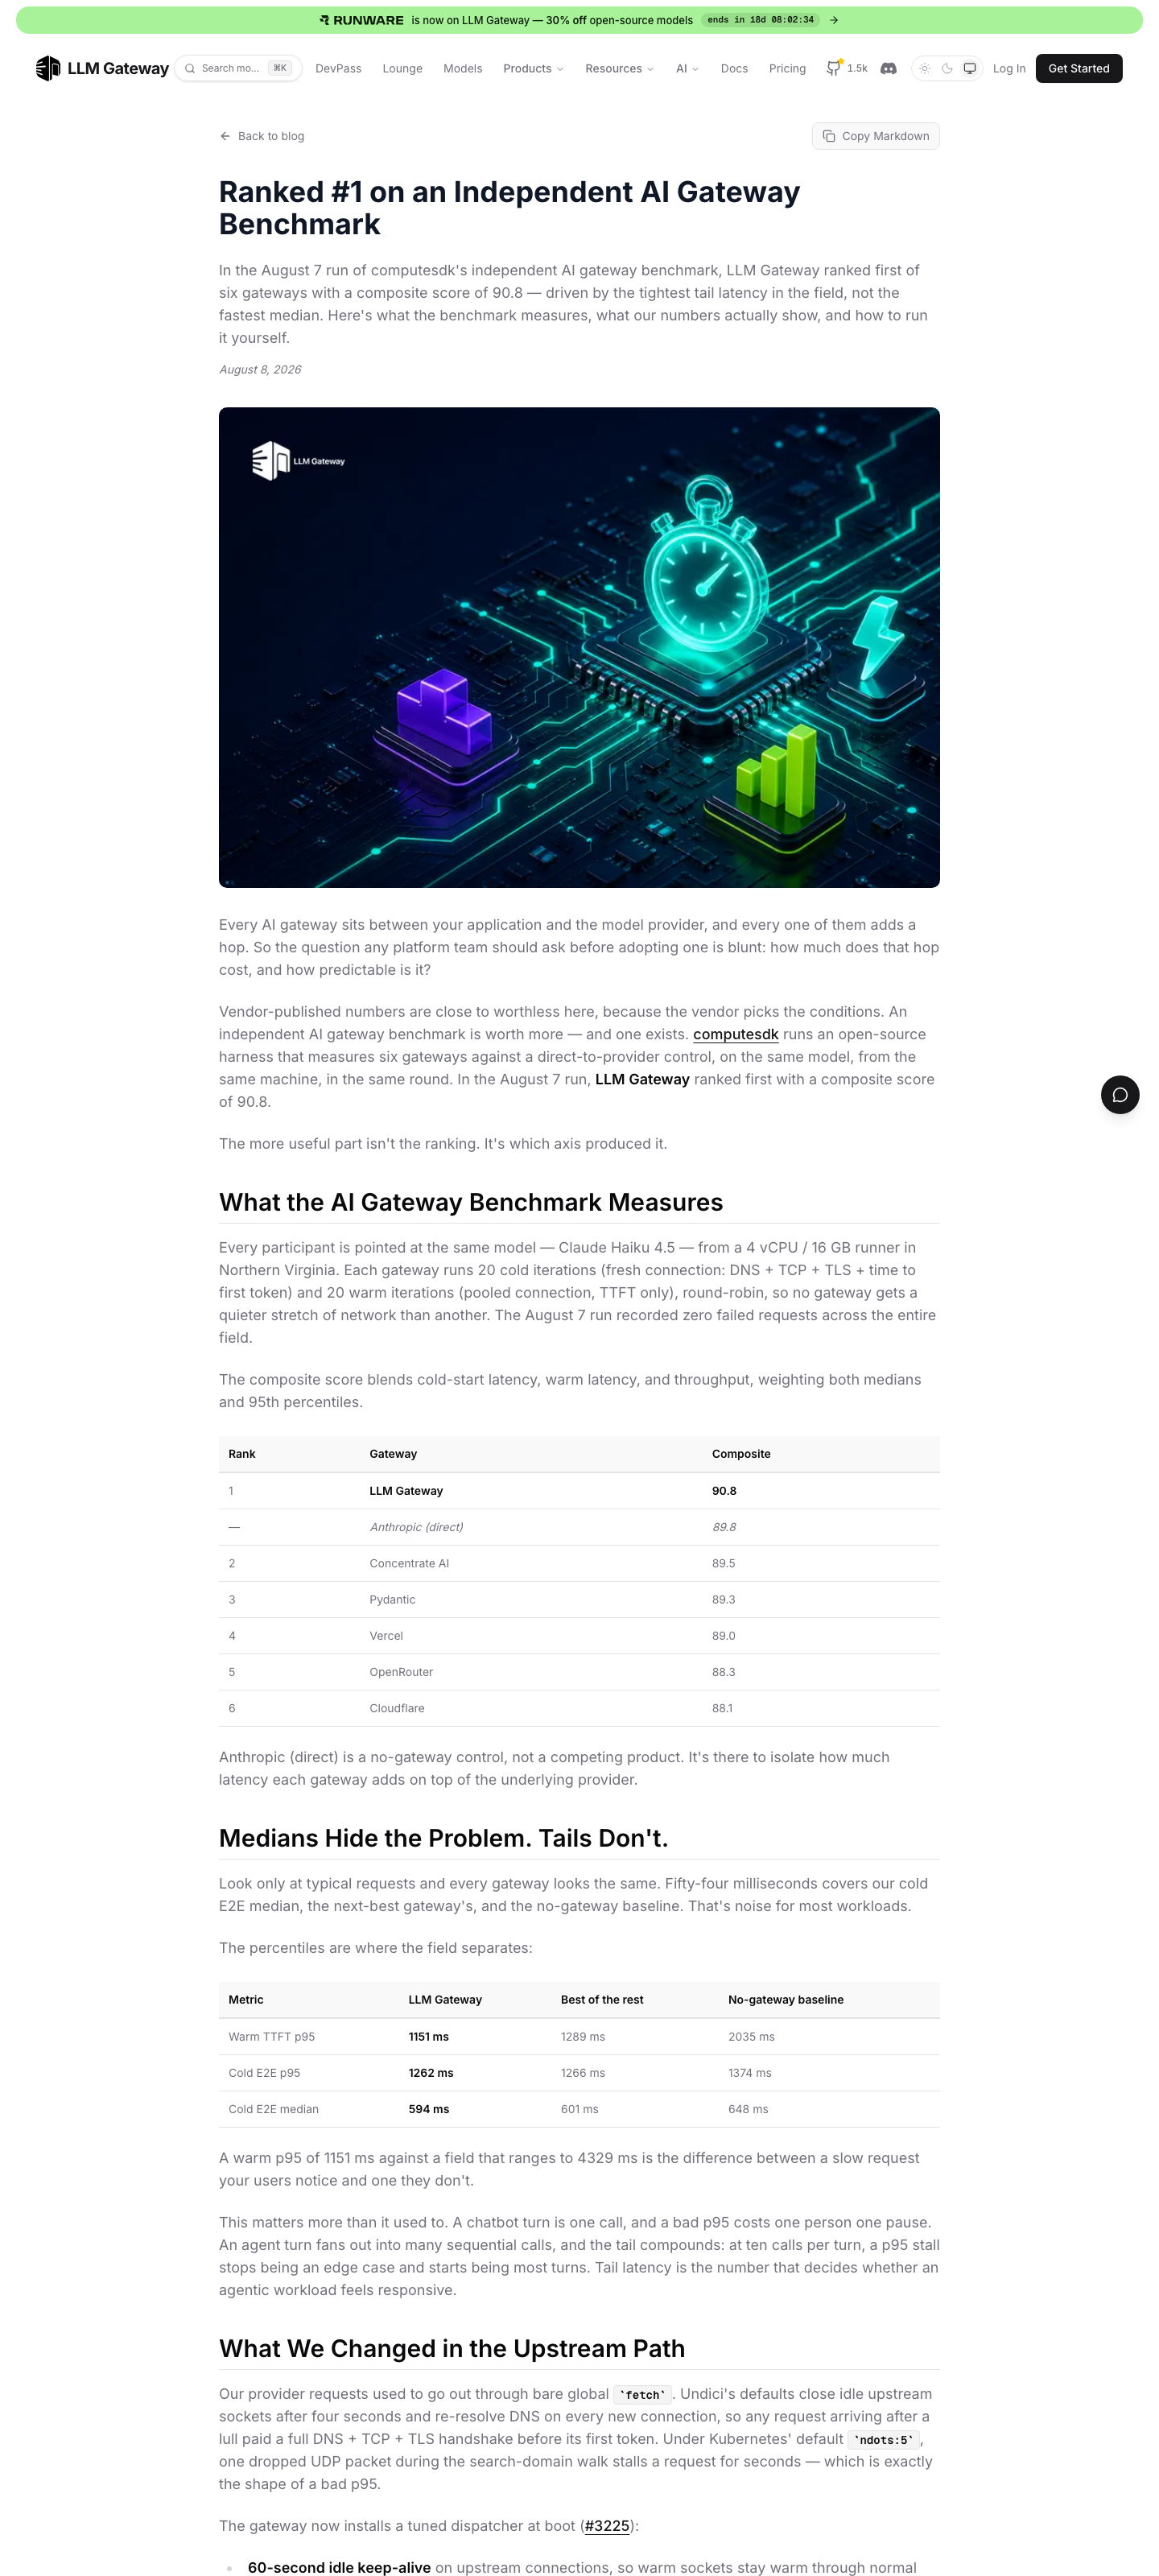
> **Scope changed:** this started as a changelog entry and is now a blog
post. Changelog is for shipped-feature release notes; this is
SEO/marketing content about a third-party benchmark result, which
belongs in `/blog`. The changelog entry and its image are removed in
this PR.

## Problem

We placed first in the August 7 run of [computesdk's independent AI
gateway benchmark](https://www.computesdk.com/benchmarks/ai-gateway/) —
composite 90.8, ahead of five other gateways and the no-gateway
Anthropic control. Nothing communicates that to customers or prospects,
and "AI gateway benchmark" is a keyword we don't currently rank for.

## Approach

New post at `/blog/ai-gateway-benchmark` (category `Engineering`, id
`blog-ai-gateway-benchmark`), plus its OG image.

The post leads with the theopenco#1 result, then pivots to the axis that actually
produced it — tail latency, not median speed:

| Metric | LLM Gateway | Best of the rest | No-gateway baseline |
| --------------- | ----------- | ---------------- | -------------------
|
| Warm TTFT p95 | **1151 ms** | 1289 ms | 2035 ms |
| Cold E2E p95 | **1262 ms** | 1266 ms | 1374 ms |
| Cold E2E median | **594 ms** | 601 ms | 648 ms |

That framing is deliberate: it's the enterprise-relevant story
(predictability under load, which compounds in agentic workloads) and
it's the one the data supports outright.

Per the blog skill, the OG image was generated with the top-left
reserved as negative space and the real `logo-with-name-white.svg`
composited in afterward — gpt-image-2 hallucinates the mark if asked to
draw it.

## Screenshots

`/blog/ai-gateway-benchmark` at 1440px, rendered from the production
build.

<details open>
<summary>Light</summary>

<img width="1440" alt="Blog post 'Ranked theopenco#1 on an Independent AI Gateway
Benchmark' in light theme, showing the OG image with composited logo,
the composite leaderboard table and the tail-latency table"
src="https://raw.githubusercontent.com/theopenco/llmgateway/5d0e1e7031cdafb8a4e06bf6f20a289ea5798f78/blog-light.png"
/>

</details>

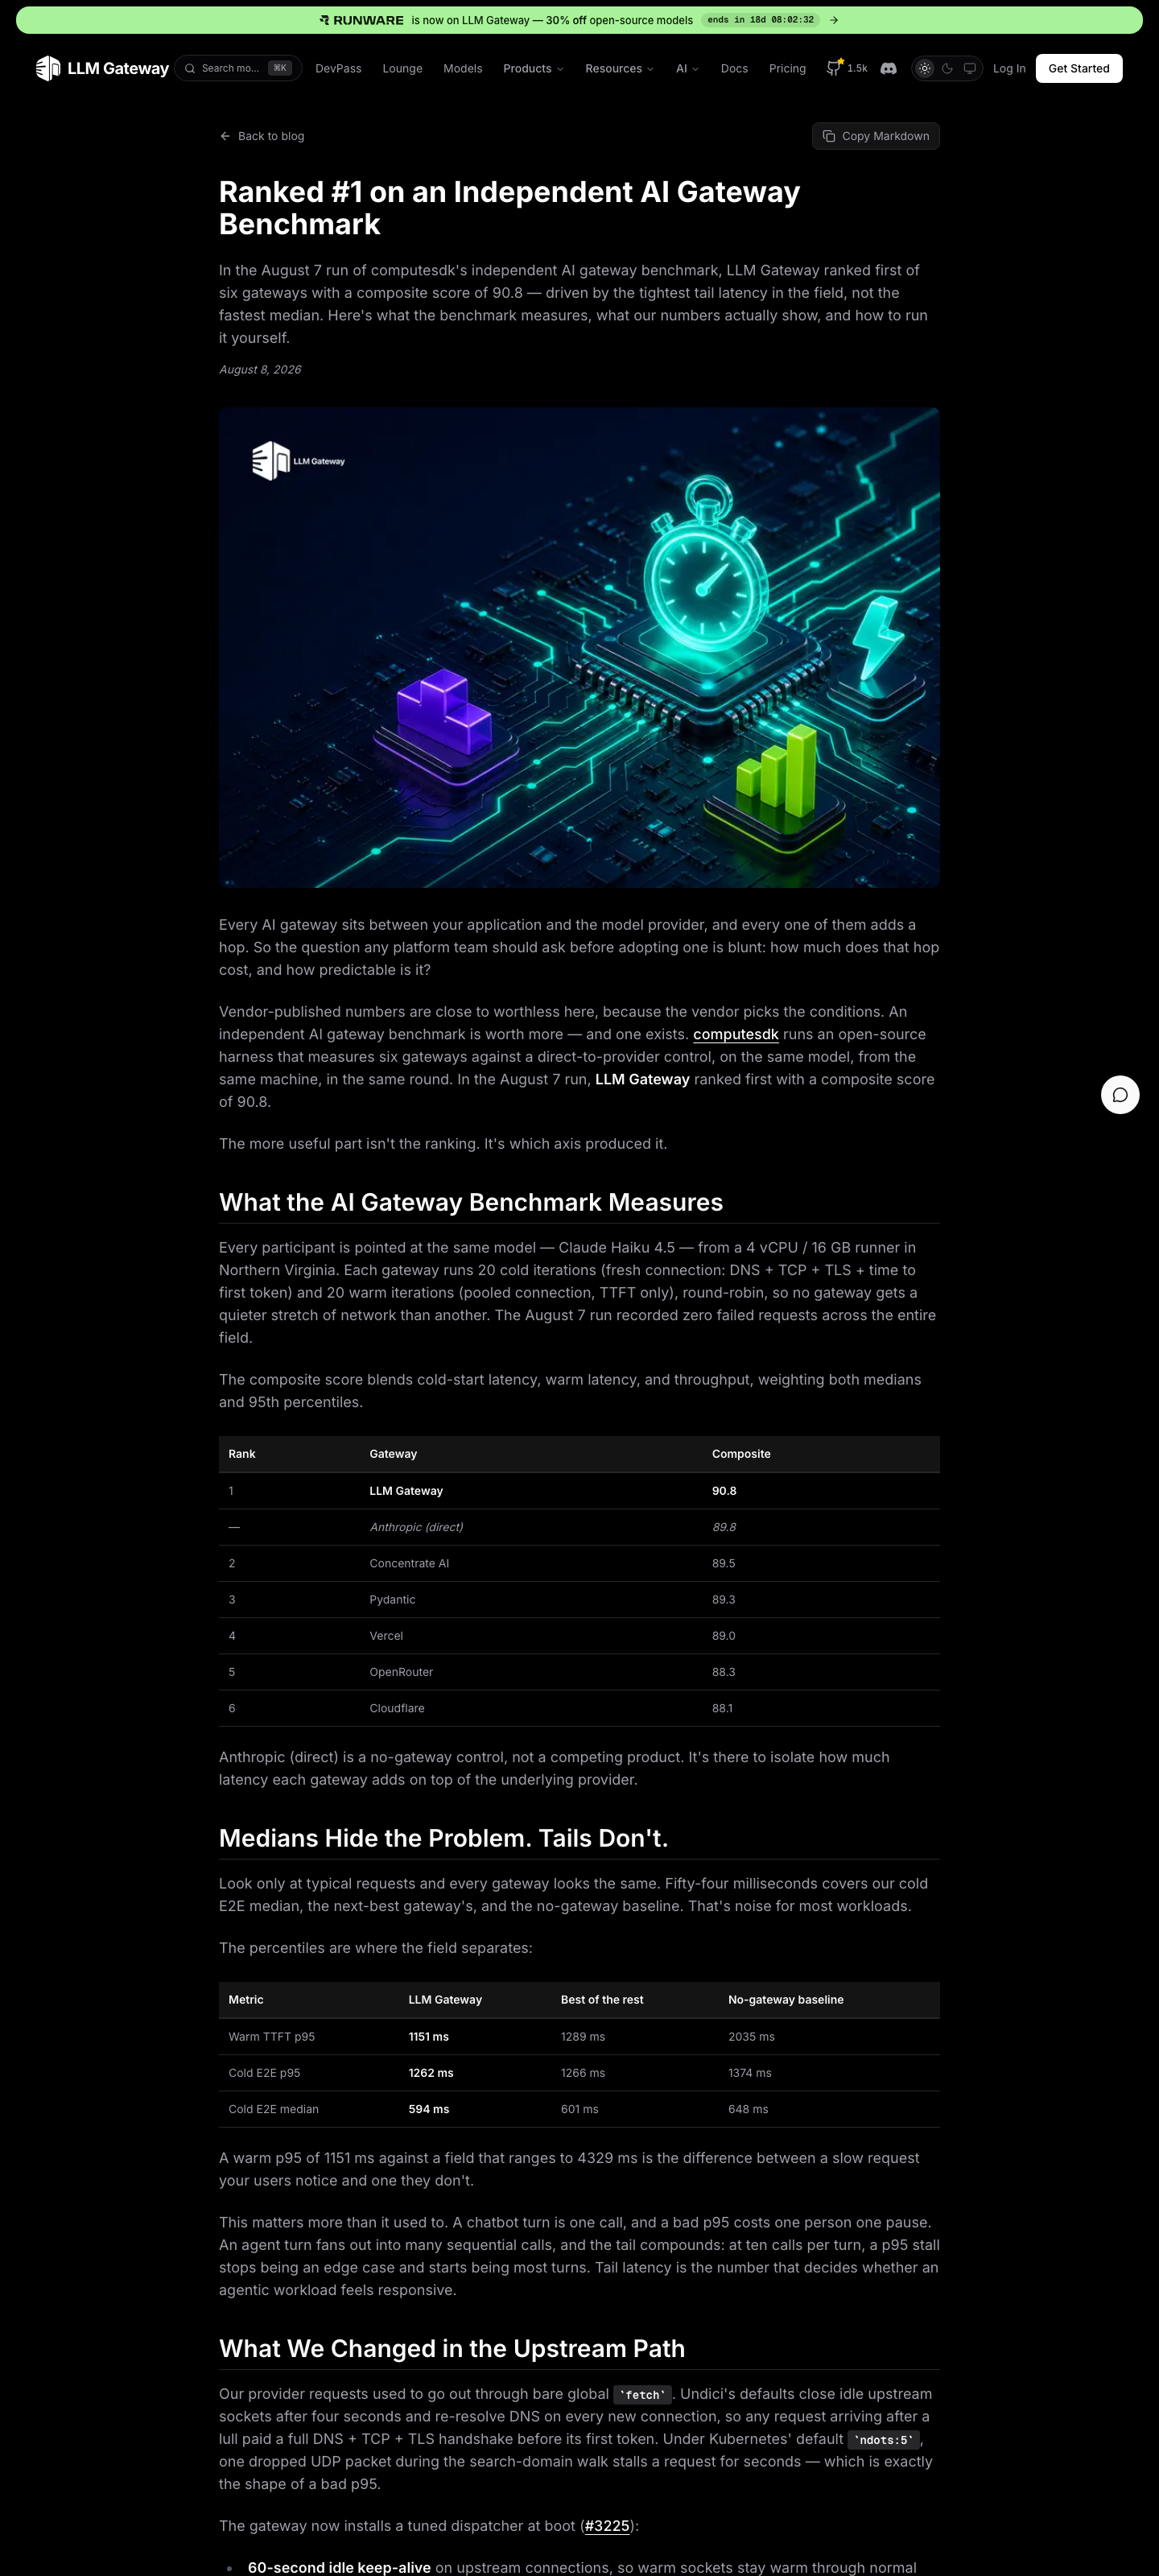
<details>
<summary>Dark</summary>

<img width="1440" alt="The same blog post in dark theme"
src="https://raw.githubusercontent.com/theopenco/llmgateway/5d0e1e7031cdafb8a4e06bf6f20a289ea5798f78/blog-dark.png"
/>

</details>

## Reviewer notes — read before approving

Three things a reviewer would otherwise have to reverse-engineer:

1. **No shipped change explains the week-over-week jump.**
[theopenco#3374](theopenco#3374)
(`perf(gateway): kill cold-path TTFT tail` — prewarm pinger,
`dnsConfig`/ndots, hedging, CPU limits) is **closed and unmerged**;
`UPSTREAM_PREWARM_ORIGINS` is not on `main`. The only merged latency
work, [theopenco#3225](theopenco#3225), landed
Jul 25 — before _both_ runs, including the Jul 31 one where we placed
**last**. The post therefore describes theopenco#3225 as the engineering behind
our upstream path and makes **no causal claim** about the Jul→Aug delta.
Please keep it that way if you edit the copy.

2. **This is one run, and the field is tight.** Our +1.06 over the
baseline is 62% a single number (warm TTFT p95 ≈ 1–2 samples out of 20).
The post has a dedicated "Read the Caveats Before You Cite This" section
and links the live benchmark rather than embedding a screenshot, so
readers see current numbers.

3. **The unflattering history is public in the same repo.**
`results/ai-gateway/2026-07-31.json` shows us last with a 3368 ms cold
p95. The post says so directly rather than inviting a gotcha.

Two claims are deliberately **left out**: that we're faster than calling
Anthropic directly (the FAQ states the opposite outright — our warm TTFT
_median_, 629 ms, is slower than the baseline's 615 ms), and our
field-leading tokens/sec (92.7), since `outputTokensPerSec` is regexed
from the SSE buffer on a per-wire-format path and we're compared on the
`openai` path against the baseline's `anthropic` path.

## Reproduction steps were verified against the pinned tree

The "Run It Yourself" block is pinned to `7548e7584940`, the commit
holding the August 7 results. That commit postdates computesdk's
restructure into a pnpm workspace, so the instructions use `pnpm
install` / `pnpm bench:ai-gateway` and reference
`benchmarks/ai-gateway/scoring.ts` (there is no `src/` at that commit).
`--iterations 20` is correct, not 40: `ai-gateway.bench.ts` sets
`ITERATIONS_COLD` and `ITERATIONS_WARM` _each_ from the flag, so 20
yields the cited 20 cold + 20 warm; the `config.iterations: 40` in the
results JSON is their sum.

## Verification

- `pnpm format` — clean
- `turbo run build --filter=ui` — passes (content-collections validates
the frontmatter schema)
- `/blog/ai-gateway-benchmark` returns 200 and
`/changelog/ai-gateway-benchmark` returns 404 against the production
build
- Benchmark figures read from `results/ai-gateway/latest.json` at
`computesdk/benchmarks@7548e7584940` (`generatedAt
2026-08-07T13:18:32Z`), not transcribed from a screenshot

Content-only; no code paths touched.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Co-authored-by: Luca Steeb <contact@luca-steeb.com>

This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
Sign up for free
to join this conversation on GitHub.
Already have an account?
Sign in to comment
2 participants


Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.
No description provided.