Repository navigation
[Feature] Transfer AR-to-diffusion payloads over NIXL - #6264
hsliuustc0106 merged 46 commits into
Conversation


|
Codex usage limits have been reached for code reviews. Please check with the admins of this repo to increase the limits by adding credits. |
A100 Docker E2E test resultsValidated commit Focused regression suiteCovered:
Six-GPU H3 E2E
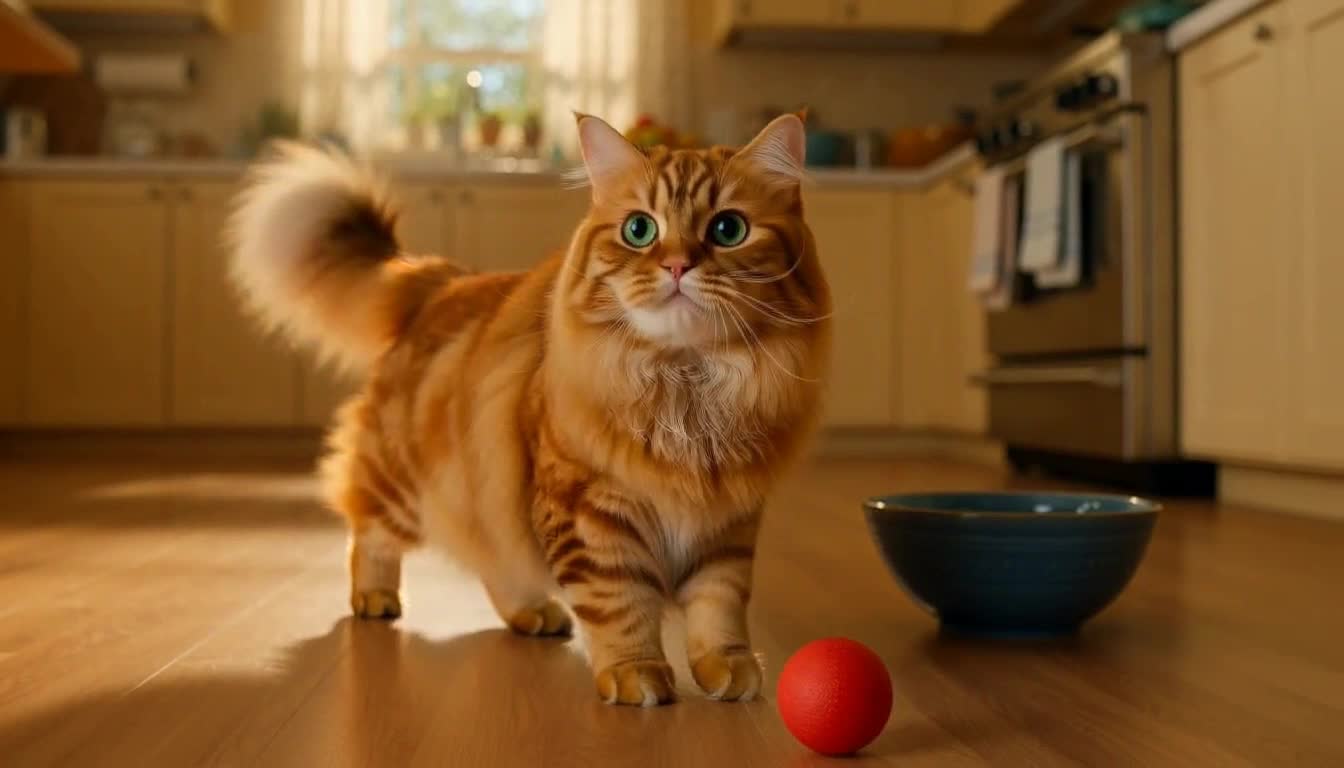
Transport smoke test ( Visual test ( The preview confirms that the eight-step output is visually meaningful rather than the near-gray two-step smoke output:
|
Reproduction commandsThe successful run mapped physical GPUs Start the six-GPU serverRun from the repository root and adjust export REPO_ROOT="$PWD"
export HF_CACHE=/mnt/disk5/HF_CACHE
export H3_SNAPSHOT="$HF_CACHE/hub/models--MiniMaxAI--MiniMax-H3/snapshots/42ed227ee7df40d41602854ae760620d6eb651fe"
docker run --rm --name h3-nixl-e2e-v027 --gpus '"device=0,1,3,4,5,6"' --network host --ipc host -v "$REPO_ROOT:/workspace/vllm-omni" -v "$HF_CACHE:/root/.cache/huggingface:ro" -w /workspace/vllm-omni -e CUDA_VISIBLE_DEVICES=0,1,2,3,4,5 -e HF_HOME=/root/.cache/huggingface -e HF_HUB_OFFLINE=1 -e TRANSFORMERS_OFFLINE=1 -e HF_MODULES_CACHE=/tmp/hf_modules -e VLLM_LOGGING_LEVEL=DEBUG -e VLLM_WORKER_MULTIPROC_METHOD=spawn -e VLLM_OMNI_VIDEO_SYNC_TIMEOUT=14400 -e SETUPTOOLS_SCM_PRETEND_VERSION=0.26.1.dev0 --entrypoint /bin/bash vllm/vllm-openai:v0.27.0 -lc 'mkdir -p /tmp/hf_modules && exec vllm serve /root/.cache/huggingface/hub/models--MiniMaxAI--MiniMax-H3/snapshots/42ed227ee7df40d41602854ae760620d6eb651fe --omni --host 0.0.0.0 --port 8091 --trust-remote-code --task-type fl2va --deploy-config /workspace/vllm-omni/vllm_omni/deploy/minimax_h3_disaggregated.yaml'Wait until curl -fsS http://127.0.0.1:8091/healthSubmit the eight-step visual requestcurl -sS --max-time 14400 -D /tmp/h3-cat-headers.txt -o /tmp/h3-cat-output.mp4 -w 'http_code=%{http_code}\ncontent_type=%{content_type}\nsize_download=%{size_download}\ntime_total=%{time_total}\n' http://127.0.0.1:8091/v1/videos/sync -F 'prompt=A fluffy orange tabby cat with bright green eyes walks across a sunlit wooden kitchen floor, pauses beside a blue ceramic bowl, looks directly into the camera, then playfully bats a small red ball. Warm natural daylight, detailed orange fur, realistic cinematic video, smooth camera movement, vivid colors, clear subject.' -F 'width=1344' -F 'height=768' -F 'fps=24' -F 'num_inference_steps=8' -F 'seed=123' -F 'flow_shift=12.0' -F 'extra_params={"task":"t2va","duration":4.0,"aspect_ratio":"16:9","audio_flow_shift":3.0}'Expected response characteristics from this run: Run the focused regression suitedocker run --rm --entrypoint /usr/bin/python3 -v "$REPO_ROOT:/workspace/vllm-omni:ro" -w /workspace/vllm-omni -e PYTHONPATH=/workspace/vllm-omni vllm-omni-h3-nixl:test -m pytest -q tests/diffusion/test_diffusion_stage_payload.py tests/distributed/omni_connectors/test_tp_rank_aware.py tests/distributed/omni_connectors/test_nixl_connector.py tests/worker/test_omni_connector_mixin.pyResult: |

|
This PR appears to be related to model: MinimaxH3. Model owners: @david6666666 @yuanwu2017, please review your own changes and leave a short self-review comment describing what you checked. PRs without author self-review may not be assigned a reviewer. Please take a look when you have a chance. If you would like an automated review, mention @vllm-omni-review-bot in a comment. |
Retest after
|
 hsliuustc0106
added
diffusion
Signed-off-by: yuanwu <yuan.wu@intel.com>
Regression results (completed September 22, 2026)@hsliuustc0106 @xuechendi Please see the completed regression results below. Revision scope: The full matrix tested PR commit Results on b9844ca
Six-GPU request measurements (individual runs, not a performance benchmark):
The paired aggregated tests covered T2VA (including a 50-step request), FL2VA, reference-video Ref2VA and mixed image/audio Ref2VA. Dense FastH3 generation coverage was T2VA only. Retained failuresThe overall queue exited 1, not all green. Both pinned main and PR returned HTTP 500 instead of the expected 4xx for:
That is 6 failing checks per revision, 12 total. All 12 subsequent valid recovery requests returned HTTP 200. These failures reproduce on the paired main baseline; they have not been waived or relabeled as passes. Environment and verification boundaries
Subsequent merge validation (separate evidence)Merge commit The initial CPU-only H3 run had five failures because that runtime's CPU platform did not implement |

 xuechendi
left a comment
xuechendi
left a comment
There was a problem hiding this comment.
Codes and Design Doc is clear to me, approved
hsliuustc0106
added
ready
Signed-off-by: yuanwu <yuan.wu@intel.com>
Signed-off-by: yuanwu <yuan.wu@intel.com>
Signed-off-by: yuanwu <yuan.wu@intel.com>
hsliuustc0106
added
cuda-test
Signed-off-by: yuanwu <yuan.wu@intel.com>
Signed-off-by: yuanwu <yuan.wu@intel.com>
Signed-off-by: yuanwu <yuan.wu@intel.com>


main already gained receive-timeout safety for
test_unknown_key_is_queried_once through its force_timeout
parametrization (vllm-project#6264), so keep the upstream test body and fold this
branch's remaining guarantee into it: the request socket is retired
exactly on the timeout path and stays reusable when the producer
serves a reply.

Signed-off-by: fusinjay <1747683542@qq.com>

7 participants


Purpose
Transfer complete AR/encoder-to-diffusion payloads through an Omni connector rather than duplicating conditioning through engine-core IPC and the orchestrator. MiniMax-H3 payloads include text, visual/audio latents and layout metadata. Leader-only transfer and receiver TP broadcast support TP2 → TP4.
Updated dependency stack — 2026-09-14
Published and freshly tested:
c9d7bf83c337db7cad5005af7946d0ed5244c3d7, tree2d80115109128973bad63f4411af87666124bc3c.65055774596d53362ef8c8340ed155ff12cd0d54.6753bbd18c9a1f45cfebcec3eacdd2f1e5ea859b. Its old commit stack is no longer included; the NIXL implementation and KV transfer manager match main exactly.7abb255a1ba9176faf9805c0de04f90488076d3e. This exact head and pinned main are actual ancestors. The earlier encoder snapshot/fork-fix history has been replaced by the refreshed eight-commit dependency.New main streaming decode and image-response changes are retained. This is still a stacked integration, not #6264 independently applicable without #6939.
Fresh validation — PASS
Completed 2026-09-14 01:41:46 UTC, overall runner exit 0. Frozen source, index, refs and runner hashes remained unchanged.
All three requests passed exact producer/consumer key and positive-byte matching, H.264 1344×768, 107 frames/24fps, stereo 32-kHz audio, full ffmpeg decode and preview extraction. Keys:
video_sync-9e35132f9fa268e8-816c22ca_0_0video_sync-92937f4a63654b16-a03e02c1_0_0video_sync-b4a995398d3c805f-90ca89fd_0_0These are fresh tests on the rebuilt tree, not reattributed historical results. The earlier September 13 0625 media-only successes used inline fallback after receiver initialization failed; they remain not NIXL receive evidence. The receiver fix is now inherited from merged main, and the current strict matcher is unchanged.
Runtime and scope
sha256:bce11ef0dfb05cd4c9e18695bccdd751b7c200514b14ee67fa14bf06b3f981e4: Python3.12.3, vLLM0.29.0, Torch2.13cu130, NIXL1.3.2.vllm_omni/deploy/minimax_h3_disaggregated.yaml, CLI overrides{"0":{"max_model_len":32768},"1":{"tensor_parallel_size":4,"ulysses_degree":1}}.42ed227ee7df40d41602854ae760620d6eb651fe, FL2VA/Ref2VA partitions; 8 steps, seed42.Local evidence:
vllm-omni-pr6264-artifacts/restack-20260914-retry/(local files, not public attachments). No cross-node, non-CUDA or Turbo-checkpoint model validation is claimed. Remote CI and approvals are separate.DCO: inherited #6939 commit
957505518cfe583e70ed9971240a4d933ce825b2still lacks its author's sign-off. This restack preserves author identity and does not fabricate a trailer or claim DCO is fixed.