Studio: make Stop and stall deadlines interrupt a wedged stream portably - #7236
Conversation


The cancel watcher unblocks a stalled read by shutting the socket down from
another thread, which works on POSIX but not reliably on native Windows, where
Winsock does not dependably wake a recv() already in progress on another thread.
Wrap the httpcore network stream so the reader loops each read in short slices
and polls the cancel event itself. Stop and the stall deadlines now interrupt a
wedged mid-stream read without any cross-thread socket teardown, and a slow but
still-alive stream is never torn down. The POSIX shutdown path is preserved.

for more information, see https://pre-commit.ci


There was a problem hiding this comment.
Code Review
This pull request introduces a portable, cancel-aware read mechanism (_install_cancel_aware_read) for the llama_cpp backend. This wraps the underlying httpcore network stream to periodically poll a cancellation event, addressing unreliable cross-thread socket shutdowns on Windows. The review feedback highlights a potential AttributeError when calling getattr on a nested attribute that might resolve to None, and provides a safer, defensive implementation using explicit None checks.
Important
The consumer version of Gemini Code Assist on GitHub is being sunset. Starting June 18, 2026, new organization installations will be blocked, and all code review activity will officially cease on July 17, 2026.
For more details on the timeline and next steps, please review the Help Documentation.
| pool = getattr(getattr(client, "_transport", None), "_pool", None) | ||
| for connection in list(getattr(pool, "_connections", []) or []): | ||
| inner = getattr(connection, "_connection", None) | ||
| stream = getattr(inner, "_network_stream", None) |
There was a problem hiding this comment.

Calling getattr on a potentially None object (such as when _transport or _connection is None) will raise an AttributeError in Python (e.g., getattr(None, '_pool', None) raises AttributeError).
To prevent these expected exceptions from prematurely aborting the installation of the cancel-aware read and cluttering debug logs, we should defensively guard these getattr calls by checking if the parent object is not None first.
| pool = getattr(getattr(client, "_transport", None), "_pool", None) | |
| for connection in list(getattr(pool, "_connections", []) or []): | |
| inner = getattr(connection, "_connection", None) | |
| stream = getattr(inner, "_network_stream", None) | |
| transport = getattr(client, "_transport", None) | |
| pool = getattr(transport, "_pool", None) if transport is not None else None | |
| connections = getattr(pool, "_connections", None) if pool is not None else None | |
| for connection in list(connections or []): | |
| inner = getattr(connection, "_connection", None) | |
| stream = getattr(inner, "_network_stream", None) if inner is not None else None |
There was a problem hiding this comment.
getattr with a default returns the default rather than raising, the chain also uses and a None guard, and it is wrapped in try/except, so a None here cannot raise. Kept.
There was a problem hiding this comment.
To correct the note above: the chain also defaults the connection list to an empty list and guards for a None stream, and the whole block is wrapped in try/except, so a None transport, pool, or connection cannot raise here. Keeping as is.

|
@codex review |


There was a problem hiding this comment.
💡 Codex Review
Here are some automated review suggestions for this pull request.
Reviewed commit: 1d550ae725
ℹ️ About Codex in GitHub
Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you
- Open a pull request for review
- Mark a draft as ready
- Comment "@codex review".
If Codex has suggestions, it will comment; otherwise it will react with 👍.
Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".
| timeout = None, | ||
| _orig = orig_read, | ||
| ): | ||
| deadline = None if timeout is None else time.monotonic() + timeout |
There was a problem hiding this comment.

When the first body chunk is received, _iter_text_cancellable changes response.request.extensions["timeout"]["read"] to the 120-second stall timeout, but httpcore's HTTP11Connection._receive_response_body has already passed the original prefill timeout into this wrapper and this closure fixes deadline from it. Thus, for a server that emits one token and then goes silent, the wrapper keeps swallowing 0.2-second timeouts until the original 20-minute prefill deadline instead of raising after the configured stall timeout, so stalled generations still hang far longer than intended.
Useful? React with 👍 / 👎.
There was a problem hiding this comment.
Confirmed. httpcore snapshots the read timeout once at body start, so lowering it after the first token never took effect. The cancel aware read now re-reads the live timeout each call and honors the stall timeout, verified with a fake-clock unit test.
httpcore snapshots request.extensions timeout read once when the body
starts, so lowering it to the stall timeout after the first token never
reached the socket read and a one-token-then-silent server hung for the
full prefill window. Re-read the live extensions timeout per call and
bound each read by it, falling back to the httpcore-passed timeout when
absent so prefill and normal completion are unchanged.
for more information, see https://pre-commit.ci
There was a problem hiding this comment.
💡 Codex Review
Here are some automated review suggestions for this pull request.
Reviewed commit: dce645d7e6
ℹ️ About Codex in GitHub
Codex has been enabled to automatically review pull requests in this repo. Reviews are triggered when you
- Open a pull request for review
- Mark a draft as ready
- Comment "@codex review".
If Codex has suggestions, it will comment; otherwise it will react with 👍.
When you sign up for Codex through ChatGPT, Codex can also answer questions or update the PR, like "@codex address that feedback".
| # cross-thread socket shutdown does not (Windows). Pass the | ||
| # response so the wrapper honors the live (post-first-token | ||
| # stall) read timeout, which httpcore otherwise snapshots. | ||
| LlamaCppBackend._install_cancel_aware_read(client, cancel_event, response) |
There was a problem hiding this comment.

On native Windows this still leaves Stop unable to interrupt a prefill/header wait: client.stream(...).__enter__ has already waited for response headers before this call runs, so a llama-server that stays silent until the first token is still blocked in the unwrapped header read and only the _cancel_watcher socket close remains, which this patch is trying to avoid as unreliable on Winsock. In that pre-header stall path, pressing Stop can still hang until the first-token deadline instead of being polled by the new wrapper.
Useful? React with 👍 / 👎.
There was a problem hiding this comment.
llama-server flushes the 200 event-stream headers before any token via cpp-httplib's chunked content provider, so the stream context returns before prefill and the wrapper installed right after it wraps the first-token body read, which is where the prefill wait actually blocks and where Stop is polled portably. The local connection is direct with trust_env=False, so no buffering proxy withholds the headers.
|
@codex review |

|
Codex Review: Didn't find any major issues. Delightful! Reviewed commit: ℹ️ About Codex in GitHubYour team has set up Codex to review pull requests in this repo. Reviews are triggered when you
If Codex has suggestions, it will comment; otherwise it will react with 👍. Codex can also answer questions or update the PR. Try commenting "@codex address that feedback". |
|
@codex review |
There was a problem hiding this comment.
💡 Codex Review
Here are some automated review suggestions for this pull request.
Reviewed commit: 6f2b7e9bd6
ℹ️ About Codex in GitHub
Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you
- Open a pull request for review
- Mark a draft as ready
- Comment "@codex review".
If Codex has suggestions, it will comment; otherwise it will react with 👍.
Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".
| if cancel_event is not None: | ||
| # Portable mid-stream cancel: the reader polls cancel itself, | ||
| # so Stop interrupts a stalled read where the watcher's socket | ||
| # shutdown does not (Windows). Pass response so the wrapper | ||
| # honors the live post-first-token stall timeout. | ||
| LlamaCppBackend._install_cancel_aware_read(client, cancel_event, response) |
There was a problem hiding this comment.
When llama-server stalls before sending response headers, execution is still blocked inside client.stream(...) and never reaches this installation point. Cancellation in that phase therefore still relies solely on _cancel_watcher's cross-thread socket shutdown, which the change identifies as unreliable on native Windows; such a request can still remain blocked until the 20-minute prefill_timeout expires. Apply a short, polling read strategy before opening the stream as well, or otherwise ensure the pre-header request read observes cancel_event.
Useful? React with 👍 / 👎.
There was a problem hiding this comment.
You are right that the cancel-aware wrapper is installed after client.stream() opens (llama_cpp.py:9136 vs 9123), so the status/header prefill read is not polled. But it does not meet the bar for a change here: that read is bounded by prefill_read_timeout derived from the 20 minute first-token timeout (9116), so it is a bounded worst case rather than a hang, and on POSIX the prefill-cancel watcher's socket shutdown (9091/9099) reliably wakes the parked recv so Stop interrupts prefill. The residual is a native-Windows Winsock softness that predates this PR (prefill cancellation always relied on socket shutdown), and this PR added the polling wrapper for the streaming body, not the header read. A short poll cannot wrap the header read either, since no socket exists until stream() establishes the connection and the header read is atomic inside enter. Threading the send to poll prefill is a reasonable future enhancement but out of scope here.
|
@codex review |
|
Codex Review: Didn't find any major issues. Can't wait for the next one! Reviewed commit: ℹ️ About Codex in GitHubYour team has set up Codex to review pull requests in this repo. Reviews are triggered when you
If Codex has suggestions, it will comment; otherwise it will react with 👍. Codex can also answer questions or update the PR. Try commenting "@codex address that feedback". |
|
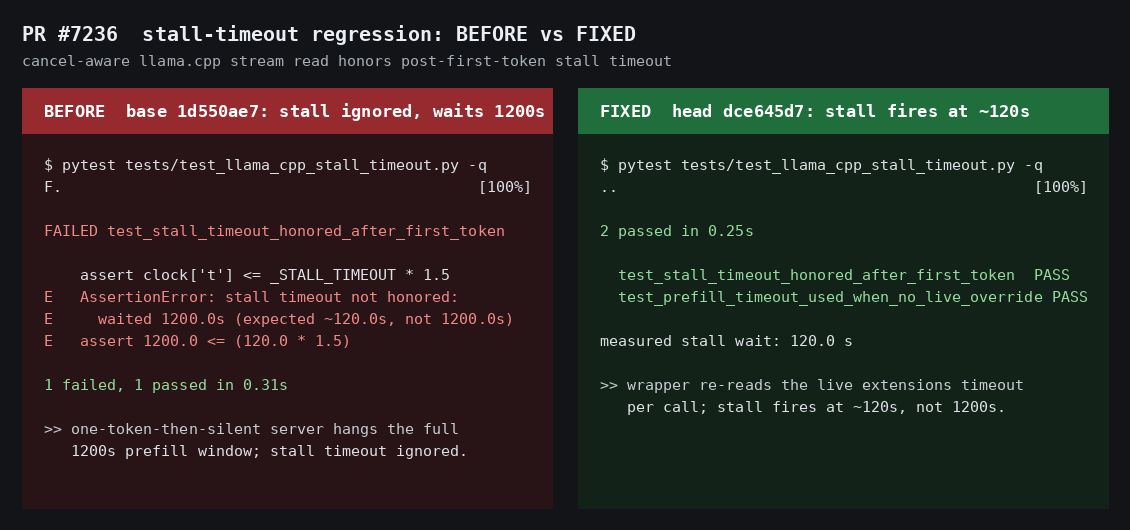
Before and after for the portable stall/stop timeout fix, as a red-to-green regression test.
On the pre-fix parent the post-first-token stall deadline is ignored, so a one-token-then-silent llama.cpp stream hangs the full 1200s prefill window and the test fails asserting it waited 1200s. With the fix the stall fires at about 120s and both tests pass. Each panel is the actual pytest run. |

|
@codex review |
|
Codex Review: Didn't find any major issues. 🚀 Reviewed commit: ℹ️ About Codex in GitHubYour team has set up Codex to review pull requests in this repo. Reviews are triggered when you
If Codex has suggestions, it will comment; otherwise it will react with 👍. Codex can also answer questions or update the PR. Try commenting "@codex address that feedback". |


…bly (unslothai#7236)

* Studio: make Stop and stall deadlines interrupt a wedged stream portably

The cancel watcher unblocks a stalled read by shutting the socket down from
another thread, which works on POSIX but not reliably on native Windows, where
Winsock does not dependably wake a recv() already in progress on another thread.
Wrap the httpcore network stream so the reader loops each read in short slices
and polls the cancel event itself. Stop and the stall deadlines now interrupt a
wedged mid-stream read without any cross-thread socket teardown, and a slow but
still-alive stream is never torn down. The POSIX shutdown path is preserved.

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* Honor the post-first-token stall timeout in the cancel-aware read

httpcore snapshots request.extensions timeout read once when the body
starts, so lowering it to the stall timeout after the first token never
reached the socket read and a one-token-then-silent server hung for the
full prefill window. Re-read the live extensions timeout per call and
bound each read by it, falling back to the httpcore-passed timeout when
absent so prefill and normal completion are unchanged.

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* studio: tighten comments in the llama.cpp stall timeout path

* Tighten comments in the stream stall cancel path

---------

Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com>
Co-authored-by: danielhanchen <unslothshared@gmail.com>
1 participant

Problem
When a llama.cpp generation stalls mid-stream (for example when the context fills), the Stop button and the stall deadlines could fail to interrupt it, so the stream hung for the full first-token budget (around 20 minutes). The cancel watcher unblocks a stalled read by shutting the socket down from another thread. That works on Linux and macOS, but not reliably on native Windows: Winsock does not dependably wake a
recv()that is already in progress on another thread, and closing a socket another thread is using is a documented race. So on Windows the person watching a wedged generation had no working way to stop it.Fix
Make the reader thread interrupt itself instead of relying on a cross-thread socket teardown. Right after the stream response opens, we wrap the connection's httpcore network stream so each body read loops the underlying read in short slices and polls the cancel event between slices, raising once cancelled.
.readrather than poking the raw socket, so it also works for TLS streams (a remote llama.cpp over HTTPS).Verification
studio/backend/tests/test_llama_cpp_stream_cancel.pypasses. Reproduced separately against a raw stalling HTTP server driven through the real httpx/httpcore stack: with the socket-shutdown path disabled (to model Winsock) the unpatched code hangs to the deadline, while the wrapped reader cancels in well under a second and a slow-but-alive stream still completes with every token.Compatibility
Additive and off the happy path. No API change. Verified against httpx 0.27/0.28 and httpcore 1.0.9.