Repository navigation
[Feat] comfyui: Add SGLDCacheOptions for per-run Cache-DiT - #43696
OnePunchMonk wants to merge 19 commits into
Conversation


Adds a node that sets Cache-DiT per run on a cloned MODEL, so toggling it
never restarts the worker. The executor reads the options from
transformer_options and maps them to the per-request enable_cache_dit and
cache_dit_params fields. The loader option enable_cache_dit stays as the
fallback, and a per-run on/off wins over it.

Only MiniMax-H3 runs a multi-step session on the worker. Other models send
one independent step per request, so Cache-DiT has no history to reuse; the
node and the executor reject it for them instead of silently doing nothing.
TeaCache is not exposed: its state resets on timestep 0, and every ComfyUI
request is timestep 0.
 github-actions
Bot
added
documentation

|
GPU run on a Modal L4 (CUDA 13, torch 2.13 with the released sglang 0.5.21 deps, this branch's code on top, ComfyUI master checked out). Ran all This does not exercise Cache-DiT on a real H3. The full H3 checkpoint is about 498 GB, so I did not run it. Treat the per-run on/off behavior as unit-tested only, and it would be good to have someone with H3 weights try it. The only skip is a test that needs a tiny H3 checkpoint. |

|
Full details of the GPU run, so it can be reproduced. Environment
Command (from Baseline: plain Result on this branch: 123 passed, 1 skipped, 3 xfailed. The one skip needs a tiny H3 checkpoint. What this does and does not show
|

|
Thanks! Can this be generic rather than H3-only? Also, please add an e2e run and share speed and quality numbers with it on vs off. |
ComfyUI sends one request per DiT call, so the worker keeps one Cache-DiT
context per sampler run, sized from the run's sample_sigmas.
|
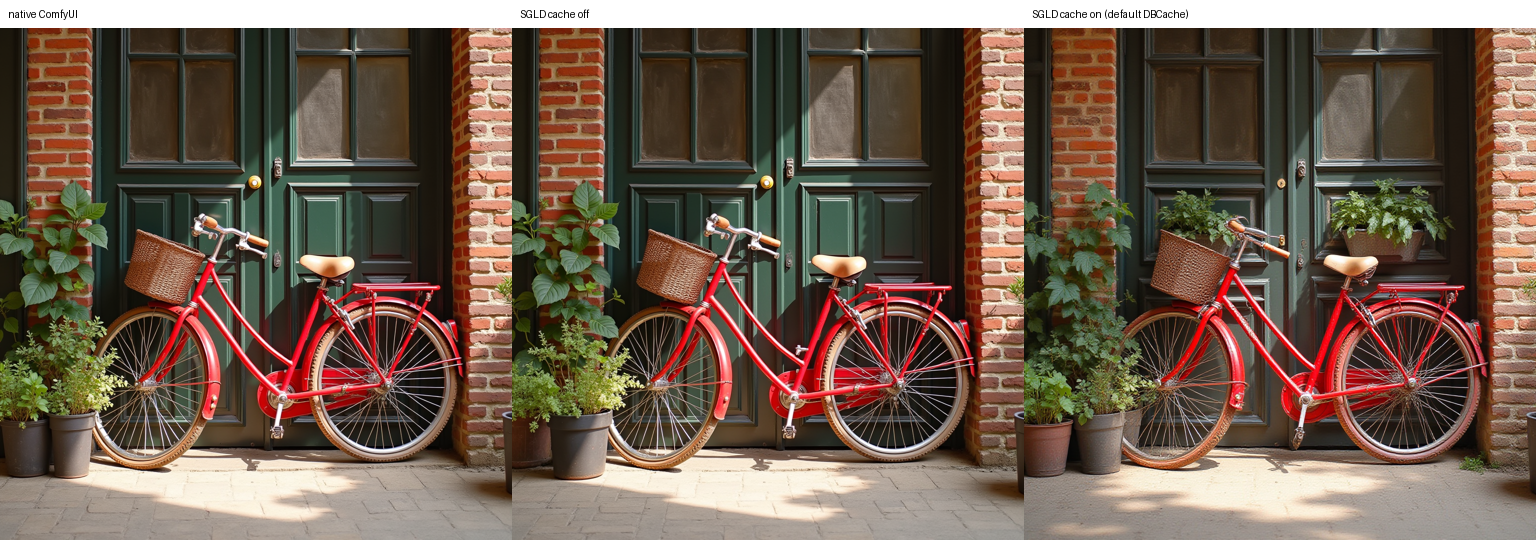
E2E numbers. H100, ComfyUI v0.39.2, Flux.1-dev, 1024x1024, 25 steps, euler/simple, cfg 1, same seed, default DBCache settings (Fn=1 Bn=0 W=4 R=0.24 MC=3). The worker log confirms one context for the whole run:
That is 1.81x vs cache off. With these defaults the output drifts noticeably (layout shifts a bit, still a clean image), so the default threshold is on the aggressive side for 25 step Flux. The node exposes the DBCache knobs for a more conservative setting.
|
cache-dit 1.5.1 marks the FakeDiffusionPipeline class as cached and never
clears it on disable_cache(transformer), so a knob change between requests
asserted on remount.
|
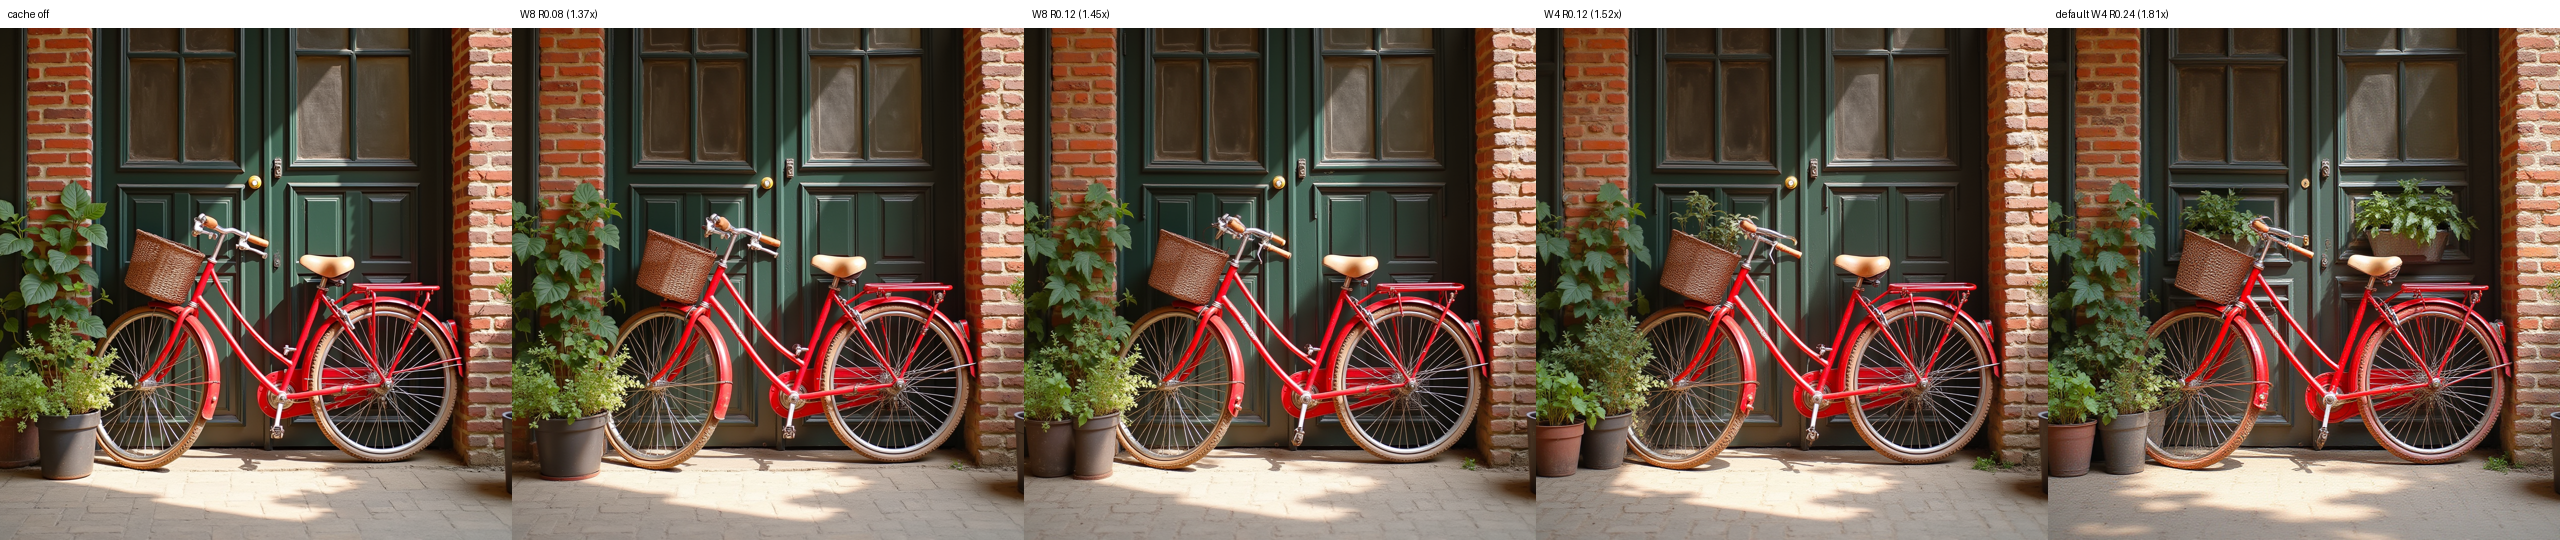
Follow-up with gentler DBCache settings, same H100 setup (Flux.1-dev, 1024x1024, 25 steps, same seed), compared against cache off:
Every setting keeps a clean image, with the layout shifting more as the threshold goes up. To make sure the drift is Cache-DiT itself and not the per-run wiring, I checked that W25 (no caching possible) is bit-identical to cache off, and that a fresh mount and a later run with the same seed are bit-identical too. The sweep also hit a crash when the knobs change between runs: cache-dit 1.5.1 leaves a class-level flag set after disable_cache on a bare transformer, so the remount asserted. Fixed in 7585fd5 with a regression test against the real cache-dit. This affects server requests that change cache_dit_params as well, not just ComfyUI.
|

ComfyUI calls the model once per CFG branch, so each request carries one
row and no CFG of its own. Instead of rejecting uncond calls, the executor
reads the guider in the sampler wrapper (cfg != 1 with a negative cond) and
sends comfyui_separate_cfg; the worker then mounts Cache-DiT with separate
CFG so alternating cond / uncond calls count as one step. Registered
adapters (Z-Image, Qwen-Image, FLUX) ignore has_separate_cfg and default to
their diffusers pipeline, which batches CFG, so pass enable_separate_cfg
explicitly for ComfyUI runs only.

Z-Image Turbo, 30 steps, H200, warm: cfg 4 6.2-6.8 s -> 4.1 s; cfg 1
4.0 s -> 2.0 s; switching cfg and cache on one worker remounts cleanly.
|
Hi @OnePunchMonk, I pushed one commit on top of your branch (814256e) so CFG > 1 runs are cached instead of rejected:
Feel free to rework or drop the commit. |
Resolve test_comfyui_generator.py: keep both appended tests; the reuse test's
last_options gains runtime_model_path, which main's gather_options now holds.
|
Could you merge the latest main into this branch, resolve the conflicts, and update the docs and default parameter guidance? Please clarify the quality trade-off and consider a more conservative preset. I also reproduced an issue where switching to off/default after tuning the cache knobs raises a ValueError; users should be able to disable caching without resetting every knob. |
…s, add conservative preset

This comment has been minimized.
This comment has been minimized.
OnePunchMonk
changed the title
This comment has been minimized.
This comment has been minimized.
…models in preflight, fix cache docs
comfyui_cache_dit_run detected the first call of a sampler run from the shared run-state slot, which Qwen-Image-2.1's condition stage fills before denoising, so first_call was never true and the Cache-DiT context was not refreshed after the first run. Track it in its own dict, cleared with the run state.
…, keep knobs on default
|
Does the 3N fallback hold for |


Adds an
SGLDCacheOptionsnode that turns Cache-DiT on or off for a single run from the graph. It sets the options on a cloned MODEL, so toggling it never restarts the worker. The executor reads them fromtransformer_optionsand maps them to the per-requestenable_cache_ditandcache_dit_params. The loader option stays as the fallback, and a per-run on/off wins over it.Only MiniMax-H3 supports it. Other models send one independent step per request, so there is no step history to reuse, and the node rejects them with an error. TeaCache is not exposed because its state resets on timestep 0.
This is meant to line up with slimming
SGLDOptionsdown to load-time options. If #43504 lands first I will rebase onto itsmodel_optionspath.Tested on CPU only (
test_comfyui_adapters.py,test_comfyui_generator.py, 44 passed). GPU unit run is in the comments.CI States
Latest PR Test (Base): ❌ Run #41124542308
Latest PR Test (Extra): ❌ Run #41124542543
Latest PR Test (AMD ROCm 10): ❌ Run #41124542339