Repository navigation
Conversation





Carried unchanged from sgl-project#43465 (by @At1a8, open at the time of writing) so this
PR is self-contained; only the imports were re-resolved against current main.
Drop this commit once sgl-project#43465 is merged.

… TP, skip zero-row indexer groups

- --enable-cp-decode-attn-tp narrows the attention linears per rank. On gfx950
  the V4.1 block-fp8 (ue8m0, 32-wide) linears run from scale copies derived at
  load time (weight_scale_mx_e8m0, weight_scale_inv_mx, weight_bf16); slice
  them on the same dim as the weight, and reject the MXFP8-native route whose
  weight layout cannot be narrowed.
- With prefill CP a request group can own no rows on a rank (a one-token
  extend lands on one rank). Skip that group in the HIP low-ratio indexer
  before scoring: the fp4 prefill logits schedule still sends its CTAs to row 0
  of a freshly allocated (null) page table, and top-k cannot launch on an empty
  batch. Seen as a GPU memory fault at concurrency 64 with mixed short and long
  extends.
- sgl-project#43465's HIP small-shard floor (interleave CP needs 16 rows per rank) now
  lives in interleave_cp_min_tokens(), which also bounds the CP breakable-graph
  capture buckets: a bucket below the floor never activates CP, so its CP-local
  capture asserted at startup on ROCm.
- The HIP BCG metadata test follows sgl-project#43465's apply_cp_reindex call, which
  passes the CP layout's local_index (the stub gains it, and the expected call
  carries it).

Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
At1a8
changed the title
 bingxche
added
the
bypass-fail-fast

…oject#43465 by At1a8)

Applied sgl-project#43465 (head 5c5862f, author @At1a8, open) on top of
the HIP CP+BCG port (sgl-project#43819). Conflict resolution in
deepseek_v4_backend_hip_radix.py: both PRs pad swa_replay_start and pass
cp_metadata.local_index to apply_cp_reindex; kept the single copy from sgl-project#43819,
which also keeps num_write_tokens for breakable prefill graphs.

|
CUDA: prefill CP + decoder SWA bounded replay + DSpark crashes at the first large prefill (tail rows are not scattered back before the CP gather) We reproduced a failure on CUDA/SM90 with the combination enabled. The analysis points at the same tail-layout gap that the "Bounded-replay tail under CP" part of this PR closes on HIP. Setup: DeepSeek-V4.1-Flash, 8×H20-3e (SM90), CUDA, sglang v0.5.22, Symptom: the server boots, but the first 128K-token prefill kills the scheduler: Analysis
Launch-time guard gap: Fix we validated: in
Is this the same gap #43465 closes on HIP, and is a CUDA-side counterpart planned? Happy to send the 22-line patch if useful. |
Hi @SAXEM1997, we dont have Nvidia device for your settings, feel free to submit a new pr for your issues. |
Squashed from sgl-project#43465 by @At1a8 (head c55ba0c), unchanged.
It is carried here only until sgl-project#43465 merges and will be dropped on rebase.
Resolve the conflicts with sgl-project#45339 in deepseek_v4_backend_hip_radix.py: keep
main's tail entry (the source layer runs inside the tail after
write_tail_source_kv) and add the CP metadata / DP buffer switch on top of it.
The HIP CP low-ratio sources take q_lora rows only for the indexer, since
write_tail_source_kv runs the compressor alone with q_lora=None.
bingxche
added
the
parallel-stages

…ill CP gather with DSpark

When prefill CP, decoder SWA bounded replay and DSpark run together, the late
layers return only each rank's SWA tail rows (16 of 32768), while
_eager_runner._execute_extend_cp gathers with the full-batch CP layout (4096
rows per rank). The capture_dspark guard skipped the tail scatter, so the first
large prefill aborted in interleave.py:

  RuntimeError: Interleave CP gather received an unexpected local token count:
  rank=3, got=16, expected_at_least=4096, total=32768, cp_size=8

Add _needs_cp_tail_scatter() for the CUDA/CP gate and scatter hidden_states,
pre_hc_head and the tail-layer DSpark aux tensors back into the rank's full
layout before the CP gather. Non-tail rows are zero-filled (defensive; they are
never read). Scoped to CUDA so it composes with the HIP counterpart in sgl-project#43465.

This covers eager prefill only: the breakable prefill CUDA graph with prefill
CP is guarded by sgl-project#44141.

Tested on 8x H20-3e (SM90), sglang v0.5.22: 5/5 greedy outputs match the
non-CP production baseline; cold TTFT 128K/256K/512K = 3.37/6.86/15.95 s vs
5.41/11.71/28.66 s with replay off.
…ill CP gather with DSpark

When prefill CP, decoder SWA bounded replay and DSpark run together, the late
layers return only each rank's SWA tail rows (16 of 32768), while
_eager_runner._execute_extend_cp gathers with the full-batch CP layout (4096
rows per rank). The capture_dspark guard skipped the tail scatter, so the first
large prefill aborted in interleave.py:

  RuntimeError: Interleave CP gather received an unexpected local token count:
  rank=3, got=16, expected_at_least=4096, total=32768, cp_size=8

Add _needs_cp_tail_scatter() for the CUDA/CP gate and scatter hidden_states,
pre_hc_head and the tail-layer DSpark aux tensors back into the rank's full
layout before the CP gather. Non-tail rows are zero-filled (defensive; they are
never read). Scoped to CUDA so it composes with the HIP counterpart in sgl-project#43465.

This covers eager prefill only: the breakable prefill CUDA graph with prefill
CP is guarded by sgl-project#44141.

Tested on 8x H20-3e (SM90), sglang v0.5.22: 5/5 greedy outputs match the
non-CP production baseline; cold TTFT 128K/256K/512K = 3.37/6.86/15.95 s vs
5.41/11.71/28.66 s with replay off.
|
@amd-bot ci-status |

CI Status for PR #43465Verdict: None of the 6 executed test failures was caused by this PR. Four AMD failures fail the same test case the same way on comparable Note The PR updates Executed failures: AMD: 4 (0 related) · Others: 2 (0 related) AMD Executed Failures
Other Executed Failures
Xeon (
What to do before merge
Generated by amd-bot using Claude Code CLI |
Resolve the conflict with sgl-project#45783 in deepseek_v4_backend_hip_radix.py: main
removed the SGLANG_DSV41_TORCH_PREFILL_INDEXER check from the extend branch of
_low_ratio_index_topk and the PR removed the prefill CP assert next to it, so
drop both.
…io_sources

sgl-project#45407 slices q_lora with [:n] on the hoisted-rows path of
forward_low_ratio_sources. On gfx950 the indexer's wq_b operand is an
Mxfp8Activation or Fp8GridActivation, which refuses slicing, so a DeepSeek-V4.1
DSpark server crashes while capturing the target-verify CUDA graph. Move
_first_rows from the HIP backend into the shared backend and take the rows
through it.
Gate the gfx950 q_lora row helper behind get_platform().is_hip and keep it in the
HIP backend, so the CUDA path still slices q_lora with [:n].
Decoder SWA bounded replay keeps only each request's 128-token tail in the
late layers. With prefill CP, the runner's gather expects this rank's full
shard layout, so CUDA needs the tail rows put back even when DSpark captures
aux hidden states; the DSpark aux tensors must be scattered the same way.
HIP keeps rejecting replay + CP until sgl-project#43465 lands.

Co-Authored-By: Claude Code <noreply@anthropic.com>
|
@amd-bot ci-status |
CI Status for PR #43465Warning Verdicts the evidence does not support (treat them as unknown):
Verdict: Neither executed failure comes from this PR. Both are bugs that were already on Note Each failure has a fix on Executed failures: AMD: 1 (0 related) · Others: 1 (0 related) AMD Executed Failures
Other Executed Failures
The failed gate and coordinator jobs ( What to do before merge
Generated by amd-bot using Claude Code CLI |
|
@amd-bot ci-status |
CI Status for PR #43465Warning Verdicts the evidence does not support (treat them as unknown):
Verdict: None of the three executed AMD failures were caused by this PR. Two of them came from a Note CI tested Executed failures: AMD: 3 (0 related) · Others: 0 (0 related) AMD Executed Failures
What to do before merge
Generated by amd-bot using Claude Code CLI |
With --enable-prefill-cp SGLang keeps all 64 attention heads on every rank
(attention TP 1) and the whole KV and index caches on every rank, but decode and
verify steps never run CP. K1 and K2 therefore run this rank's TP share of the
heads as without CP: wq_b's and wo_a's rows are views of the replicated weights,
wo_b's columns (in aiter's (16, 16) preshuffle too) and its block codes a copy.
The kernels are unchanged. The gate accepts CP only as prefill CP over the whole
TP group; decode CP or a narrower CP group is refused.

The README names sgl-project/sglang#43465 (prefill CP on HIP) among its
requirements.
Decoder SWA bounded replay keeps only each request's 128-token tail in the
late layers. With prefill CP, the runner's gather expects this rank's full
shard layout, so CUDA needs the tail rows put back even when DSpark captures
aux hidden states; the DSpark aux tensors must be scattered the same way.
HIP keeps rejecting replay + CP until sgl-project#43465 lands.

Co-Authored-By: Claude Code <noreply@anthropic.com>

|
Reviewed the full diff. Most of this is a faithful mirror of the CUDA prefill-CP work onto HIP — the Three things I think should block, one of which cannot execute at all. 1. The copied
|
Thanks for @kkHuang-amd 's comments — all three blocking points were right.
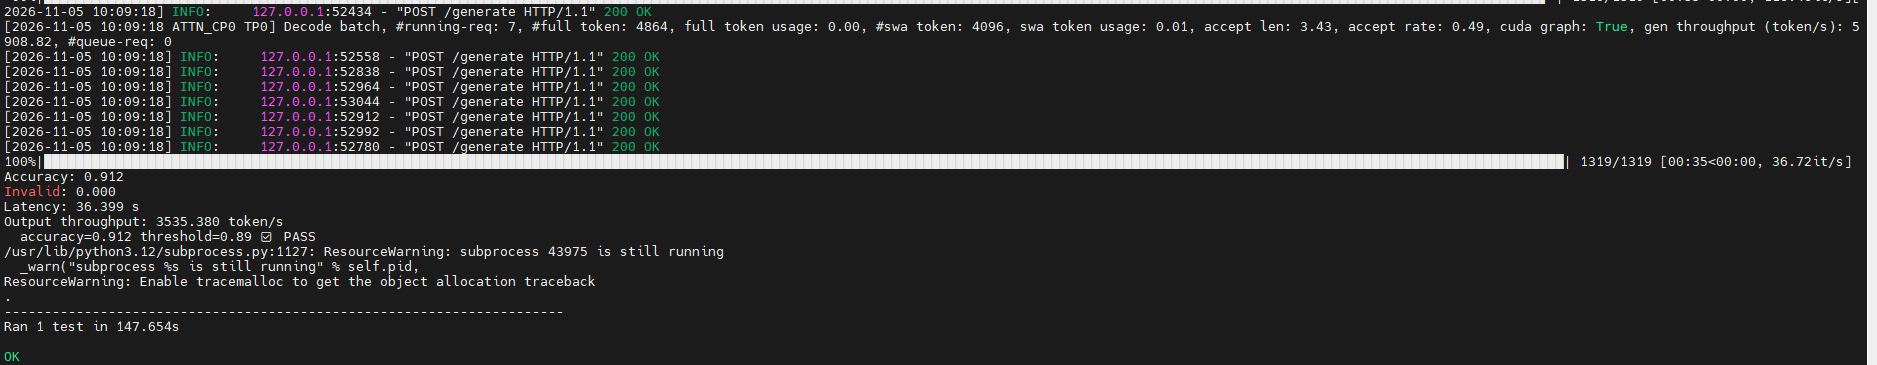
|
|
/rerun-failed-ci |


Motivation
Prefill CP for DeepSeek-V4.1 already works on CUDA, but on AMD it's still blocked.
Long prompts (e.g. 100k) are slow to prefill on plain TP8, this PR turns it on for AMD HIP platform, validated on gfx950.
Modifications
deepseek_v4_hook.py: stop rejecting V4.1 for prefill CP on HIP, including with--enable-decoder-swa-bounded-replay(V4 is still rejected).deepseek_v4_backend_hip_radix.py:_forward_low_ratio_sources_cpinstead of previous CUDA version:_low_ratio_index_topk: drop the assert that rejectedrows_per_requestand pass it down to the HIP indexer._first_rows: on gfx950q_loracan be an FP8 activation wrapper that can't be sliced with[:n]._late_layer_tail_cp_layoutto build the tail's own CP layout.init_forward_metadata_prefilltakes an optionalcp_metadatafor the tail: padswa_replay_startand reindex rows withlocal_index.enter_late_layer_tail/exit_late_layer_tailswap in and restore the CP metadata and DP buffer length, and cut candidate masks by each rank's local tail rows.low_ratio_backend_hip.py: passrows_per_requestinto the HIP indexer so it knows how many local rows each request has.deepseek_v4.py: with HIP CP, put the tail outputs (including DSpark aux) back into the rank's full layout, because the CP runner gathers by that layout.interleave.py: on HIP, skip CP when a rank would get fewer than 16 tokens. aiter's group32 MXFP8 GEMM returns NaN forwqkv_a(N=1792, K=5120) at M=5~8. Left a TODO to drop this once the kernel is fixed.test_platform_prefill_cp_deprecation.py.Accuracy Tests
Server Command
Speed Tests and Profiling
I/O=100k/500
Checklist
Review and Merge Process
/tag-and-rerun-ci,/tag-run-ci-label,/rerun-failed-ciCI States
Latest PR Test (Base): ⏳ Run #41991791828
Latest PR Test (Extra): ❌ Run #41991791640
Latest PR Test (AMD ROCm 10): ⏳ Run #41991792278
Tip
Base CI only covers the core cases, and its workload may not exercise your change. Use
/rerun-testto run the tests your change touches, or copy this prompt for an agent: