[Spec] DFlash: remove per-step host syncs so the CPU runs a full step ahead (spec-v2 overlap) - #31468
Conversation


|
Warning You have reached your daily quota limit. Please wait up to 24 hours and I will start processing your requests again! |

…to the draft graph

Two per-step host-stall fixes for spec-v2 run-ahead (the CPU must launch
step N+1's cuda graphs while step N still executes):

1) Compact draft req_to_token rebuild: replace the masked segment gather
(+ 2x assign_req_to_token_pool) with one fused fixed-grid triton kernel.
The old path blocked the host twice per decode step: lengths.max().item()
and the boolean-mask packed gather (data-dependent shape => implicit
nonzero D2H), serializing the CPU behind the previous verify step. The
draft-forward host planning bound (seq_lens_cpu) is now computed on CPU
from the scheduler-maintained host lens via the monotonic envelope
min(len, window+page) instead of a blocking D2H. The exact page-align
mapping is a non-monotonic sawtooth, so the envelope (not a mirror of the
arithmetic) is required to stay an upper bound when fed the reserved
overlap over-estimate. Legacy path kept only for non-GPU-triton platforms.

2) Extend _DflashDraftSampler to the vocab-parallel (TP>1) head and lift
the tp>1 eager bail: per-rank shard max/argmax -> global id, two NCCL
all-gathers (captured into the draft graph like the draft model's own
collectives), first-max select. Tie resolution is bit-exact vs a
full-vocab argmax (contiguous ascending shards + first-max argmax).
A/B escape hatch: SGLANG_DFLASH_EAGER_DRAFT_SAMPLER=1 forces eager.
Removes the eager between-graphs sampler cluster (matmul + reduce +
2x all_gather + gather) from the host launch path.
decide_needs_cpu_seq_lens ORs the flag across attn backends; the hybrid
prefill/decode wrapper had no attribute so the getattr default (True)
forced FutureMap.resolve_seq_lens_cpu into its per-step pinned D2H +
fwd_prepare_d2h_stream.synchronize() even when both sub-backends opted
out (trtllm_mla prefill + cutedsl_mla decode). That host sync sits before
any of step N's launches and blocks on step N-1's verify completing on
GPU, forcing zero CPU run-ahead on the hybrid arm.
DFlashDraftInputV2.filter_batch sliced reserved_seq_lens_cpu with
new_indices.cpu(), a blocking D2H of the GPU index tensor on the
scheduler thread every time batch composition changed. ScheduleBatch
already holds the host-side keep list; pass it through and index the CPU
tensor directly. EAGLE/ngram accept the kwarg unchanged.
…prep churn

- init_forward_metadata: never derive max_seq from the GPU tensor (the
  .max().item() drains the whole stream backlog under spec-v2 overlap);
  fall back to the static context bound when no host mirror exists.
- DCP eager paths: set dcp_local_max_seq_len / dcp_prefix_local_max
  host-side (ceil(global/world) bound covers get_dcp_lens on every rank),
  so forward_decode/_forward_verify_dcp never hit the per-layer
  local .max().item() device sync (61 syncs/step on Kimi) off-graph.
- _apply_cuda_graph_metadata target-verify: fuse the seq_lens+T add
  straight into the captured int32 seq_lens_k buffer (out= same-kind
  downcast) and feed that buffer to the block-table kernel: one kernel,
  no per-step temp alloc.
- WAR fastpath: reuse a 2-deep event ring instead of allocating a fresh
  cuda Event per graph replay (DFlash records twice per step).

677d454 to
361a7e8
Compare
…comments further, add unit tests

- SGLANG_DFLASH_EAGER_DRAFT_SAMPLER moves to the typed envs registry.
- Second comment pass: keep only the load-bearing invariants (sawtooth
  envelope, tie-safety, needs_cpu_seq_lens OR-default trap, re-record
  safety, legacy-path sync rationale).
- test_dflash_overlap_hostsync.py: fused rebuild bit-exact vs legacy path
  (+ no write past the verify block), vocab-parallel sampler == full-vocab
  argmax incl. shard-boundary ties (simulated TP group, single GPU),
  host-bound envelope >= exact incl. the sawtooth counterexample,
  HybridAttnBackend needs_cpu_seq_lens delegation, filter_batch host
  keep-list equivalence.

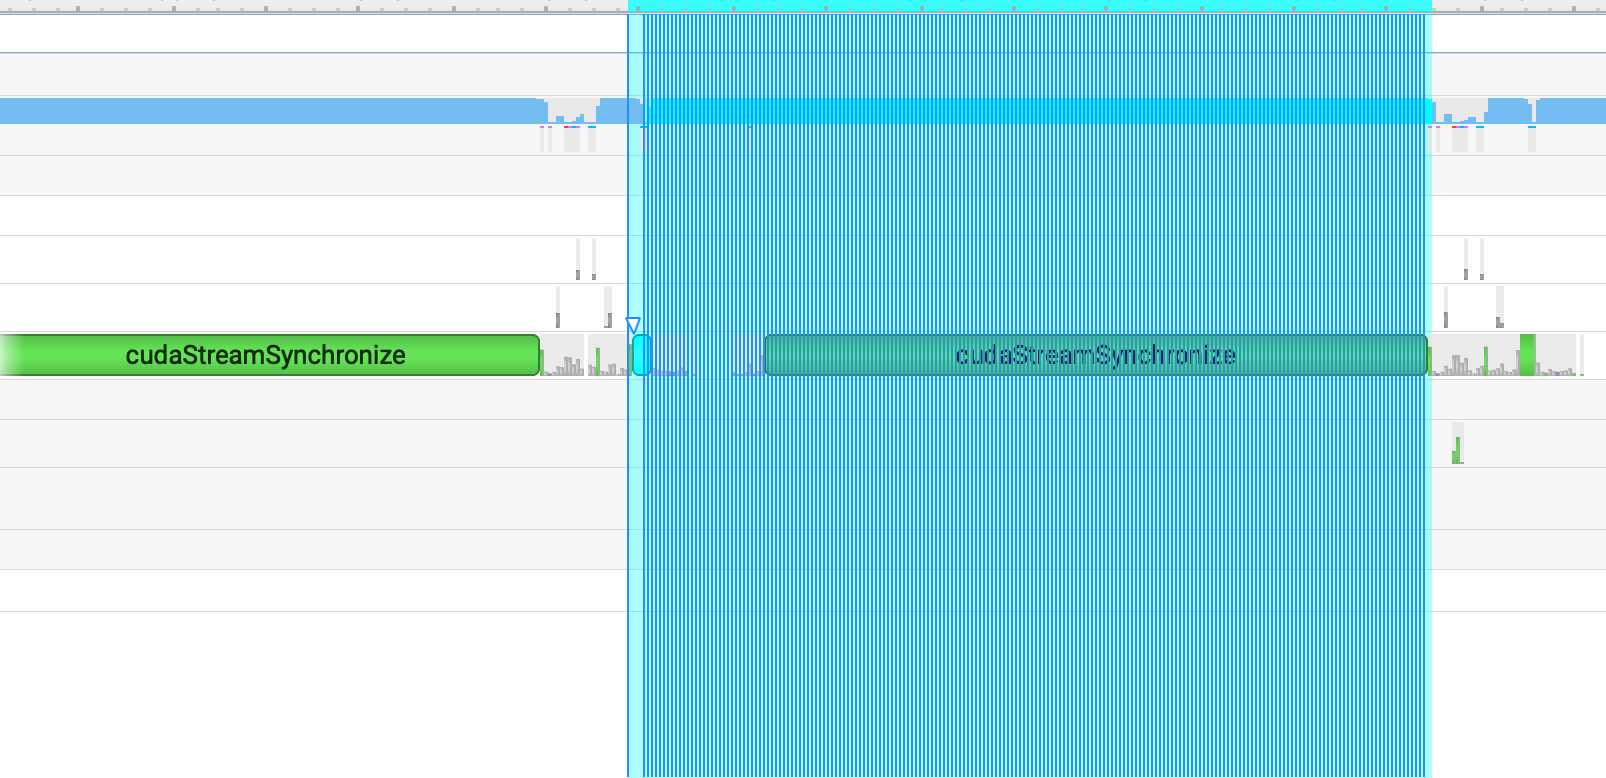
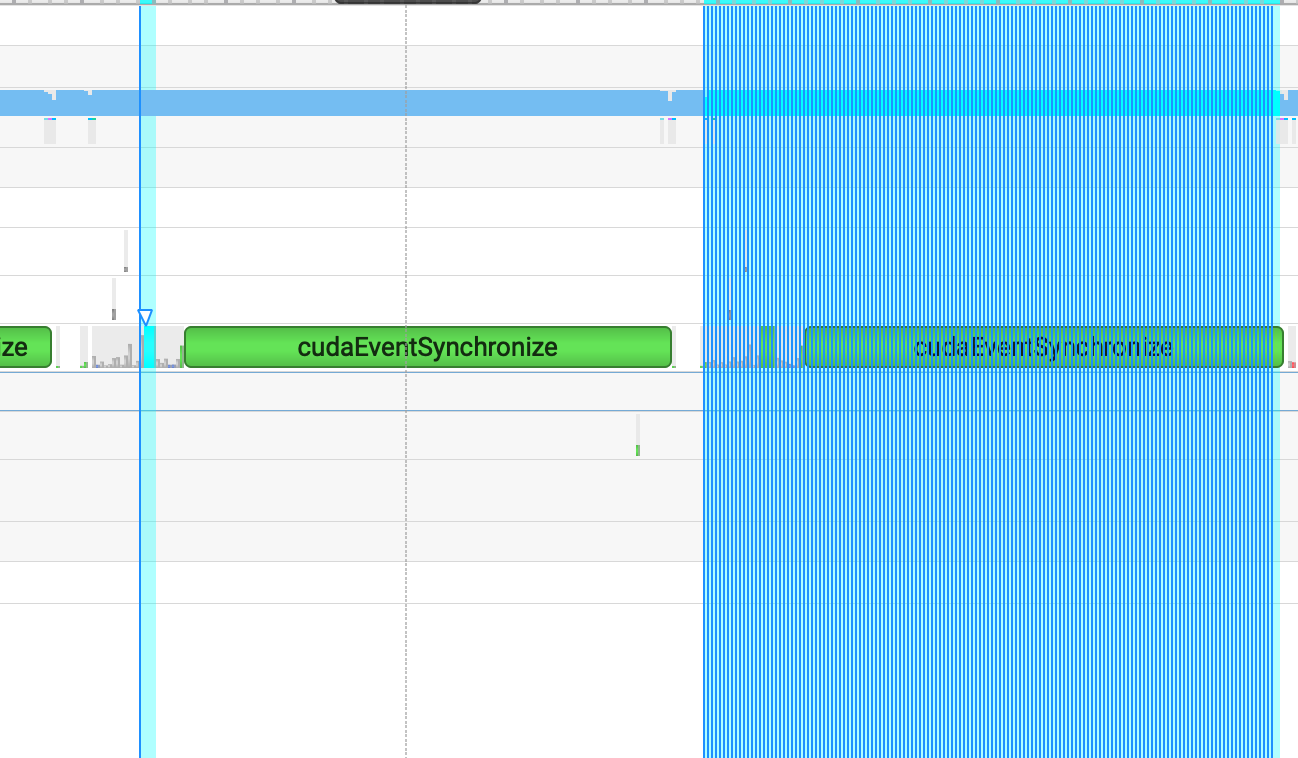
nsys before/after — the overlap improvement, Kimi-K2.6-NVFP4 cuteDSL, cc16BEFORE (main 40a3bd7):
AFTER (this PR):
|


|
/rerun-test registered/unit/spec/test_dflash_overlap_hostsync.py registered/spec/dflash/test_dflash.py registered/core/test_basic_sanity_dflash.py registered/spec/eagle/test_spec_eagle.py registered/spec/test_spec_ngram.py registered/attention/test_hybrid_attn_backend.py registered/attention/unittests/mla/test_trtllm_mla.py |
|
/tag-and-rerun-ci |

|
|
Results for 🚀 🚀 🚀 |
|
@thanhhao98 I reverted the Could you resubmit the event-ring change as a separate PR covering all the per-step |
|
/rerun-failed-test |


|
Thanks @hnyls2002 @kpham-sgl for pushing this. I removed event-ring in PR description. |


… ahead (spec-v2 overlap) (sgl-project#31468)

Co-authored-by: Hao Phan <htphan@nvidia.com>

… ahead (spec-v2 overlap) (sgl-project#31468)

Co-authored-by: Hao Phan <htphan@nvidia.com>
… ahead (spec-v2 overlap) (sgl-project#31468)

Co-authored-by: Hao Phan <htphan@nvidia.com>

… ahead (spec-v2 overlap) (sgl-project#31468)

Co-authored-by: Hao Phan <htphan@nvidia.com>
3 participants


Motivation
Under spec-v2 overlap scheduling, DFlash stalls the host every decode step: nsys shows a large
cudaStreamSynchronizebetween the draft and verify cuda graphs, socudaGraphLaunchfor step N+1 is only issued after step N has finished (launch lead ≈ −50 µs). EAGLE3 spec-v2 runs a full step ahead; DFlash should too. This PR removes every per-step host↔device sync on that path. Result: the CPU queues step N+1 a full step early (launch lead +19 ms, run-ahead fraction 0.88 → 0.995), worth +12–13% tok/s/user at low concurrency and +3–5% at high, with GSM8K and accept-length unchanged.Modifications
Each item removes one per-step host block:
Compact draft-cache rebuild → one triton kernel (
rebuild_compact_draft_req_to_token). The old rebuild synced three times per step (lengths.max().item(), a boolean-mask gather's implicitnonzeroD2H, and a blocking.to("cpu")), each waiting on the previous verify step. The kernel writes the suffix window + verify-block slots directly into the draftreq_to_tokenrow with no data-dependent shapes. The hostseq_lens_cpuplanning bound becomesmin(len, window+page)— deliberately an envelope, not a mirror of the exact page-align math, which is a non-monotonic sawtooth and would under-shoot when fed the reserved over-estimate.HybridAttnBackend: OR-delegateneeds_cpu_seq_lensto the sub-backends. The missing attribute defaulted to True, forcingFutureMap.resolve_seq_lens_cpu's pinned D2H +stream.synchronize()before every step's launches — zero run-ahead on hybrid arms even when both sub-backends opt out.Fold the TP>1 draft greedy sampler into the draft cuda graph (tp=1 fold already existed): per-rank shard (max, global id) → two in-graph NCCL all-gathers → first-max select. Bit-exact vs a full-vocab argmax including shard-boundary ties.
SGLANG_DFLASH_EAGER_DRAFT_SAMPLER=1restores the eager path.Correctness
test/registered/unit/spec/test_dflash_overlap_hostsync.py): kernel bit-exact vs the legacy path (incl. no writes past the verify block), sampler == full-vocab argmax incl. a shard-boundary tie, the sawtooth-envelope bound with its counterexample, hybrid flag delegation, filter_batch host-list equivalence.Benchmarks (Kimi-K2.6-NVFP4 + DFlash draft, 8×B200 TP=8, aiperf 50K-prefix)
Same-base A/B, identical stack, only this PR's commits differ:
40a3bd76nsys (cc16, same pair): launch lead median −51 µs → +19.1 ms; run-ahead fraction 0.883 → 0.995; per-thread
cudaStreamSynchronize336×/3816 ms → 9×/11 ms. The only remaining per-step host sync is the intendedcopy_donein result processing (identical to EAGLE3 spec-v2). Same shape on the tokenspeed_mla arm (K2.7: +11.5% cc1, lead −57 µs → +17.1 ms); details in the PR comments.Checklist
test/registered/unit/spec/test_dflash_overlap_hostsync.py, 7 tests, validated on B200).🤖 Generated with Claude Code
CI States
Latest PR Test (Base): ⏳ Run #29632179798
Latest PR Test (Extra): ❌ Run #29632179752