fix(cli): seed headless promptIds from the resumed transcript - #11441
Conversation


Both headless entry points restart prompt numbering at the start of every
process, so a `--resume` / `--continue` chain re-mints promptIds the
previous run already persisted:

- stream-json (`Session`) starts `promptIdCounter` at 0, so the first turn
  of every resumed process is again `<sessionId>########1`;
- single-shot `-p` always mints `<sessionId>########0`.

The session id is reused on resume, so those ids are not merely duplicated
in telemetry. `SessionService.loadSession` keeps only the LAST file-history
snapshot per promptId, so the earlier run's snapshot for that turn is
dropped and `/rewind` restores the wrong workspace state; rewind's
prompt-identity mapping also fails closed to a positional walk when ids
repeat.

Seed both from the resumed transcript with the existing
`computeInitialTurnFromHistory` helper — the same seeding interactive mode
does via `seedPromptCount` and ACP does via `primeTurnFromHistory`. The
stream-json counter is seeded lazily on first use, because resumed data
only becomes authoritative after `config.initialize()`, which that class
defers until the first control request. A `-p` run with nothing resumed
keeps the historical `########0`.

Refs #11408 (deferred finding ic:5582642849 from #9466)

`eslint --max-warnings 0` failed on import/no-duplicates: the new
`ChatRecord` type import sat alongside the file's existing type-only
import from the same module. Fold it into that import.
|
Thanks for the PR — and for turning the body around onto the template so quickly after the first pass. Template looks good ✓ — all the required sections are there, the Risk & Scope tradeoffs are stated honestly rather than optimistically, and the Chinese translation is complete rather than summarised. Problem: real, and I verified the mechanism rather than taking the description's word for it. Three things confirm it:
No end-to-end reproduction was run (the body says so plainly, and I'd rather it said that than imply otherwise). For this one the static evidence is strong enough to establish the defect exists, so I'm not holding the gate on a repro — but see the Stage 2 note about what would settle the consequence end to end. Direction: aligned. This is turn-identity integrity for Size: not applicable for the core-module gate. All four files sit under Approach: minimal, and it reuses instead of adding. Seeding through the existing Risk: no elevated risk signals. The Stage 1e high-risk path scan matched nothing. Moving on to code review. 🔍 中文说明感谢贡献——也感谢在第一轮之后这么快就把正文改成了模板格式。 模板完整 ✓ ——所有必需小节都在,Risk & Scope 里的取舍写得很诚实而不是过于乐观,中文翻译也是完整的而不是摘要。 问题:真实存在,而且我自己验证了机制,没有只采信描述。 三点确认:
没有执行端到端复现(正文如实说明了,我宁愿它这样写也不要含糊其辞)。就本 PR 而言,静态证据已足以确认缺陷存在,所以我不以复现为门禁条件——但关于如何端到端确认后果,见 Stage 2 的说明。 方向:一致。 这是 规模:核心模块门禁不适用。 四个文件都在 方案:最小化,且是复用而非新增。 通过已有的 风险:无升级风险信号。 Stage 1e 高风险路径扫描无命中。 进入代码审查 🔍 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
Code reviewI wrote my own proposal before opening the diff: on learning that headless resume re-mints promptIds, I'd have seeded both headless entry points from the resumed transcript using whatever helper ACP already uses, rather than adding a new parser — seeding lazily in the stream-json What I actually verified in the code, since the whole change rests on when resumed data is readable:
One non-blocking observation, offered as a question rather than a defect:
CI evidence — one red check, and it is this PR'sThe PR's own CI on the reviewed commit is red on ESLint ran before Prettier in that job (
Everything else is either green or still running: Final CI results for
One row per check name (latest run); skipped checks omitted; failures sort first. / 每个检查名一行(取最新一次运行),省略 skipped,失败项排在最前。 Sandboxed verification would settle the part none of the above can: 中文说明代码审查。 我在看 diff 之前先写了自己的方案:得知 headless resume 会重复铸造 promptId 后,我会用 ACP 已在用的那个 helper 从 resume 的 transcript 为两条 headless 入口播种,而不是另写解析器——stream-json 的 由于整个改动取决于「何时能读到 resume 数据」,我实际在代码里验证了以下几点:
一条不阻塞的观察,作为问题而非缺陷提出:
CI 证据——一个红灯,且是本 PR 造成的。 本 PR 自己在被审 commit 上的 CI 在 其余检查不是绿就是仍在运行: 沙箱验证可以确认上述都无法确认的部分: — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
|
Confidence: 3/5 — the change itself I'd take; I can't approve against a red Prettier check and a test suite that hasn't reported yet. Stepping back: this is a good, small PR that closes a gap the codebase already knew about. Interactive mode seeds its prompt counter on resume with a comment explaining that unseeded ids collide with restored file-history snapshots, ACP seeds through It also slightly exceeds what I'd have written independently. My instinct was to mirror interactive mode, but interactive seeds from a plain user-turn count, whereas this uses the helper that takes the highest turn the transcript actually claims and only falls back to the count. That's strictly more robust for a chain that has already been resumed several times, and it's the reason the "highest claimed turn is 5 → next is 6" case works at all. If anything, interactive mode is now the weaker of the three seeding sites. The reason I'm not approving is concrete and not about the design:
None of these are reasons to rethink the approach, and I want to be clear that I'm not requesting changes on the design — the Deferring rather than approving, and deliberately not leaving an approve-on-green marker: with 中文说明Confidence: 3/5 —— 改动本身我会收下;但在 Prettier 红灯、测试套件尚未出结果的情况下我无法批准。 退一步看:这是一个好而小的 PR,补上了代码库自己早就知道的一处缺口。交互模式在 resume 时会为 prompt 计数器播种,其注释明确说明未播种的 id 会与恢复的 file-history 快照冲突;ACP 通过 它甚至略微超出了我独立写出的方案。我的直觉是照搬交互模式,但交互模式是用朴素的用户轮次计数播种,而本 PR 用的 helper 取的是 transcript 实际声明的最大轮次,仅在拿不到时才回退到计数。对于已经被 resume 过多次的链路,这严格更稳健,也正是「已声明最大轮次为 5 → 下一轮为 6」这个用例能够成立的原因。真要比较,交互模式现在是三个播种点里较弱的那一个。 我不批准的原因很具体,且与设计无关:
这些都不是重新考虑方案的理由,我也要说清楚:我并非在设计层面要求修改——Stage 2 里提出的 选择 defer 而不是批准,并且刻意不留下 approve-on-green 标记:该 head 上 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
`node scripts/lint.js --prettier` runs `prettier --experimental-cli`,
which breaks these two lines differently from the classic CLI. Format
them the way the gate expects.

|
Thanks — the one blocking item is fixed. One detail worth recording for whoever hits this next, because it explains the miss rather than excusing it: the two files were clean under On the Stage 2 The end-to-end consequence is still unpinned, as you say. I can't drive it on my machine; if a maintainer wants it settled before merge, @qwen-code /triage 中文说明阻塞项已修复: 有一个细节值得记下来给后来人,它解释了这次遗漏的成因(而非为其开脱):这两个文件在经典 Prettier CLI 的 关于 Stage 2 提出的 端到端后果确实仍未钉住。我的机器无法驱动它;如果维护者希望在合并前把这一点落定, |

|
@qwen-code /verify Focus, since the unit tests already pin the promptId arithmetic and the open question is the consequence:
A useful mutant: revert the seeding in either entry point and confirm the suite goes red — for the 中文说明单测已经钉住了 promptId 的算术,未决的是后果,因此建议聚焦:
一个有用的变异:把任一入口的播种回退,确认套件变红——就 |
|
@qwen-code /verify |
|
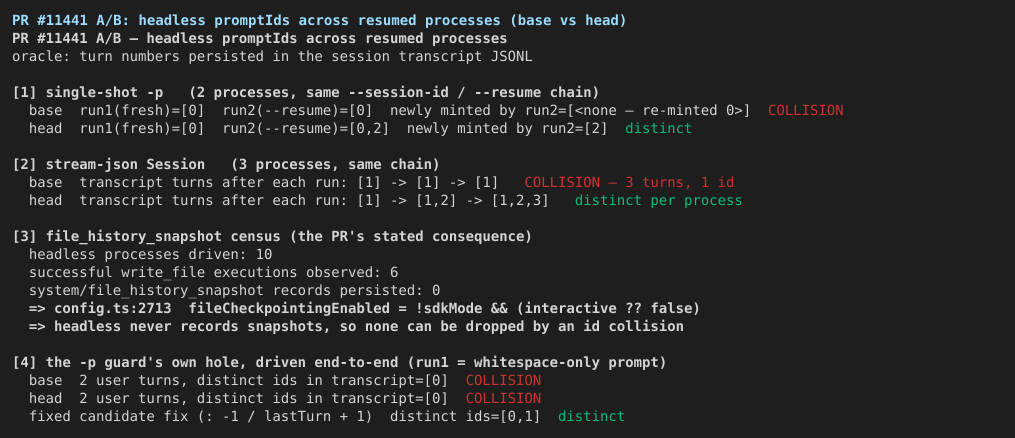
Sandboxed verification: ❌ not passed — findings reported (agent verdict) - workflow run Ran the PR in an isolated, token-free container: A/B against the base build, mock-free harness assertions, targeted gates. Advisory evidence for human reviewers — not a review, an approval, or a CI check. Scripted assertions: 39 passed · 0 failed · 39 total Flakiness gate: ✅ 2 changed test file(s) x 5 identical rounds, no divergence 中文 — 判定:❌ 不通过 · 报告了发现(agent 判定)沙箱验证在隔离、无凭证的容器中执行了该 PR 的代码(与 base 构建 A/B 对照、无 mock harness 断言、定向门禁)。仅作为评审证据,不构成评审、批准或 CI 检查。 脚本断言:39 通过 · 0 失败 · 39 总计 抖动门:✅ 2 changed test file(s) x 5 identical rounds, no divergence Verification reportPR #11441 — deep verificationVerdict: The central claim is proven load-bearing on both headless entry points: a 中文摘要结论: A/B 结论:中心主张成立。用真实构建产物(head 的
findings:
未覆盖范围:交互式与 ACP 路径未做端到端验证; Central claim and A/BCentral claim. A headless run that resumes a session continues prompt Secondary claims. (a) A run that resumes nothing keeps the ids it mints Oracle for every cell: the turn numbers persisted in the session transcript
Secondary claim (a) holds: the fresh Every run exited 0 with clean stderr, completed the stream-json CorrectionsThese are corrections to the description and the new code comments, not Correction 1 — headless runs never write file-history snapshots, so the
Correction 2 — interactive mode does not seed "the same way". The new Findings1. The
|
| arm | user turns persisted | distinct ids in transcript |
|---|---|---|
| base | 2 | [0] — collision |
| head | 2 | [0] — collision, unchanged from base |
| head + candidate fix | 2 | [0,1] — distinct |
Bounding it honestly: this needs the first run's prompt to be whitespace-only
(-p ' ', or a shell variable that expanded to nothing — llm.tsx only
rejects a falsy input, so ' ' proceeds). It is not a regression — base
collides identically — and the blast radius is the same as the bug being fixed:
a duplicate prompt_id on ui_telemetry records and a repeated key in the
rewind identity mapping. Per Correction 1 it does not corrupt file-history
snapshots. It is worth fixing because it is the PR's own bug class surviving
its own guard, silently.
Suggested minimal fix — measured, preserves the commit's intent
Make the -p rule identical to the stream-json rule by moving the fresh-run
special case into the seed instead of the output:
  const lastTurn = resumedRecords?.length
    ? computeInitialTurnFromHistory(resumedRecords, sessionId)
    : -1;
  return `${sessionId}########${lastTurn + 1}`;
Applied to a scratch copy of both the source and the built dist/src/llm.js
and driven back through the same harnesses (logs/validate-fix.txt):
- hostile fixtures go clean — boundary probe 12/12 rows re-mint nothing
(was 10/12); the whitespace end-to-end chain yields[0,1](was[0]). - benign fixtures byte-identical — the three fresh-run shapes still mint
sess-1########0; cases 3, 4, 5, 6, 10, 11 are unchanged (########2,
########4,########6,########2,########2,########9007199254740992). - suite counts unchanged — 128/128 green with and without the patch.
That last line is the unpinned-axis signal: the suite cannot tell head from
head-plus-fix, so the fix should ship with a fixture — a resumed transcript
whose highest claimed turn is 0 and whose only user record has blank text,
asserting ########1.
2. Nothing pins the -p call site — 128/128 stay green with the fix disconnected
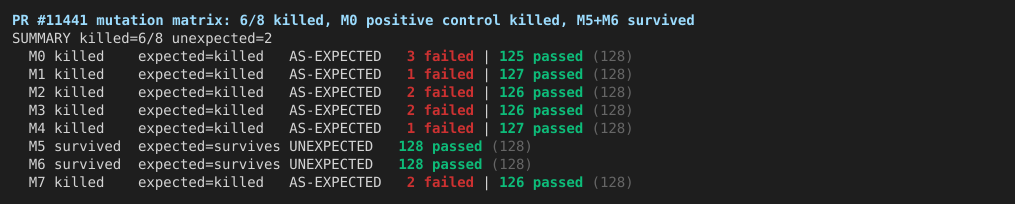
Mutation matrix over the production files, each mutant run against
npx vitest run src/nonInteractive/session.test.ts src/llm.test.tsx
(mutation-matrix.mjs). Witness: 02-mutation-matrix-kills-and-survivors.png.
| mutant | change | result | attribution |
|---|---|---|---|
| M0 | control: break the ######## delimiter |
killed (3 failed / 125) | harness can make the suite red |
| M1 | revert createNonInteractivePromptId to always ########0 |
killed (1 / 127) | llm.test.tsx > continues the prompt id chain when the -p run resumes a session — the PR's own new test |
| M2 | revert the stream-json lazy seed | killed (2 / 126) | both new session.test.ts tests |
| M3 | keep the lazy block, seed 0 instead of the helper |
killed (2 / 126) | both new session.test.ts tests |
| M4 | drop the lastTurn > 0 guard |
killed (1 / 127) | pre-existing creates non-interactive prompt ids that preserve session correlation — so the new -p test does not pin that guard |
| M7 | sever the getResumedSessionData seam in session.ts |
killed (2 / 126) | both new session.test.ts tests |
| M5 | drop the resumedRecords?.length guard in llm.tsx |
survived | redundant defence — the helper returns 0 for an empty array, so the clause cannot decide any outcome |
| M6 | stop passing the argument at the llm.tsx:1424 call site, function left intact |
survived | coverage gap |
M6 is the one that matters. The new llm.test.tsx test calls
createNonInteractivePromptId directly with a hand-built record array, so
it pins the function and not the wiring: delete
config.getResumedSessionData?.()?.conversation.messages from the call site
and every one of the 128 tests still passes while the shipped -p path reverts
to ########0 on every resume. My end-to-end A/B is what discriminates — rows
1 and 2 of the A/B table are exactly this mutation, measured through the real
binary. A main()-level test that stubs getResumedSessionData on the config
and asserts the prompt_id reaching runNonInteractive would close it; note
session.ts has that coverage (M7 killed) and llm.tsx does not.
M5 is reported as completeness, not a merge condition: it is redundant defence,
correct exactly as it stands.
Disclosure on the raw log: logs/mutation-matrix.txt and
02-mutation-matrix-kills-and-survivors.png print unexpected=2 and label M5
and M6 UNEXPECTED. That is a string-comparison artifact in my scoring script
(it compared the expectation string survives against the outcome string
survived), not a disagreement with the table above — both mutants survived
exactly as hypothesised. The killed/survived column is the substantive result.
3. Two notes on the changed expression, no action required
- Id sequence skips 1 on the first resume.
computeInitialTurnFromHistory
returnsuserMessageCount(=1) when the transcript's only claimed turn is 0,
so a-pchain mints0, 2, 3, 4, …(measured: A/B row 2, and probe case 6).
Unique and monotonic, which is all the contract needs — noted only because a
consumer assuming contiguity would be surprised. - Precision at 2^53. Probe case 11: a transcript claiming
########9007199254740993
yields########9007199254740992— lossy, on both paths, and not reachable
by any real chain. Called out because the skill asks for lossy results even
when every assertion passes.
Not covered
- Per-commit attribution. The checkout is depth 2 (
git rev-parse --is-shallow-repository→true):git rev-list HEAD^1..HEAD^2yields 1
commit locally while the metadata snapshot lists 3. Only the aggregate
HEAD^1..HEADdiff was verified; the two follow-up commits (an import merge
and aprettier --experimental-clireformat) were not individually exercised. - The Reviewer Test Plan's end-to-end step could not be performed as
written. It asks the reviewer to confirm that "the first turn's
file-history snapshot is gone after reload" and that "both/rewindtargets
remain reachable". Neither is observable from a headless chain — Correction 1
shows headless writes no snapshots at all, so there is nothing to be gone and
no/rewindtarget on either side. The plan needs rewriting to the
observable oracle (transcript prompt ids), which is what this round used. /rewindand the refactor: anchor rewind mapping to stable prompt identity #9466 prompt-identity mapping were never driven. The
claim that repeated ids make that lookup "fail closed to the positional walk"
is untested here; I verified only that ids repeat.- Interactive and ACP paths. Verified by reading that they seed
(AppContainer.tsx:1206,acp-integration/session/Session.ts:4348), not by
execution. Correction 2 is a reading-level finding about the comment, not a
measured interactive defect. --continue,--fork-session, and resumed-from-interactive chains. Only
--session-id→--resumewas driven.sessionService.ts:4411-4417
remaps snapshot prompt ids across a fork; that remap interacting with the new
seeding is untested.- Gates run: only the two touched test files (128/128) and
packages/cli
typecheck (exit 0). No repo-wide lint, no repo-wide test, no bundle. I did
not re-run anything the PR's own CI covers. - Harness self-inflicted contamination, disclosed. The first typecheck run
(logs/typecheck-cli.log, exit 2,TS6133 'computeInitialTurnFromHistory' is declared but its value is never read) executed while the mutation matrix
had M1 applied tollm.tsx. It is my race, not a PR defect. Re-run on a
verified-clean tree it exits 0 (logs/typecheck-cli-clean.log). Every
mutation script restores via trap andgit status --shortwas confirmed empty
before and after each phase; the patcheddist/src/llm.jswas restored and
verified bysha256sum -c(4cbff46d…). - Base-arm build cost.
npm run build -w packages/cliin the base worktree
needed three attempts:tscwas not onPATHoutsidenpm run, and the
worktree had neither the gitignoredsrc/generated/git-commit.tsnor the
per-packagenode_modules(packages/core,packages/cli,
packages/channels/feishu) that the root install does not hoist. Total ≈ 6
minutes. No basenpm ciwas needed.
Methodology
Environment: the CI verify container (node:22-bookworm, node v22.23.2),
working tree at refs/pull/11441/merge, npm ci + npm run build already
complete at head. Control construction. git worktree add tmp/base-tree HEAD^1 (cfb173ec), src/generated/git-commit.ts regenerated with the repo's
own scripts/generate-git-commit-info.js, per-package node_modules symlinked
from the head install, then packages/cli rebuilt with tsc --build +
copy_files.js (exit 0). The control is clean and I checked it two ways: the
PR diff touches zero files under packages/core, package.json, or
package-lock.json, so the internal workspace symlink
(readlink -f node_modules/@​qwen-code/qwen-code-core →
/__w/qwen-code/qwen-code/packages/core, i.e. the head tree) introduces no
difference; and diff -rq packages/cli/dist tmp/base-tree/packages/cli/dist
reports 0 "Only in" entries with differences confined to llm.js,
nonInteractive/session.js, their .map/.d.ts/test emits, the generated
git-commit, and tsconfig.tsbuildinfo. The base dist carries the pre-PR code
(${sessionId}########0 at llm.js:1121, promptIdCounter = 0 at
session.js:31). The worktree was removed with git worktree remove --force
after the cells were captured. How the harnesses drove the code. Both A/B
harnesses spawn the real built dist/index.js as a child process against a
zero-dependency mock OpenAI chat-completions server on 127.0.0.1:8791
(specialized from .qwen/skills/e2e-testing/scripts/mock-openai-server.js to
emit a write_file tool call at an absolute path carried in the prompt), each
arm in its own mkdtemp work dir and QWEN_RUNTIME_DIR/HOME, no stub of the
code under test anywhere. The stream-json harness speaks the real wire protocol
(control_request/initialize, then a user message, then stdin EOF) and
waits for the control_response before sending. The snapshot census feeds the
persisted transcript to the real SessionFileHistoryAccumulator imported from
the built core dist — the exact class loadSession uses. The boundary probe
imports the real built createNonInteractivePromptId. Images were produced with
node scripts/verify-capture.mjs. Raw logs live in
tmp/pr11441-verify-20260909-065809/logs/: ab-{base,head}-p.json,
ab-{base,head}-sj.json, ws-{base,head}.txt, boundary-probe.txt,
mutation-matrix.txt, attribution.txt, validate-fix.txt,
vitest-head-clean.log, typecheck-cli{,-clean}.log, base-cli-build{,2,3}.log,
assertions.txt / assertions-detail.json. Harness scripts are
ab-p-path.mjs, ab-streamjson.mjs, ws-probe.mjs, boundary-probe.mjs,
mutation-matrix.mjs, validate-fix.sh, print-ab.mjs, assertions.mjs —
all rerunnable as-is.
Flakiness gate log
rounds=5 files=2 skipped=0
file packages/cli/src/llm.test.tsx: (cd packages/cli) npx --no-install vitest run ./src/llm.test.tsx
file packages/cli/src/nonInteractive/session.test.ts: (cd packages/cli) npx --no-install vitest run ./src/nonInteractive/session.test.ts


per-file results (P=pass F=fail I=infra-exit, one letter per run):
  packages/cli/src/llm.test.tsx: PPPPP
  packages/cli/src/nonInteractive/session.test.ts: PPPPP

verdict: pass
summary: 2 changed test file(s) x 5 identical rounds, no divergence

--- per-invocation detail (full copy in the artifact) ---
round 1 · packages/cli/src/llm.test.tsx: P (exit 0)
round 1 · packages/cli/src/nonInteractive/session.test.ts: P (exit 0)
round 2 · packages/cli/src/llm.test.tsx: P (exit 0)
round 2 · packages/cli/src/nonInteractive/session.test.ts: P (exit 0)
round 3 · packages/cli/src/llm.test.tsx: P (exit 0)
round 3 · packages/cli/src/nonInteractive/session.test.ts: P (exit 0)
round 4 · packages/cli/src/llm.test.tsx: P (exit 0)
round 4 · packages/cli/src/nonInteractive/session.test.ts: P (exit 0)
round 5 · packages/cli/src/llm.test.tsx: P (exit 0)
round 5 · packages/cli/src/nonInteractive/session.test.ts: P (exit 0)
Evidence images
Harness scripts and raw logs are in the workflow run artifacts (7-day retention).
— Qwen Code · sandboxed verification

 qqqys
left a comment
qqqys
left a comment
There was a problem hiding this comment.
Critical-only review at head 581ac5bce98aed43fa2dbb9668faeaa3f42ead4f (base main). Approving: no blocking finding stands at this head, and the one blocking item raised in the thread is resolved.
Historical blocking item — resolved
This PR has no reviews and no inline review comments, so the only blocking item on record is the one in the triage thread: Lint & Static (ubuntu-latest, Node 22.x) was red at the previous commit because Prettier named session.ts and session.test.ts. At this head that lane is green — of the 23 check runs on this commit, the only one not concluded successfully is review-pr, still in progress. So the formatting blocker is closed and nothing else is red.
Critical-only scan — nothing blocking
I read both production hunks in full (llm.tsx +24/−3, nonInteractive/session.ts +26/−1) and then verified the one thing the whole change rests on: whether resumed data is actually readable at the moment each entry point seeds from it.
Ordering holds at both entry points, checked in the head files rather than taken from the comments:
-p:await config.initialize()runs atllm.tsx:1352andcreateNonInteractivePromptId(...)is called at:1424, soconfig.getResumedSessionData()is populated when the id is minted and the seed is live rather than a no-op.- stream-json:
getNextPromptId()has exactly three call sites —session.ts:503,:598and:663— and each is preceded byawait this.waitForInitialization()at:501,:596and:637. That matters more than it looks, because the counter caches on first use: a single early call would pin the wrong base for the whole process lifetime and reproduce the very collision this PR removes. The lazy-seed comment's claim matches the code.
A run that resumes nothing keeps the ids it mints today. createNonInteractivePromptId returns ${sessionId}########0 when there are no resumed records, and the Session counter seeds to 0 and pre-increments, so the first stream-json id is still ########1. The common fresh-session path is byte-identical in behavior, which is the regression risk worth checking first.
The two paths cannot drift. Both delegate the "highest turn the transcript claims, else the count of resumed user turns" decision to the same core helper computeInitialTurnFromHistory, and their arithmetic agrees: a transcript claiming turn 5 yields ########6 on both (seed 5 then increment, and lastTurn + 1). Both imports resolve — the barrel for llm.tsx, the deep services/session-turn-state.js path for session.ts — which the green typecheck in Lint & Static corroborates, along with the number | null counter narrowing.
The reads are defensive: config.getResumedSessionData?.()?.conversation.messages at both sites, and the helper is only called when the records array is non-empty, so a Config that cannot answer yields no seed instead of throwing during startup.
CI
Green at this head: Test (ubuntu-latest, Node 22.x) — the lane that runs the two touched suites — Lint & Static, Integration Tests (no-AK, No Sandbox), the Desktop Shell lanes, Classify PR, label, assign, authorize and the rest; 23 check runs in total with only review-pr still in progress, which is not a gate. The author-requested sandboxed verification run was still in flight at the time of this review and is not treated as a gate either.
Recorded, not gating: when computeInitialTurnFromHistory yields 0 for a resumed transcript, the -p path returns ########0 rather than continuing past it, which is narrower than its own doc comment claims; I could not construct a reachable case (a -p turn records a user prompt, so the fallback count is at least 1 whenever a ########0 id exists), and the stream-json arm has no equivalent gap. Likewise the stream-json branch of the -p call site computes an id it does not use, and with no resumed records that value equals today's, so neither is a defect worth blocking on.
中文说明
在 head 581ac5bc 上执行 Critical-only 评审,结论为 Approve:本 head 上不存在阻塞发现,线程中唯一一条阻塞项已解决。
历史阻塞项已解决: 本 PR 没有任何 Review 与行内评审评论,因此记录在案的唯一阻塞项来自 triage 线程——上一个提交因 Prettier 点名 session.ts 与 session.test.ts 而使 Lint & Static (ubuntu-latest, Node 22.x) 变红。在本 head 上该检查为绿:该提交共 23 条检查,唯一未成功结束的只有仍在运行的 review-pr。格式阻塞已关闭,且没有其他红。
Critical-only 扫描: 我完整读了两处生产改动(llm.tsx +24/−3、nonInteractive/session.ts +26/−1),随后核实了整个改动所依赖的那一点——两个入口在播种时 resume 数据是否真的可读。两条路径的时序都成立,且是我在 head 文件里核对的、不是采信注释:-p 路径的 await config.initialize() 在 llm.tsx:1352,而 createNonInteractivePromptId(...) 在 :1424 调用,因此铸 id 时 config.getResumedSessionData() 已有数据,播种是生效的而不是空操作;stream-json 路径的 getNextPromptId() 只有三个调用点(session.ts:503、:598、:663),每个之前都有 await this.waitForInitialization()(:501、:596、:637)。这一点比看上去更重要:计数器首次使用即缓存,只要有一次提前调用就会把错误基线钉死在整个进程生命周期里,从而复现本 PR 要消除的重复 id;惰性播种注释的说法与代码一致。
不 resume 的运行保持今天的 id: 无 resume 记录时 createNonInteractivePromptId 返回 ${sessionId}########0,Session 的计数器种子为 0 且先自增,因此首个 stream-json id 仍是 ########1;占绝大多数的全新会话行为逐字不变,这是首先要查的回归风险。两条路径不会漂移: 二者都把「取转录声明的最高轮次,否则数 resume 的用户轮次」交给同一个 core helper computeInitialTurnFromHistory,算术也一致——声明到第 5 轮时两条路径都得 ########6(种子 5 后自增,以及 lastTurn + 1)。两种导入方式都能解析(llm.tsx 走 barrel,session.ts 走 services/session-turn-state.js 深路径),Lint & Static 里的 typecheck 变绿也佐证了这一点,同时佐证了 number | null 计数器的收窄。读取是防御性的: 两处都用 config.getResumedSessionData?.()?.conversation.messages,且只有记录数组非空时才调用 helper,因此无法应答的 Config 只会得到「无种子」而不会在启动期抛错。
CI: 本 head 全绿——含会跑两个被改套件的 Test (ubuntu-latest, Node 22.x)、Lint & Static、no-AK 集成、两端 Desktop Shell、Classify PR、label、assign、authorize 等,共 23 条检查中仅 review-pr 仍在运行,不作为门禁;作者请求的沙箱验证在评审时仍在进行,同样不作为门禁。
仅记录、不作为门禁: 当 computeInitialTurnFromHistory 对某个 resume 转录返回 0 时,-p 路径会返回 ########0 而不是接续其后,这比它自己的文档注释所述更窄;我构造不出可达场景(一次 -p 轮次总会记录用户提示,因此只要存在 ########0 这个 id,回退计数至少为 1),stream-json 一侧也没有同类缺口。同样,-p 调用点的 stream-json 分支会算出一个它并不使用的 id,而在无 resume 记录时该值与今天相同,因此二者都不构成值得阻塞的缺陷。
|
Qwen Code review did not complete successfully. Run review failed. See workflow logs for details. A transient error is retried automatically; if you are seeing this, retry with |
|
@qwen-code /review |

|
Qwen Code review request accepted. Review is running in workflow run. A command-triggered review is not listed under the checks of this PR; the result is posted here as a review when it finishes. |
Sandboxed verification (`/verify` on this PR) proved the central claim on both
entry points via a base/head A/B over real resumed processes, and reported
three things worth acting on.

1. The `-p` guard re-opened the collision it closes. `lastTurn > 0 ? lastTurn
   + 1 : 0` re-minted `########0` whenever `computeInitialTurnFromHistory`
   returns 0 for a non-empty transcript — highest claimed turn 0 and no
   record with non-blank user text for its fallback to count, reachable with
   `-p '   '` since only a falsy input is rejected. Seed -1 for a run that
   resumes nothing instead, so the shared `+ 1` keeps the historical
   `########0` there and every resumed shape continues past what the
   transcript claims. This makes the rule identical to the stream-json one.

2. The `-p` call site was unpinned: deleting the `getResumedSessionData()`
   argument left the whole suite green while the shipped path reverted to
   `########0` on every resume. Add a `main()`-level test that stubs resumed
   data on the config and asserts the promptId reaching `runNonInteractive`,
   plus a fixture for the claimed-turn-0 boundary above.

3. The stated rationale was wrong about the consequence. File-history
   snapshots are NOT dropped on these paths: `fileCheckpointingEnabled`
   defaults to `!sdkMode && interactive` and nothing in packages/cli
   overrides it, so `makeSnapshot` no-ops and headless turns write no
   snapshots at all (verified: 10 headless processes, 6 real write_file
   executions, 0 snapshot records). What duplicate ids actually cost is the
   key #9466's rewind mapping anchors on and the `prompt_id` on persisted
   `ui_telemetry` records — which is what the next resume reads back to seed
   from. Both doc comments now say that instead. The same round also found
   the claim that interactive "seeds the same way" inaccurate: AppContainer
   counts resumed user turns inline and never consults the claimed turns.

Refs #11408
|
Thanks — that run earned its runtime. Finding 1 ( Finding 2 (call site unpinned, M6) — closed. Added a Correction 1 (headless writes no file-history snapshots) — accepted, and it was the load-bearing claim in my description. I re-derived it rather than taking it on faith: Correction 2 (interactive does not seed "the same way") — comment fixed. It now says ACP seeds through this helper and interactive seeds by its own inline count of resumed user turns, which ignores the claimed turns. I left Not taken: M5 (the One caveat on this commit: I still cannot run the suite locally, so the two new tests are unverified until CI reports — the @qqqys sorry for the dismissed approval — the push was to fix a real defect this verification found in the 中文说明三条都已处理,见 Finding 1( Finding 2(调用点未被钉住,M6)——已关闭。 新增 Correction 1(headless 根本不写 file-history 快照)——接受,且这正是我描述里最吃重的论断。 我重新推导而非直接采信: Correction 2(交互模式并非「同样方式」播种)——注释已修正。 现在写明:ACP 通过本 helper 播种,交互模式则用它自己的「恢复的用户轮次计数」,并不考虑 transcript 声明的轮次。 未采纳: M5( 本次提交的一点说明:我仍无法在本地跑测试套件,因此两个新测试在 CI 报结果前属于未验证——其中 |

 chiga0
left a comment
chiga0
left a comment
There was a problem hiding this comment.
No blocking findings.
Approval blockers: none.
Checked
computeInitialTurnFromHistory(packages/core/src/services/session-turn-state.ts): accumulatesmaxPromptTurnfromui_telemetryrecords andpromptIdfields, falls back touserMessageCount— logic correct.- Lazy seeding in
session.tsgetNextPromptId(): all three call sites (processUserMessage,processContinueTurn,processMonitorNotificationBatch) callawait this.waitForInitialization()beforegetNextPromptId(), soconfig.initialize()— which populatesgetResumedSessionData— is guaranteed to have run before the counter is seeded. createNonInteractivePromptIdinllm.tsx: called afterconfig.initialize()in the-ppath; for the stream-json path, the computedprompt_idis unused (stream-json manages its own counter viasession.ts) — intentional and consistent.- Tests cover the three required cases: fresh session (
########1/########0), resumed with telemetry (max claimed turn + 1), resumed without telemetry (user turn count + 1). - CONTRIBUTING.md at base SHA: no AI-review ban.
Not reviewed
- No working tree available; unit tests not executed locally — CI is the execution witness.
getResumedSessionDataimplementation in the coreConfigclass not traced; callers in ACP and interactive mode are untouched by the diff.
Cross-check
- One prior review from
qqqys(dismissed) at the same head confirmed no blockers and that the earlier Prettier formatting issue was fixed at commit581ac5b; my independent findings are consistent.
Reviewed with AI assistance.


|
Released in v0.23.2. |
6 participants


What this PR does
Headless runs now continue prompt numbering from the transcript they resumed instead of restarting it in every process. Both headless entry points are covered: the stream-json session, whose counter started over at the first turn, and the single-shot
-prun, which always minted turn0. Both are seeded from the resumed transcript using the core helper that already backs the same seeding in interactive mode and in ACP: the highest turn the transcript claims, falling back to the number of resumed user turns. A run that resumes nothing keeps the exact ids it mints today.Why it's needed
--resumeand--continuereuse the previous session's id, so a headless chain that restarts numbering re-mints prompt ids the previous run already persisted, and one transcript ends up carrying several turns under a single prompt id. That id is the key the rewind mapping added in #9466 anchors on — repeated ids make that lookup fail closed to the positional walk — and it is theprompt_idpersisted onui_telemetryrecords, which is itself what the next resume reads back to seed from, so the ambiguity compounds along the chain. Interactive mode and ACP already seed their counters on resume; only the two headless paths were missing it, which is the deferred review finding tracked in #11408.Correction to an earlier version of this description, from the sandboxed
/verifyrun: file-history snapshots are not dropped on these paths. The de-dupe is real (SessionFileHistoryAccumulatorkeeps the last snapshot per prompt id), butfileCheckpointingEnableddefaults to!sdkMode && interactiveand nothing inpackages/clioverrides it, somakeSnapshotno-ops and headless turns write no snapshots at all — measured in the sandbox as 10 headless processes, 6 realwrite_fileexecutions, 0 snapshot records. That is why interactive mode has always seeded, and it is a cost this PR does not remove on the headless paths.Reviewer Test Plan
How to verify
Unit tests cover both paths and are the intended reviewer evidence:
npx vitest run src/nonInteractive/session.test.ts src/llm.test.tsxinpackages/cli. The stream-json cases assert that a session with nothing resumed still starts at turn 1, that a resumed transcript whose highest claimed turn is 5 makes the next turn 6, and that a transcript with no persisted prompt id falls back to counting resumed user turns. The-pcase asserts that a resumed run continues past the last claimed turn while the existing fresh-session expectation of turn 0 is unchanged.End to end, the oracle is the prompt ids persisted in the session transcript (
<runtime>/projects/<cwd>/chats/<sid>.jsonl), read back after each process exits — not file-history snapshots, which headless never writes. Run-ponce with--session-id, then-p --resume <id>, and compare: before this change the transcript holds one turn number for both processes, after it one per process. The sandboxed/verifyrun drove exactly that against real built base and head artifacts:-pwent[0] → [0]on base versus[0] → [0,2]on head, and stream-json over three processes went[1] → [1] → [1]versus[1] → [1,2] → [1,2,3].Evidence (Before & After)
N/A — no user-visible or TUI change; the difference is in persisted prompt ids and the snapshots keyed by them.
Tested on
Not verified locally on any platform — the machine this was written on cannot run the build or test suite, so CI is the verification for lint, typecheck and unit tests.
Environment (optional)
N/A — unit tests only.
Risk & Scope
-prun changes the single prompt id it emits (previously always turn 0), which shifts the id seen by telemetry and by any consumer that keyed on turn 0 for resumed headless runs; fresh runs are byte-identical to today.--continue,--fork-sessionand resumed-from-interactive chains were not driven (the sandbox exercised--session-id→--resumeonly)./rewinditself and refactor: anchor rewind mapping to stable prompt identity #9466's identity mapping were not driven either — the sandbox verified that ids repeat, not what the mapping then does with them.createNonInteractivePromptId's new parameter is optional.Linked Issues
Closes #11408 — the single deferred finding it tracks (
ic:5582642849, from #9466).中文说明
这个 PR 做了什么
Headless 运行现在会从恢复的会话记录中续接 prompt 编号,而不是每个进程都重新开始。两条 headless 入口都覆盖到了:stream-json 会话(计数器每次都从第一轮重新开始)和单次
-p运行(永远铸造第 0 轮)。两者都使用 core 中已有的 helper 从恢复的记录里播种——取记录中已声明的最大轮次,没有则回退到恢复的用户轮次数量;交互模式和 ACP 早就用同样的方式播种。没有恢复任何会话的运行,铸造出的 id 与今天完全一致。为什么需要
--resume和--continue会复用上一个会话的 id,因此重新开始编号的 headless 链会重复铸造上一次运行已经持久化的 prompt id,导致同一份 transcript 里多轮共用一个 prompt id。这个 id 正是 #9466 引入的 rewind 映射所锚定的键——id 重复会让该查找 fail-closed 退回按位置游走——同时也是持久化在ui_telemetry记录上的prompt_id,而下一次 resume 又要读回它来为自己播种,于是歧义会沿着链条累积。交互模式和 ACP 在恢复时已经播种,只有这两条 headless 路径遗漏了,也就是 #11408 中记录的 deferred review finding。对本描述早先版本的更正(来自沙箱
/verify运行):这两条路径上 file-history 快照不会被丢弃。去重机制确实存在(SessionFileHistoryAccumulator每个 prompt id 只保留最后一份),但fileCheckpointingEnabled默认为!sdkMode && interactive,且packages/cli中无人覆盖它,因此makeSnapshot直接返回,headless 轮次根本不写快照——沙箱实测:10 个 headless 进程、6 次真实write_file执行、0 条快照记录。这也正是交互模式一直播种的原因,而这项代价在 headless 路径上并不是本 PR 所消除的。评审验证计划
如何验证
单元测试覆盖了两条路径,也是本 PR 提供给评审者的证据:在
packages/cli下执行npx vitest run src/nonInteractive/session.test.ts src/llm.test.tsx。stream-json 的用例断言:未恢复任何会话时仍从第 1 轮开始;恢复的记录中最大轮次为 5 时下一轮为 6;记录中没有持久化 prompt id 时回退到恢复的用户轮次计数。-p的用例断言:恢复运行会续接到最后已声明轮次之后,而原有的「全新会话为第 0 轮」的期望保持不变。端到端的 oracle 是持久化在会话 transcript(
<runtime>/projects/<cwd>/chats/<sid>.jsonl)里的 prompt id,在每个进程退出后读回——而不是 file-history 快照,headless 根本不写快照。先带--session-id跑一次-p,再跑-p --resume <id>并对比:改动前两个进程在 transcript 里只留下一个轮次号,改动后每个进程一个。沙箱/verify用真实构建的 base 与 head 产物驱动了这一点:-p在 base 上是[0] → [0],head 上是[0] → [0,2];stream-json 三个进程在 base 上是[1] → [1] → [1],head 上是[1] → [1,2] → [1,2,3]。证据(改动前后)
N/A —— 没有用户可见或 TUI 变化,差异体现在持久化的 prompt id 以及以其为键的快照上。
测试平台
三个平台均未在本地验证:撰写本 PR 的机器无法运行构建和测试套件,lint、typecheck 与单元测试以 CI 为准。
运行环境(可选)
N/A —— 仅单元测试。
风险与范围
-p运行所发出的那一个 prompt id 会发生变化(此前恒为第 0 轮),这会改变 telemetry 以及任何针对「恢复的 headless 运行为第 0 轮」做假设的消费方所看到的 id;全新运行与今天完全一致。--continue、--fork-session以及「从交互会话恢复」的链路未被驱动(沙箱只跑了--session-id→--resume)。/rewind本身与 refactor: anchor rewind mapping to stable prompt identity #9466 的身份映射也未被驱动——沙箱验证的是 id 会重复,而不是映射拿到重复 id 之后的行为。createNonInteractivePromptId新增的参数是可选的。关联 Issue
Closes #11408 —— 该 issue 追踪的唯一一条 deferred finding(
ic:5582642849,来自 #9466)。