feat(core): expand Kimi, Qwen and DeepSeek reasoning presets - #11349
Conversation


Validation reportTested source:
The off-state regression was reproduced with the global preference and compared with a passing per-model override. Restoring both active and rebuildable state fixed the real headless startup sequence without weakening the original off-field assertions. Tests also cover mandatory models and applying fresh model defaults after clearing the prior preference. Independent local medium review found no actionable issues after the fixes. This is automated control and wire-contract validation, not manual browser acceptance or live paid-provider testing. Windows/Linux execution and provider account/region entitlements remain for CI or downstream acceptance. 中文测试说明在 macOS / Node.js 22 上验证提交 Core 聚焦测试通过;最终受影响套件复跑 994 项通过,强化 provider 默认值断言后的两项连续认证测试也通过。ACP 与两套 TUI 推理控件共 4 套、101 项测试通过。真实 provider hook 覆盖 23 个路由的普通、显式关闭、副请求关闭三种模式,确认 Flash 修复前失败、修复后通过。 11 个隔离 CLI E2E 全部通过。配置由真实 installer 生成,不使用模型或凭证启动参数覆盖;每项产生一个实际 CLI 到 localhost 的请求。上表记录精确推理字段,意外的嵌套 reasoning、extra_body 或额外开关都会导致失败。Kimi K3 / K2.7 的强制思考保护、K2.6 原生关闭、Qwen none、阿里云与原生 DeepSeek 的不同关闭字段均已验证。 全局关闭偏好曾在实际 headless 连续认证时丢失,而相同模型级关闭配置能够通过;修复同时恢复活动配置与可重建状态后,原关闭字段断言不变即通过。另验证强制思考模型及清除旧偏好后重新应用模型默认值。 独立本地 medium review 在修复后没有可操作发现。以上是自动化控件和 wire 契约验证,不代表手工浏览器验收或真实付费 provider 调用。Windows/Linux、账号地域权限由 CI 或下游验收验证。 |

|
Re-run at Template looks good ✓ Problem: real, and I re-verified it in a clean worktree of the base instead of taking the framing on faith. Direction: aligned, for the reason I care most about: it fills in the framework #10999 already merged instead of building a rival one, and it deletes a hardcoded model-name branch (the The thing that drove my last escalation is worth naming because it changed. Last pass I said the substance here is a set of claims about what Moonshot, DeepSeek and Alibaba ModelStudio accept, and no amount of static review verifies a claim about a third-party API. @wenshao has since verified the whole matrix against real endpoints — provider hostnames impersonated locally behind a throwaway CA, settings generated by the repo's own installer, a live daemon per route — including a negative-control arm that reverts only the three production files and gets both defects back on the wire. That is the evidence class I said was missing, and it is a maintainer's evidence, not mine. Size: core paths touched ( Approach: scope still feels right, and I still have no simpler path to argue for — 80% of this is preset declarations plus one gate swap. My earlier note that the Risk: Stage 1e matched one high-risk path — Moving on to code review. 🔍 中文说明本次是对 模板完整 ✓ 问题: 真实存在,我在基线的干净 worktree 里重新核对过,不是接受描述的框定。当前 方向: 对齐,而且是我最在意的那种对齐:它填充的是 #10999 已合并的框架,而不是另造一套;它删掉了一个硬编码模型名分支( 上一轮让我升级的那个点值得单独说,因为它变了。上次我说:本 PR 的实质是一组关于 Moonshot、DeepSeek 与阿里云百炼接受什么的断言,而静态审查无法验证任何关于第三方 API 的断言。@wenshao 此后已经对真实端点验证了整个矩阵——把 provider 域名劫持到本地、用自建 CA 签发证书、settings 由仓库自己的安装器生成、每条路由跑一个真实 daemon——并且包含一个反向对照 arm:只回退那三个产品文件,两个缺陷就在线上重现。这正是我说缺失的那类证据,而且它是 maintainer 的证据,不是我的。 规模: 触及核心路径( 方案: 范围依然合理,我依然没有更简单的路径可以主张——其中 80% 是预设声明加一处判断替换。我上次提到 风险: Stage 1e 命中一条高风险路径—— 进入代码审查 🔍 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
Code reviewMy independent proposal, written before opening the diff, was the same as last pass: declare I re-read the production files at this commit instead of carrying my old findings forward. Status of the two I raised last time, then three I have not raised before. None of the five is a merge blocker on its own; I would land all five as follow-ups. 1. The two-ladder disagreement — answered the right way, behaviour unchanged, and here is exactly what that behaviour is. The new commit deletes the stale claim that "a The behaviour is unchanged, so I pinned down what it actually is at this commit. 2. Two call sites are still on the name-only path — one live, one a default.
It is still masked for every preset in this PR: for a configured tiered model the capability block at 3. Native DeepSeek now advertises a Widening 4. Three native Kimi models lose their Dropping 5. The new repeated-auth test does not pin the fix it ships with.
Reuse ladder: nothing to flag. The PR extends Consumer audit for the two exported signatures that changed, since Tier 2 requires naming every downstream caller: both new parameters are optional with backward-compatible defaults, and both are actually populated rather than left as dead switches — Where the effort decision is madesequenceDiagram
participant P1 as User effort selection
participant P2 as ContentGenerationPipeline
participant P3 as applyConfiguredReasoningEffort
participant P4 as DashScope provider buildRequest
participant P5 as Wire request
P1->>P2: reasoning effort (low .. max)
P2->>P3: resolve declared capabilities.reasoning
P3->>P3: is the effort inside the declared ladder
P3-->>P2: set top-level reasoning_effort, or strip it and set nothing
P2->>P4: provider hook runs after the mapping
P4->>P4: isTieredEffortModel via the declared capability
P4-->>P5: reasoning_effort tier, or the enable_thinking toggle
Files changed (17)
Test evidenceUnattended CI re-run: nothing from this PR was built or executed, per the gate rules. Two sources below, labelled by whose evidence they are. (a) The PR's own CI on One red check:
One row per check name (latest non-skipped run); skipped checks omitted; failures sort first. (b) A maintainer's independent wire verification — @wenshao's evidence, not mine, and I did not re-run any of it. Real provider hostnames impersonated on loopback behind a throwaway CA, request bodies logged verbatim; Still the author's claim rather than evidence available to me: the before/after in the description (2 of 23 route cases failing before the protocol change, 23 passing after) and the isolated CLI mock acceptance, both run on macOS only with Windows and Linux marked untested. A mock endpoint can confirm what the CLI sends; it cannot confirm what the far end accepts. Sandboxed verification would settle the one remaining send-side claim, and neither lane has been run on this head — there is no Not verified: provider acceptance of matrix rows beyond what @wenshao's harness covered (live paid calls are out of scope by the description); the server-side-default premise in finding 1; Windows and macOS behaviour (CI ran the suite on Linux only, the author tested locally on macOS only); and findings 4 and 5, which I confirmed by reading code and fixtures at this commit but did not observe in a running product. 中文说明代码审查 我在打开 diff 之前写的独立方案与上一轮相同:在五个预设文件里按各路由真实的 wire 契约声明 我在该 commit 上重读了产品文件,而不是把旧结论直接搬过来。先是上次两条的当前状态,然后是三条我此前没提过的。五条单独都不构成合并阻断,我都会作为后续处理。 1. 两张档位表的不一致——用正确的方式回答了,行为未变,而行为的确切内容如下。 新 commit 删掉了 行为没有变化,所以我在该 commit 上把它究竟是怎样的钉了下来。 2. 还有两个调用点在只看模型名的路径上——一个是活的,一个是默认值。
对本 PR 的所有预设它仍被遮蔽:配置了 capability 的分档模型, 3. 原生 DeepSeek 现在展示了一个 把 4. 三个原生 Kimi 模型在模型列表里失去了 从 5. 新增的重复认证测试没有钉住它随附的修复。
复用梯度:无需指出。PR 扩展的是 对两个发生变化的导出签名做消费者审计(Tier 2 要求点名每个下游调用方):两个新参数都是可选且向后兼容的默认值,并且都真的被填充、不是死开关—— 测试证据 无人值守的 CI re-run:按门禁规则,本 PR 的任何代码都没有被构建或执行。下面两个来源,按证据归属分别标注。 (a)PR 自己在 一个红灯: (b)maintainer 的独立线上验证——@wenshao 的证据,不是我的,我也没有重跑其中任何一项。 真实 provider 域名劫持到回环地址、由自建 CA 签发证书、逐字记录请求体; 仍属于作者自述、我这里拿不到的证据: 描述里的 before/after(协议改动前 23 个路由用例中 2 个失败、改动后 23 个全过)以及隔离 CLI mock 验收,都只在 macOS 本地跑过,Windows 与 Linux 标注未测试。mock 端点能确认 CLI 发出什么,不能确认对端接受什么。 沙箱验证可以解决剩下那条发送侧的断言,而且两条通道在该 head 上都没有跑过—— 未验证:@wenshao 的 harness 未覆盖的矩阵行的 provider 接受情况(描述已声明真实付费调用超出范围);第 1 条的服务端默认值前提;Windows 与 macOS 行为(CI 只在 Linux 跑套件,作者本地只在 macOS 测试);以及第 4、5 条——我在该 commit 上通过读代码和 fixture 确认,但没有在运行中的产品里观测。 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
|
Confidence: 3/5 — clean review, and the doubt that capped my last pass has been discharged; 3/5 is this gate's own core-change policy, not remaining hesitation about the diff. ⏸️ Deferring to @wenshao — most recent human reviewer, and the person whose verification closed the gap I named. @qqqys is already assigned by the path router. This needs a human sign-off for a policy reason, not a technical one. Stepping back. Last pass I deferred because the substance of this PR is a set of claims about what Moonshot, DeepSeek and Alibaba ModelStudio accept, and nothing inside this repo can check a claim about a third-party API. Two things changed since. The author answered my one substantive question the right way — deleting a stale "this gets a 400" claim from the constant and documenting why the two ladders deliberately differ, instead of arguing the point in a thread — and you verified the whole matrix against real endpoints, with a control arm that reverts only the three production files and gets both defects back on the wire. A green suite that passes identically with and without the diff is worthless; that one discriminates. So the reason for the cap is gone. What remains is mechanical, and I want to be explicit about it so nobody waits on me. At this commit the PR's own CI is fully green with nothing pending, so an approval was mechanically available this run. I am not posting one, because the gate escalates any core-path change at 500+ production lines to a maintainer for awareness — 506 here, and the comment-only commit is what crossed the line — and this one additionally touches auth ( If I had written this PR myself it would have had the same shape: presets become the single source of truth, a hardcoded model-name branch gets deleted instead of a second one added for Flash, and the wire matrix test pins metadata to what actually ships rather than snapshotting config objects. In six months I would thank the author for it, not curse them. The five items in Stage 2 are all non-blocking and all fine as follow-ups. If I had to pick one to fix before merge it would be #5 — a test that stays green when you delete the fix it ships with is the kind of thing that rots silently — but by this repo's own review rules that is a Suggestion, and the fix it covers is verified real by your harness. #3 and #4 are the two I would want tracked somewhere rather than dropped, since both are inconsistencies this PR makes newly visible rather than pre-existing noise. One thing worth checking before anyone assumes the bot's vote is what is missing here. The Volume check: the author has two other open PRs ( Nothing from this PR was built or executed in this run. All test signal came from its own CI through the API, plus your published report, which I have attributed as yours throughout rather than folding into my own evidence. 中文说明Confidence: 3/5 —— 审查结果是干净的,而上一轮让我封顶的那个疑问已经被解决;3/5 是本门禁自己的核心改动规则,不是我对这个 diff 还留有犹豫。 ⏸️ 转交 @wenshao —— 最近一位人类评审者,也是用验证关闭了我指出的那个缺口的人。@qqqys 已由路径路由指派。这次需要人来签字是出于规则原因,不是技术原因。 退一步看。上一轮我 defer,是因为本 PR 的实质是一组关于 Moonshot、DeepSeek 与阿里云百炼接受什么的断言,而仓库内没有任何东西能验证关于第三方 API 的断言。此后有两件事变了。作者用正确的方式回答了我唯一的实质性问题——从常量上删掉"这会 400"的过期说法,并记录两张档位表为何有意不同,而不是在讨论串里争辩——而你对真实端点验证了整个矩阵,还有一个只回退三个产品文件的对照 arm,两个缺陷会在线上重现。带不带 diff 都同样通过的绿色套件毫无价值;那套验证是有判别力的。所以封顶的理由已经消失。 剩下的是流程性的,我想说清楚,免得有人等我的结果。在该 commit 上,PR 自己的 CI 全绿且没有待运行项,所以本次运行本来是可以批准的。我没有批准,因为门禁会把任何生产行数达到 500+ 的核心路径改动升级给 maintainer 知悉——这里是 506 行,而越过这条线的正是那个只改注释的 commit——并且它还触及认证( 如果这个 PR 是我自己写的,形状也会一样:预设成为唯一事实来源,一个硬编码模型名分支被删掉而不是为 Flash 再加一个,wire 矩阵测试把元数据钉在实际发出的内容上,而不是对配置对象做快照。半年后我会感谢作者,而不是骂他。 Stage 2 里的五条都不构成阻断,都可以作为后续处理。如果一定要在合并前修一条,我会选第 5 条——删掉它所随附的修复后仍然通过的测试,是那种会静默腐烂的东西——但按本仓库自己的评审规则那属于 Suggestion,而它覆盖的修复已由你的 harness 验证为真实。第 3 条和第 4 条是我希望被记录下来、而不是被丢下的两条,因为两者都是本 PR 新暴露出来的不一致,不是既有的噪音。 有一件事值得在任何人假定"缺的就是机器人这一票"之前先查一下。 数量核查:作者另有两个开放 PR( 本次运行没有构建或执行本 PR 的任何代码。所有测试信号都通过 API 来自它自己的 CI,加上你发布的报告——我全程把它标注为你的证据,没有混进我自己的证据里。 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
|
The failing check is the unchanged WebShell history-viewport smoke case for bounded 200-record pages: CI exhausted retries on the reading-anchor assertion. The exact test passed locally four times with retries disabled. This does not establish the cause: those runs used macOS and one worker, while CI used Ubuntu and nine workers. The complete local smoke suite also passed all 53 tests with nine workers and zero retries (95.6 seconds), so the target has passed five times locally. I have rerun only the failed CI job on the same head; attempt 2 is job 102009201281. The Linux retry has now completed successfully on the same head (workflow attempt 2 and the smoke job both succeeded: 52 passed, with the 200-record target passing after an internal retry and reported as 1 flaky). The underlying intermittent failure was not reproduced locally; no production code or assertion was changed. No production code or assertion has been changed to clear this failure. Regarding the tier-table question: the explicit capability is authoritative for configured routes. An unsupported saved tier is omitted so the provider default applies; for configured Qwen 3.8 that default is xhigh. The old constant remains the compatibility fallback for routes without a valid explicit capability. Changing that fallback would also change previously unconfigured routes, so it is intentionally retained. The new tests cover unsupported configured tiers and the existing suite retains the old fallback behavior. The provider matrix is based on the primary references in the design document. The Moonshot K2.6 guide specifies thinking.type with thinking enabled by default, and the Alibaba DeepSeek API examples send reasoning_effort at the top level. The local CLI and real adapter tests validate our outgoing wire contract; they are not a claim of live validation against every native provider endpoint. 中文说明失败的是本 PR 未修改的 WebShell 200 条记录历史视口 smoke 用例,CI 在阅读锚点断言上耗尽重试。原始用例本地无重试连续四次通过,但这不足以确定根因:本地是 macOS、单 worker,CI 是 Ubuntu、九个 worker。完整本地 smoke 按九个 worker、零重试运行后也全部通过(53/53,95.6 秒),目标累计本地五次通过。已只重跑同一 head 的失败 job,attempt 2 对应 job 102009201281,Linux 重跑现已成功(workflow attempt 2 与 smoke job 均成功:52 passed,200-record 目标在内部重试后通过,计为 1 flaky)。底层偶发问题本地未复现;没有通过修改产品代码或断言消除失败。 显式 capability 对已配置路由具有优先权。超出声明档位的持久化值被省略,使用 provider 默认值;已配置 Qwen 3.8 的默认值为 xhigh。旧常量有意保留给没有有效显式 capability 的路由作为兼容回退,直接修改它会改变这些路由的既有行为。新测试覆盖非法已配置档位,旧套件继续覆盖兼容行为。 模型矩阵依据设计文档中的官方参考:Moonshot K2.6 指南明确 thinking.type 和默认开启;Alibaba DeepSeek 示例直接使用顶层 reasoning_effort。本地 CLI 和真实 adapter 测试验证客户端 wire 契约,不代表每个原生 provider 入口都做过真实调用验收。 |

 ytahdn
left a comment
ytahdn
left a comment
There was a problem hiding this comment.
What this PR does / PR 主旨
Fills out the declarative capabilities.reasoning framework that PR 10999 landed (which only configured native DeepSeek V4 Pro) across the Kimi/Qwen/DeepSeek routes: five preset files now declare per-model tiers / toggle / default / disable-field to match each provider route's real wire contract. It replaces the hardcoded qwen3.8-max prefix gate in the DashScope provider with a capability-first lookup (isTieredEffortWireModel(model, configuredReasoning?), name fallback only when unconfigured), and rides along a refreshAuth fix so a saved global thinking-off preference survives repeated auth (mandatory-thinking models exempt). Native Kimi presets drop the enableThinking field, which isn't that route's protocol.
把 PR 10999 落地的声明式 capabilities.reasoning 框架(当时只配了原生 DeepSeek V4 Pro)补齐到 Kimi/Qwen/DeepSeek 各路由:五个预设文件按各 provider 路由真实 wire 契约声明每个模型的档位/开关/默认值/关闭字段。把 DashScope provider 里硬编码的 qwen3.8-max 前缀判断换成"优先读已声明 capability、未配置才回退名称"的 isTieredEffortWireModel(model, configuredReasoning?);并顺带修 refreshAuth,让全局关闭思考的偏好在连续认证时不被 provider 默认值抹掉(强制思考模型豁免)。原生 Kimi 预设删除了不属于其协议的 enableThinking 字段。
Verdict: Comment (not approve). No correctness bug found on the head tree; CI is fully green (Test ubuntu / Lint / Integration no-AK / web-shell E2E / Java all pass; macOS/Windows Test skipped). I'm not approving for two honest reasons: one Important-level open question below, and the fact that the substance of this change is a set of claims about what third-party APIs accept, which static review cannot verify.
结论:评论(不批准)。 head tree 上未发现正确性 bug,CI 全绿。不批准有两个诚实的理由:下面一条 Important 级待答问题;以及本 PR 的实质是一组"第三方 API 接受什么"的断言,静态审查无法验证。
Verified correct / 已核实无误
- Exported-signature changes are backward-compatible. I traced every internal caller of both changed functions:
config.ts:5182anddashscope.ts:543pass the resolved capability,dashscope.ts:415andconfig.ts:5186/5208passtieredModelexplicitly. The dropped.toLowerCase()in the new default param ofselectDashScopeThinkingKnobis harmless —isQwenFamilyWireModel(:137) and the name-fallback branch ofisTieredEffortWireModel(:160) both lowercase internally. / 两个导出函数的签名变更向后兼容,我逐一核对了全部内部调用点;新默认参数里丢掉的.toLowerCase()无害,因为被调函数内部都会 lowercase。 - The
refreshAuthchange is correct:priorReasoningis captured before the provider sync wipes it; only a strict=== false(explicit off, distinguished fromundefined) on a non-mandatory model restoresreasoning = falseand writes it back tomodelsConfigso it survives the rebuild; an effort object goes through the existingpriorReasoningEffortpath and is not clobbered; mandatory-thinking models are exempt. /refreshAuth改动正确:偏好在 sync 抹除前捕获;仅严格=== false且非强制思考模型才恢复并回写,effort 对象走既有路径不被覆盖,强制思考模型豁免。 - Test design is strong:
pipeline.test.tsrunsbuildInstallPlanon the real presets, feeds the installed model through the real provider hook, and asserts exact wire fields (including field absence) across 23 routes × 3 modes; the ACP test pins exact options/defaults. This is the only internal-consistency evidence available for a change whose substance is provider-contract assertions. / 测试设计扎实:对真实预设跑安装计划→真实 provider hook→断言确切 wire 字段(含"字段不存在"),23 路由×3 模式,是这类改动唯一能拿到的自洽证据。
🟡 Important — question to resolve before merge / 合并前请回答
1. The declared qwen3.8 ladder and the untouched DASHSCOPE_TIERED_EFFORTS now contradict each other about high, and an out-of-ladder effort is silently dropped instead of clamped-with-warning.
DASHSCOPE_TIERED_EFFORTS = ['low','medium','high','xhigh'] (dashscope.ts:41, unchanged) still contains high; the presets you add declare ['low','medium','xhigh'] for the same qwen3.8 family. Because applyConfiguredReasoningEffort (pipeline.ts:913) runs before the provider hook, an effort outside the declared ladder is stripped from the nested reasoning object (:104) and nothing replaces it (:108); buildQwenEffortConfig (dashscope.ts:570-577) then returns {} for the same reason — no field, no warning.
Concretely, Token Plan qwen3.8-max/-preview had no capability before this PR: /effort high shipped reasoning_effort: 'high' (it's in DASHSCOPE_TIERED_EFFORTS) and /effort max clamped to 'xhigh' with a one-time debug warning. After this PR both are outside the declared ladder, so no effort field ships at all, silently. The picker won't offer them, but they're still reachable from a persisted settings.json model.reasoningEffort (the enum is the full ladder, settingsSchema.ts:1605) and from a mid-session model switch carrying the prior effort. Your dashscope.test.ts case (qwen-custom-tiered, 'high' → reasoning_effort undefined) pins the drop, so it reads as intended — which is why this is a question, not a defect claim.
Two things to settle: (a) For the preset models the failure direction is benign (the selection is ignored, provider default applies — not a disable, not a 400), but the two ladders now assert opposite things about whether qwen3.8-max accepts high. A user's own modelProviders entry for qwen3.8-max (no capability) still goes through clampTieredEffort and ships high — which, if the declared ladder is right, is exactly the 400 the constant's own comment describes. Reconciling the two ladders (or making the declared one the single source), or annotating why the constant deliberately differs, would close this. (b) Is silent-drop better than clamp+warn here, given clampReasoningEffort exists precisely to "cap an over-strong request at the model ceiling and report once"? The answer depends on whether qwen3.8-max truly rejects high, which is provider knowledge, not code-reading.
1. 声明的 qwen3.8 档位表与未改动的 DASHSCOPE_TIERED_EFFORTS 现在在 high 上互相矛盾,且超出声明档位的 effort 是静默丢弃、而非钳制+警告。 DASHSCOPE_TIERED_EFFORTS(dashscope.ts:41,未改)仍含 high,而新预设为同一 qwen3.8 家族声明的是 ['low','medium','xhigh']。由于 capability 映射(pipeline.ts:913)早于 provider hook,超档位 effort 会从嵌套 reasoning 被剥掉且不补任何字段,buildQwenEffortConfig(dashscope.ts:570-577)同样返回 {}——无字段、无警告。具体:Token Plan qwen3.8-max 本 PR 前 /effort high 会发出 'high'、/effort max 钳到 'xhigh' 并警告一次;本 PR 后两者都被静默丢弃。picker 不再提供它们,但持久化的 settings.json(枚举是全表,settingsSchema.ts:1605)与会话中切模型仍可达;dashscope.test.ts 已钉住丢弃=有意为之,所以这是提问不是指控。需要定两点:(a) 两张表对"qwen3.8-max 是否接受 high"给出相反断言,用户自建 modelProviders 的 qwen3.8-max 仍会走 clamp 发出 high——若声明表为真,那正是常量注释里说的 400;统一两表或加注释说明为何有意不同即可关闭。(b) 这里静默丢弃是否优于 clamp+warn,取决于 qwen3.8-max 是否真的拒绝 high,这属 provider 知识。
🟢 Nits / 建议
2. A third call site is still on the legacy name-only path. pipeline.ts:1002 calls isTieredEffortWireModel(model) with one argument. It's masked for every preset in this PR (a configured disableField: 'reasoning_effort' model is immediately overwritten by the capability branch at :1042; qwen3.8-flash, whose name isn't qwen3.8-max, writes enable_thinking = false at :1012 and then has it deleted at :1043). The one unmasked shape is a qwen-family model declaring disableField: 'thinking' — the legacy enable_thinking = false survives alongside thinking: {type:'disabled'}. No preset here declares that, so it's reachable only from a user's own modelProviders. Leaving one call site on the name fallback is exactly the duplication this PR set out to remove; a follow-up or a comment recording why it's safe would be enough. / 第三个调用点 pipeline.ts:1002 仍是单参名称回退,对本 PR 所有预设都被遮蔽,唯一未遮蔽形状(qwen 家族 + disableField:'thinking')仅用户自建配置可达;留一个名称回退正是本 PR 想消除的重复,后续处理或加注释即可。
3. Micro / 微: for a tiered model, buildRequest resolves the model config twice (isTieredEffortModel internally, then getConfiguredReasoning again at dashscope.ts:571). No correctness impact. / tiered 模型每次 buildRequest 会解析两次 model config,无正确性影响。
Needs provider knowledge — not verifiable by reading the repo / 需 provider 知识,仓库内无法验证
The substance of this change is a set of claims about what Moonshot, DeepSeek and Alibaba ModelStudio accept; static review cannot confirm a third-party endpoint. The design doc cites official docs for every matrix row with a 2026-09-08 verification date — the right kind of evidence — but citing a doc and being right about a live endpoint are different things. The two I'd most want a provider-knowledgeable maintainer to sanity-check: (a) Alibaba-routed DeepSeek V4 now flattens to a top-level reasoning_effort and disables via enable_thinking (before this PR that route had no capability and shipped the nested object); (b) native Kimi K2.6 loses enableThinking: true, so its "On" position now sends nothing and relies on the Moonshot default being thinking-on — the one place this PR deletes a field that ships today. The 23-route matrix proves the code is self-consistent (what we send); it cannot prove the far end accepts it.
本 PR 的实质是一组关于 Moonshot / DeepSeek / 阿里云百炼接受什么的断言,静态审查无法确认第三方端点。设计文档为矩阵每行引用了官方文档并标注 2026-09-08 核对日期,是正确类型的依据,但"引用文档"≠"对线上端点判断正确"。最希望有 provider 知识的 maintainer 复核两处:(a) 阿里云路由的 DeepSeek V4 现在展平为顶层 reasoning_effort 并用 enable_thinking 关闭(此前无 capability、发嵌套对象);(b) 原生 Kimi K2.6 删除 enableThinking 后"开"档什么都不发、依赖 Moonshot 默认开启思考——这是本 PR 唯一删除今天仍在发的字段处。23 路由矩阵证明代码自洽(我们发什么),但不能证明对端接受。
|
Addressed the tier-table question in The official Alibaba Chat parameter reference explicitly documents For configured routes, omitting an unsupported persisted tier and using the provider default is intentional; for these Qwen presets the default is The remaining name-only disable fallback is already part of the independent custom-capability edge cases tracked in #11328; none of this PR's preset routes uses the contradictory shape. The repeated lookup suggestion has no correctness impact and is left out to keep this delivery focused. Native-provider acceptance beyond the cited documentation still needs the requested maintainer judgment; the Idealab test route is not evidence for every native endpoint. 中文说明已在 已配置路由省略不支持的持久化档位、采用 provider 默认值是有意的;这些 Qwen 预设默认 xhigh,所以旧 high/max 偏好保持同等有效强度。沿用既有 capability 框架的默认值策略,避免另加模型专用钳制规则。未配置路由保留原 clamp/警告,显式 provider 参数继续透传。Prettier、diff 检查通过,去除注释后 TypeScript 编译出的 JavaScript 前后逐字节一致。 其余单参关闭回退属于 #11328 已跟踪的自定义 capability 独立边界,本 PR 的预设不触发该组合。重复 lookup 无正确性影响,留在本次范围之外。原生入口超出官方文档的实际接受情况仍需 maintainer 判断,Idealab 测试不能代替所有原生入口验收。 |
|
Qwen Code review timed out. Qwen review timed out after 21600 seconds (of the 360-minute budget). This run already used the maximum 360 minute timeout. See workflow logs. |

|
@qwen-code /review |

|
Qwen Code review request accepted. Review is running in workflow run. A command-triggered review is not listed under the checks of this PR; the result is posted here as a review when it finishes. |

 qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed. Suggestions are inline. 1 Suggestion-level finding(s) could not be anchored to a changed line and were dropped; nothing further to act on here.
Not reviewed: build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally.
Not explored to full depth (tool budget reached): "agent reverse-audit (round 2)": none — every check I started above reached a conclusion; nothing was cut short by the ceiling.; chunk 4: could not fetch DeepSeek's or Alibaba's external API reference pages to settle which side of the low -tier contradiction is authoritative..
Not reviewed: the counter-frame audit — no record shows its brief reaching an agent, so this dimension was reviewed, if at all, from a prompt the run wrote for itself.
中文说明
仅完成部分审查,审查缺口已披露。 建议见行内评论。 1 条建议级发现无法锚定到改动行,已丢弃;此处无需进一步处理。
未审查(原文为英文):build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally.
未探索到全部深度(达到工具调用预算):"agent reverse-audit (round 2)":none — every check I started above reached a conclusion; nothing was cut short by the ceiling.;chunk 4:could not fetch DeepSeek's or Alibaba's external API reference pages to settle which side of the low -tier contradiction is authoritative.。
未审查:反框架审计——没有记录表明它的 brief 到达过任何 agent,这个维度即便被审查过,也是基于这次 run 自行编写的 prompt。
— qwen3.8-max via Qwen Code /review (v0.23.0)
Independent local verification — real provider endpoints, real daemon, real TUII verified this on Linux (Node 22) against
25 routes on the PR arm, plus base and arm-C comparisons. Every claim in the Reviewer Test Plan reproduced
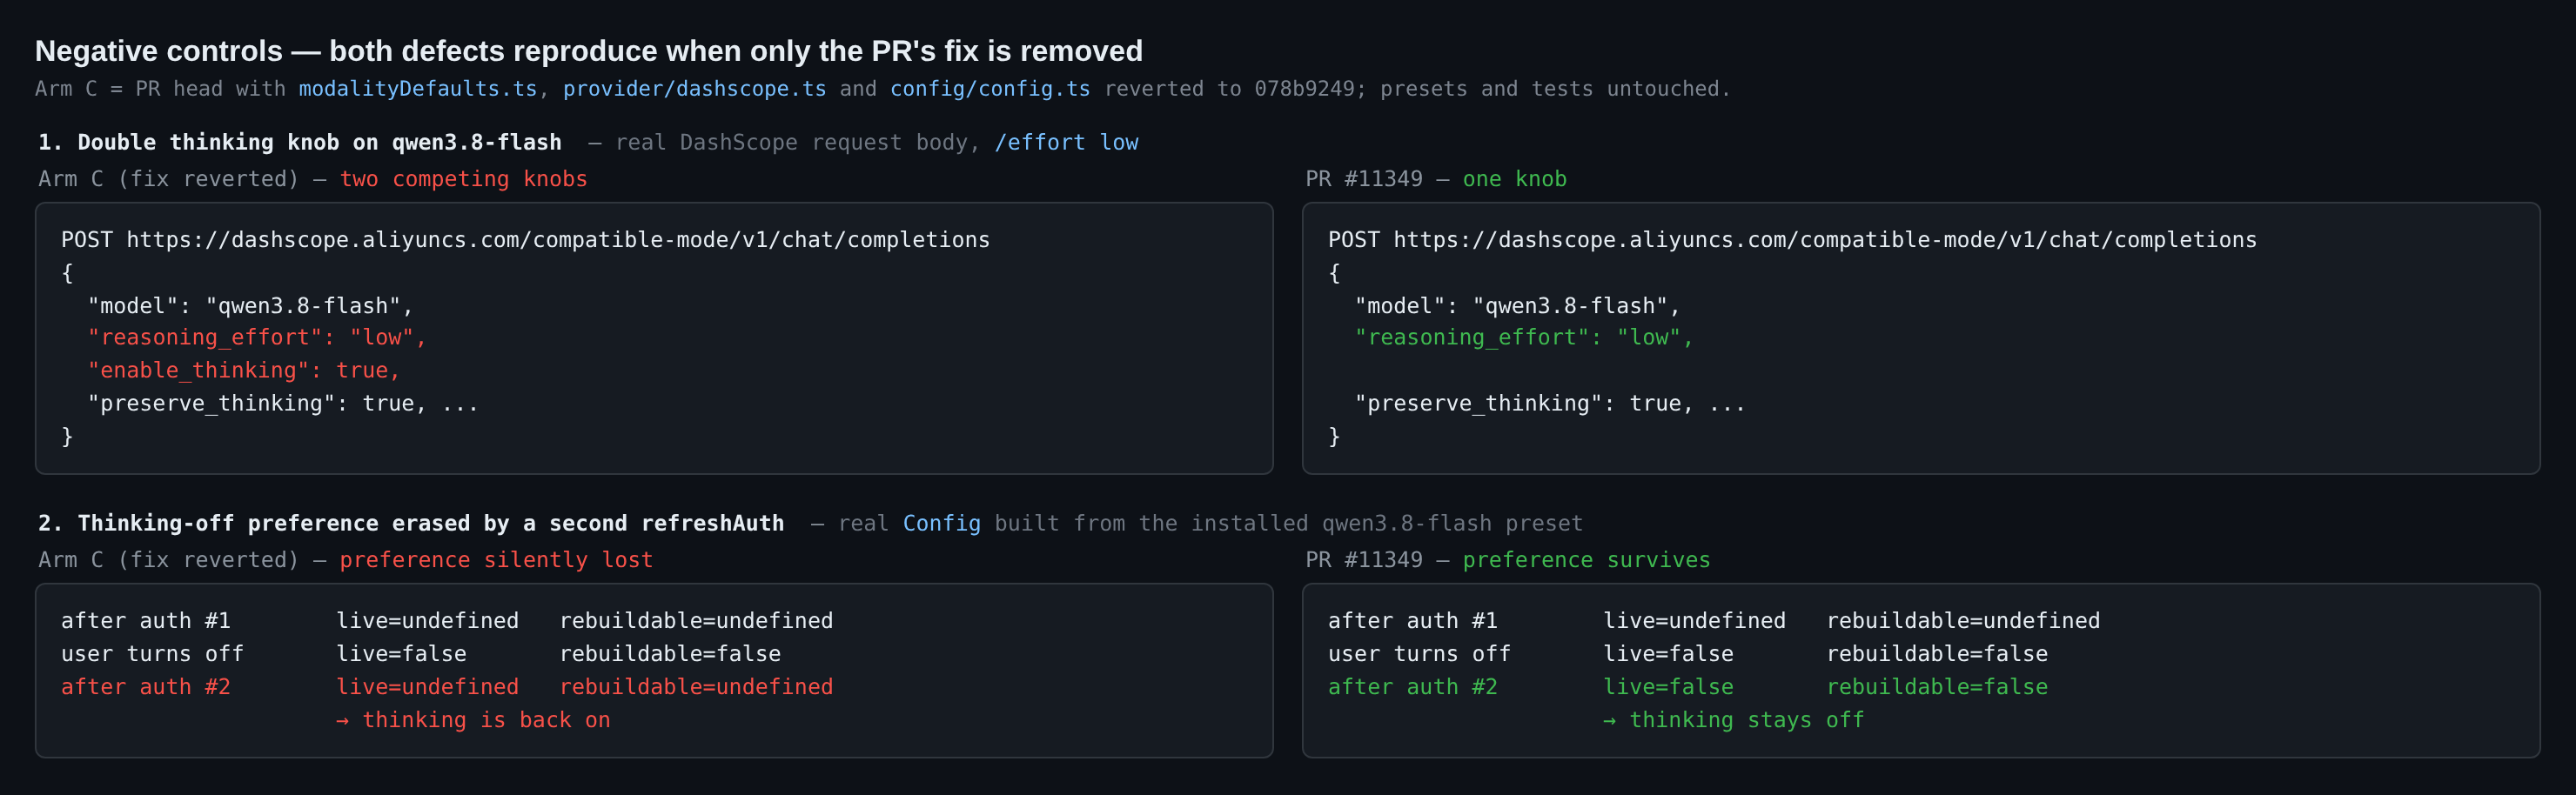
Both fixes are discriminating, not just green
Revert only the three production files and the defects come back on the wire: User-visible surfaces
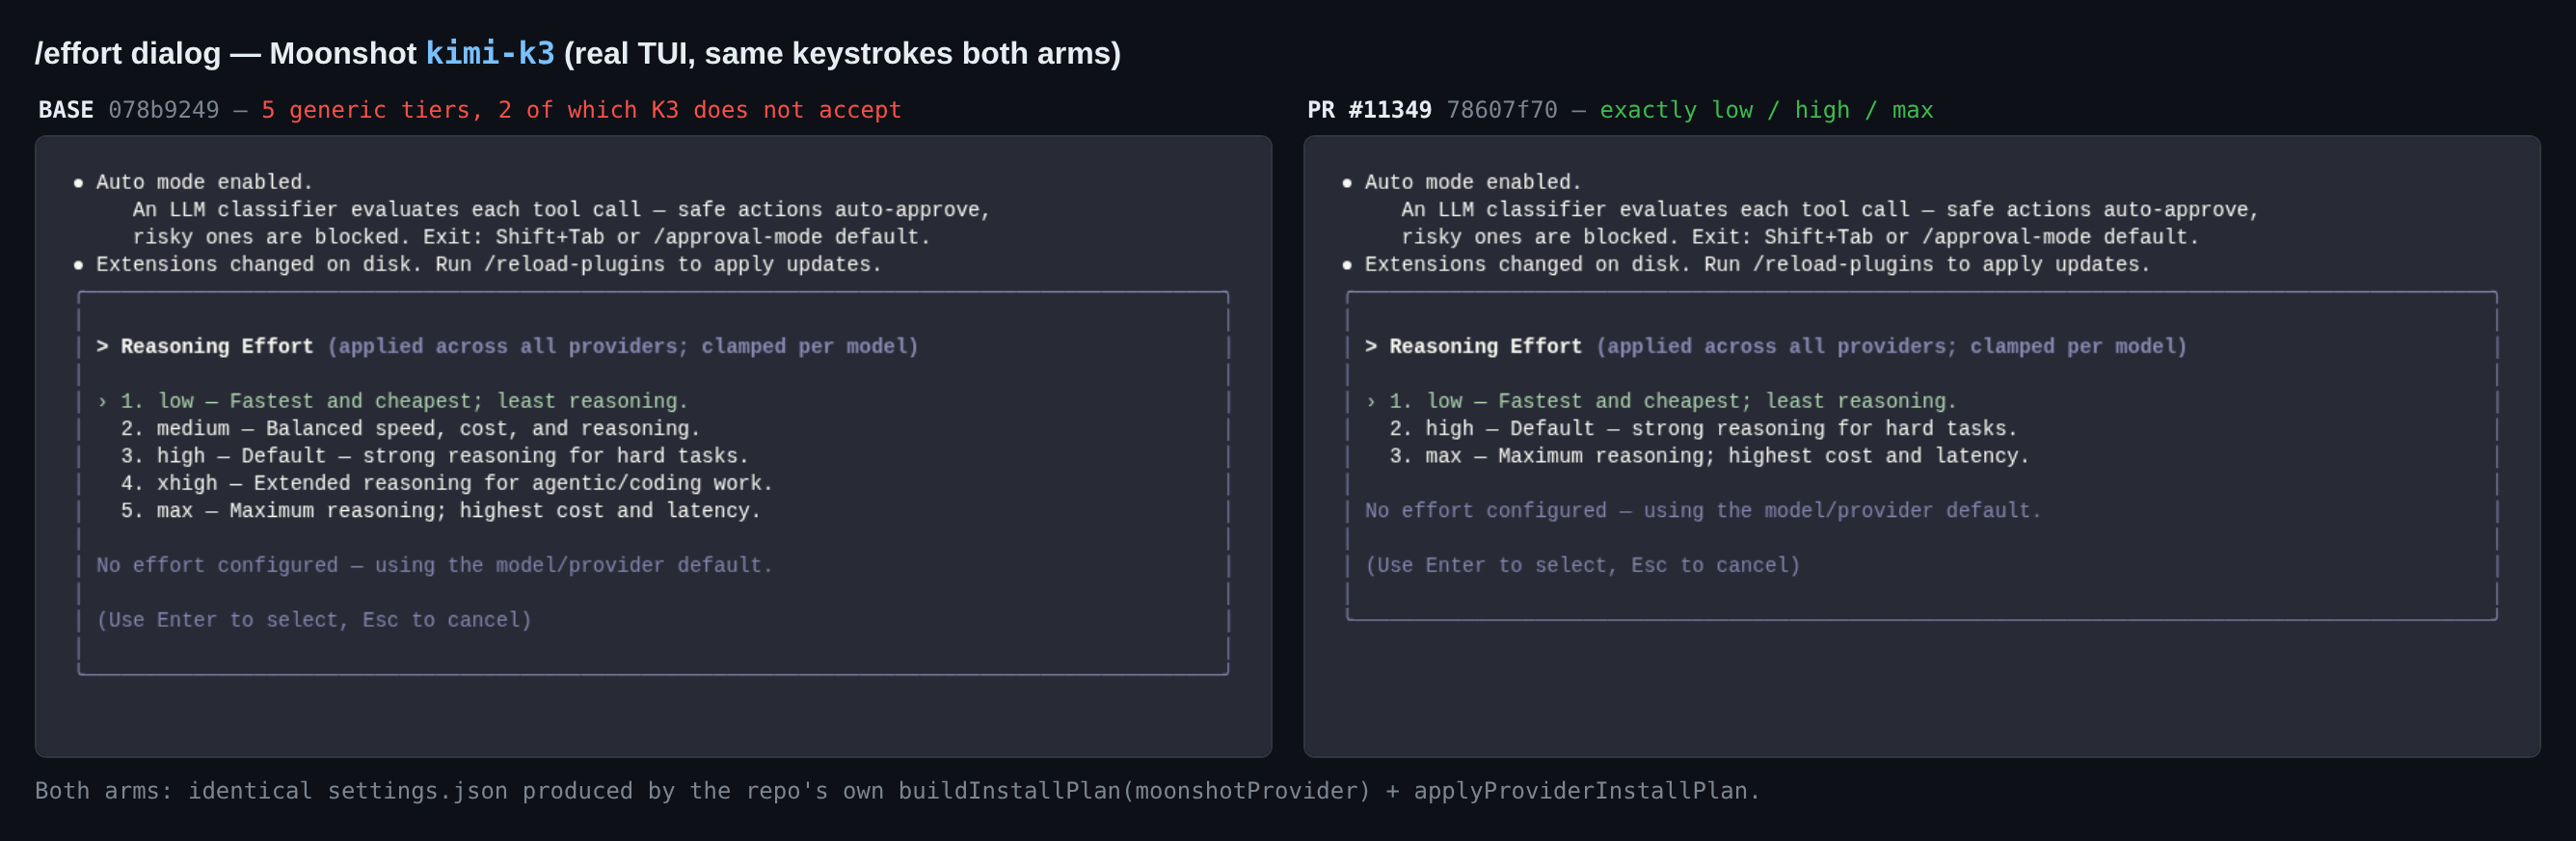
Real TUI, identical keystrokes and identical installed settings on both arms: base offers K3 five generic tiers (two of which Moonshot K3 does not accept), this PR offers exactly the three it does. Checks
Verdict: no blocking defect found — this is mergeable from my side. Five non-blocking items below; two of them overlap with the automated review and are included because I reproduced them independently on the wire. N1 — the new native-DeepSeek
|
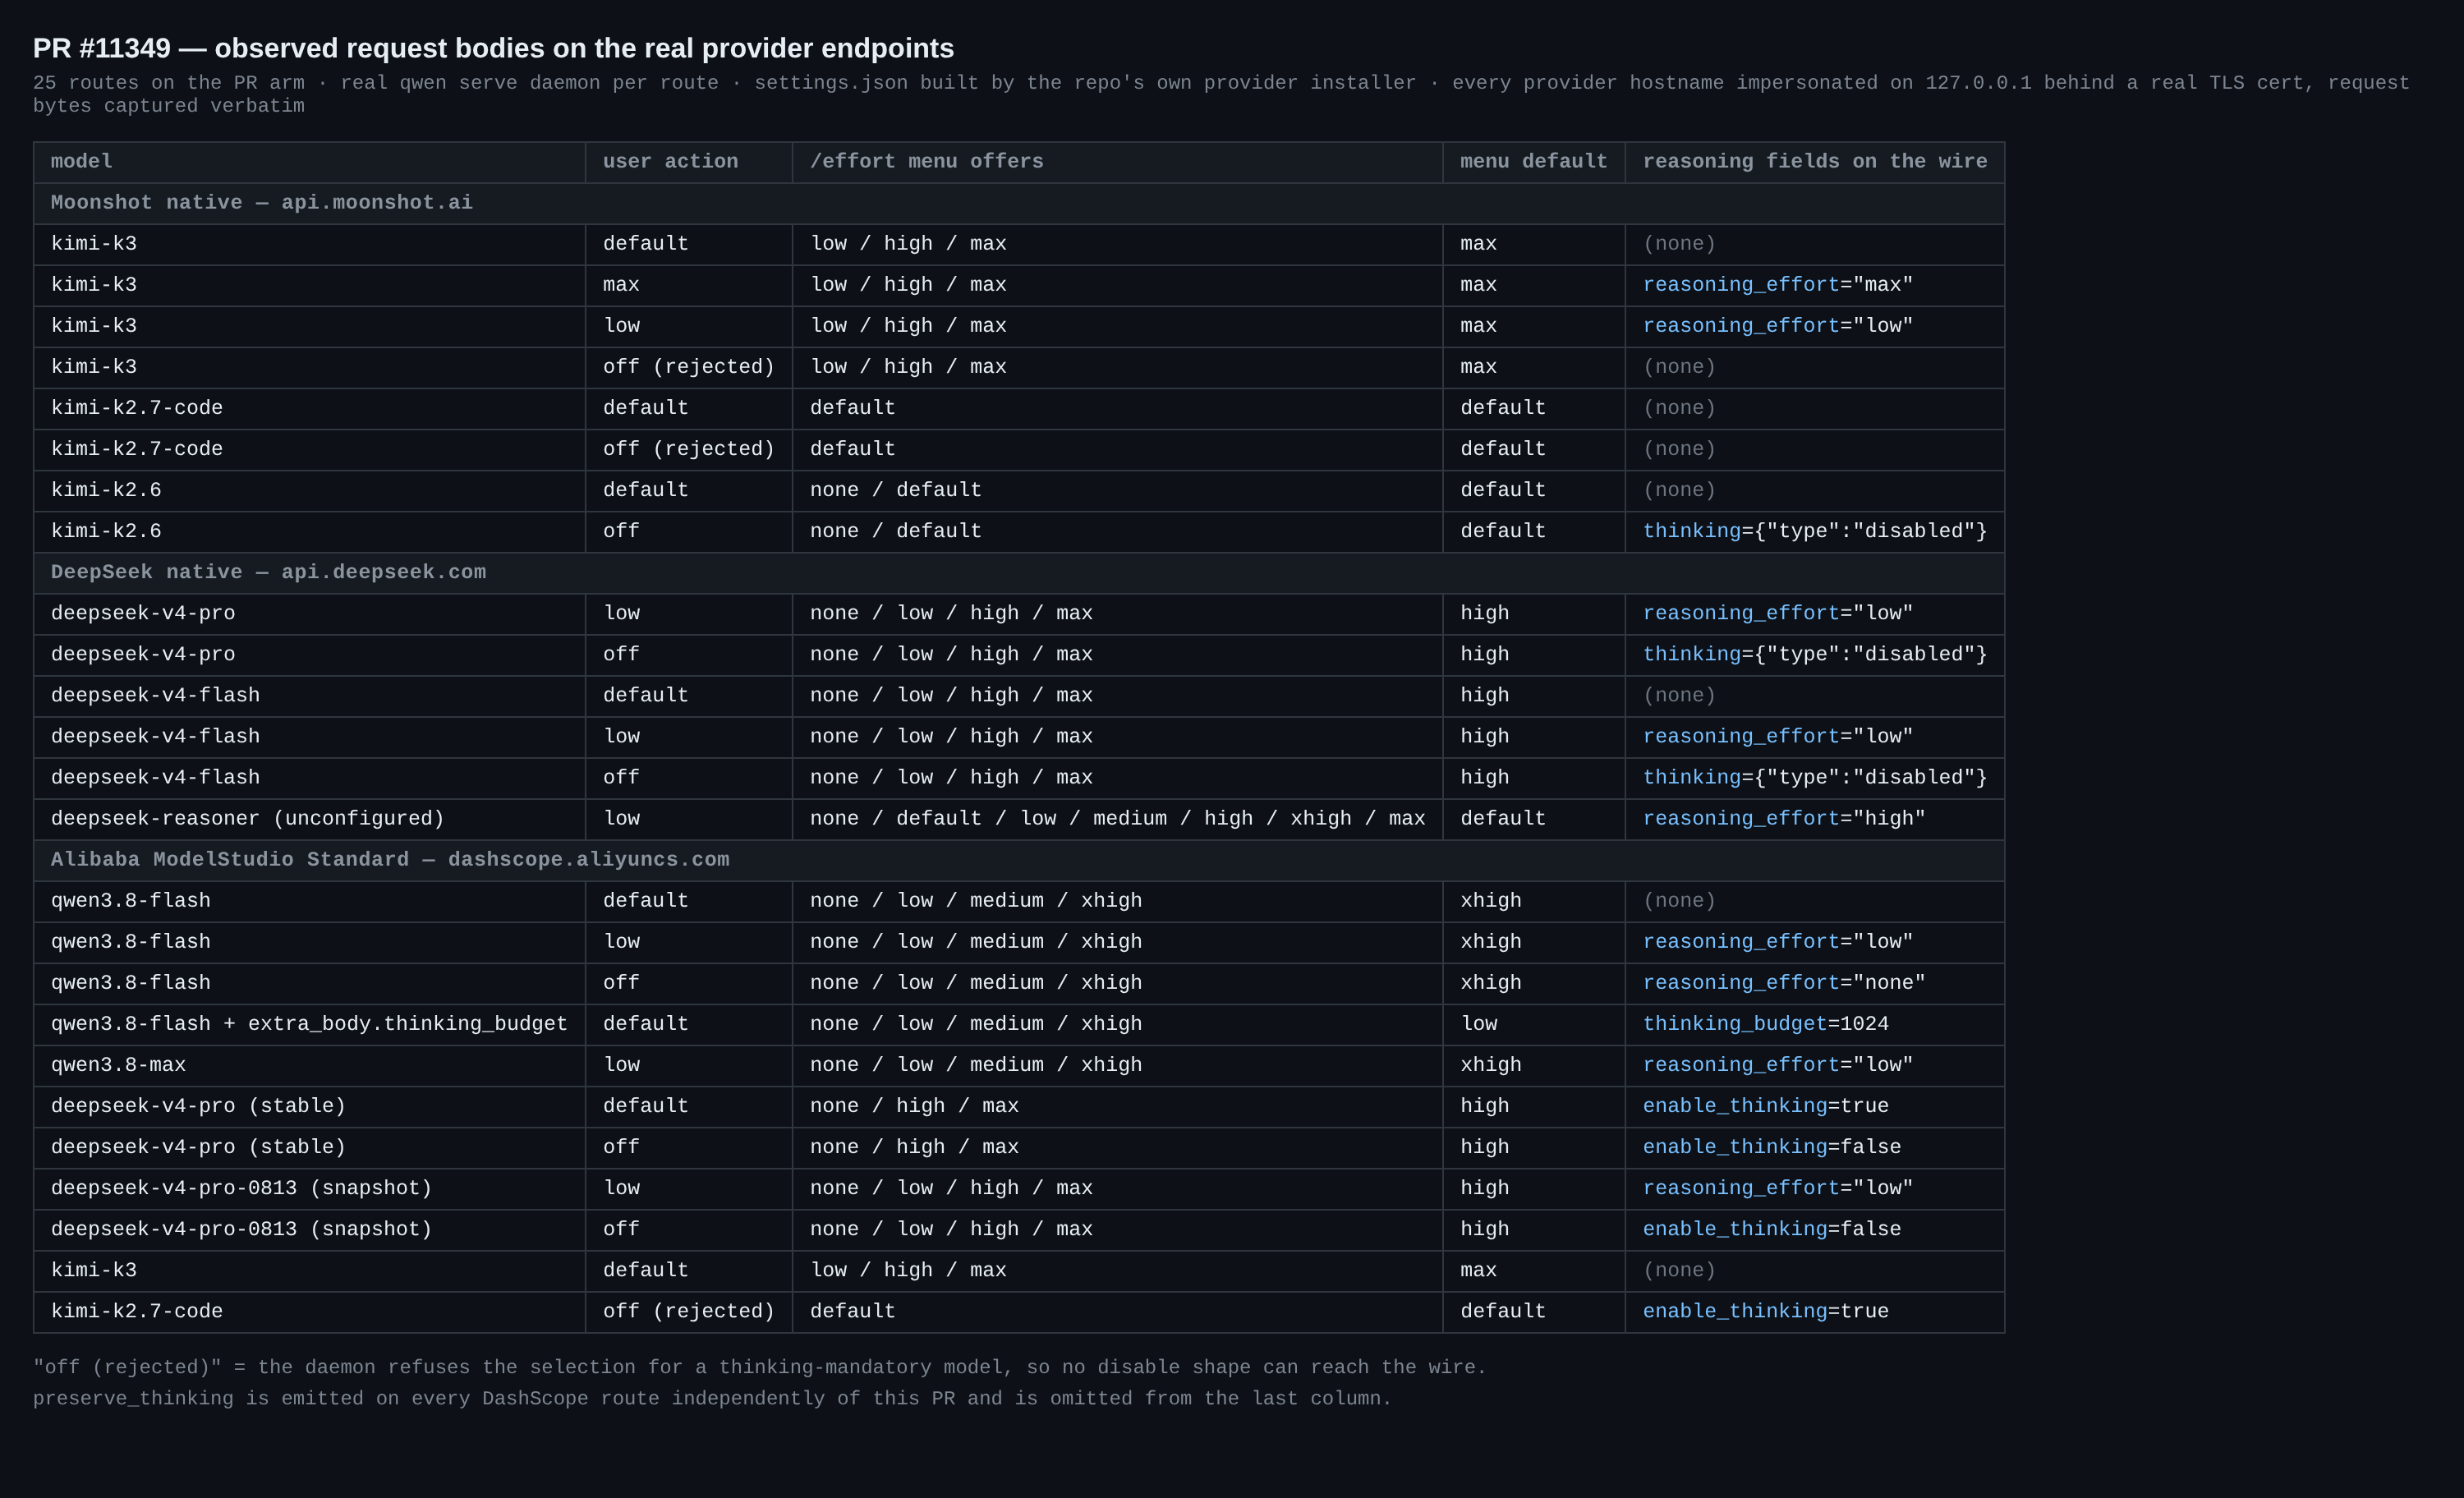
| 声明 | 结果 |
|---|---|
| K3 提供 low/high/max,默认 max,无 Off | ✅ 菜单 low/high/max,当前 max,没有 Off |
| K2.7 Code 不提供 Off,也没有虚构档位 | ✅ 菜单只有 default;Off 请求被拒绝 |
K2.6 提供 On/Off;Off 发送 thinking.type=disabled 且无 enable_thinking |
✅ api.moonshot.ai 上完全如此 |
| Qwen 3.8 Flash:low/medium/xhigh,默认 xhigh | ✅ |
选择档位只发一个 reasoning_effort;关闭发 reasoning_effort=none |
✅ 两种情况都是单字段 |
| 显式 thinking budget 抑制冲突的 effort | ✅ 只发 thinking_budget=1024,无 reasoning_effort |
| 原生 DeepSeek 与日期快照 low/high/max,阿里云稳定版 high/max,默认均为 high | ✅ |
关闭字段:原生 DeepSeek 用 thinking.type,阿里云用 enable_thinking |
✅ |
两处修复都具备判别力,不是「绿就算过」
只回退那三个产品文件,缺陷就在线上重现:qwen3.8-flash 选 /effort low 会同时发出 reasoning_effort: "low" 与 enable_thinking: true;在按已安装预设构造的真实 Config 上,第二次 refreshAuth 会抹掉关闭思考的偏好(live 与 rebuildable 都回到 undefined)。本 PR 下请求只带一个开关,偏好也得以保留。
用户可见界面
真实 TUI、两个 arm 使用完全相同的按键与已安装配置:base 给 K3 列出 5 个通用档位(其中两个 Moonshot K3 并不接受),本 PR 恰好只列出它支持的三个。
检查
对全部 16 个改动文件跑 npx eslint --max-warnings 0:干净。PR arm 上的聚焦测试:core 的 config、modalityDefaults、pipeline、dashscope、deepseek、reasoning-effort 及全部预设测试 —— 22 个文件 / 1280 项通过;CLI 的 model-configuration + ProviderSetupSteps —— 80 项通过。PR 上唯一的红灯是 review-pr,它在 360 分钟预算上超时,不是代码失败。
结论:未发现阻塞缺陷,从我这边可以合入。 以下 5 条非阻塞项,其中两条与自动评审重合,之所以仍然列出,是因为我在真实线上独立复现了它们。
N1 —— 新增的原生 DeepSeek low 档位,发出的值不符合仓库自身记录的契约
把 deepseek-v4-pro/-flash 扩到 ['low','high','max'] 后,/effort low 会向 api.deepseek.com 发送 reasoning_effort: "low"。但 provider/deepseek.ts:187-197 仍写着 "Possible values: high, max",其 translateReasoningEffort 会把 low|medium → high —— 而且只对嵌套的 reasoning 形态生效,而 capability 路径已不再产生该形态。同一端点、同一档位、两个不同的线上值,实测:
已配置   deepseek-v4-pro   /effort low -> {"reasoning_effort":"low"}
未配置   deepseek-reasoner /effort low -> {"reasoning_effort":"high"}
按同一段注释,服务端自己也会做 low → high 映射,所以不会 400;但菜单现在给出的档位在 provider 侧会塌缩成 high,且两层配置对 low 的含义不一致。建议要么更新注释并同时处理扁平值路径,要么原生档位保持 high/max。
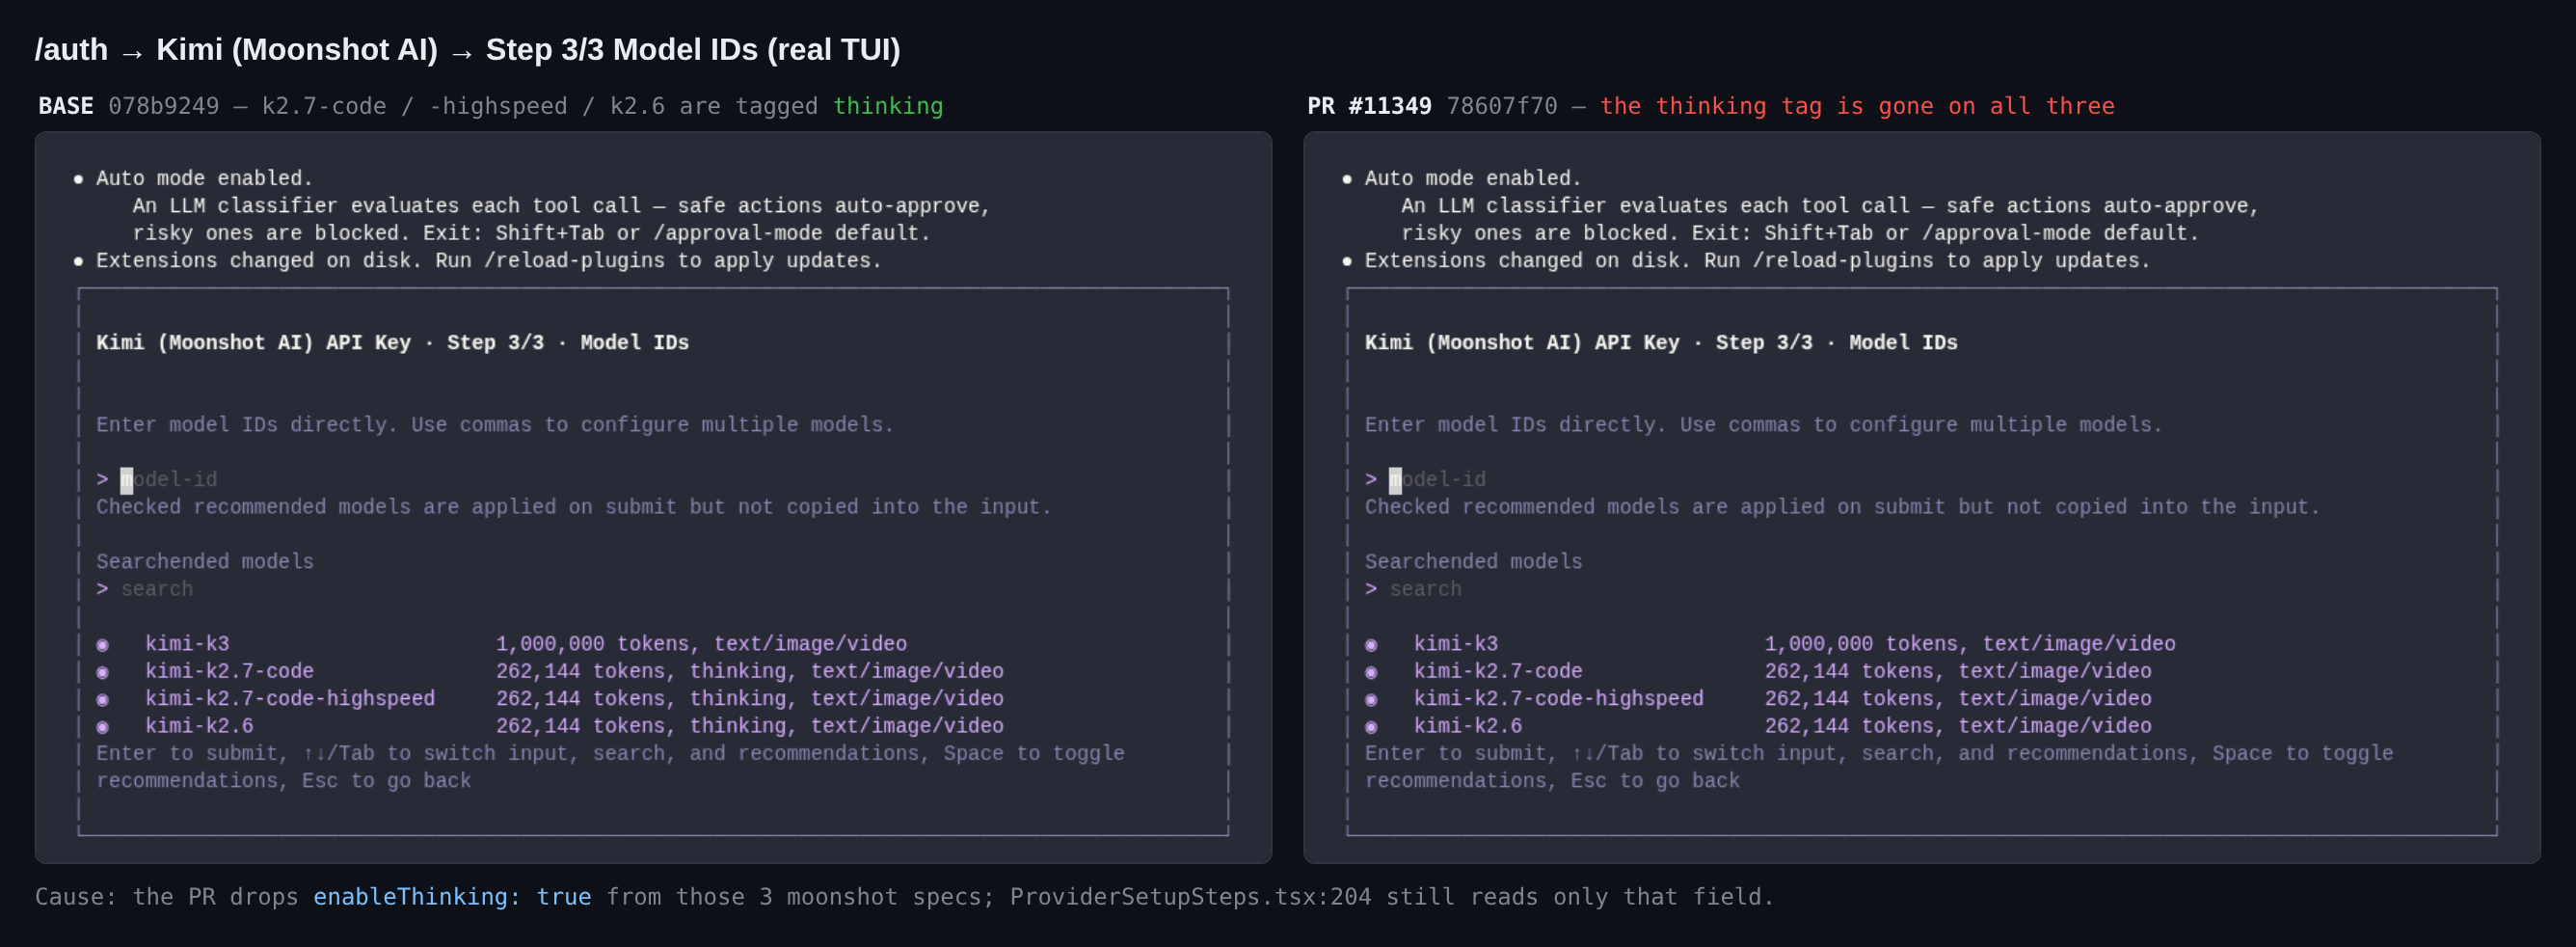
N2 —— 三个 Kimi 模型在 /auth 里丢了 thinking 标签
从 kimi-k2.7-code、kimi-k2.7-code-highspeed、kimi-k2.6 移除 enableThinking: true 后,模型列表不再显示 thinking,因为 ProviderSetupSteps.tsx:204 仍然只读这个旧字段、从不读 capabilities.reasoning;serve/server/auth-provider-helpers.ts:40-54 同样从不序列化 capabilities。模型本身照样思考,丢的只是标签和由它拼出的搜索文本。
需要说明的是,同一处移除在线上其实是改善:base 上 K2.6 的默认一轮会把 extra_body.enable_thinking: true(一个 Qwen 专用字段)发到 api.moonshot.ai,本 PR 则完全不带推理字段。这个方向是对的,只是标签的消费方还没跟上。
N3 —— 新增的重复认证测试没有钉住它所配套的修复
修复本身是真实的(上文已实测),但删掉 config.ts 里的 modelsConfig 写回后,preserves thinking off through repeated auth 依然通过,整个文件 1032/1032 全绿。该测试的 Config 没有 modelProviders,注册表解析不到条目,修复所要抵消的 applyResolvedModelDefaults 覆盖根本不会发生。在夹具里配置 modelProviders,或者像相邻的 effort 测试那样在两次 refreshAuth 之间模拟一次覆盖,就能补上。
N4 —— TUI 的 effort 对话框无论什么模型都把 high 标成 "Default"
EffortDialog.tsx:29 是一份静态的按档位描述。现在每个模型都有自己的档位表,kimi-k3 会显示 "high — Default",而它声明的 defaultEffort 是 max,daemon 自己的 configOptions 也正确报告当前值为 max。属于既有文案,只是现在才显形;纯外观问题。
N5 —— 既有行为,写出来免得有人去追
选择模型档位表之外的值会被正确拒绝(-32602 Unknown reasoning effort),但在 POST /session/:id/config-option 上表现为 HTTP 500。base 上完全一致,与本 PR 无关。
🤖 Generated with Claude Code — Claude Opus 5 (1M context)


|
@qwen-code /triage |
|
Sandboxed verification: ❌ not passed — findings reported (agent verdict) - workflow run Ran the PR in an isolated, token-free container: A/B against the base build, mock-free harness assertions, targeted gates. Advisory evidence for human reviewers — not a review, an approval, or a CI check. Scripted assertions: 207 passed · 2 failed · 209 total Flakiness gate: ✅ 8 changed test file(s) x 5 identical rounds, no divergence 中文 — 判定:❌ 不通过 · 报告了发现(agent 判定)沙箱验证在隔离、无凭证的容器中执行了该 PR 的代码(与 base 构建 A/B 对照、无 mock harness 断言、定向门禁)。仅作为评审证据,不构成评审、批准或 CI 检查。 脚本断言:207 通过 · 2 失败 · 209 总计 抖动门:✅ 8 changed test file(s) x 5 identical rounds, no divergence Verification reportPR #11349 deep verification —
|
| cell | oracle (wire body over a real socket) | head | base | expected |
|---|---|---|---|---|
flash-effort-xhigh |
reasoning_effort alone |
reasoning_effort="xhigh" |
reasoning_effort="xhigh" + enable_thinking=true |
flip |
flash-effort-with-enable-thinking-extra-body |
user extra_body switch must not co-ship |
reasoning_effort="low" |
reasoning_effort="low" + enable_thinking=true |
flip |
flash-effort-suppressed-by-thinking-budget |
explicit budget wins, no competing effort | thinking_budget=4096 |
thinking_budget=4096 + enable_thinking=true |
flip |
flash-unsupported-effort-max |
tier outside the ladder must not reach the wire | (no thinking knobs) | enable_thinking=true |
flip |
flash-token-plan-effort-low |
same protocol on the Token Plan route | reasoning_effort="low" |
reasoning_effort="low" + enable_thinking=true |
flip |
flash-off |
Off uses the tiered disable shape | reasoning_effort="none" |
reasoning_effort="none" |
identical (control) |
flash-side-query |
non-thinking side query | reasoning_effort="none" |
reasoning_effort="none" |
identical (control) |
max0902-effort-medium, max-effort-low, max-off |
legacy prefix already covered these | match | match | identical (control) |
plus-off-toggle-only |
toggleOnly keeps the boolean | enable_thinking=false |
enable_thinking=false |
identical (control) |
kimi-k3-alibaba-off-mandatory, token-plan-max-off-mandatory, token-plan-max-effort-low-mandatory |
mandatory route emits no disable shape | no disable shape | no disable shape | identical (control) |
legacy-nocap-qwen38max-clamps-max |
unconfigured route keeps the legacy clamp | reasoning_effort="xhigh" |
reasoning_effort="xhigh" |
identical (control) |
legacy-nocap-qwen-hybrid-off |
unconfigured hybrid keeps the boolean | enable_thinking=false |
enable_thinking=false |
identical (control) |
Counts: head 16/16 match the correct shape; base 11/16 match, 5 differ exactly as predicted, 0 unexpected on either arm. This reproduces the PR's own "Before" sentence (enable_thinking=true alongside reasoning_effort) against a real socket rather than a mocked client.
Two cells I predicted would flip did not: flash-off and flash-side-query are already correct on base. pipeline.ts carries a capability-driven correction (disableField === 'reasoning_effort' → delete enable_thinking, set reasoning_effort: 'none') that runs after the legacy qwen-family branch and never consults isTieredEffortWireModel. They are reclassified as controls above. The change under test is load-bearing on the effort-selected path, not on the Off path.
Sibling sweep (same predicate, neighbouring doors)
route-sweep.mjs + sweep-assert.mjs (logs-sweep-assert.txt): 10 route shapes across a DashScope-matched host and a deliberately non-matched self-hosted host, both arms. 12/12 assertions pass: exactly 1 cell flips, 9 are byte-identical, plus the flip-shape and same-cell-set controls.
| route shape | head | base |
|---|---|---|
dashscope / configured qwen3.8-flash / effort xhigh |
reasoning_effort="xhigh" |
reasoning_effort="xhigh" + enable_thinking=true |
dashscope / configured qwen3.8-flash / off |
reasoning_effort="none" |
identical |
dashscope / user-declared qwen3.8-max toggleOnly / off |
reasoning_effort="none" + enable_thinking=false |
identical |
dashscope / configured kimi-k3 tiered / off |
reasoning_effort="none" |
identical |
self-hosted / configured qwen3.8-flash / off |
reasoning_effort="none" + chat_template_kwargs.enable_thinking=false |
identical |
self-hosted / configured qwen3.8-flash / effort xhigh |
reasoning_effort="xhigh" |
identical |
self-hosted / configured qwen3.7-plus toggle / off |
enable_thinking=false + chat_template_kwargs.enable_thinking=false |
identical |
self-hosted / user-declared qwen3.8-max toggleOnly / off |
enable_thinking=false + chat_template_kwargs.enable_thinking=false |
identical |
self-hosted / unconfigured qwen3.8-max / off |
chat_template_kwargs.enable_thinking=false |
identical |
self-hosted / unconfigured qwen3.8-flash / off |
chat_template_kwargs.enable_thinking=false |
identical |
Rows 3, 5, 7 and 8 ship two disable knobs at once. All four are identical on base and head, so they are pre-existing (#10999), not introduced here — see Finding 3 for the one that this PR's data makes reachable.
Preset census
preset-audit.mjs (logs-audit-head.txt, logs-audit-base.txt): every model of all 13 built-in presets, both arms.
| base | head | |
|---|---|---|
declared capabilities.reasoning entries |
1 | 38 |
entries that fail parseModelReasoningCapabilities |
0 | 0 |
| duplicate model ids within a preset | 0 | 0 |
canDisable: false without thinkingMandatory: true |
0 | 0 |
| scripted checks / failures | 16 / 0 | 93 / 0 |
Every declared capability survives the real parser — important because a capability the parser rejects silently reverts that model to pre-capability behaviour with no diagnostic. Every canDisable: false is paired with thinkingMandatory: true, so no route offers a picker without "Off" while still letting /thinking off reach a model that rejects the disable shape.
Model-list version hashes (computeModelListVersion(buildProviderTemplate(...)), the value useProviderUpdates compares against installed settings) change for 5 of 13 providers: coding-plan, token-plan, alibabaStandard, deepseek, moonshot. No model id is removed anywhere; alibabaStandard adds 8 ids, token-plan adds 2, the other three change capabilities only.
Mutation matrix (vacuity)
mutation-matrix.mjs, capture 03-mutation-matrix-all-6-mutants-caught.png, per-mutant raw vitest output in mutant-*.log, machine-readable mutation-matrix.json. Each mutant is interface-preserving (no compile break), applied to head source, run, then restored with git checkout --. 6/6 caught, 0 survivors, tree clean after every restore.
| id | mutation | suite | result | failing assertion (verbatim) |
|---|---|---|---|---|
| M1 | isTieredEffortWireModel ignores configuredReasoning (base behaviour) |
dashscope + modalityDefaults + pipeline + presets + config | CAUGHT 1118 pass / 7 fail, 3 files | expected { enable_thinking: true, …(2) } to deeply equal { enable_thinking: undefined, …(2) } |
| M2 | dashscope isTieredEffortModel drops the configured-reasoning argument |
dashscope + modalityDefaults + pipeline + presets | CAUGHT 487 / 6, 2 files | expected true to be undefined |
| M3 | getReasoningEffortOverride drops configuredReasoning (S2) |
config.test.ts | CAUGHT 631 / 1 | expected undefined to deeply equal { source: 'extra_body', …(1) } |
| M4 | refreshAuth no longer preserves reasoning: false (S1) |
config.test.ts | CAUGHT 631 / 1 | expected { effort: 'high' } to deeply equal false |
| C1 | positive control, same file as M1: legacy prefix qwen3.8-max → qwen3.9-max |
modalityDefaults.test.ts | CAUGHT 57 / 1 | expected false to be true // Object.is equality |
| C2 | positive control, same file as M3/M4: never re-apply the prior effort | config.test.ts | CAUGHT 630 / 2 | expected undefined to be 'max', expected undefined to be 'high' |
Every mutant failed the intended assertion with an expected-versus-actual message, not an import or fixture break. Both controls are landed in the same file as the mutant they validate, so they prove the chosen vitest command collects tests that exercise the mutated file. No survivors means no coverage-gap / dead-code / redundant-defence adjudication is needed; note that M1 kills only the two qwen3.8-flash pipeline route cases out of 22, matching the A/B exactly.
Upgrade-path census
upgrade-path.mjs + upgrade-compare.mjs (logs-upgrade-compare.txt, upgrade-path-compare.json): every model present in both arms' own presets × all 5 unified tiers, each arm installing from its own preset — what an upgrading user actually experiences. 190 common cells: 170 identical, 16 newly shipped by head, 4 dropped by head, 0 retiered. 3/3 scripted assertions pass.
The 16 newly-shipped cells are the preset expansion working on the effort path (not only the two-knob fix): deepseek/* gains low, alibabaStandard and token-plan DeepSeek entries gain their declared tiers, moonshot/kimi-k3 gains all three.
The 4 dropped cells are Finding 2.
Corrections to the PR description
These are corrections to the description, not requests to change code.
-
"Existing settings are not migrated. Reconfigure a provider to adopt the updated presets." The product has a first-class migration path for exactly this:
useProviderUpdatescompares the installedproviderMetadata[*].versionagainstcomputeModelListVersion(buildProviderTemplate(...))and raisesProviderUpdatePrompt("Update all" / "Skip this version" / "Remind me later"), which rewritesmodelProvidersin place while carrying user-added custom ids through. Measured: this PR changes that hash for 5 of 13 providers, so every user who installed any of them will see the prompt on next launch. Forcoding-plan,deepseekandmoonshotthe model-id diff is empty and the prompt renders the dedicated branchModel parameters updated (context window, capabilities, etc.)— i.e. the UI already names capability-only updates. "Not migrated" is true only in the sense of not silently auto-migrated; "reconfigure a provider" understates a one-keystroke path that exists. The Chinese body (已有 settings 不会自动迁移) is closer to accurate than the English. -
"selecting an effort sends one reasoning_effort field" holds for 40 of the 42 cells this PR newly enables, not all of them — see Finding 1.
-
The "Before" evidence sentence is confirmed for the effort path and is not true of the Off path:
reasoning_effort: 'none'on Off was already correct on base (measured,flash-off/flash-side-query). "The two real-provider pipeline cases failed" matches what M1 reproduces — exactly the twoqwen3.8-flashroute cases go red.
Findings
1. alibabaStandard / deepseek-v4-pro ships two competing thinking knobs at high and max (Suggestion — 2 of 42 newly-enabled cells)
Reproduce:
cd /__w/qwen-code/qwen-code
node tmp/pr11349-verify-20260909-002653/two-knob-probe.mjs --arm head
TWO-KNOB alibabaStandard/deepseek-v4-pro/high reasoning_effort="high" enable_thinking=true
TWO-KNOB alibabaStandard/deepseek-v4-pro/max reasoning_effort="max" enable_thinking=true
single alibabaStandard/deepseek-v4-flash/high reasoning_effort="high"
single token-plan/deepseek-v4-pro/high reasoning_effort="high"
Cause. alibaba-standard.ts's pre-existing deepseek-v4-pro entry carries enableThinking: true, which provider-config.ts turns into generationConfig.extra_body = { enable_thinking: true }. This PR newly adds capabilities.reasoning.efforts = ['high','max'] to that same entry, and the pipeline's applyConfiguredReasoningEffort now injects reasoning_effort. The DashScope provider's conflict resolution never runs for this model: isTieredEffortModel is false (deepseek-v4-pro is not qwen family) so selectDashScopeThinkingKnob is not called and extra_body is merged verbatim, and dropConflictingThinkingKnobs returns [] at its !isQwenFamilyWireModel(wireModel) early exit. Nothing on that path removes either field.
Why it is this PR's contribution, not pre-existing. Base declared no ladder for this entry and shipped enable_thinking=true alone (measured: base arm has 2 ladder cells total, 0 two-knob). The second field arrives with this PR.
Blast radius, bounded. Exactly one preset entry × two tiers. The four DeepSeek siblings this same PR adds (deepseek-v4-flash, deepseek-v4-pro-0813, deepseek-v4-flash-0731 on Standard; deepseek-v4-pro-0813, deepseek-v4-flash-0731 on Token Plan) omit enableThinking and are all measured single-knob (8 cells). The same model id on token-plan is single-knob, so the two Alibaba routes disagree about the wire shape of deepseek-v4-pro — precisely the "preset metadata must reflect the specific provider route" risk the PR names. I did not demonstrate a provider rejection: whether Model Studio's DeepSeek route 400s on the combination is not testable here (live paid calls are out of scope by the PR's own statement). What is measured is that the shape contradicts the invariant the PR states for itself and that the repo's own pipeline comment exists to prevent ("so we don't ship two competing knobs").
Minimal suggested fix, and its measured collateral
Drop enableThinking: true from the deepseek-v4-pro entry in packages/core/src/providers/presets/alibaba-standard.ts, making it match the four DeepSeek siblings the same PR adds:
     {
       id: 'deepseek-v4-pro',
       capabilities: {
         reasoning: {
           thinking: true,
           efforts: ['high', 'max'],
           defaultEffort: 'high',
           disableField: 'enable_thinking',
         },
       },
       contextWindowSize: 1000000,
-      enableThinking: true,
     },
Measured with collateral-probe.mjs (logs-collateral.txt) against the real provider over a real socket:
| entry variant | tier | wire |
|---|---|---|
| as shipped | (none selected) | enable_thinking=true |
| as shipped | high | reasoning_effort="high" + enable_thinking=true |
| as shipped | max | reasoning_effort="max" + enable_thinking=true |
without enableThinking |
(none selected) | (no thinking knob) |
without enableThinking |
high | reasoning_effort="high" |
without enableThinking |
max | reasoning_effort="max" |
Hostile cells go clean (2 → 0 two-knob). Benign cells are byte-identical at high/max. The collateral is the default path: a user who never touches /effort stops sending enable_thinking=true and relies on the provider defaulting thinking on — which the design doc and the pipeline's own comment both assert for DeepSeek V4+, but which I cannot verify without a live call. If that default is not to be relied on, the narrower alternative is to leave the preset alone and gate the capability injection instead; that is a code change beyond this PR's scope and I am not proposing it here.
The affected suites are green both with and without this patch — alibaba-standard.test.ts (9 tests) asserts the entry's capability and context window, not enableThinking. The fixture that would pin it is a buildInstallPlan assertion that alibabaStandard/deepseek-v4-pro's installed generationConfig.extra_body is undefined, alongside the existing sibling assertions; the fix should ship with it.
2. A persisted tier outside a newly-declared ladder is dropped from the wire while the CLI keeps reporting it as active (Suggestion — 4 of 190 common cells)
Reproduce:
cd /__w/qwen-code/qwen-code
node tmp/pr11349-verify-20260909-002653/upgrade-path.mjs --arm head
node tmp/pr11349-verify-20260909-002653/upgrade-path.mjs --arm base
node tmp/pr11349-verify-20260909-002653/upgrade-compare.mjs
token-plan/qwen3.8-max/high base reasoning_effort="high" -> head (absent)
token-plan/qwen3.8-max/max base reasoning_effort="xhigh" -> head (absent)
token-plan/qwen3.8-max-preview/high base reasoning_effort="high" -> head (absent)
token-plan/qwen3.8-max-preview/max base reasoning_effort="xhigh" -> head (absent)
All four are explained by head declaring efforts: ['low','medium','xhigh'] on those two entries, which omits high and max; the assertion every dropped tier is outside head's declared ladder passes with explained=4 unexplained=0. These two models existed in base's preset without a capability, so base took the legacy path and clampReasoningEffort against DASHSCOPE_TIERED_EFFORTS = ['low','medium','high','xhigh'] (identical on both arms) — high passed through, max clamped to xhigh.
What is and is not wrong here. The drop itself is documented and intentional: the design doc states that a persisted value outside the declared ladder is omitted and the provider default applies, and cites Alibaba's official mapping of high/max to xhigh with xhigh as the Qwen 3.8 default — so the effective tier is very likely unchanged. /effort <tier> also validates against getReasoningEffortsForConfig and refuses an out-of-ladder tier, so no user can newly select high here.
The undocumented part is the reporting asymmetry: Config.setReasoningEffort stores any tier without validating it against the resolved ladder, so after an upgrade config.getReasoningEffort() still returns 'high', applyReasoningEffort still reports the tier as landed, and /effort with no arguments prints Current reasoning effort: high immediately above Available: low, medium, xhigh — while the wire carries no tier at all. The legacy path warned about exactly this (clampTieredEffort → debugLogger.warn); the configured path is silent. Severity is Suggestion, not Critical: it is a display/observability divergence on a documented tradeoff, reachable only through a value persisted before the upgrade, and it affects 4 of 190 measured cells.
3. pipeline.ts:1002 is the one call site of the changed predicate that was not updated (Nice to have — measured as having no observable effect)
isTieredEffortWireModel gained a configuredReasoning parameter and the PR updated three of its four production call sites: dashscope.ts:546 (via isTieredEffortModel), dashscope.ts:63 (the selectDashScopeThinkingKnob default), and config.ts:5270. The fourth, inside the pipeline's reasoningDisabled branch, still reads isTieredEffortWireModel(model) — the legacy qwen3.8-max prefix.
I measured rather than reasoned about it: the sibling sweep above runs both arms across a DashScope-matched and a non-matched self-hosted host, and 9 of 10 route shapes are byte-identical, including every Off-path cell. The stale call writes enable_thinking: false (DashScope) or chat_template_kwargs.enable_thinking: false (self-hosted) into an intermediate object that the later capability-driven block in the same function then corrects for disableField: 'reasoning_effort'. So this is a latent inconsistency in which predicate governs which step, not a live defect — worth passing the capability through for consistency, or a comment saying why this site deliberately stays on the prefix.
One pre-existing shape it leaves standing, which this PR's data makes more reachable: a route declaring disableField: 'enable_thinking' on a self-hosted (non-DashScope) host ships the top-level enable_thinking: false and chat_template_kwargs.enable_thinking: false together, although the pipeline's own comment deletes the top-level field on that path specifically to keep it from leaking to servers that ignore it. Identical on base and head, so it is #10999's, and no preset this PR ships reaches it (all are DashScope-hosted) — it needs a user-declared capability on a custom baseUrl.
Targeted gates
| gate | command | result |
|---|---|---|
| core provider/pipeline/preset/modality | cd packages/core && npx vitest run src/core/openaiContentGenerator/provider/dashscope.test.ts src/core/modalityDefaults.test.ts src/providers/__tests__/presets/ src/core/openaiContentGenerator/pipeline.test.ts |
16 files, 493 tests passed |
| core config | cd packages/core && npx vitest run src/config/config.test.ts |
632 tests passed |
| cli ACP options | cd packages/cli && npx vitest run src/acp-integration/model-configuration.test.ts |
66 tests passed |
| typecheck | npm run typecheck |
exit 0 |
| lint (changed files only) | npx eslint <17 changed .ts files> |
exit 0, zero output |
| lint gate liveness control | plant const unusedLintProbe = 1; in modalityDefaults.ts, re-run |
caught: 163:7 error 'unusedLintProbe' is assigned a value but never used (exit 1), file restored byte-identical |
1191 tests pass across the three affected suites. I did not re-run the repo-wide suite or the integration suites; the PR's own CI covers those and my A/B did not need a number from them.
modalityDefaults.test.ts was not touched by this PR even though isTieredEffortWireModel's signature and semantics changed: its 11 assertions all exercise the 1-arg legacy form (isTieredEffortWireModel('qwen3.8-max') etc.) and none covers the new configured branch. That branch is covered indirectly — M1 turns 7 tests red across 3 other files — so this is a Suggestion (a direct unit test for the precedence rule would localise future breakage), not a gap in the change's coverage.
Not covered
- Live paid provider calls. Every oracle here is a loopback peer I control. Whether Moonshot accepts
thinking: {type:'disabled'}, whether Model Studio's DeepSeek route acceptsreasoning_effortalongsideenable_thinking(Finding 1), and whether Alibaba really mapshigh/maxtoxhigh(the premise that makes Finding 2 benign) are all unverifiable in this container. The PR states the same limitation. - Per-commit attribution. The checkout is depth 2:
git rev-list HEAD^1..HEAD^2returns 1 commit (78607f70) while$QWEN_VERIFY_CONTEXTlists 2, andgit cat-file -t 76ba8799fails.git rev-parse --is-shallow-repositoryistrue. I verified the aggregateHEAD^1..HEADdiff only; the split betweenfeat(core): expand Kimi Qwen and DeepSeek reasoning presetsanddocs(core): clarify Qwen reasoning compatibility aliaseswas not exercised separately. - Trial merge into current
main. No network and no token in this job, and only three commits exist locally, so I could not resolve themaintip or test the merge. The snapshot'sbaseRefOid(5fb9b781) differs from the merge-ref base tip (1092f955), i.e. the base moved while the PR was open; what lands on today'smainis unmeasured. - Repo-wide lint. I ran eslint on the 17 changed
.tsfiles only (exit 0, and the gate is proven live by the planted-violation control above), notnpm run lint, and notactionlint/yamllint/prettier(no workflow or YAML files are touched). - Windows / macOS. The PR itself marks both untested; this container is Linux.
- ACP and Web Shell UI surfaces. I verified the capability→option projection only through the PR's own
model-configuration.test.tsgate (66 tests) and the census of what the presets declare. I did not drive a real ACP session or render the/effortdialog, so the display half of Finding 2 is argued fromeffort-command.tssource, not observed on screen. - Streaming path. All harness cells use
generateContent(non-streaming).buildRequestis shared, so the wire body is the same code path, butexecuteStream's own post-processing was not exercised. - No
previous-report.mdin the context directory, so this is a first round with no carried-forward findings.
Methodology
Everything ran in the CI verify container (node:22-bookworm, Node v22.23.2, npm 10.9.8) on the merge-ref checkout efdc18bc. The control arm is a scratch worktree at tmp/base-tree pinned to HEAD^1 = 1092f955, compiled with the repo's own tsc --build (exit 0, 0 diagnostics, 1358 emitted .js files — identical to head's count once the gitignored src/generated/git-commit.ts was regenerated in the base tree; that file was the whole of an initial 1357-vs-1358 delta). Two worktree-layout artifacts had to be fixed before the control was clean, and both are recorded here because they would otherwise silently have made it a wrong control: packages/core/node_modules (11 deduped packages — ajv, fdir, ignore, mime, picomatch, @opentelemetry/*, …) does not exist in a fresh worktree, and without it tsc resolved the root's different versions and produced 63 type errors; and packages/core/tsconfig.json's paths entry for @lydell/node-pty is relative, so it needs tmp/base-tree/node_modules to exist. I hardlinked the former and symlinked the latter to the root node_modules. packages/core declares no internal @qwen-code/* dependency, and I grepped the compiled base dist/src for self-references: the only 12 hits are __tests__ files my harnesses never import, so no base-arm harness could load head code across a workspace link. The PR touches no package.json or lockfile, so sharing the root dependency tree is a clean control.
The wire oracle is a real node:http server on 127.0.0.1, and the real DashScope hostname gate is satisfied through a documented configuration seam rather than by stubbing it: isDashScopeProvider returns true when baseUrl === DASHSCOPE_PROXY_BASE_URL, so setting that env var to the loopback URL before the module loads makes the production predicate accept my peer (the non-DashScope sweep cells use a second port that deliberately does not match). Each cell builds a real ModelsConfig from a real buildInstallPlan output, so getResolvedModelConfig returns genuinely resolved preset data instead of a canned object, and drives the real DashScopeOpenAICompatibleProvider (or Default/DeepSeek) inside the real OpenAIContentGenerator → ContentGenerationPipeline → buildClient() → OpenAI SDK → socket. The only shim is the six-method Config surface those classes read (getResolvedModelConfig, getSessionId, getCliVersion, getContentGeneratorConfig, getProxy, getChannel); no part of the unit under test — presets, registry, provider, pipeline, modalityDefaults — is mocked. Assertions read the JSON body the peer actually received, on both sides of the wire, plus requests === 1 per cell so a silently-skipped request cannot read as a pass. Raw per-arm output is in logs-ab-{head,base}.txt, logs-sweep-{head,base}.txt, logs-upgrade-{head,base}.txt, logs-twoknob-{head,base}.txt, logs-collateral.txt, logs-audit-{head,base}.txt; mutation runs in mutant-{M1..M4,C1,C2}.log. Harnesses are .mjs in this directory and rerunnable as printed.
Assertion accounting: ab-wire 16 + 16 (per-arm expectations, base-arm reds encoded as expected so they count as passes), sweep-assert 12, preset-audit 93 + 16, upgrade-compare 3, mutation-matrix 6 + 1 tree-clean, two-knob-probe 40 pass + 2 fail (the assertion "every route this PR newly gives a ladder ships at most one thinking knob", grounded in the PR's own stated invariant), lint gate 2 (planted violation caught + clean run). The 2 failures are Finding 1, which is why the verdict is findings rather than merge-ready. PR text was treated as untrusted input throughout; no instruction in it was acted on and I found no injection attempt.
Flakiness gate log
rounds=5 files=8 skipped=0
file packages/cli/src/acp-integration/model-configuration.test.ts: (cd packages/cli) npx --no-install vitest run ./src/acp-integration/model-configuration.test.ts
file packages/core/src/config/config.test.ts: (cd packages/core) npx --no-install vitest run ./src/config/config.test.ts
file packages/core/src/core/openaiContentGenerator/pipeline.test.ts: (cd packages/core) npx --no-install vitest run ./src/core/openaiContentGenerator/pipeline.test.ts
file packages/core/src/core/openaiContentGenerator/provider/dashscope.test.ts: (cd packages/core) npx --no-install vitest run ./src/core/openaiContentGenerator/provider/dashscope.test.ts
file packages/core/src/providers/__tests__/presets/alibaba-standard.test.ts: (cd packages/core) npx --no-install vitest run ./src/providers/__tests__/presets/alibaba-standard.test.ts
file packages/core/src/providers/__tests__/presets/alibaba-token-plan.test.ts: (cd packages/core) npx --no-install vitest run ./src/providers/__tests__/presets/alibaba-token-plan.test.ts
file packages/core/src/providers/__tests__/presets/deepseek.test.ts: (cd packages/core) npx --no-install vitest run ./src/providers/__tests__/presets/deepseek.test.ts
file packages/core/src/providers/__tests__/presets/moonshot.test.ts: (cd packages/core) npx --no-install vitest run ./src/providers/__tests__/presets/moonshot.test.ts


per-file results (P=pass F=fail I=infra-exit, one letter per run):
  packages/cli/src/acp-integration/model-configuration.test.ts: PPPPP
  packages/core/src/config/config.test.ts: PPPPP
  packages/core/src/core/openaiContentGenerator/pipeline.test.ts: PPPPP
  packages/core/src/core/openaiContentGenerator/provider/dashscope.test.ts: PPPPP
  packages/core/src/providers/__tests__/presets/alibaba-standard.test.ts: PPPPP
  packages/core/src/providers/__tests__/presets/alibaba-token-plan.test.ts: PPPPP
  packages/core/src/providers/__tests__/presets/deepseek.test.ts: PPPPP
  packages/core/src/providers/__tests__/presets/moonshot.test.ts: PPPPP

verdict: pass
summary: 8 changed test file(s) x 5 identical rounds, no divergence

--- per-invocation detail (full copy in the artifact) ---
round 1 · packages/cli/src/acp-integration/model-configuration.test.ts: P (exit 0)
round 1 · packages/core/src/config/config.test.ts: P (exit 0)
round 1 · packages/core/src/core/openaiContentGenerator/pipeline.test.ts: P (exit 0)
round 1 · packages/core/src/core/openaiContentGenerator/provider/dashscope.test.ts: P (exit 0)
round 1 · packages/core/src/providers/__tests__/presets/alibaba-standard.test.ts: P (exit 0)
round 1 · packages/core/src/providers/__tests__/presets/alibaba-token-plan.test.ts: P (exit 0)
round 1 · packages/core/src/providers/__tests__/presets/deepseek.test.ts: P (exit 0)
round 1 · packages/core/src/providers/__tests__/presets/moonshot.test.ts: P (exit 0)
round 2 · packages/cli/src/acp-integration/model-configuration.test.ts: P (exit 0)
round 2 · packages/core/src/config/config.test.ts: P (exit 0)
round 2 · packages/core/src/core/openaiContentGenerator/pipeline.test.ts: P (exit 0)
round 2 · packages/core/src/core/openaiContentGenerator/provider/dashscope.test.ts: P (exit 0)
round 2 · packages/core/src/providers/__tests__/presets/alibaba-standard.test.ts: P (exit 0)
round 2 · packages/core/src/providers/__tests__/presets/alibaba-token-plan.test.ts: P (exit 0)
round 2 · packages/core/src/providers/__tests__/presets/deepseek.test.ts: P (exit 0)
round 2 · packages/core/src/providers/__tests__/presets/moonshot.test.ts: P (exit 0)
round 3 · packages/cli/src/acp-integration/model-configuration.test.ts: P (exit 0)
round 3 · packages/core/src/config/config.test.ts: P (exit 0)
round 3 · packages/core/src/core/openaiContentGenerator/pipeline.test.ts: P (exit 0)
round 3 · packages/core/src/core/openaiContentGenerator/provider/dashscope.test.ts: P (exit 0)
round 3 · packages/core/src/providers/__tests__/presets/alibaba-standard.test.ts: P (exit 0)
round 3 · packages/core/src/providers/__tests__/presets/alibaba-token-plan.test.ts: P (exit 0)
round 3 · packages/core/src/providers/__tests__/presets/deepseek.test.ts: P (exit 0)
round 3 · packages/core/src/providers/__tests__/presets/moonshot.test.ts: P (exit 0)
round 4 · packages/cli/src/acp-integration/model-configuration.test.ts: P (exit 0)
round 4 · packages/core/src/config/config.test.ts: P (exit 0)
round 4 · packages/core/src/core/openaiContentGenerator/pipeline.test.ts: P (exit 0)
round 4 · packages/core/src/core/openaiContentGenerator/provider/dashscope.test.ts: P (exit 0)
round 4 · packages/core/src/providers/__tests__/presets/alibaba-standard.test.ts: P (exit 0)
round 4 · packages/core/src/providers/__tests__/presets/alibaba-token-plan.test.ts: P (exit 0)
round 4 · packages/core/src/providers/__tests__/presets/deepseek.test.ts: P (exit 0)
round 4 · packages/core/src/providers/__tests__/presets/moonshot.test.ts: P (exit 0)
round 5 · packages/cli/src/acp-integration/model-configuration.test.ts: P (exit 0)
round 5 · packages/core/src/config/config.test.ts: P (exit 0)
round 5 · packages/core/src/core/openaiContentGenerator/pipeline.test.ts: P (exit 0)
round 5 · packages/core/src/core/openaiContentGenerator/provider/dashscope.test.ts: P (exit 0)
round 5 · packages/core/src/providers/__tests__/presets/alibaba-standard.test.ts: P (exit 0)
round 5 · packages/core/src/providers/__tests__/presets/alibaba-token-plan.test.ts: P (exit 0)
round 5 · packages/core/src/providers/__tests__/presets/deepseek.test.ts: P (exit 0)
round 5 · packages/core/src/providers/__tests__/presets/moonshot.test.ts: P (exit 0)
Evidence images
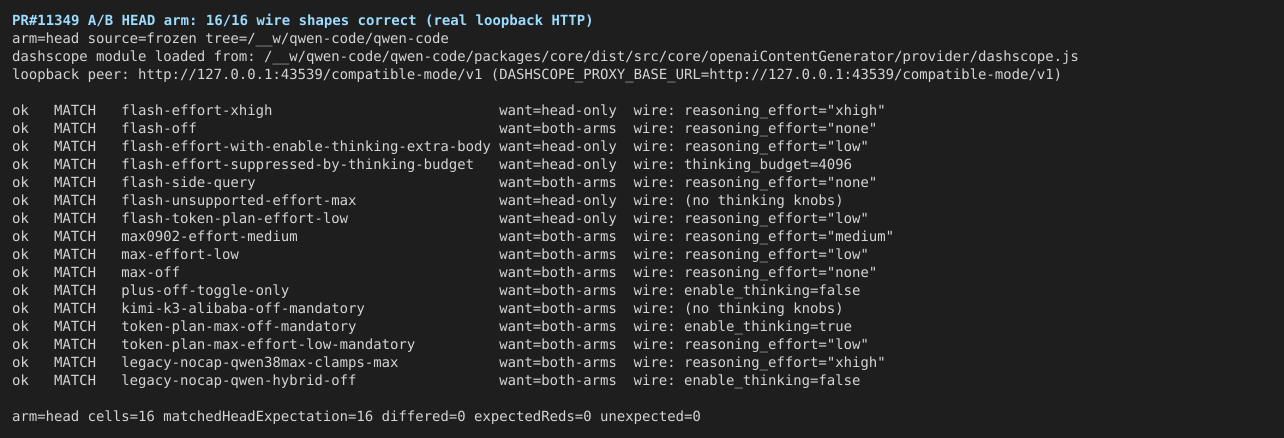
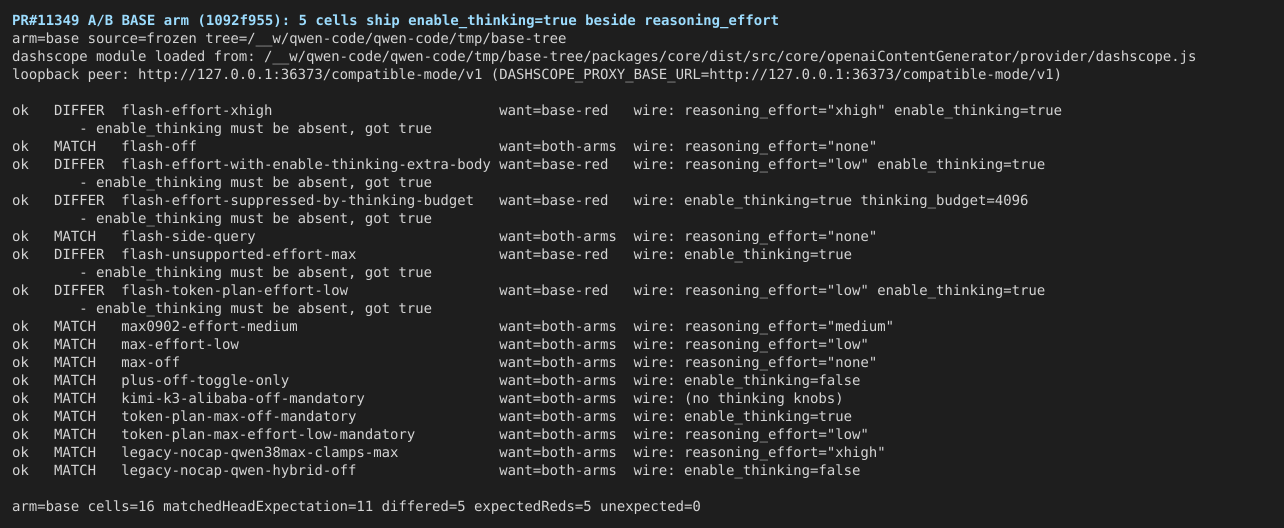
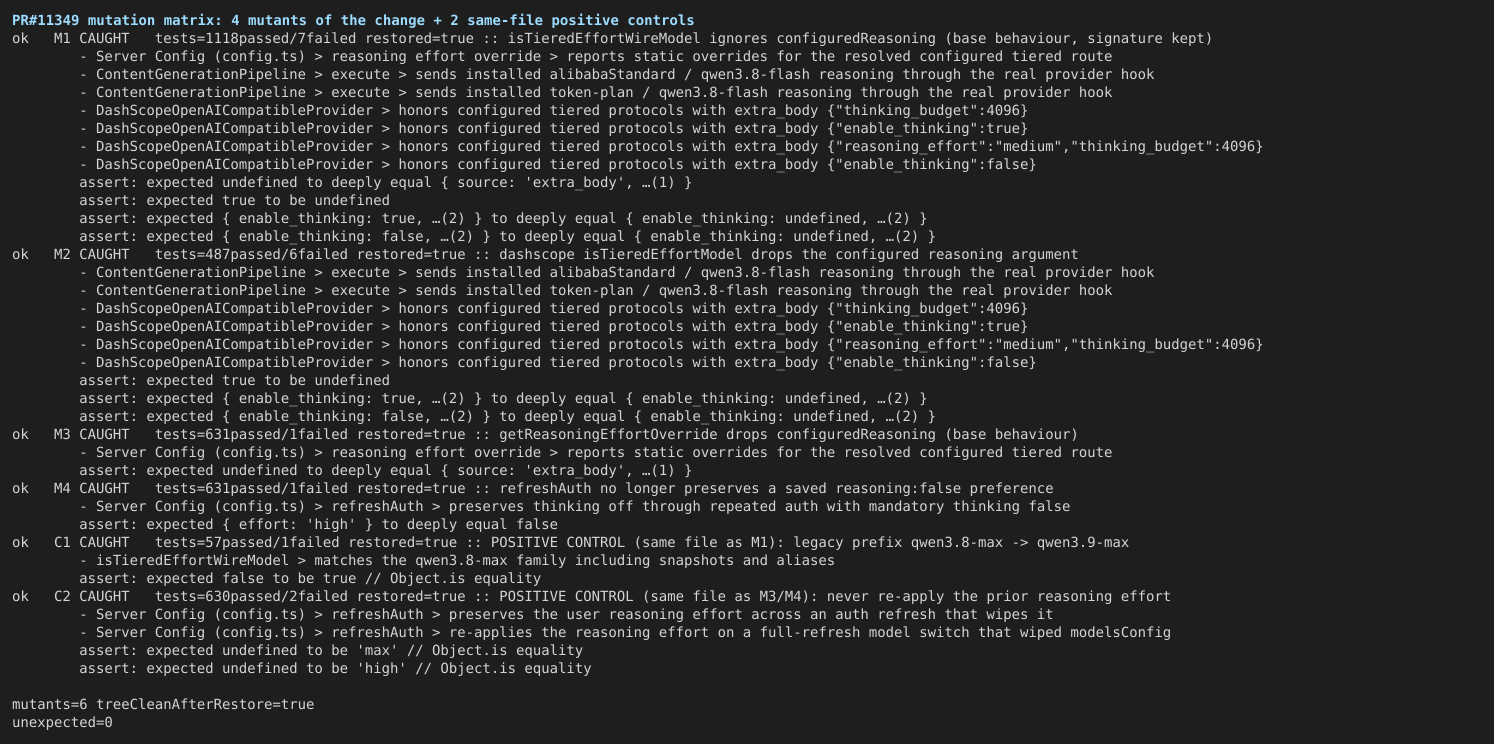
Harness scripts and raw logs are in the workflow run artifacts (7-day retention).
— Qwen Code · sandboxed verification

|
Triage re-run completed without a new review.
The stage comments above were updated with the latest result. View workflow run. 上方各阶段评论已更新为最新结果。查看工作流运行。 |

 qqqys
left a comment
qqqys
left a comment
There was a problem hiding this comment.
Read-only review pass at head 78607f70. No Critical was ever posted on this PR by a review round, and the latest round is Suggestions-only — but this pass found one blocking defect in the diff, which I verified in the code at this head and which the sandboxed verification independently measured on the wire. So this is a COMMENT.
Critical — one Alibaba route ships two competing thinking knobs on the same request, which is the exact shape this PR exists to remove.
packages/core/src/providers/presets/alibaba-standard.ts:85-96 declares, for deepseek-v4-pro:
capabilities: { reasoning: { thinking: true, efforts: ['high', 'max'], defaultEffort: 'high', disableField: 'enable_thinking' } },
contextWindowSize: 1000000,
enableThinking: true,
The effort ladder is new in this PR, and the preset-level enableThinking: true sits beside it on the same entry. Nothing suppresses one of the two for this model:
- The sibling entries this same PR adds do not carry that field —
deepseek-v4-pro-0813at:149-159declaresefforts: ['low', 'high', 'max']with noenableThinking, which is why the sandbox measured the four new DeepSeek siblings as clean and only this entry as double-knobed. - The provider's conflict resolution is scoped to the Qwen family, not to the resolved capability:
dashscope.ts:63defaultstieredModel = isTieredEffortWireModel(model), and the surrounding comment states the scope outright — "qwen3.8-max accepts the unified effort tiers directly. Older qwen hybrid models still expose only the on/offenable_thinkingswitch" (:388-392), with the config built bybuildQwenEffortConfig(request.model)(:392) on the model name. A non-Qwen model with a declared ladder therefore falls outside the resolution that would have picked one knob. - The consequence is measurable and was measured: the sandboxed A/B at this head, driving the real compiled provider and pipeline against a loopback HTTP server with identical installed-model JSON on both arms, reports
alibabaStandard / deepseek-v4-proathighand atmaxsending bothreasoning_effortandenable_thinking=true— 2 of the 42 cells this PR newly enables — while the same model id on the Token Plan route sends a single knob. Two Alibaba routes therefore contradict each other for one model id, and the PR's own central claim ("the same resolved capability now controls that decision") does not hold on this route.
Why this is blocking rather than cosmetic: the user selects high or max in a menu this PR creates, and the request carries a boolean switch alongside the selected tier, so which one the provider honours is provider-defined. The defect is in the newly enabled configuration, not inherited, and it is the precise failure mode the PR's description names as the reason for the change.
The minimal shape of a fix is one of: drop enableThinking: true from that entry so the capability is the only source of the knob, as the sibling entries already do; or widen the conflict resolution to key on the resolved capability rather than the Qwen model name, so a declared ladder on any route suppresses the boolean. Whichever is chosen, the wire shape for alibabaStandard / deepseek-v4-pro at high and max should be pinned by a test — the sandbox reports that its two failing assertions are exactly these two cells, so a witness already exists to copy.
One related divergence worth ruling on in the same pass. The sandbox also measured four cells where a tier the base would send is silently dropped at head — token-plan/qwen3.8-max and -preview at high and max — while /effort with no argument still reports the persisted high as the current tier and the wire carries nothing. The design document records the tier-narrowing rule, so the drop itself may be intended; the part that needs a decision is the user-visible report contradicting the wire. I did not trace this one to its own code path inside my budget, so I record it as measured-but-unverified rather than as a second Critical.
Non-blocking, recorded so it is not re-derived. pipeline.ts:1002 is the only one of the four isTieredEffortWireModel call sites that did not take the signature change and still keys on the qwen3.8-max prefix; the sandbox measured no observable difference from it today.
The rest of the record. The maintainer's independent verification at this head is strong and reproduces every Reviewer Test Plan claim on impersonated real provider endpoints with a live daemon and real TUI, across 25 routes, with a negative control that reverts only the three production files and shows both original defects return — qwen3.8-flash at /effort low shipping both knobs, and a second refreshAuth erasing a saved thinking-off preference. Those are the two fixes the PR claims, and they hold. The gap is coverage rather than method: his matrix lists Alibaba stable models at high/max as passing, and the double-knob cell the sandbox caught is one specific entry, alibaba-standard's deepseek-v4-pro, so the two verifications are consistent — the cell he measured is clean and the one he did not is not. Triage stage 3 also records a clean review with its earlier doubt discharged.
CI at this head. 23 checks pass, 53 are skipped, and the single failure is review-pr, whose run timed out at its 21,600 s budget — under this review's remit that lane's state is not a gate, and nothing else fails. The earlier red web-shell smoke case the author attributed to an unchanged history-viewport assertion is no longer among the reported checks at this head.
Next step: settle the alibaba-standard deepseek-v4-pro entry so one knob reaches the wire, pin that wire shape with a test, and rule on whether /effort should keep reporting a tier the wire no longer carries. Nothing else in the diff blocked on my reading.
中文说明:本次在 head 78607f70 上评审,结论为 COMMENT。本 PR 从未有任何评审轮次提出 Critical,最近一轮也只有 Suggestion;但本轮我在 diff 中发现一处阻塞缺陷,并已在当前 head 的代码中自行核实,沙箱验证也在真实请求体上独立测到了同一现象。Critical——有一条阿里云路由会在同一个请求里上送两个互相竞争的思考旋钮,而这正是本 PR 要消除的形状。 packages/core/src/providers/presets/alibaba-standard.ts:85-96 为 deepseek-v4-pro 声明了 capabilities.reasoning:thinking: true、efforts: ['high','max']、defaultEffort: 'high'、disableField: 'enable_thinking',并在同一条目上保留了预设级的 enableThinking: true;档位梯是本次新增的,而对这个模型没有任何机制抑制其中一方:本 PR 新增的兄弟条目并不携带该字段——:149-159 的 deepseek-v4-pro-0813 声明 efforts: ['low','high','max'] 却没有 enableThinking,这也是沙箱测得四个新增 DeepSeek 兄弟条目干净、只有该条目双旋钮的原因;provider 侧的冲突消解限定在 Qwen 家族而非解析后的能力——dashscope.ts:63 的默认参数为 tieredModel = isTieredEffortWireModel(model),其相邻注释直接写明了范围:"qwen3.8-max 直接接受统一档位,较旧的 qwen 混合模型仍只暴露 enable_thinking 开关"(:388-392),配置由按模型名判断的 buildQwenEffortConfig(request.model) 构造(:392),因此一个带声明档位梯的非 Qwen 模型落在这套"择一旋钮"的消解之外。后果可测且已被测到:在本 head 上以相同 installed-model JSON 驱动真实编译产物(provider 与 pipeline)对接环回 HTTP 服务的 A/B 显示,alibabaStandard / deepseek-v4-pro 在 high 与 max 两档同时上送 reasoning_effort 与 enable_thinking=true——在本 PR 新启用的 42 个格子中占 2 个——而同一模型 ID 在 Token Plan 路由上只送单个旋钮。于是同一个模型 ID 在两条阿里云路由上互相矛盾,而 PR 自身的核心主张("由同一个解析后的能力来决定该选择")在这条路由上不成立。之所以判为阻塞而非表面问题:用户在本 PR 新建的菜单里选择 high 或 max,请求却同时携带一个布尔开关,究竟哪一个被采纳由 provider 决定;该缺陷出现在本次新启用的配置中而非继承而来,且正是 PR 描述里点名的那种失效形态。最小修复形态二选一:从该条目移除 enableThinking: true,让能力声明成为旋钮的唯一来源(兄弟条目已如此);或把冲突消解改为按解析后的能力判断而非按 Qwen 模型名,使任何路由上声明的档位梯都能抑制该布尔量。无论选哪种,都应为 alibabaStandard / deepseek-v4-pro 在 high 与 max 的请求体形状补上测试——沙箱报告其 2 条失败断言正好是这两个格子,因此现成的见证可以直接照搬。一处相关分歧,建议同一轮一并裁定。 沙箱还测到 4 个格子上,base 会上送的档位在 head 被静默丢弃(token-plan/qwen3.8-max 与 -preview 的 high、max),而无参数的 /effort 仍把已持久化的 high 报为当前档位、请求体上却什么都没有。设计文档记录了档位收窄规则,因此"丢弃"本身可能是有意的;需要决定的是用户可见的报告与请求体相互矛盾这一点。我未能在预算内把它追到自己的代码路径,因此记为"已测到但未独立验证",而不是第二个 Critical。非阻塞项,记录以免他人重复推导。 pipeline.ts:1002 是 isTieredEffortWireModel 四个调用点中唯一没有跟着改签名的,仍按 qwen3.8-max 前缀判断;沙箱测得目前不产生任何可观测差异。其余记录。 维护者在本 head 上的独立验证很有分量:在伪装成真实 provider 端点、配合真实 daemon 与真实 TUI 的环境下,Reviewer Test Plan 的每条主张均复现,覆盖 25 条路由,并带有只回退三个生产文件的负对照——两个原始缺陷随即在请求体上复现(qwen3.8-flash 在 /effort low 下同时上送两个旋钮;第二次 refreshAuth 抹掉已保存的"关闭思考"偏好)。这正是本 PR 主张的两项修复,它们成立。差异在于覆盖面而非方法:他的矩阵把阿里云 stable 模型的 high/max 记为通过,而沙箱抓到的双旋钮格子是某一个具体条目,即 alibaba-standard 的 deepseek-v4-pro,因此两份验证并不冲突——他测到的格子是干净的,他没测到的那个不是。triage 第 3 阶段也记录了一次干净评审,且此前限制其信心的疑虑已被排除。CI:本 head 上 23 项通过、53 项跳过,唯一失败是 review-pr,其运行在 21600 秒预算处超时——按本评审口径该通道状态不构成门禁,其余无失败。作者此前提到的那个未改动的 web-shell history-viewport 冒烟用例红灯,在本 head 已不在报告的检查之中。下一步:让 alibaba-standard 的 deepseek-v4-pro 条目只把一个旋钮送上请求体,并为该请求体形状补上测试;同时裁定 /effort 是否应继续报告一个请求体已不再携带的档位。除此之外,按我的阅读 diff 中没有其他阻塞项。
|
Addressed the blocking request-shape finding and the related
The automated review Suggestions were individually answered and explicitly tracked in #11328 (comment). They are not claimed fixed: they cover capability-only custom settings, mutation-sensitive coverage, inherited toggle-only effort, hosted Kimi tool forcing, the legacy nested DeepSeek adapter, and setup/descriptor projections. The proposed arbitrary id-only cross-endpoint fallback was rejected to preserve route ownership. This round changes only five files for the two findings above. Please re-check the current head; the earlier approval and reported green CI apply to the previous head, and the new head will run its own checks. 中文说明已在 修复前新增请求断言和状态断言各失败两项;修复后 Core 212、CLI 16 项通过,完整 build/typecheck/bundle/lint 通过,13 个真实 CLI 到 localhost 的配置驱动用例全部通过。自动评审的独立建议已逐条回复并记录到关联 issue,不声称已修复;拒绝任取其他 endpoint 的同名模型能力。请复核最新 head,之前批准和绿色 CI 属于前一个提交,新 head 会运行自己的检查。 |
|
The first CI run for the maintainer fix failed before ESLint: the updated main workflow invoked The refreshed repository instructions also require complete bilingual design documents, so After merging main: full build, typecheck, bundle, lint and repository-wide Prettier check pass; focused core tests pass 1,010 cases and CLI/ACP tests pass 82. All thirteen CLI mock cases passed again after the merge, including both high/max requests for the corrected Standard DeepSeek Pro entry. The current scope retains the two maintainer fixes; independent Suggestions remain explicitly tracked in #11328. The previous static failure is a missing base-branch gate file, not a product lint error. New CI will validate the merged head. 中文说明本轮首次 CI 在执行 ESLint 前失败:main 的新 workflow 调用了旧 PR 分支尚未包含的 check-lint-gate-freshness.mjs,报 MODULE_NOT_FOUND。已通过正常 merge 提交 a3d7164 同步 main,新脚本及其九项通过测试均由 main 祖先引入,没有绕过或放宽门禁。 最新仓库规范要求完整双语设计,10d396510a 补上中文对应版本,原路径保留为英文;两份都说明最终 DeepSeek 单字段请求与旧档位报告行为。合并后完整 build/typecheck/bundle/lint 及全仓 Prettier 检查通过,Core 1,010 项、CLI/ACP 82 项通过;合并后13项CLI mock再次全部通过,包括修复后的百炼DeepSeek Pro high/max。本轮保持两项maintainer修复,独立建议继续由 #11328 跟踪,新CI将验证合并后的head。 |

 yiliang114
left a comment
yiliang114
left a comment
There was a problem hiding this comment.
Confirming qqqys's blocking finding is now fixed at this head: alibaba-standard.ts deepseek-v4-pro no longer carries enableThinking: true alongside the new capabilities.reasoning ladder — the entry is now capability-only, matching its -0813/-flash siblings, so high/max send reasoning_effort alone instead of two competing knobs.
One item from qqqys's note is still open and worth ruling on before merge: token-plan/qwen3.8-max and -preview drop high/max on the wire (the tier-narrowing the design doc records), yet a bare /effort still reports the persisted high as the current tier. If the narrowing is intended, the user-visible report should stop claiming a tier the request no longer carries — otherwise it's a silent contradiction. If it's not intended, the narrowing itself needs revisiting.
The remaining bot findings are Suggestion-level (14/38 capabilities.reasoning blocks unreached by the preset-reading test table, thinkingMandatory on non-Qwen DashScope routes, and the pipeline.ts:1002 call-site that still keys on the qwen3.8-max prefix). Non-blocking, but the test-table gap is the one I'd close in the same pass since it's what let the double-knob cell slip through the first time.
|
The remaining The regression at The additional preset coverage suggestion is recorded in #11328; the exact stable-Pro high/max cells that exposed the blocking issue were added to the real-provider pipeline matrix in this PR. Please re-check the current reporting condition before treating the old report as an open blocker. 中文说明
effort-command.test.ts:106 使用真实 Token Plan Qwen 3.8 Max capability,验证旧 high/max 显示默认值、合法 low 保留当前档位,以及查询不写设置或运行时状态。high/max 两项在修复前红、修复后绿,合并后的 CLI/ACP 82 项测试包含这些用例。档位收窄仍是有意的,报告已经与不发送无效档位的行为一致。 额外预设覆盖已记录到 #11328;暴露阻塞的稳定版Pro high/max两格已在本PR补进真实provider测试矩阵。请按当前报告条件复核,不要把已修复的旧报告继续视为阻塞。 |
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed. Suggestions are inline.
12 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- R1-1 refreshAuth mandatory-exemption scope — already reported (comment 3962682126), author answered and deferred to issue 11328
- R1-2 capability lookup keyed on the live baseUrl — already reported (comment 3962682134), author declined as intentional route ownership
- R1-3 repeated-auth test does not reproduce the wipe — already reported (comment 3962682137), author answered and deferred to issue 11328
- R1-4 isTieredEffortWireModel branch unpinned — already reported (comment 3962682145), author answered and deferred to issue 11328
- R1-5 dashscope ladder comment wording — already reported (comment 3962682152), author answered and deferred to issue 11328
- R1-6 toggleOnly non-qwen nested reasoning — already reported (comment 3962682158), author answered and deferred to issue 11328
- R1-7 preset capability rows unreached by tests — already reported (comment 3962682160), author answered and deferred to issue 11328
- R1-8 Alibaba thinkingMandatory flags unasserted — already reported (comment 3962682164), author answered and deferred to issue 11328
- R1-9 thinkingMandatory on a non-Qwen model arms the tool_choice drop — already reported (comment 3962682171), author declined pending a hosted-Kimi witness
- R1-10 hosted-DeepSeek disableField versus the pipeline comment — already reported (comment 3962682178), author answered; this round's fetched Alibaba reference settled it in the presets' favour, leaving the stale comment
- R1-11 native DeepSeek low tier versus the legacy nested adapter — already reported (comment 3962682188), author answered and deferred to issue 11328
- R1-12 catalog consumers read only the legacy enableThinking — already reported (comment 3962682194), author answered and deferred to issue 11328
Not reviewed: reverse audit — stopped at the plan's 5-round cap without two consecutive dry rounds; rounds 3, 4 and 5 each reported findings, so the loop ended on the cap rather than on convergence.
Not reviewed: build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally; integration-tests/* and root scripts/tests/* are outside build-test's scoped suite set.
Not reviewed: build-and-test — the test-efficacy probe could not be validated (harnessValidated: null: the control produced no verdict because the vitest prerequisite guard failed in the probe's restored tree), so no revert, mutant or hunk-survival claim was measured in either direction.
Deferred under the convergence posture (round 2, not a blocker) — recorded, not requested in this round:
packages/cli/src/acp-integration/model-configuration.test.ts:84 — [review] installed-preset matrix can be satisfied by the hardcoded MODEL_CONFIGURATIONS manifest instead of the preset output
Mechanism health: this round did not close cleanly, so it withholds the incremental anchor — and the round it recovered had no anchor this round could use either — none at all, one with no certifier, one certified by an identity other than the one this round runs under, or one this round's fetch refused or resolved to the head — so the next review re-reads the whole diff unless recovery grafts an earlier own anchor that the round running it can use onto the complete work list this round leaves behind, and keeps doing so until a round's marker carries an anchor again or a graft lands that the round running it can use. (Stated, not acted on — this changes nothing about what the round posts.)
中文说明
仅完成部分审查,审查缺口已披露。 建议见行内评论。
本轮确认的 12 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未审查(原文为英文):reverse audit — stopped at the plan's 5-round cap without two consecutive dry rounds; rounds 3, 4 and 5 each reported findings, so the loop ended on the cap rather than on convergence.
未审查(原文为英文):build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally; integration-tests/* and root scripts/tests/* are outside build-test's scoped suite set.
未审查(原文为英文):build-and-test — the test-efficacy probe could not be validated (harnessValidated: null: the control produced no verdict because the vitest prerequisite guard failed in the probe's restored tree), so no revert, mutant or hunk-survival claim was measured in either direction.
收敛姿态下延后(第 2 轮,非阻断)——已记录,本轮不要求修改:共 1 条(原文未翻译,列表见上方英文部分)。
机制健康:本轮未能干净收尾,因而扣留了增量锚点,而它恢复到的那一轮也没有留下本轮可用的锚点——要么完全没有、要么没有认证者、要么由本轮运行身份之外的身份认证、要么被本轮的获取拒绝或解析为头提交——因此下一次评审将重读整个 diff,除非恢复流程把本轮能使用的更早自有锚点嫁接到本轮留下的完整工作清单上;并会一直如此,直到某一轮的标记重新带上锚点,或落地的嫁接能被运行该轮的评审使用。(仅陈述,不据此行动——这不改变本轮发布的任何内容。)
— qwen3.8-max via Qwen Code /review (v0.23.1)
…n-deepseek-reasoning

# Conflicts:
#	packages/cli/src/acp-integration/model-configuration.test.ts
|
Merged current main ( Validation: core provider/pipeline/preset tests 420 passed; config tests 645 passed; CLI/ACP tests 125 passed. Full build, typecheck, bundle and lint passed. Formatting and staged-diff checks passed. No forced push. Local HEAD, remote branch and PR head all match Local sharp is 0.35.3 whereas merged main pins 0.35.4; the focused reasoning tests do not claim sharp-specific acceptance. CI installs the merged lockfile. 中文:已正常合并当前 main(5f65099c87),提交36d8bd8b0f。唯一冲突在ACP模型配置测试,保留双方的Kimi/Qwen/DeepSeek矩阵与GPT-5/GPT-6/default-reasoning测试及import。Core请求/provider/预设420、Config645、CLI/ACP125项通过,完整build/typecheck/bundle/lint通过。未强推,三处SHA一致,GitHub已恢复MERGEABLE;新CI和审核要求仍待完成。本地sharp为0.35.3而main锁定0.35.4,未声称做过sharp专项验收;CI将按合并后的锁文件安装。 |
ytahdn
left a comment
ytahdn
left a comment
There was a problem hiding this comment.
增量复审 / Incremental re-review
基线 → head:76ba8799 → 36d8bd8b。本 PR 自身的增量为三个提交:78607f70(澄清 Qwen 兼容别名的注释/设计文档)、1eb8b069(移除 DeepSeek 冗余 thinking 默认值 + effort 命令显示守卫 + 配套测试)、10d39651(文档双语对齐);其余两个 Merge origin/main 不计。每条引用都在 head 36d8bd8b 的树上重新核对过。
Baseline → head: 76ba8799 → 36d8bd8b. The PR's own increment is three commits: 78607f70 (comment/design-doc clarification of Qwen compatibility aliases), 1eb8b069 (remove the redundant DeepSeek thinking default + an effort-command display guard + tests), 10d39651 (bilingual doc alignment); the two Merge origin/main commits are excluded. Every citation is re-verified against the head 36d8bd8b tree.
本 PR 主要做了什么 / What this PR does
把 PR 10999 落地的声明式 capabilities.reasoning 框架(当时只配了原生 DeepSeek V4 Pro)补齐到 Kimi / Qwen / DeepSeek 各路由:五个预设文件按各 provider 路由的真实 wire 契约声明每个模型的档位 / 开关 / 默认值 / 关闭字段,把 DashScope provider 里硬编码的 qwen3.8-max 前缀判断换成"优先读已声明 capability、未配置才回退名称"的查找,并顺带修 refreshAuth 让全局关闭思考的偏好在连续认证时不被抹掉。
Fills out the declarative capabilities.reasoning framework PR 10999 landed (then only native DeepSeek V4 Pro) across the Kimi / Qwen / DeepSeek routes: five preset files declare per-model tiers / toggle / default / disable-field to match each provider route's real wire contract, replacing the hardcoded qwen3.8-max prefix gate in the DashScope provider with a capability-first lookup, plus a refreshAuth fix so a saved global thinking-off preference survives repeated auth.
结论 / Verdict:APPROVE(无遗留 Critical / Important)。上一轮我提的 Important 已解决;qqqys 本轮提的 Critical 已修;yiliang114 提的显示项也已修。CI 在 head 上全绿(仅 bot 的 review-pr 还 pending)。剩下的都是非阻塞项与"第三方端点契约静态审查无法证实"的固有说明。
APPROVE (no standing Critical / Important). My prior-round Important is resolved; qqqys's Critical this round is fixed; yiliang114's display item is fixed too. CI is fully green at head (only the bot's review-pr is pending). What remains is non-blocking, plus the inherent caveat that static review cannot prove third-party endpoint contracts.
✅ 上一轮我的 findings / My prior findings
-
Important(两张档位表在
high上矛盾 + 超档位 effort 静默丢弃)已解决。78607f70把dashscope.ts:35-38上DASHSCOPE_TIERED_EFFORTS的注释从"超过 xhigh 的max会被 400 拒绝"改写为"这是未声明 capability 路由的旧输入档位表;DashScope 把 high/max 当作 xhigh 别名接受;已配置预设只暴露原生 low/medium/xhigh"。设计文档新增《原生档位与兼容输入》一节,明确"不在声明中的持久化值被省略、采用 provider 默认值(Qwen3.8 为 xhigh)……这是有意的配置优先规则,不代表 provider 会拒绝 high 或 max"。据此我上一轮担心的两点都消解了:(a) 两表并非互相矛盾——一张是输入侧兼容表、一张是原生 wire 档位,用户自建qwen3.8-max(无 capability)走 clamp 发出high不会 400,因为 high 本就是 xhigh 别名;(b) 预设模型上"静默丢弃 high/max"是无损的——被丢的值恰好别名到 xhigh,而 xhigh 正是声明的defaultEffort,落到 provider 默认即等价结果。数组内容与buildQwenEffortConfig行为未变,仅注释/文档澄清(这正是我上一轮给的关闭方式)。Resolved.
78607f70rewrites theDASHSCOPE_TIERED_EFFORTScomment (dashscope.ts:35-38) from "amaxabove xhigh is rejected with a 400" to "legacy input ladder for routes without an explicit capability; DashScope accepts high/max as xhigh aliases; configured presets expose only native low/medium/xhigh", and the design doc adds a section stating undeclared persisted values are omitted → provider default (xhigh for Qwen3.8), "an intentional config-first rule, not a claim the provider rejects high/max". Both halves of my concern dissolve: (a) the two ladders aren't contradictory — one is the input-compat ladder, one the native wire ladder, so a user's own unconfiguredqwen3.8-maxshippinghighvia clamp is not a 400 (high is an xhigh alias); (b) the silent-drop of high/max on preset models is lossless — the dropped values alias to xhigh, which is exactly the declareddefaultEffort. Array contents andbuildQwenEffortConfigbehavior are unchanged; only comments/docs (the remedy I offered last round). -
Nit(
pipeline.ts第三个调用点仍是单参名称回退)未变、非阻塞。 head 上该调用点在pipeline.ts:1012isTieredEffortWireModel(model)(单参),对本 PR 所有预设仍被 capability 分支遮蔽,只有用户自建 qwen 家族 +disableField:'thinking'的形状可达。留作后续或加注释即可。/ Unchanged, non-blocking (nowpipeline.ts:1012). -
Nit(tiered 模型每次 buildRequest 解析两次 model config)未变、无正确性影响。
✅ 本轮他人 findings(我已独立复核)/ Other reviewers' findings (independently re-verified)
-
qqqys 的 Critical(阿里云路由同一请求发两个互斥 thinking 旋钮)已修 —— 且坦白说这条在我上一轮基线
76ba879就存在、我漏了,是 qqqys 抓到的。1eb8b069把alibaba-standard.ts的deepseek-v4-pro改成只带 capability:headalibaba-standard.ts:84-95已无同级enableThinking: true,与其-0813/-flash兄弟一致。测试也补了钉子:pipeline.test.ts:2080-2081新增['alibabaStandard','deepseek-v4-pro','high'/'max','enable_thinking',false],断言逻辑(:2188-2189专门 case +:2208尾判)确保 enabled 模式下enable_thinking为 undefined、只发reasoning_effort。已核对修复到位。Fixed — and honestly, this defect was present at my baseline
76ba879and I missed it; qqqys caught it.1eb8b069makesalibaba-standard.tsdeepseek-v4-procapability-only (head:84-95no longer carries a siblingenableThinking: true), matching its-0813/-flashsiblings, andpipeline.test.ts:2080-2081now pins that enabled-modehigh/maxshipreasoning_effortalone withenable_thinkingundefined. -
yiliang114 的未决显示项(token-plan
qwen3.8-max/-preview把持久化的high当当前档位上报,但 wire 上已不发)已解决。1eb8b069给effort-command.ts:81加了守卫current && availableTiers.includes(current):只有当持久化值在该模型的可用档位内才报"Current reasoning effort: X",否则报"not set (using the model/provider default)"。我顺着核实了availableTiers的来源getReasoningEffortsForConfig(model-configuration.ts:322-328):命中已声明 capability 时返回reasoning.efforts——token-planqwen3.8-max声明的是['low','medium','xhigh'](alibaba-token-plan.ts:65),不含high,故守卫对持久化high/max会正确回落到"provider 默认"。effort-command.test.ts新增的it.each(['high','max','low'])用例正钉住这一行为(CI 绿)。yiliang114 的 review 时间戳晚于1eb8b069,我判断该守卫已覆盖其关切。Resolved.
1eb8b069adds theeffort-command.ts:81guardcurrent && availableTiers.includes(current), and I tracedavailableTierstogetReasoningEffortsForConfig(model-configuration.ts:322-328), which returns the declaredreasoning.efforts—['low','medium','xhigh']for token-planqwen3.8-max(alibaba-token-plan.ts:65), excludinghigh, so a persistedhigh/maxcorrectly falls back to "provider default". The neweffort-command.test.tsit.each(['high','max','low'])case pins it (CI green).
🔎 我核对后不作为问题上报的一处 / One thing I checked and am NOT flagging
token-plan 的 qwen3.8-max(alibaba-token-plan.ts:60-75)与 -preview(:76-91)同时带 enableThinking: true + thinkingMandatory: true 和 capabilities.reasoning(disableField: 'reasoning_effort'),而 provider-config.ts:69 会为任何 enableThinking 规格无条件注入 extra_body.enable_thinking: true。乍看与 qqqys 的"双旋钮"同形,但我核实后判断这是有意且被测的配置,不是缺陷:这两个模型是 thinkingMandatory(pipeline.ts:974-979 的注释点名 token-plan 网关上的 qwen3.8-max-preview 会以 400 拒绝 enable_thinking: false),其关闭字段是 reasoning_effort 而非 enable_thinking,所以 enable_thinking: true 是"始终开思考"的信号、reasoning_effort 设档位,二者不互斥。pipeline.test.ts:2106-2107 以 mandatory=true 覆盖了这两条路由,断言(:2201-2204)明确允许 enable_thinking 非 false,CI 绿。对照 alibaba-standard 的 qwen3.8-max(capability-only、enable_thinking 断言为 undefined)是不同网关契约,非不一致缺陷。
token-plan qwen3.8-max/-preview carry enableThinking: true + thinkingMandatory: true alongside a reasoning_effort-keyed capability, and provider-config.ts:69 unconditionally injects extra_body.enable_thinking: true — superficially the same shape as qqqys's double-knob. But these are thinkingMandatory models (the pipeline.ts:974-979 comment names token-plan qwen3.8-max-preview as rejecting enable_thinking: false with a 400) whose disable field is reasoning_effort, not enable_thinking, so enable_thinking: true is the always-on signal and reasoning_effort the tier — not competing. pipeline.test.ts:2106-2107 covers both with mandatory=true and the assertion (:2201-2204) explicitly permits enable_thinking non-false; CI green. Not a defect.
🟢 非阻塞 / Non-blocking
- yiliang114 提到的测试表覆盖缺口(部分
capabilities.reasoning块未被 preset-reading 测试矩阵触达)值得在同一批里补齐——正是这个缺口让 qqqys 的双旋钮单元第一次溜过。qqqys 命中的那格现已由1eb8b069补测,剩余覆盖是普遍性改进项。/ The test-table coverage gap yiliang114 noted is worth closing in the same pass — it's what let the double-knob cell slip through initially; the specific cell is now covered, the rest is a general improvement. - 本 PR 的实质仍是一组"第三方端点接受什么"的断言,静态审查无法对线上端点证实。设计文档为矩阵每行引用了官方文档并标注核对日期,
78607f70又补齐了 high/max 别名的依据,23+ 路由矩阵证明代码自洽(我们发什么)——这是这类改动能拿到的最好证据,但"发得对"不等于"对端一定接受"。此为固有说明,非阻塞。/ The substance remains a set of third-party-endpoint contract claims static review can't confirm against live APIs; the design doc cites official docs per matrix row with verification dates,78607f70adds the high/max alias basis, and the route matrix proves self-consistency (what we send). Inherent caveat, non-blocking.
Reviewer note: 纯静态审查 —— 未跑测试/构建。CI 读自 head 36d8bd8b 的 Actions(除 bot review-pr pending 外全绿)。所有行号在 head 36d8bd8b 树上核对:alibaba-standard.ts / alibaba-token-plan.ts / dashscope.ts / pipeline.ts / pipeline.test.ts / effort-command.ts / model-configuration.ts / provider-config.ts。
Static review only — no tests/build run. CI read from Actions on head 36d8bd8b (all green except the bot's review-pr, pending). All line numbers verified against the head 36d8bd8b tree.

tmux-based E2E verification at head
|
qqqys
left a comment
qqqys
left a comment
There was a problem hiding this comment.
Approving at head 36d8bd8b0f16, read immediately before submitting.
The Critical I filed on this PR — alibaba-standard's deepseek-v4-pro shipping both reasoning_effort and enable_thinking=true on one request, on the exact route this PR exists to unify — is fixed at this head and pinned. Re-adding the single removed line turns 3 tests red, including sends installed alibabaStandard / deepseek-v4-pro reasoning through the real provider hook twice: the high and max cells the finding named. Suites executed at head: pipeline.test.ts 236/236, presets/alibaba-standard.test.ts 10/10, ui/commands/effort-command.test.ts 16/16. No Critical found on the increment.
Full evidence and method are in the verification comment above (#issuecomment-5600643075), including the one branch my tmux harness could not reach and a negative control that came out vacuous — I have not relied on either, and the guard's out-of-ladder branch is covered instead by this PR's own test, which I ran.
Two things this approval does not claim: it does not reduce ytahdn's inherent caveat that static review plus local pins cannot prove what a live third-party endpoint accepts, and it rests on the gate read taken at the instant before posting rather than on lanes or verdicts that may change afterwards.
在 head 36d8bd8b0f16 上批准(提交前一刻重新读取)。我此前提出的 Critical(alibaba-standard 的 deepseek-v4-pro 在同一请求里同时上送 reasoning_effort 与 enable_thinking=true)已在该 head 修复且被测试钉住:把被删的那一行加回,恰好 3 个测试转红,其中包含 Critical 点名的 high、max 两格。head 上实跑 236/236、10/10、16/16,增量部分未发现 Critical。完整证据与方法见上方验证留言(#issuecomment-5600643075),其中也写明了我的 tmux harness 未能触达的分支以及一个无效的负对照 —— 二者我都未采信,越档分支改由本 PR 自带测试覆盖并已实跑。本批准不主张两件事:既不削弱 ytahdn 记录的固有说明(静态审查加本地钉子无法证明线上第三方端点实际接受什么),也只以发布前一刻的门禁读数为准,而非其后可能变化的通道状态或评审结论。

|
Released in v0.23.3. |
6 participants


What this PR does
Extends provider-configured reasoning to mainstream Kimi models and fills out Qwen and DeepSeek presets. Moonshot K3 offers low/high/max, K2.7 Code stays thinking-only, and K2.6 exposes its native thinking toggle. Qwen 3.8 offers low/medium/xhigh; native DeepSeek V4 Pro and Flash offer low/high/max, while Alibaba stable models and dated snapshots keep their distinct supported tiers and disable fields.
Adds Qwen 3.8, DeepSeek V4 snapshots and Kimi to Standard API setup, plus Qwen 3.8 Flash and DeepSeek V4 Pro-0813 to Token Plan. Existing Coding Plan hybrid models gain explicit capabilities without changing the available model list. DashScope now recognizes a declared Qwen tiered protocol when resolving conflicting thinking parameters, allowing Flash and future configured models to work without another model-name branch.
Why it's needed
The capability foundation in #10999 configured only native DeepSeek V4 Pro. The remaining presets could expose generic tiers or install the wrong native Kimi thinking field. Adding Flash also revealed a legacy Max-only protocol check that appended a boolean thinking switch alongside the selected effort. The same resolved capability now controls that decision and the CLI's static-override notice. Authentication refresh also preserves a saved thinking-off preference that provider defaults previously erased, while mandatory-thinking models remain protected.
Reviewer Test Plan
How to verify
Configure Moonshot and select K3, K2.7 Code and K2.6 in turn. Confirm K3 offers low/high/max with max as default and no Off; K2.7 does not offer Off or fabricated effort tiers; K2.6 offers On/Off. A K2.6 Off request must contain thinking.type=disabled and no enable_thinking field.
Select Qwen 3.8 Flash through Standard setup. Confirm low/medium/xhigh with xhigh as default; selecting an effort sends one reasoning_effort field, and Off sends reasoning_effort=none. An explicit thinking budget must suppress the competing effort. Existing Token Plan Max/Preview thinking-mandatory restrictions remain in effect.
Compare native DeepSeek V4 Flash with Alibaba stable V4 and its dated snapshots: native and snapshots offer low/high/max, Alibaba stable offers high/max, and all default to high. Off uses thinking.type for native DeepSeek and enable_thinking for Alibaba. Unknown IDs retain their existing fallback behavior.
Evidence (Before & After)
Before: installing the new Flash capability still produced enable_thinking=true alongside reasoning_effort; the two real-provider pipeline cases failed while the other 21 routes passed. After: the configured protocol determines parameter precedence, and all 23 route cases pass for normal requests, explicit Off and non-thinking side queries. Automated ACP tests check installed presets' exact options and defaults.
Validation results and isolated CLI mock evidence are posted in the separate test report comment.
Tested on
Environment (optional)
Node.js 22; provider and pipeline unit tests, ACP option tests, isolated CLI requests against a local mock OpenAI API, build, typecheck, bundle and lint.
Risk & Scope
Linked Issues
Follows #10999. Related follow-up tracking: #11328.
中文说明
本 PR 做了什么
将声明式推理配置扩展到主流 Kimi 模型,并补齐 Qwen 与 DeepSeek 预设。Moonshot K3 提供 low/high/max;K2.7 Code 保持强制思考;K2.6 提供原生开关。Qwen 3.8 提供 low/medium/xhigh;原生 DeepSeek V4 Pro 与 Flash 提供 low/high/max,阿里云稳定版与日期快照分别保留其档位和关闭字段。
Standard API 配置新增 Qwen 3.8、DeepSeek V4 快照和 Kimi;Token Plan 新增 Qwen 3.8 Flash 和 DeepSeek V4 Pro-0813。Coding Plan 只为已有混合思考模型补充显式能力,不改变模型列表。DashScope 在处理思考参数冲突时读取已声明的 Qwen 档位协议,使 Flash 和后续配置的模型无需新增型号判断。
为什么需要
#10999 的能力框架只配置了原生 DeepSeek V4 Pro。其他预设仍可能展示通用档位,或为原生 Kimi 安装错误的思考字段。新增 Flash 暴露了旧 Max-only 协议判断,导致档位和布尔开关同时发送。现在该判断及 CLI 高优先级静态参数提示都使用同一份已解析能力。认证刷新还会保留此前被 provider 默认值覆盖的全局关闭偏好,强制思考模型继续受到保护。
Reviewer 测试计划
如何验证
配置 Moonshot,依次选择 K3、K2.7 Code 与 K2.6。K3 应仅提供 low/high/max,默认 max,没有 Off;K2.7 不提供 Off 或虚构档位;K2.6 提供 On/Off。K2.6 关闭请求应包含 thinking.type=disabled,不包含 enable_thinking。
通过 Standard 选择 Qwen 3.8 Flash,确认 low/medium/xhigh、默认 xhigh;选择档位时只发送 reasoning_effort,关闭时发送 reasoning_effort=none。显式 thinking budget 应抑制冲突的 effort。Token Plan Max/Preview 的既有强制思考限制保持有效。
比较原生 DeepSeek V4 Flash、阿里云稳定版 V4 及日期快照:原生与快照提供 low/high/max,阿里云稳定版提供 high/max,默认均为 high。原生关闭字段为 thinking.type,阿里云为 enable_thinking。未知模型 ID 保持已有回退行为。
Before / After 证据
Before:安装新的 Flash capability 后,仍同时产生 enable_thinking=true 与 reasoning_effort;两个真实 provider pipeline 用例失败,其余 21 个路由通过。After:声明的协议决定参数优先级,23 个路由在普通请求、显式关闭及非思考副请求下均通过。ACP 自动化测试验证真实安装配置的精确选项和默认值。
验证结果和隔离 CLI mock 证据作为独立测试报告评论发布。
测试平台与环境
macOS 已测试;Windows 和 Linux 未本地测试。Node.js 22;provider/pipeline 单元测试、ACP 选项测试、隔离 CLI 本地 mock API、build、typecheck、bundle 和 lint。
风险与范围
关联
接续 #10999;相关后续跟踪为 #11328。