perf(web-shell): derive the session workflow projection once and share it across surfaces (#10865) - #11237
perf(web-shell): derive the session workflow projection once and share it across surfaces (#10865)#11237now-ing wants to merge 3 commits into
Conversation


…er (QwenLM#10865)

The cockpit, the workflow inspector and the graph embedded in the cockpit
each derived their own copy of the session workflow projection for a single
render. The app now builds one projection per render and hands the same
object to every surface; each surface keeps a raw-props fallback so
standalone mounts (ToolApproval, TasksStatusMessage, isolated tests) still
work unchanged.

To make the sharing possible without a circular import, the task-execution
lookups PlanExecutionView owned (the index, its walkers, the node-state and
active-agent derivations) move to a shared taskExecutionIndex module that
both the projection and the graph depend on. The projection now carries
its task index and the unassigned-tools bucket, so the embedded graph reads
grouping, node states, counts and dependents from the shared object
instead of recomputing them, and its dependents map comes from the
projection's own derivation rather than a third copy of the blockedBy walk.

Pinned by tests: a mount of cockpit + inspector + embedded graph with the
shared projection derives nothing extra (spy on buildSessionWorkflowProjection
and createTaskExecutionIndex); a standalone cockpit tree or inspector
derives exactly one projection and one index; hovering a node re-renders
without re-running layerPlanTodos or the topology serialization; a
same-frame resize storm coalesces to one measure per animation frame.

Fixes QwenLM#10865


 qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Thanks for the PR, @now-ing — the direction here matches exactly what #10865 still has open, but the description doesn't follow this repo's PR template, so I have to stop at the gate and ask for a restructure before anyone spends time on the code.
You have the four main sections right (What this PR does, Why it's needed, Reviewer Test Plan → How to verify) and the Chinese translation is there in full, which is appreciated. What's missing is the rest of the template: Evidence (Before & After), the Tested on OS table, Risk & Scope, and Linked Issues. (Environment is marked optional.) Most of the material already exists under other headings — Fixes #10865 at the top is the Linked Issues content, and your "Not covered / out of scope" section is most of Risk & Scope — so this is largely a move, not a rewrite. Please rework it against .github/pull_request_template.md.
Two things worth settling while you're in there, because both are substantive rather than cosmetic:
- The Evidence section is where a
perfPR has to carry numbers, and right now there are none. Your test plan is genuinely good at pinning the structural claim — the spy counts prove the projection went from three derivations to one, and that hovering no longer re-sorts. But it doesn't say what that is worth. One measurement on a real session (derivation counts or ms before/after, on a plan with dependencies and agent steps) would turn "one projection per render" from a code-shape fact into a demonstrated win. If you judge that unmeasurable, say so explicitly under Evidence rather than leaving the section out — that's a decision a maintainer can accept, whereas a missing section is just a gap. - The new app-level memo runs whether or not a workflow surface is open. It's gated on
sessionWorkflowEnabledonly. When the cockpit is closed and there's no workflow tab,planAgentToolsalready short-circuits to[], butsessionWorkflowTodosandenvironmentAgentTasks(which tracksmessages) do not — so a chat-only session with the flag enabled now pays onebuildSessionWorkflowProjectionplus onecreateTaskExecutionIndexper message update, where before it paid nothing. Gating the memo on the same conditionplanAgentToolsuses would remove that. Worth a deliberate decision either way, since it's the one spot where this PR could add work instead of removing it.
For the record, nothing in this pass is a judgment on the code itself: sharedProjection ?? buildSessionWorkflowProjection(...) keeps standalone mounts and isolated tests on the old path, and folding the graph's grouping, node states and dependents map into the projection is what the issue's remaining acceptance criterion asks for. Also note CI on this commit is still in flight — Test (ubuntu-latest, Node 22.x), Lint & Static and Capture web-shell visuals were running when I looked, and the macOS/Windows test jobs are skipped for this PR — so the suite results quoted in the description are self-reported for now. Fill in Tested on with what you actually ran locally.
Once the body is restructured, re-trigger with @qwen-code /triage and it'll go through the full review.
中文说明
感谢贡献,@now-ing —— 方向正好对应 #10865 仍未完成的验收项,但 PR 描述没有遵循本仓库的模板,所以这里必须先停下来,请在进入代码审查前先重新组织描述。
四个主要小节是对的(What this PR does、Why it's needed、Reviewer Test Plan → How to verify),中文翻译也完整,这点很好。缺的是模板的其余部分:Evidence (Before & After)、Tested on 操作系统表格、Risk & Scope 和 Linked Issues(Environment 标注为可选)。大部分内容其实已经在别的小节里了——开头的 Fixes #10865 就是 Linked Issues,你的"Not covered / out of scope"基本就是 Risk & Scope——所以主要是搬移,而非重写。请参照 .github/pull_request_template.md 调整。
重写时有两点值得顺手确定,因为它们不只是格式问题:
- Evidence 小节正是
perfPR 该放数据的地方,而目前一个数字都没有。 你的测试计划在钉住结构性结论上做得很好——spy 计数证明了投影从三次派生变为一次、hover 不再重跑拓扑排序。但它没有说明这值多少。在真实会话上做一次测量(带依赖与 agent 步骤的计划,前后对比派生次数或毫秒数),就能把"每次渲染一份投影"从代码形态事实变成已验证的收益。如果你判断它无法测量,请在 Evidence 里明确说明,而不是直接省略该小节——前者是维护者可以接受的决定,后者只是一个缺口。 - 新增的 App 层 memo 在 workflow 界面未打开时也会执行。 它只受
sessionWorkflowEnabled约束。当 cockpit 关闭且没有 workflow 标签页时,planAgentTools已经短路返回[],但sessionWorkflowTodos和environmentAgentTasks(跟随messages变化)并不会——所以开启该开关的纯聊天会话,现在每次消息更新都要付一次buildSessionWorkflowProjection加一次createTaskExecutionIndex,而此前是零成本。让这个 memo 使用与planAgentTools相同的条件即可消除。无论选哪种都值得明确决定,因为这是本 PR 唯一可能增加而非减少计算量的地方。
需要说明:本次审查并非对代码本身的评价——sharedProjection ?? buildSessionWorkflowProjection(...) 保留了独立挂载与隔离测试的原有路径,把图的分组、节点状态与 dependents 映射收进投影也正是 issue 剩余验收标准所要求的。另外,此提交上的 CI 仍在进行中——我查看时 Test (ubuntu-latest, Node 22.x)、Lint & Static 与 Capture web-shell visuals 正在运行,且本 PR 的 macOS/Windows 测试任务被跳过——因此描述中引用的测试结果目前均为作者自述。请在 Tested on 中填写你本地实际验证过的平台。
描述调整完成后,用 @qwen-code /triage 重新触发,即可进入完整审查。
— Qwen Code · qwen3.8-max-2026-09-02
🖼️ web-shell visual previewRendered against a mock daemon (no real backend): the PR base vs this PR head Screenshots · before / afterℹ️ No screenshot changed against the PR base — but this PR edits 5 render-shaping files:
Either the change has no visual effect (logic, plumbing, a state the scenarios never reach), or no scenario renders this UI — in which case the preview cannot see it, and an empty result is a coverage gap rather than a clean bill of health. To make it visible, add a scenario to Full-resolution recordings (.webm) are attached to the workflow run. — Qwen Code · web-shell visuals |
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed. Suggestions are inline.
Not reviewed: reverse audit — stopped at the plan's 5-round cap without two consecutive dry rounds; rounds 3, 4 and 5 each still produced new findings, so the audit did not converge on exhaustion.
Not explored to full depth (tool budget reached): chunk 2: none — no check was cut short by the tool ceiling..
中文说明
仅完成部分审查,审查缺口已披露。 建议见行内评论。
未审查(原文为英文):reverse audit — stopped at the plan's 5-round cap without two consecutive dry rounds; rounds 3, 4 and 5 each still produced new findings, so the audit did not converge on exhaustion.
未探索到全部深度(达到工具调用预算):chunk 2:none — no check was cut short by the tool ceiling.。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| layerPlanTodos: (...args: Parameters<typeof actual.layerPlanTodos>) => { | ||
| counts.layers += 1; | ||
| return actual.layerPlanTodos(...args); |
There was a problem hiding this comment.
[Suggestion] The counts.layers counter this new test relies on can never increment, so both expect(counts.layers).toBe(layersAfterMount) assertions reduce to 0 === 0 and the "hover does not re-run the topological layering" half of the file's stated guarantee is unpinned. vi.mock('./PlanExecutionView', … importOriginal) replaces the module's exported binding, but the component under test is ...actual, whose closure calls layerPlanTodos(todos) through the module-local declaration inside its own useMemo — a module mock does not rewrite intra-module call sites.
Hoist const layers = hasDependencies ? layerPlanTodos(todos) : [todos.slice()] out of the useMemo at PlanExecutionView.tsx:249 into the component body, or split layering into a separate memo keyed on focus/hover state, and every pointerover/pointerout/focus/blur re-runs the O(V+E) topological sort — the exact regression issue #10865's acceptance criterion forbids and this file's header claims to pin "by counting rather than by inspection" — while the suite stays green. The co-located JSON.stringify spy IS a genuine global-property spy and does pin the serialization half, so only the layering counter is dead; the contrast is the sibling suites, which mock a different module from the one their consumers import, and whose counters therefore do increment.
Witness:
Probe with the test's own mock shape: nodes rendered (layering really ran): 3 / counts.layers after mount: 0 / counts.layers after direct namespace call: 1.
Mutant M1 (the call hoisted into the component body), counter instrumented on the function itself: real layerPlanTodos calls afterMount = 2 / afterHover = 3 / hover delta = 1 — while the shipped file reports 'Tests 2 passed (2)'.
Intact arm (M1 reverted, instrument kept): afterMount = 1 / afterHover = 1 / hover delta = 0, shipped test green.
Control M2 (topology + JSON.stringify(topology) hoisted out instead): shipped test RED — AssertionError: expected 1 to be +0 at :107.
Give the layering a seam a mock can reach: move layerPlanTodos into its own module (e.g. planTodoLayering.ts), import it in PlanExecutionView.tsx, re-export it from there alongside the existing taskExecutionIndex shim, and point this test's vi.mock at the new module. Then add a mount-time sanity assertion — expect(layersAfterMount).toBeGreaterThan(0) — so a non-intercepting mock fails loudly instead of passing silently. Alternative: delete the dead counter and its two assertions and correct the header comment to claim only the serialization pin.
Constraint the fix must not violate: PlanExecutionView.test.tsx:10-18 imports layerPlanTodos plus getActiveAgents, getAttentionAgentTool, getPlanNodeState, nestedAgentToolsForTool and nestedTasksForTool from './PlanExecutionView', and the comment this diff adds at PlanExecutionView.tsx:30-32 states the re-export block exists "to keep this module's public surface stable for its existing importers (tests included)" — any extraction must preserve that re-export.
Acceptance: PlanExecutionView.derivation.test.tsx › 'does not re-run the layering or the topology serialization on hover'. After the fix, expect(layersAfterMount).toBeGreaterThan(0) must hold at mount, and moving the layerPlanTodos(todos) call out of the useMemo into the component body must turn expect(counts.layers).toBe(layersAfterMount) red after the pointerover dispatch. Both mutations leave the test green today — that is the gap.
中文说明
这个新测试所依赖的 counts.layers 计数器永远不会自增,因此两处 expect(counts.layers).toBe(layersAfterMount) 断言实际都退化成 0 === 0,文件头声称要钉住的「hover 不会重跑拓扑分层」这半边保证并没有被钉住。
vi.mock('./PlanExecutionView', … importOriginal) 替换的是模块导出的绑定,但被测组件是 ...actual,它的闭包通过模块内部的局部声明调用 layerPlanTodos(todos)(在组件自己的 useMemo 里)。模块 mock 不会改写模块内部的调用点,所以包装函数根本不在渲染路径上。
把 layerPlanTodos(todos) 从 useMemo 里提到组件函数体,或把分层拆进另一个以 hover/focus 状态为依赖的 memo,那么每次 pointerover/pointerout/focus/blur 都会重跑 O(V+E) 的拓扑排序——正是 issue #10865 验收标准禁止、也是本文件头声称「用计数而非人工检查钉住」的那个回归——而测试套件依然全绿。
需要说明的边界:同一个测试里的 JSON.stringify spy 是真正的全局属性 spy,它确实钉住了拓扑序列化那一半,所以失效的只有分层计数器。对照的是同批新增的另外两个套件:它们 mock 的是与消费方不同的模块,所以计数器是真正的跨模块命名空间查找,确实会自增。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:给分层一个 mock 能拦到的接缝——把 layerPlanTodos 移到独立模块,在 PlanExecutionView.tsx 里 import 并 re-export,然后把本测试的 vi.mock 指向新模块;同时补一条挂载期自检断言 expect(layersAfterMount).toBeGreaterThan(0),让「mock 没拦住」这种情况直接失败而不是静默通过。另一种选择是删掉这个死计数器与两处断言,并把文件头注释改为只声称钉住了序列化。
约束:PlanExecutionView.test.tsx:10-18 从 './PlanExecutionView' 导入 layerPlanTodos 等六个名字,而本 diff 在 PlanExecutionView.tsx:30-32 新增的注释说明 re-export 块正是「为了保持本模块对既有导入方(含测试)的公开面稳定」——任何抽取都必须保留这个 re-export。
验收:修好之后,expect(layersAfterMount).toBeGreaterThan(0) 在挂载后必须成立;把 layerPlanTodos(todos) 调用移出 useMemo 到组件体,必须让 hover 之后的 expect(counts.layers).toBe(layersAfterMount) 变红。今天这两种变更都保持绿色,这就是缺口。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| <TranscriptRenderModeProvider> | ||
| <PlanExecutionView todos={todos} tools={[]} tasks={[]} /> |
There was a problem hiding this comment.
[Suggestion] The new derivation test renders TranscriptRenderModeProvider with no value prop. transcriptRenderMode.ts:9-10 exports it as the bare TranscriptRenderModeContext.Provider, so omitting value yields undefined and overrides the createContext('interactive') default at :5-6 — React logs a required-prop error on every run, and the component under test receives a render mode no production host produces.
documentMode at PlanExecutionView.tsx:201 (const documentMode = useTranscriptRenderMode() === 'document') is computed from undefined rather than from a declared mode, and it gates real behaviour at :898 (disabled={documentMode}) on the plan-node button. So the two guarantees this file exists to pin — hover does not re-run the layering, one measure per animation frame across a resize storm — are asserted only for an accidental undefined mode, never for the modes production uses; and every CI run of the web-shell suite carries a React provider-misuse warning attributed to this new file, which readers must triage as a non-defect each time. Every other usage in the package passes a value (PlanExecutionView.test.tsx:95, UserMessage.test.tsx:77, MessageList.dom.test.tsx:430, ParallelAgentsGroup.test.tsx:105, production WebShellTranscript.tsx:249); the sibling new suite session-workflow-surfaces.test.tsx omits the provider entirely and so warns nothing.
Witness:
From running the file: stderr | components/messages/PlanExecutionView.derivation.test.tsx > PlanExecutionView derivation discipline > does not re-run the layering or the topology serialization on hover — 'The `value` prop is required for the `<Context.Provider>`. Did you misspell it or forget to pass it?' followed by '(2 tests) 51ms' passing. One warning per test, independently observed by four agents across three review rounds.
| <TranscriptRenderModeProvider> | |
| <PlanExecutionView todos={todos} tools={[]} tasks={[]} /> | |
| <TranscriptRenderModeProvider value="interactive"> | |
| <PlanExecutionView todos={todos} tools={[]} tasks={[]} /> |
Pass the mode the assertions target — — matching the context default, or drop the wrapper and let the default apply as the sibling suite does.
Constraint the fix must not violate: The value must keep documentMode false: PlanExecutionView.tsx:201 has exactly one read site, :898 disabled={documentMode}, on the plan-node button, so value="document" (the mode the sibling PlanExecutionView.test.tsx:95 uses) is not a drop-in choice here — it would render disabled on the very node the hover assertion targets via container.querySelector('[data-plan-node-id="build"]')?.closest('article'). Use 'interactive' or 'readonly', per transcriptRenderMode.ts:3 export type TranscriptRenderMode = 'interactive' | 'readonly' | 'document'.
中文说明
新增的 derivation 测试渲染 TranscriptRenderModeProvider 时没有传 value。transcriptRenderMode.ts:9-10 导出的就是裸的 TranscriptRenderModeContext.Provider,所以省略 value 得到的是 undefined,它会覆盖掉 :5-6 处 createContext<TranscriptRenderMode>('interactive') 的默认值——React 每次运行都会打印必填 prop 的错误,被测组件拿到的是一个生产环境永远不会出现的渲染模式。
PlanExecutionView.tsx:201 的 documentMode(useTranscriptRenderMode() === 'document')于是基于 undefined 计算,而它在 :898 通过 disabled={documentMode} 影响真实行为(计划节点按钮)。也就是说,本文件要钉住的两条保证——hover 不重跑分层、一次 resize 风暴只跑一轮 measure——只在一个意外的 undefined 模式下被断言过,生产真正使用的模式从未被覆盖;并且每次 CI 运行 web-shell 套件都会带上这条归属于新文件的 React provider 误用告警,读者每次都要重新判断它不是缺陷。包内其他所有使用点都传了 value(PlanExecutionView.test.tsx:95、UserMessage.test.tsx:77、MessageList.dom.test.tsx:430、ParallelAgentsGroup.test.tsx:105,生产代码 WebShellTranscript.tsx:249);同批新增的 session-workflow-surfaces.test.tsx 干脆不套这个 provider,因此不产生告警。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:传入断言真正针对的模式 <TranscriptRenderModeProvider value="interactive">(与 context 默认值一致),或者像姊妹套件那样直接去掉这层包裹、让默认值生效。
约束:传入的值必须让 documentMode 保持 false。PlanExecutionView.tsx:201 只有一个读取点,即 :898 计划节点按钮上的 disabled={documentMode},所以这里不能照搬姊妹测试 PlanExecutionView.test.tsx:95 用的 value="document"——那会让 hover 断言要操作的那个节点(container.querySelector('[data-plan-node-id="build"]')?.closest('article'))直接变成 disabled。请用 'interactive' 或 'readonly',取值范围见 transcriptRenderMode.ts:3。
验收:N/A——没有任何断言读取这个 context,所以去掉新加的 value 不会让任何测试变红。可观察的验收标准是:套件运行时这条 React 告警消失,同时两个用例仍然通过。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| // One viewport change lands as several schedule calls in the same | ||
| // frame (the window resize plus, in a real browser, the resize | ||
| // observer's per-node batch). All of them must share a single |
There was a problem hiding this comment.
[Suggestion] The coalescing test drives only the window resize listener; the ResizeObserver source its own comment names is never exercised, because client/test/setup.ts:38-43 installs a ResizeObserverStub whose observe() is a silent no-op that never invokes the callback. packages/web-shell/vitest.config.ts sets setupFiles: ['./test/setup.ts'] with root: 'client', so the stub applies to this file.
PlanExecutionView.tsx:512-517 does construct the observer with scheduleMeasure and calls observe() on the graph element plus every node, but the stub never fires, so the only path reaching scheduleMeasure in this test is window.dispatchEvent(new Event('resize')) three times. The observer half of the storm — which the component's own comment at PlanExecutionView.tsx:493-498 names as the dominant real-world source ("Every node is observed and a window resize lands in the same frame as the observer's own batch, so one viewport change ran measure many times over") — has zero coverage. Rewire the observer to the un-coalesced function (new ResizeObserver(measure) at :515) and in a browser a single viewport change on a 20-step plan runs 20+ full measure passes, each reading 21 rects and concatenating a 20-edge signature string, while both assertions stay green.
Witness:
INTACT: PlanExecutionView.derivation.test.tsx 2/2 green (baseline). MUTANT :515 new ResizeObserver(scheduleMeasure) -> new ResizeObserver(measure): 'Test Files 3 passed (3) / Tests 35 passed (35)' — derivation 2/2, PlanExecutionView.test 30/30, surfaces 3/3 all green. Premise probe: {"nodes":3,"constructed":1,"observed":4,"callbacks":0,"framesDelta":1,"rects":4} — observer constructed, observe() called 4x (graph + 3 nodes), callback fired 0 times. FLIP CONTROL (:511 window listener -> measure, the path the test does drive): 'AssertionError: expected +0 to be 1 (:159)' — so the harness is not vacuous.
Give the test a controllable observer, following the pattern already used three times in this package (PaneHeaderActions.test.tsx:20-27 and :113, data-table.test.tsx:142-163, App.test.tsx:13270-13291): collect the constructor callbacks via vi.stubGlobal('ResizeObserver', …) before mount(), then fire the captured callback once per observed target inside the SAME act() as the window resizes, and assert the rect count taken BEFORE the frame runs is still nodes + 1. Restore with vi.unstubAllGlobals() alongside the existing animationSpy.mockRestore().
Constraint the fix must not violate: The observer callbacks must be fired inside the same act() as the window resizes and strictly before frames.at(-1)!(0) runs the frame — PlanExecutionView.tsx:502-506 is if (pending) return; pending = true; frame = requestAnimationFrame(() => { pending = false; measure(); });, so pending is cleared only when the callback executes; firing the observer after the frame has run would legitimately schedule a second frame and the delta assertion would read 2 on correct code.
Acceptance: The observable that flips is the rect count taken before the frame runs, NOT the frame delta. Measured with the observer callbacks driven 4x in the same act(): INTACT {"observerCallbacksFired":4,"framesDelta":1,"rectsAfterStorm":4} green vs MUTANT {"observerCallbacksFired":4,"framesDelta":1,"rectsAfterStorm":20} -> 'AssertionError: expected 20 to be 4'. A direct measure never schedules a frame so framesDelta stays 1, and the shipped test's rectSpy.mockClear() sits between the storm and the frame run, erasing the observer-driven reads — so an assertion on frames.length - framesAfterMount would not catch this.
中文说明
这个合并调度的测试只驱动了 window 的 resize 监听器;它自己注释里点名的另一个来源 ResizeObserver 从未被触发,因为 client/test/setup.ts:38-43 装的 ResizeObserverStub 的 observe() 是个静默空实现,永远不会回调。packages/web-shell/vitest.config.ts 设了 setupFiles: ['./test/setup.ts'] 且 root: 'client',所以这个 stub 对本文件生效。
PlanExecutionView.tsx:512-517 确实用 scheduleMeasure 构造了 observer,并对图容器和每个节点调用了 observe(),但 stub 从不触发回调,于是本测试里唯一能走到 scheduleMeasure 的路径就是三次 window.dispatchEvent(new Event('resize'))。而风暴里的 observer 这一半——组件自己的注释在 PlanExecutionView.tsx:493-498 明确说它是真实世界里的主要来源(「每个节点都被 observe,一次 window resize 会和 observer 自己的批量回调落在同一帧,所以一次视口变化会让 measure 跑很多遍」)——覆盖率为零。把 observer 改接到未合并的函数上(:515 写成 new ResizeObserver(measure)),在浏览器里一次视口变化对一个 20 步计划就会跑 20 多轮完整 measure,每轮读 21 个 rect 并拼接 20 条边的签名字符串,而两条断言依然全绿。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:给测试一个可控的 observer,沿用本包已有的三处写法(PaneHeaderActions.test.tsx:20-27 与 :113、data-table.test.tsx:142-163、App.test.tsx:13270-13291):在 mount() 之前用 vi.stubGlobal('ResizeObserver', …) 收集构造回调,然后在与 window resize 同一个 act() 里按被 observe 的目标数各触发一次回调,并断言在帧运行之前读到的 rect 数仍是 nodes + 1。收尾与现有的 animationSpy.mockRestore() 一起调用 vi.unstubAllGlobals()。
约束:observer 回调必须在与 window resize 同一个 act() 内、且严格在 frames.at(-1)!(0) 执行帧之前触发——PlanExecutionView.tsx:502-506 是 if (pending) return; pending = true; frame = requestAnimationFrame(() => { pending = false; measure(); });,pending 只有在回调执行时才会被清除;如果在帧已经跑完之后再触发 observer,那会正当地再调度一帧,delta 断言在正确的代码上就会读到 2。
验收:会翻转的可观测量是帧运行之前的 rect 计数,不是帧的 delta。实测把 observer 回调在同一 act() 内触发 4 次:原状 {observerCallbacksFired:4, framesDelta:1, rectsAfterStorm:4} 绿;变异后 {observerCallbacksFired:4, framesDelta:1, rectsAfterStorm:20} 红(expected 20 to be 4)。直接调用 measure 从不调度帧,所以 framesDelta 始终是 1;而且现有测试的 rectSpy.mockClear() 正好夹在风暴与帧运行之间,会把 observer 触发的读取清掉——所以对 frames.length - framesAfterMount 加断言抓不到这个问题。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| * Shared task-execution lookups for the plan surfaces. Extracted from | ||
| * `PlanExecutionView` so the workflow projection (`session-workflow-model`) |
There was a problem hiding this comment.
[Suggestion] The 398-line shared module this diff creates has no collocated test file, against AGENTS.md's "Tests: Collocated with source (file.test.ts next to file.ts), vitest framework" and against every sibling in this change (session-workflow-model.ts / session-workflow-model.index.test.ts, PlanExecutionView.tsx / PlanExecutionView.test.tsx). Every behavioural assertion on its moved pure functions stays behind in PlanExecutionView.test.tsx — a file this PR does not touch — reaching them only through the compatibility re-export block.
The assertions that actually exercise this module are PlanExecutionView.test.tsx:133,144,150,160,174,187,202,210,227,231,243,270,292,300,324,581, importing getActiveAgents, getAttentionAgentTool, getPlanNodeState, nestedAgentToolsForTool and nestedTasksForTool from './PlanExecutionView' at :10-18. The two new test files that do name this module only wrap createTaskExecutionIndex in a counter and assert build counts, never behaviour. So the obvious cleanup when the graph is next touched — dropping those helper describe blocks as "not this component's tests" — deletes the only behavioural coverage of getPlanNodeStateFromIndex's status precedence, attentionAgentStatuses' record() non-downgrade ordering and nestedTasksFromIndex's visited cycle guard, and CI stays green: no test file goes missing, no assertion fails, and nothing marks the loss because the module has no test file whose absence is visible. Secondarily, pure-function assertions about a dependency-free module are paid for inside a jsdom file that also mounts the graph component with its CSS module, i18n provider and rAF measurement effects.
Witness:
git ls-tree -r --name-only HEAD -- packages/web-shell/client/components/messages/ | grep -i taskExecution -> taskExecutionIndex.ts only; no .test.ts at HEAD or on disk. Behaviour bug injected into the extracted module (taskExecutionIndex.ts:316 attention: false -> attention), run over all five test files referencing either module: 'FAIL components/messages/PlanExecutionView.test.tsx > PlanExecutionView > clears resolved failures when their todo is completed -> expected { Object (status, attention) } to deeply equal { status: 'completed', …(1) }'; 'Test Files 1 failed | 4 passed (5)', 'Tests 1 failed | 38 passed (39)'. The only catcher is a test in a file named for a different module; session-workflow-surfaces.test.tsx and session-workflow-model.index.test.ts stayed green.
Add packages/web-shell/client/components/messages/taskExecutionIndex.test.ts and move the getPlanNodeState / getAttentionAgentTool / nestedTasksForTool / getActiveAgents / nestedAgentToolsForTool describe blocks out of PlanExecutionView.test.tsx into it, importing directly from './taskExecutionIndex'. Leave the component-render and layerPlanTodos blocks where they are. This also removes the pressure on the re-export block: once the tests import the new module directly, that block no longer has to exist for its existing importers.
Constraint the fix must not violate: layerPlanTodos was NOT moved — the deletion hunk's own header is '@@ -128,328 +140,6 @@ export function layerPlanTodos(todos: readonly TodoItem[]): TodoItem[][] {' and it is still called at PlanExecutionView.tsx:249 — and PlanExecutionView.test.tsx:14 imports it from './PlanExecutionView', so the relocation must split that import list, not move it wholesale.
中文说明
本 diff 新建的这个 398 行共享模块没有同目录的测试文件,这与 AGENTS.md 的「Tests: Collocated with source (file.test.ts next to file.ts), vitest framework」相悖,也与本次改动里的每个同类文件不一致(session-workflow-model.ts / session-workflow-model.index.test.ts,PlanExecutionView.tsx / PlanExecutionView.test.tsx)。它所有被搬过来的纯函数的行为断言都留在 PlanExecutionView.test.tsx 里——一个本 PR 没有改动的文件——只能透过兼容用的 re-export 块才够得着。
真正在测这个模块的断言是 PlanExecutionView.test.tsx:133,144,150,160,174,187,202,210,227,231,243,270,292,300,324,581,它们在 :10-18 从 './PlanExecutionView' 导入 getActiveAgents、getAttentionAgentTool、getPlanNodeState、nestedAgentToolsForTool、nestedTasksForTool。而两个确实点名了这个新模块的测试文件只是把 createTaskExecutionIndex 包进计数器、断言构建次数,从不断言行为。
具体代价:下次改动图组件时最自然的清理,就是把这些 helper describe 块当成「不是本组件的测试」删掉——那会删掉 getPlanNodeStateFromIndex 的状态优先级、attentionAgentStatuses 的 record() 不降级顺序、以及 nestedTasksFromIndex 的 visited 环检测的唯一行为覆盖,而 CI 依然全绿:没有测试文件消失、没有断言失败,也没有任何东西标记这次损失,因为这个模块根本没有一个「缺失就能被看见」的测试文件。其次,一个无依赖模块的纯函数断言,现在要在一个 jsdom 文件里付费——那个文件同时还挂载了图组件及其 CSS module、i18n provider 和 rAF 测量副作用。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:新增 packages/web-shell/client/components/messages/taskExecutionIndex.test.ts,把 getPlanNodeState / getAttentionAgentTool / nestedTasksForTool / getActiveAgents / nestedAgentToolsForTool 这些 describe 块从 PlanExecutionView.test.tsx 迁过去,直接从 './taskExecutionIndex' 导入;组件渲染与 layerPlanTodos 的块留在原处。这样也顺带化解了 re-export 块的压力:一旦测试直接导入新模块,那个块就不再需要「为了既有导入方」而存在。
约束:layerPlanTodos 没有被搬走——删除 hunk 自己的头就是 @@ -128,328 +140,6 @@ export function layerPlanTodos(todos: readonly TodoItem[]): TodoItem[][] {,它仍然在 PlanExecutionView.tsx:249 被调用,且 PlanExecutionView.test.tsx:14 从 './PlanExecutionView' 导入它,所以迁移必须拆分那份导入列表,而不是整体搬走。
验收:N/A——这个修复只是搬迁既有断言,没有新增可被测试钉住的守卫、分支或行为。可观察的验收标准是:同样的断言在新文件里仍然运行并通过,并且只删掉 PlanExecutionView.test.tsx 的组件渲染块不再会连带删掉这个被抽取模块的覆盖。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| * and the graph (`PlanExecutionView`) both depend on this module instead of | ||
| * on each other, and so one build of the index can be threaded from the | ||
| * projection into every consumer in a single render. |
There was a problem hiding this comment.
[Suggestion] The new module header claims the graph and the workflow projection "both depend on this module instead of on each other", but this diff reverses that edge rather than removing it: PlanExecutionView.tsx:25-26 now imports SessionWorkflowProjection and buildSessionWorkflowProjection from ../workflow/session-workflow-model, so the two modules are still directly coupled and the only sentence in the repo documenting why this module exists states a module-graph property that is false at HEAD.
At the merge base git grep 'session-workflow-model' over packages/web-shell/client/components/messages/ returns nothing — the graph never imported the model — and session-workflow-model.ts was one of two importers of '../messages/PlanExecutionView'. At HEAD that importer is gone and the graph imports the model instead. A maintainer adding the next shared helper reads this header, concludes the two modules are independent, and imports a projection type from session-workflow-model into taskExecutionIndex.ts — closing the cycle taskExecutionIndex -> session-workflow-model -> taskExecutionIndex (the model already imports this module at session-workflow-model.ts:9-11) that the extraction exists to prevent, in the one module whose header says that cannot happen. Acyclicity holds today; the comment is what is wrong.
Witness:
Edge direction measured at both commits. BASE: git grep 'session-workflow-model' 62588d2892 -- packages/web-shell/client/components/messages/ -> (none); git grep 'messages/PlanExecutionView' 62588d2892 -> session-workflow-model.ts:15 (model -> graph). HEAD: session-workflow-model.ts:9-16 imports from '../messages/taskExecutionIndex'; git grep 'session-workflow-model' a0e85e8063 -- packages/web-shell/client/components/messages/ -> PlanExecutionView.tsx:25 (import type SessionWorkflowProjection) and :26 (import buildSessionWorkflowProjection) (graph -> model).
| * and the graph (`PlanExecutionView`) both depend on this module instead of | |
| * on each other, and so one build of the index can be threaded from the | |
| * projection into every consumer in a single render. | |
| * and the graph (`PlanExecutionView`) depends on this module rather than on | |
| * the projection reaching back into the graph component — the graph still | |
| * imports the projection for its standalone fallback — and so one build of | |
| * the index can be threaded from the projection into every consumer in a | |
| * single render. |
Reword the two clauses to what the change actually achieved — the projection no longer reaches into the graph component, and the graph now reaches into the projection for its standalone fallback — rather than asserting mutual independence.
Constraint the fix must not violate: PlanExecutionView.tsx:25-26 imports both the SessionWorkflowProjection type and buildSessionWorkflowProjection from '../workflow/session-workflow-model', so the rewording must not assert mutual independence; and taskExecutionIndex.ts:1-7 must keep importing nothing from session-workflow-model, because session-workflow-model.ts:9-11 imports createTaskExecutionIndex, getActiveAgentsFromIndex and nestedTasksFromIndex from './taskExecutionIndex'.
中文说明
新模块的头注释声称图与 workflow projection「都依赖本模块,而不再互相依赖」,但本 diff 是把这条边反转了,而不是删掉了:PlanExecutionView.tsx:25-26 现在从 ../workflow/session-workflow-model 导入 SessionWorkflowProjection 与 buildSessionWorkflowProjection,两个模块依然直接耦合,而仓库里唯一一句说明「这个模块为什么存在」的话,陈述了一个在 HEAD 上为假的模块图属性。
在 merge base(62588d28)上,对 packages/web-shell/client/components/messages/ 执行 git grep "session-workflow-model" 什么也不返回——图从来没有导入过 model——而 session-workflow-model.ts 是 '../messages/PlanExecutionView' 的两个导入方之一。到 HEAD,那个导入方消失了,取而代之的是图导入 model。
具体代价:下一位要往这里加共享 helper 的维护者读到这句头注释,会以为两个模块互相独立,于是把 projection 的类型从 session-workflow-model 导入进 taskExecutionIndex.ts——这就闭合成环 taskExecutionIndex → session-workflow-model → taskExecutionIndex(model 已经在 session-workflow-model.ts:9-11 导入本模块),正是这次抽取要防止的环,而且发生在唯一一个头注释声称「这不可能」的模块里。今天无环成立;错的是这句注释。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:把这两句改成这次改动实际达成的效果——projection 不再反向伸进图组件,而图为了自己的 standalone 回退路径确实会导入 projection——而不是断言两者互相独立。
约束:PlanExecutionView.tsx:25-26 同时导入了 SessionWorkflowProjection 类型和 buildSessionWorkflowProjection,所以改写后的措辞不能断言互相独立;并且 taskExecutionIndex.ts:1-7 必须继续不从 session-workflow-model 导入任何东西,因为 session-workflow-model.ts:9-11 从 './taskExecutionIndex' 导入 createTaskExecutionIndex、getActiveAgentsFromIndex、nestedTasksFromIndex。
验收:N/A——纯注释改动,没有可供测试钉住的守卫、分支或行为。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| // task-execution index it carries; a regression re-introduces extra builds | ||
| // in the component bodies (App builds exactly one and passes it down). | ||
| // In its own file so the module mocks cannot reach the behavioural suites. | ||
| const counts = vi.hoisted(() => ({ projections: 0, indexBuilds: 0 })); |
There was a problem hiding this comment.
[Suggestion] The first test is the only one of the three that does not reset the module-level counts object on entry, so its opening toBe(1) pair silently depends on it running first — the suite is order-coupled and fails on correct code under any reordering. counts is vi.hoisted at :18 with no beforeEach or beforeAll anywhere in the file; test 1's first executable statement is the build at :114 and its only reset is the mid-test one at :117-118, while test 2 resets on entry at :164-165 and test 3 at :191-192, and both leave counts at {projections: 1, indexBuilds: 1}.
Whichever of tests 2 and 3 runs before test 1 hands it a count of 1 that test 1's own build turns into 2, so expect(counts.projections).toBe(1) at :115 fails on unmodified, correct code. The same red arrives with no flag at all the first time someone inserts a fourth test above test 1 that builds a projection — an ordinary edit. The failure reads as a duplicate projection build, i.e. exactly the perf regression this file exists to alarm on, so whoever triages it spends the round chasing a regression that is not there. Nothing in this repo enables shuffle today, so the defect is latent rather than live — but the repo already holds this discipline as a convention: packages/cli/src/serve/fast-path.test.ts:2190-2194, over a module-global stash and an exact-match assertion (the same shape as counts), comments "The stash is a module-global; drain any residue left by earlier tests so this exact-match assertion does not depend on test declaration order (partial -t selection, --sequence.shuffle, or a new load-bearing test inserted before this one)" and resets on entry. This new file does the opposite in test 1 only.
Witness:
Unmodified code, the reproduction command: npx vitest run components/workflow/session-workflow-surfaces.test.tsx --sequence.shuffle --sequence.seed=3 -> 'AssertionError: expected 2 to be 1' at session-workflow-surfaces.test.tsx:115:32, 'Tests 1 failed | 2 passed (3)'. Sized rather than taken on one seed: UNMODIFIED shuffled seeds 1-20 -> RED=13 GREEN=7 (red on seeds 2,3,8,9,10,11,12,13,14,16,17,18,19 — 13/20 is the share of orderings where test 1 does not run first); FIXED (2-line entry reset in test 1, mid-test reset at :117-118 kept) shuffled seeds 1-20 -> RED=0 GREEN=20; FIXED ordered -> 'Tests 3 passed (3)'; UNMODIFIED ordered -> 'Tests 3 passed (3)'.
Add counts.projections = 0; counts.indexBuilds = 0; as test 1's first two statements, leaving the mid-test reset at :117-118 untouched — this variant was verified green across all 20 seeds and ordered. Or hoist the resets into a beforeEach and drop the three per-test entry copies, keeping the mid-test reset; that variant also verified green.
Constraint the fix must not violate: The mid-test reset must stay AFTER the two toBe(1) assertions, not be merged into the new entry reset — counts.projections = 0 and counts.indexBuilds = 0 at :117-118 are what make expect(counts.projections).toBe(0) and expect(counts.indexBuilds).toBe(0) at :149-150 measure only the mount; clearing before :115 would leave the file's only in-mount pin on "one projection builds exactly one index" asserting against a counter that was never incremented.
Acceptance: npx vitest run components/workflow/session-workflow-surfaces.test.tsx --sequence.shuffle --sequence.seed=3 from packages/web-shell is red today ('expected 2 to be 1', :115) and must go green after the fix, while the default ordered run stays green in both states. Any seed that does not place test 1 first reproduces it.
中文说明
三个测试里只有第一个没有在进入时重置模块级的 counts 对象,所以它开头那对 toBe(1) 断言其实暗中依赖「它必须第一个跑」——整个套件是顺序耦合的,在正确的代码上只要换个执行顺序就会失败。counts 在 :18 用 vi.hoisted 创建,文件里没有任何 beforeEach / beforeAll;测试 1 的第一条可执行语句就是 :114 的构建,它唯一的重置是 :117-118 的测试中途重置,而测试 2 在 :164-165、测试 3 在 :191-192 都在进入时重置,并且两者跑完都把 counts 留在 {projections: 1, indexBuilds: 1}。
于是测试 2 或 3 中任何一个先跑,都会交给测试 1 一个 1,测试 1 自己再构建一次就变成 2,:115 的 expect(counts.projections).toBe(1) 在未修改的正确代码上失败。同样的红也不需要任何 flag:只要有人在测试 1 上面插入第四个会构建 projection 的测试就会发生——那是一次很普通的编辑。而这个失败读起来像是「projection 被构建了两次」,正是本文件存在的目的所要报警的那个性能回归,所以值班的人会花一整轮去追一个并不存在的回归。
今天仓库里没有任何地方开启 shuffle,所以这个缺陷是潜在的而非现存的。但仓库已经把这条纪律当作惯例:packages/cli/src/serve/fast-path.test.ts:2190-2194 面对一个模块级全局暂存和一条精确匹配断言(与 counts 完全同形),注释写着这个暂存是模块级全局的,所以要清掉前面测试留下的残留,以免这条精确匹配断言依赖测试声明顺序,并点名了三种触发方式:-t 部分选择、--sequence.shuffle、以及在它之前插入新的关键测试;它也在进入时重置。这个新文件只在测试 1 上做了相反的事。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:把 counts.projections = 0; counts.indexBuilds = 0; 作为测试 1 的头两条语句加上,:117-118 的中途重置保持不动——这一变体已实测在全部 20 个 seed 与顺序执行下均绿。或者把重置提进 beforeEach 并删掉三处逐测试的进入重置(保留中途重置),该变体也已实测为绿。
约束:中途重置必须留在那两条 toBe(1) 断言之后,不能与新的进入重置合并——:117-118 的 counts.projections = 0 / counts.indexBuilds = 0 正是让 :149-150 的 expect(counts.projections).toBe(0) / expect(counts.indexBuilds).toBe(0) 只度量这次挂载的原因;若在 :115 之前就清零,本文件里唯一那条「一份 projection 恰好构建一次 index」的挂载内断言就会去断言一个从未自增过的计数器。
验收:在 packages/web-shell 下执行 npx vitest run components/workflow/session-workflow-surfaces.test.tsx --sequence.shuffle --sequence.seed=3,今天是红的(expected 2 to be 1,:115),修复后必须变绿,同时默认顺序执行在两种状态下都保持绿。任何不把测试 1 排在首位的 seed 都能复现。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| const shared = buildSessionWorkflowProjection(todos, tools, tasks); | ||
| expect(counts.projections).toBe(1); | ||
| expect(counts.indexBuilds).toBe(1); |
There was a problem hiding this comment.
[Suggestion] The suite's headline contract — App builds exactly one projection and passes it down — is simulated by a direct call to buildSessionWorkflowProjection and never exercised. Nothing in the repo renders App under these counters, so losing the projection prop in App.tsx ships green across the whole package.
Delete projection: sessionWorkflowProjection from the ArtifactPanel workflow object (App.tsx:15960) and projection={sessionWorkflowProjection} from the cockpit JSX (App.tsx:17307) and every consumer falls back through sharedProjection ?? buildSessionWorkflowProjection(todos, tools, tasks) — three projection builds and three createTaskExecutionIndex builds per render, the O((todos + tools) x tasks) cost this PR removed. This file still passes because it hands the shared object to the surfaces itself, and no test anywhere counts App's builds. The three tests pin only the consumer half of the contract, which is the half that cannot silently regress on its own.
Witness:
Mutation run in a scratch tree, both App pass-down sites removed (mutation confirmed by grep -c -> 0): session-workflow-surfaces.test.tsx '(3 tests)' green; whole workflow + graph set 'Test Files 10 passed (10) / Tests 67 passed (67)'; whole App.test.tsx under the mutant 'Tests 746 passed (746)' in 91.24s. And grep -n "session-workflow-model|taskExecutionIndex|buildSessionWorkflowProjection|createTaskExecutionIndex" client/App.test.tsx -> zero matches.
Add an App-level counter test in its own file: apply the same two vi.mock counting wrappers, render App into the session-workflow view (the shape App.test.tsx:9640-9670 already reaches, where [data-plan-node-id] nodes are present), and assert counts.projections === 1 and counts.indexBuilds === 1 for that render.
Constraint the fix must not violate: session-workflow-surfaces.test.tsx:17 states '// In its own file so the module mocks cannot reach the behavioural suites.' — vi.mock is file-scoped, so the counting mocks must not be added to App.test.tsx itself; the App-level counter assertions need their own file.
Acceptance: That new App-level test must go red when projection={sessionWorkflowProjection} is removed from the cockpit/inspector JSX in App.tsx — counts.projections becomes 3 for one render instead of 1. The consumer-half tests in this file stay green under that mutation, which is the gap.
中文说明
本套件的头条契约——App 只构建一份 projection 并往下传——是用一次直接调用 buildSessionWorkflowProjection 模拟出来的,从未被真正执行过:仓库里没有任何测试在这些计数器下渲染 App,所以 App.tsx 里丢掉这个 projection prop 也能让整个包全绿。
把 projection: sessionWorkflowProjection 从 ArtifactPanel 的 workflow 对象(App.tsx:15960)里删掉、并把 projection={sessionWorkflowProjection} 从 cockpit JSX(App.tsx:17307)里删掉,每个消费方都会经 sharedProjection ?? buildSessionWorkflowProjection(todos, tools, tasks) 回退——一次渲染三份 projection、三次 createTaskExecutionIndex,正是本 PR 要消除的 O((todos + tools) × tasks) 开销。而本文件依然通过,因为它自己把 shared 对象递给了各个 surface;仓库里也没有任何测试统计 App 的构建次数。这三个测试只钉住了契约的消费方那一半,而那一半恰恰是不可能自己悄悄回归的。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:在单独的文件里加一个 App 级计数测试:套上同样两个 vi.mock 计数包装,把 App 渲染进 session-workflow 视图(App.test.tsx:9640-9670 已经能到达的形态,那里存在 [data-plan-node-id] 节点),并断言这一次渲染的 counts.projections === 1 与 counts.indexBuilds === 1。
约束:session-workflow-surfaces.test.tsx:17 写着「放在独立文件里,以免模块 mock 影响到行为套件」——vi.mock 是文件级的,所以这些计数 mock 不能加进 App.test.tsx 本身,App 级计数断言需要自己的文件。
验收:那个新的 App 级测试必须在 App.tsx 的 cockpit/inspector JSX 中移除 projection={sessionWorkflowProjection} 时变红——一次渲染的 counts.projections 会从 1 变成 3。本文件里针对消费方的那几个测试在同一变异下保持绿色,这就是缺口。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| <SessionWorkflowInspector | ||
| todos={todos} | ||
| tools={tools} | ||
| tasks={tasks} | ||
| projection={shared} |
There was a problem hiding this comment.
[Suggestion] Test 1 is the only test in the repo that mounts a surface with a projection prop, and it has two coupled defects. First, nothing in it is attributable to the inspector: all six post-mount assertions are satisfiable by the cockpit subtree alone, so deleting the JSX leaves the test green. Second, it mounts the inspector in the branch production never renders beside the cockpit — canvasMode is left at its false default, while App.tsx:15967 sets canvasMode: mainView === 'cockpit' in the SAME workflow object literal (artifactPanelSharedProps, App.tsx:15922) that carries projection: sessionWorkflowProjection at :15960, and App.tsx:17299 gates the cockpit on workspaceContextActive && mainView === 'cockpit'. So cockpit mounted implies canvasMode true, which implies the inspector takes the early return at SessionWorkflowInspector.tsx:188 and renders data-testid="workflow-canvas-detail" (:190) rather than the summary/progress/step-list subtree this test renders.
Because the combined tree the test pins cannot occur, the derivation contract on the state that DOES occur is unasserted anywhere: give the canvas branch its own buildSessionWorkflowProjection(todos, tools, tasks), or stop forwarding the shared projection only in cockpit view, and every suite in the package stays green — re-introducing exactly the duplicate per-render derivation #10865 asked to remove, on the one screen where two surfaces are visible at once. Separately, the standing comment at :159 ('The inspector reads the same state the cockpit header does') sits above expect(container.textContent).toContain('Build the thing'), which the cockpit's own embedded graph satisfies without the inspector, since the graph renders todo.content at PlanExecutionView.tsx:916 and todo.id at :905 while [data-testid="session-workflow-cockpit"] is the cockpit's own root at SessionWorkflowCockpit.tsx:89. App.test.tsx does assert the canvas testid at :9661 and :9674, so the branch is not wholly untested — but App.test.tsx never counts derivation, which is this file's whole job. The two defects must be fixed together: adding canvasMode without changing the assertion target, or adding a workflow-inspector assertion without canvasMode, each leaves the file wrong in the other's way.
Witness:
Attribution (three mutants on the shipped file): M1 '<SessionWorkflowInspector /> JSX deleted from test 1' -> test 1 PASSES, all six post-mount assertions green; M2 'inspector body returns null' -> test 1 passes, test 3 red at :208; M3 'inspector useMemo drops sharedProjection ??' -> test 1 RED at :149, so the counter pair IS inspector-attributable and only the DOM/text assertions are blind. Probe across both arms: cockpit-testid, plan-node-verify and both toContain strings read identically true, while workflow-inspector goes true -> false. Branch: A-test1-as-written {cockpit:true, listInspector:true, canvasInspector:false} vs B-cockpit-plus-canvas {cockpit:true, listInspector:false, canvasInspector:true}. Derivation gap: the canvas-only-rebuild mutant survives the whole suite at HEAD (SessionWorkflowInspector.test.tsx 2, session-workflow-surfaces.test.tsx 3, App.test.tsx 746 with 745 skipped) and the one-line fixture fix catches it -> 'expected 1 to be +0' at :150. Fix coupling measured: pristine fixture + a workflow-inspector assertion -> 3 passed; canvasMode added + that same assertion -> 'expected null to be truthy' at :157.
One edit to test 1 closes both: pass canvasMode to the inspector JSX (keeping projection={shared}), and add expect(container.querySelector('[data-testid="workflow-canvas-detail"]')).toBeTruthy(); beside the cockpit assertion. That single assertion is inspector-attributable AND names the branch production actually renders beside the cockpit. Do not assert [data-testid="workflow-inspector"] here — it is absent in the combined state. Test 3 already covers the list-mode inspector standing alone, which is the only production state that branch has (App.test.tsx:9634-9639 asserts workflow-inspector while cockpit-page is null).
Constraint the fix must not violate: App.tsx:17299 '{workspaceContextActive && mainView === 'cockpit' && (' is the cockpit's only mount gate and App.tsx:15967 'canvasMode: mainView === 'cockpit',' sits in the same object literal as App.tsx:15960 'projection: sessionWorkflowProjection,', so a combined cockpit+inspector fixture must use canvasMode true. And because the canvas branch returns before the summary and step-list sections (SessionWorkflowInspector.tsx:188-197), the existing expect(container.textContent).toContain('Verify the thing') can then only be satisfied by the cockpit's embedded graph — probe row D confirms the canvas inspector alone renders no 'Verify the thing' (textHasVerify false, graphNodeVerify false), so keep that string attributed to the graph.
Acceptance: With both changes, deleting the JSX from test 1 turns it red ('expected null to be truthy'), and dropping projection={shared} while keeping canvasMode turns expect(counts.projections).toBe(0) at :150 red (reads 1, because the fallback useMemo at SessionWorkflowInspector.tsx:60-65 runs before the early return and builds one). Mutating SessionWorkflowInspector.tsx:188 from 'if (canvasMode)' to 'if (false)' must fail the new canvas-detail assertion — note it also fails the pre-existing App.test.tsx:9661.
中文说明
测试 1 是仓库里唯一给 surface 传 projection prop 的测试,而它有两个互相耦合的缺陷。
第一,其中没有任何断言可归因于 inspector:挂载后的六条断言全部都能由 cockpit 子树单独满足,所以把 <SessionWorkflowInspector /> JSX 整段删掉,测试依然绿。
第二,它把 inspector 挂在了生产环境永远不会与 cockpit 同时渲染的那个分支上——canvasMode 保持在默认的 false,而 App.tsx:15967 在同一个 workflow 对象字面量(artifactPanelSharedProps,App.tsx:15922)里设置了 canvasMode: mainView === 'cockpit',这个对象同时在 :15960 携带 projection: sessionWorkflowProjection;而 App.tsx:17299 把 cockpit 的挂载条件定为 workspaceContextActive && mainView === 'cockpit'。所以「cockpit 已挂载」蕴含 canvasMode === true,进而 inspector 会走 SessionWorkflowInspector.tsx:188 的提前返回、渲染 data-testid="workflow-canvas-detail"(:190),而不是本测试所渲染的摘要/进度/步骤列表子树。
由于本测试钉住的那棵组合树根本不会出现,真正会出现的那个状态上的推导契约就无处被断言:给 canvas 分支单独一份 buildSessionWorkflowProjection(todos, tools, tasks),或者只在 cockpit 视图下停止往下传共享 projection,包里每个套件都保持绿色——这正好把 #10865 要求消除的「每次渲染重复推导」重新引入到唯一一个两个 surface 同时可见的界面上。
另外,:159 那句常驻注释(「inspector 读取与 cockpit 表头相同的状态」)位于 expect(container.textContent).toContain('Build the thing') 之上,而这条断言由 cockpit 内嵌的图就能满足、不需要 inspector:图在 PlanExecutionView.tsx:916 渲染 todo.content、在 :905 渲染 todo.id,而 [data-testid="session-workflow-cockpit"] 是 cockpit 自己的根节点(SessionWorkflowCockpit.tsx:89)。App.test.tsx:9661 与 :9674 确实断言了 canvas 那个 testid,所以该分支并非全无测试——但 App.test.tsx 从不统计推导次数,而那正是本文件的职责。
两个缺陷必须一起修:只加 canvasMode 而不改断言目标,或只加 workflow-inspector 断言而不加 canvasMode,都会让文件在另一个方向上是错的。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:对测试 1 做一次编辑即可同时关闭两者——给 inspector JSX 传 canvasMode(保留 projection={shared}),并在 cockpit 断言旁边加上 expect(container.querySelector('[data-testid="workflow-canvas-detail"]')).toBeTruthy();。这一条断言既可归因于 inspector,又指向生产环境真正与 cockpit 同时渲染的那个分支。不要在这里断言 [data-testid="workflow-inspector"]——它在组合状态下不存在。测试 3 已经覆盖了列表模式 inspector 单独挂载的情形,那是该分支唯一的生产状态(App.test.tsx:9634-9639 在 cockpit-page 为 null 时断言 workflow-inspector)。
约束:App.tsx:17299 的 {workspaceContextActive && mainView === 'cockpit' && ( 是 cockpit 唯一的挂载门,而 App.tsx:15967 的 canvasMode: mainView === 'cockpit', 与 App.tsx:15960 的 projection: sessionWorkflowProjection, 位于同一个对象字面量,所以 cockpit + inspector 的组合 fixture 必须使用 canvasMode 为 true。并且因为 canvas 分支在摘要与步骤列表之前就返回(SessionWorkflowInspector.tsx:188-197),现有的 expect(container.textContent).toContain('Verify the thing') 此后只能由 cockpit 内嵌的图来满足——实测 canvas 模式的 inspector 单独渲染时不含该字符串(textHasVerify 为 false、graphNodeVerify 为 false),所以请把这个字符串继续归因于图。
验收:两处都改之后,从测试 1 删掉 <SessionWorkflowInspector /> JSX 必须让它变红(expected null to be truthy);保留 canvasMode 而去掉 projection={shared} 必须让 :150 的 expect(counts.projections).toBe(0) 变红(读到 1,因为 SessionWorkflowInspector.tsx:60-65 的回退 useMemo 在提前返回之前就会构建一份)。把 SessionWorkflowInspector.tsx:188 的 if (canvasMode) 改成 if (false) 必须让新加的 canvas-detail 断言失败——注意它同时会让既有的 App.test.tsx:9661 失败。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| // The cockpit (with its embedded graph) and the inspector rendered from | ||
| // the shared projection without re-deriving it or its task index. | ||
| expect(counts.projections).toBe(0); |
There was a problem hiding this comment.
[Suggestion] Every assertion in the suite is a build count read once after a single mount, so all of them can only fail on OVER-derivation; the freshness half of the sharing contract — a surface picking up a rebuilt projection — is asserted nowhere in the package, and mount() drops the root so no test in this file can express a second pass at all. This PR created that exposure: PlanExecutionView.tsx:277 narrowed from [taskIndex, todos, tools] to [projection, todos], so freshness of node data-status, the attention count and the progress bar now rides entirely on the identity of an object built in App.tsx, three files away — the diff's own premise at :214-216 says so.
Drop one token out of the new adopting memo at PlanExecutionView.tsx:202-206 — deps [sharedProjection, tasks, todos, tools] becoming [tasks, todos, tools] — and App keeps handing down the same projection object after a tool call turns failed, so the graph memo never re-runs and node data-status, the attention count and the progress bar freeze while the transcript keeps streaming. The whole package stays green: all eight relevant suites pass and nothing catches a frozen graph. This is a one-token narrowing of a dep list this diff wrote, of the same class as the narrowing the diff made one line below at :277, so it is a defect in the diff's own new surface rather than a speculative future refactor. It is also NOT the same gap as R1-14: a second render pass that varies an unrelated host prop and asserts the counters unchanged — R1-14's witnessed fix — is green on both the intact and the frozen arm, because staleness leaves the counters unchanged too. R1-14 covers over-derivation, this covers under-derivation, and no single test in the package covers both.
Witness:
M2 (deps narrowed to [tasks, todos, tools] at PlanExecutionView.tsx:202-206): all eight relevant suites pass — session-workflow-surfaces.test.tsx 3, PlanExecutionView.test.tsx 30, PlanExecutionView.derivation.test.tsx 2, SessionWorkflowCockpit.test.tsx 2, SessionWorkflowInspector.test.tsx 2, session-workflow-model.test.ts 8, .index.test.ts 1 — and only the freshness probe fails: 'P2 data-status BEFORE: running AFTER: running — AssertionError: expected \'running\' to be \'in_progress\''. Full package under M2: 'Test Files 2 failed | 280 passed (282)' / 'Tests 18 failed | 6351 passed (6369)', the 2 files being build-artifact.test.ts (17, harness) and the probe. Flip: INTACT 'P2 data-status BEFORE: running AFTER: in_progress -> 2 passed'. Distinctness from R1-14 settled empirically: the R1-14-style second pass reads 'P1 data-status after second pass: running (counts 0/0)' green on BOTH arms, including the arm where the graph is demonstrably frozen. Note the reporter's originally named mutant (a todos-identity cache in buildSessionWorkflowProjection) IS caught, but incidentally — it fails :184 and :207 via a module-level cache leaking across tests, while test 1, the one that models App handing a projection down, passed under it.
Have mount() return { container, root } and add a fourth test: mount the cockpit and inspector with projection A built from (todos, tools, tasks); build B from (todos, toolsFailed, tasks) reusing the SAME todos array identity with only the tool status changed; root.render again with projection={B}; assert a projection-derived DOM value moved (the build node's data-status, or the inspector's summary count) AND that counts.projections and counts.indexBuilds are still 0 — pinning freshness and non-rebuild in one pass. Per R1-18, decide which inspector branch the fourth test models, since production renders the canvas branch beside the cockpit.
Constraint the fix must not violate: PlanExecutionView.tsx:277 is '}, [projection, todos]);' and :836 is 'const state = statesByTodo.get(todo.id)!;' — the second-render fixture must keep the new projection consistent with the todos array it renders against (every todo.id present in projection.states), or the graph throws a TypeError before the new assertion runs. Changing only the tool status and reusing the same todos array satisfies both: the memo re-runs on the new projection identity and states still covers all three ids.
Acceptance: The new test must go red when the handed-down projection goes stale. Mutation: drop sharedProjection from the dep list at PlanExecutionView.tsx:202-206. Under that mutant the three existing tests stay green (:149-150 still read 0/0, :183-184 and :206-207 still read 1/1) while the new freshness assertion fails. Verified: the probe passes on intact source and fails under the mutant.
中文说明
套件里每条断言都是在单次挂载之后读一次的构建计数,所以它们全都只能在「推导过多」时失败;共享契约的新鲜度那一半——某个 surface 拿到一份被重建过的 projection——在整个包里没有任何断言,而且 mount() 丢掉了 root,所以本文件里的测试连「第二次渲染」都无法表达。
这个暴露面是本 PR 造成的:PlanExecutionView.tsx:277 的依赖从 [taskIndex, todos, tools] 收窄为 [projection, todos],于是节点 data-status、attention 计数和进度条的新鲜度完全取决于一个在三个文件之外的 App.tsx 里构建的对象的 identity——diff 自己在 :214-216 也写明了这个前提(「todos 由 useStableArray 提供稳定 identity,而 projection 会随 transcript 重建」)。
从 PlanExecutionView.tsx:202-206 这个新的采用 memo 里删掉一个 token——依赖从 [sharedProjection, tasks, todos, tools] 变成 [tasks, todos, tools]——那么当某个工具调用转为 failed 之后,App 仍会把同一个 projection 对象递下来,图的 memo 永不重跑,节点 data-status、attention 计数与进度条就在 transcript 持续流式更新时冻结。整个包保持绿色:八个相关套件全过,没有任何东西能抓到一张冻结的图。这是对本 diff 自己写下的依赖列表做一个 token 的收窄,与 diff 在下面一行 :277 所做的收窄同类,所以它是这个 diff 新引入面上的缺陷,而不是对未来重构的猜测。
它也与 R1-14 不是同一个缺口:R1-14 的验收修复——再渲染一次、只改一个无关的宿主 prop、断言计数不变——在原状与冻结两种情况下都是绿的,因为「变陈旧」同样不会改变计数。R1-14 覆盖推导过多,本条覆盖推导过少,而包里没有任何单个测试同时覆盖两者。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:让 mount() 返回 { container, root } 并新增第四个测试:先用由 (todos, tools, tasks) 构建的 projection A 挂载 cockpit 与 inspector;再用 (todos, toolsFailed, tasks) 构建 B——复用同一个 todos 数组 identity,只改工具状态;带 projection={B} 再次 root.render;断言某个由 projection 派生的 DOM 值发生了变化(build 节点的 data-status,或 inspector 的摘要计数),并且 counts.projections 与 counts.indexBuilds 仍为 0——一次同时钉住新鲜度与不重复推导。按 R1-18,请决定第四个测试要建模 inspector 的哪个分支,因为生产环境在 cockpit 旁边渲染的是 canvas 分支。
约束:PlanExecutionView.tsx:277 是 }, [projection, todos]);,:836 是 const state = statesByTodo.get(todo.id)!;——第二次渲染的 fixture 必须让新 projection 与它所渲染的 todos 数组保持一致(每个 todo.id 都存在于 projection.states 中),否则图会在新断言运行之前抛出 TypeError。只改工具状态并复用同一个 todos 数组即可同时满足两点:memo 会因新的 projection identity 重跑,而 states 仍覆盖全部三个 id。
验收:新测试必须在「递下来的 projection 变陈旧」时变红。变异:把 PlanExecutionView.tsx:202-206 依赖列表里的 sharedProjection 删掉。在该变异下三个既有测试保持绿色(:149-150 仍读 0/0,:183-184 与 :206-207 仍读 1/1),只有新的新鲜度断言失败。已实测:该探针在原状代码上通过、在变异下失败。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| // One projection per render: the cockpit derives it and the embedded | ||
| // graph reuses it — the graph used to rebuild its own grouping, node | ||
| // states and counts from the raw props. One task index per projection. | ||
| expect(counts.projections).toBe(1); |
There was a problem hiding this comment.
[Suggestion] Every counter in the suite is read after exactly one render pass, so the "one projection per render" property the header claims to pin is only measured per mount — a surface that rebuilds on every re-render scores identically to a memoized one, and no test in the repo closes the gap because mount() calls root.render once and returns only the container, discarding the root.
Replace the useMemo at SessionWorkflowCockpit.tsx:53-57 (or SessionWorkflowInspector.tsx:60-64, or PlanExecutionView.tsx:203-206) with the bare expression sharedProjection ?? buildSessionWorkflowProjection(todos, tools, tasks), or widen its dep list with a value that changes each render, and the surface re-runs the whole derivation — createTaskExecutionIndex over the task list, getPlanNodeStateFromIndex per todo, dependentsByTodo, linkAgentTools, the activity sort — on every render instead of once per prop change, which is the re-derivation class #10865 was filed about. All three tests stay green: no test renders a second time, no event is dispatched, and onSelectedTodoIdChange / onBackToChat / onOpenSubagent are bare vi.fn()s with no state behind them, so nothing can drive a second pass. Nothing else in the repo closes it: PlanExecutionView.test.tsx has 0 vi.mock and 24 root.render calls, and session-workflow-model.index.test.ts makes one direct call and asserts once. Scope limit: with a shared projection present the ?? short-circuits, so the cost lands where a mounted surface has no shared projection — the TasksStatusMessage.tsx:824/:872 fallbacks, whose host re-renders on a 3-second interval.
Witness:
Flip pair, second render pass varying only sessionName (not in the memo dep list [sharedProjection, tasks, todos, tools]). INTACT: cockpit, inspector and graph each {"afterFirst":{"projections":1,"indexBuilds":1},"afterSecond":{"projections":1,"indexBuilds":1}} -> 6/6 green. MUTANT SessionWorkflowCockpit.tsx:53-57 useMemo -> bare ?? expression: {"afterFirst":{"projections":1,"indexBuilds":1},"afterSecond":{"projections":2,"indexBuilds":2}} -> 'AssertionError: expected 1 to be +0', while the SHIPPED session-workflow-surfaces.test.tsx on the same mutated tree reports 'Tests 3 passed (3)'.
Have mount() return { container, root } and add a second render pass to tests 2 and 3 — act(() => root.render(<SessionWorkflowCockpit … sessionName="second render" />)) — changing only a prop the memo does not depend on, then re-assert expect(counts.projections).toBe(1) and expect(counts.indexBuilds).toBe(1). Optionally add a fourth case mounting PlanExecutionView with no projection prop, re-rendered the same way, so the one production-live fallback path is counted too. Note this closes the over-derivation direction only; R1-21 is the under-derivation direction and needs a different assertion.
Constraint the fix must not violate: SessionWorkflowCockpit.tsx:56 is [sharedProjection, tasks, todos, tools]. The second render must keep those four identities unchanged and vary only an unrelated prop, because a freshly allocated tasks array — what the real standalone host passes at TasksStatusMessage.tsx:827 — legitimately invalidates the memo, so the count would read 2 with the memo intact and the assertion could no longer distinguish memoized from unmemoized.
Acceptance: The new second-render assertions. Mutation proof: with the useMemo at SessionWorkflowCockpit.tsx:53-57 replaced by the bare expression, test 2's counts.projections reads 2 after the re-render and expect(counts.projections).toBe(1) goes red (same for SessionWorkflowInspector.tsx:60-64 in test 3); restoring the memo returns both to 1.
中文说明
套件里每个计数器都只在恰好一次渲染之后读取,所以头注释声称要钉住的「每次渲染一份 projection」这个性质,实际只按每次挂载度量——一个在每次重渲染都重建的 surface 与一个已 memo 化的 surface 得分完全相同,而仓库里没有测试能补上这个缺口,因为 mount() 只调用一次 root.render 并只返回 container,把 root 丢弃了。
把 SessionWorkflowCockpit.tsx:53-57(或 SessionWorkflowInspector.tsx:60-64,或 PlanExecutionView.tsx:203-206)的 useMemo 换成裸表达式 sharedProjection ?? buildSessionWorkflowProjection(todos, tools, tasks),或者往它的依赖列表里加一个每次渲染都会变的值,该 surface 就会在每次渲染而不是每次 prop 变化时重跑整套推导——对任务列表跑 createTaskExecutionIndex、对每个 todo 跑 getPlanNodeStateFromIndex、dependentsByTodo、linkAgentTools、activity 排序——这正是 #10865 提出的那类重复推导。而三个测试全绿:没有测试渲染第二次,没有派发任何事件,onSelectedTodoIdChange / onBackToChat / onOpenSubagent 都是背后没有状态的裸 vi.fn(),所以没有任何东西能驱动第二次渲染。仓库其他地方也补不上:PlanExecutionView.test.tsx 有 0 处 vi.mock 却有 24 次 root.render,session-workflow-model.index.test.ts 只做一次直接调用并断言一次。
范围说明:有共享 projection 时 ?? 会短路,所以今天这个开销只落在「已挂载的 surface 没有共享 projection」的地方——即 TasksStatusMessage.tsx:824/:872 的回退路径,其宿主每 3 秒重渲染一次。
(上面的 Witness 是程序输出,按原样保留。)
修复方向:让 mount() 返回 { container, root },并给测试 2 与测试 3 各加一次渲染——act(() => root.render(<I18nProvider language="en"><SessionWorkflowCockpit … sessionName="second render" /></I18nProvider>)),只改一个 memo 不依赖的 prop——然后重新断言 expect(counts.projections).toBe(1) 与 expect(counts.indexBuilds).toBe(1)。可选再加第四个用例:挂载不带 projection 的 PlanExecutionView 并同样重渲染一次,以便把唯一在生产中真正走回退路径的情形也计入。注意这只关闭「推导过多」方向;R1-21 是「推导过少」方向,需要不同的断言。
约束:SessionWorkflowCockpit.tsx:56 是 [sharedProjection, tasks, todos, tools]。第二次渲染必须保持这四个 identity 不变、只改一个无关 prop,因为一个新分配的 tasks 数组——真实 standalone 宿主在 TasksStatusMessage.tsx:827 正是这么传的——会正当地让 memo 失效,那样即使 memo 完好计数也会读到 2,断言就无法区分「已 memo 化」与「未 memo 化」。
验收:新增的第二次渲染断言。变异证明:把 SessionWorkflowCockpit.tsx:53-57 的 useMemo 换成裸表达式后,测试 2 重渲染之后的 counts.projections 读到 2,expect(counts.projections).toBe(1) 变红(SessionWorkflowInspector.tsx:60-64 对测试 3 同理);恢复 memo 后两者都回到 1。
— qwen3.8-max via Qwen Code /review (v0.23.0)

qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
4 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- R1-1 counts.layers counter can never increment — already reported (comment 3947875795)
- R1-2 context provider rendered with no value prop — already reported (comment 3947875802)
- R1-4 new shared module has no collocated test — already reported (comment 3947875834)
- R1-8 production pass-down chain never observed by a test — already reported (comment 3947875862)
Not explored to full depth (tool budget reached): "agent test-matrix": none — all checks I planned completed; the only thing I could not do is execute the suites, because this worktree has no node_modules (disclosed per-finding a….
Not reviewed: reverse audit — did not converge within the reverse-audit round cap of 5.
Deferred under the convergence posture (round 2, not a blocker) — recorded, not requested in this round:
packages/web-shell/client/App.tsx:10696 — [probe] App projection memo ungated and can never holdpackages/web-shell/client/components/messages/PlanExecutionView.tsx:204 — [probe] Standalone fallback over-derives; memo can never holdpackages/web-shell/client/components/messages/PlanExecutionView.tsx:179 — [probe] New projection prop doc names the wrong ownerpackages/web-shell/client/components/workflow/session-workflow-surfaces.test.tsx:147 — [probe] indexBuilds counter blind to intra-module index rebuildspackages/web-shell/client/components/workflow/session-workflow-surfaces.test.tsx:91 — [probe] Suite cannot tell a threaded index from an empty one
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 4 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未探索到全部深度(达到工具调用预算):"agent test-matrix":none — all checks I planned completed; the only thing I could not do is execute the suites, because this worktree has no node_modules (disclosed per-finding a…。
未审查:反向审计——在 5 轮的反审轮数上限内未收敛。
收敛姿态下延后(第 2 轮,非阻断)——已记录,本轮不要求修改:共 5 条(原文未翻译,列表见上方英文部分)。
— qwen3.8-max via Qwen Code /review (v0.23.0)


Verification report — built and run locally against a real daemonI rebuilt this PR in an isolated worktree and drove it through a real Short answer: the change delivers what it says and is behaviourally invisible — but every one of the 11 open review findings reproduces, and the branch no longer merges cleanly. Rig — how the numbers below were produced
1. The perf claim holds, and the UI is unchanged
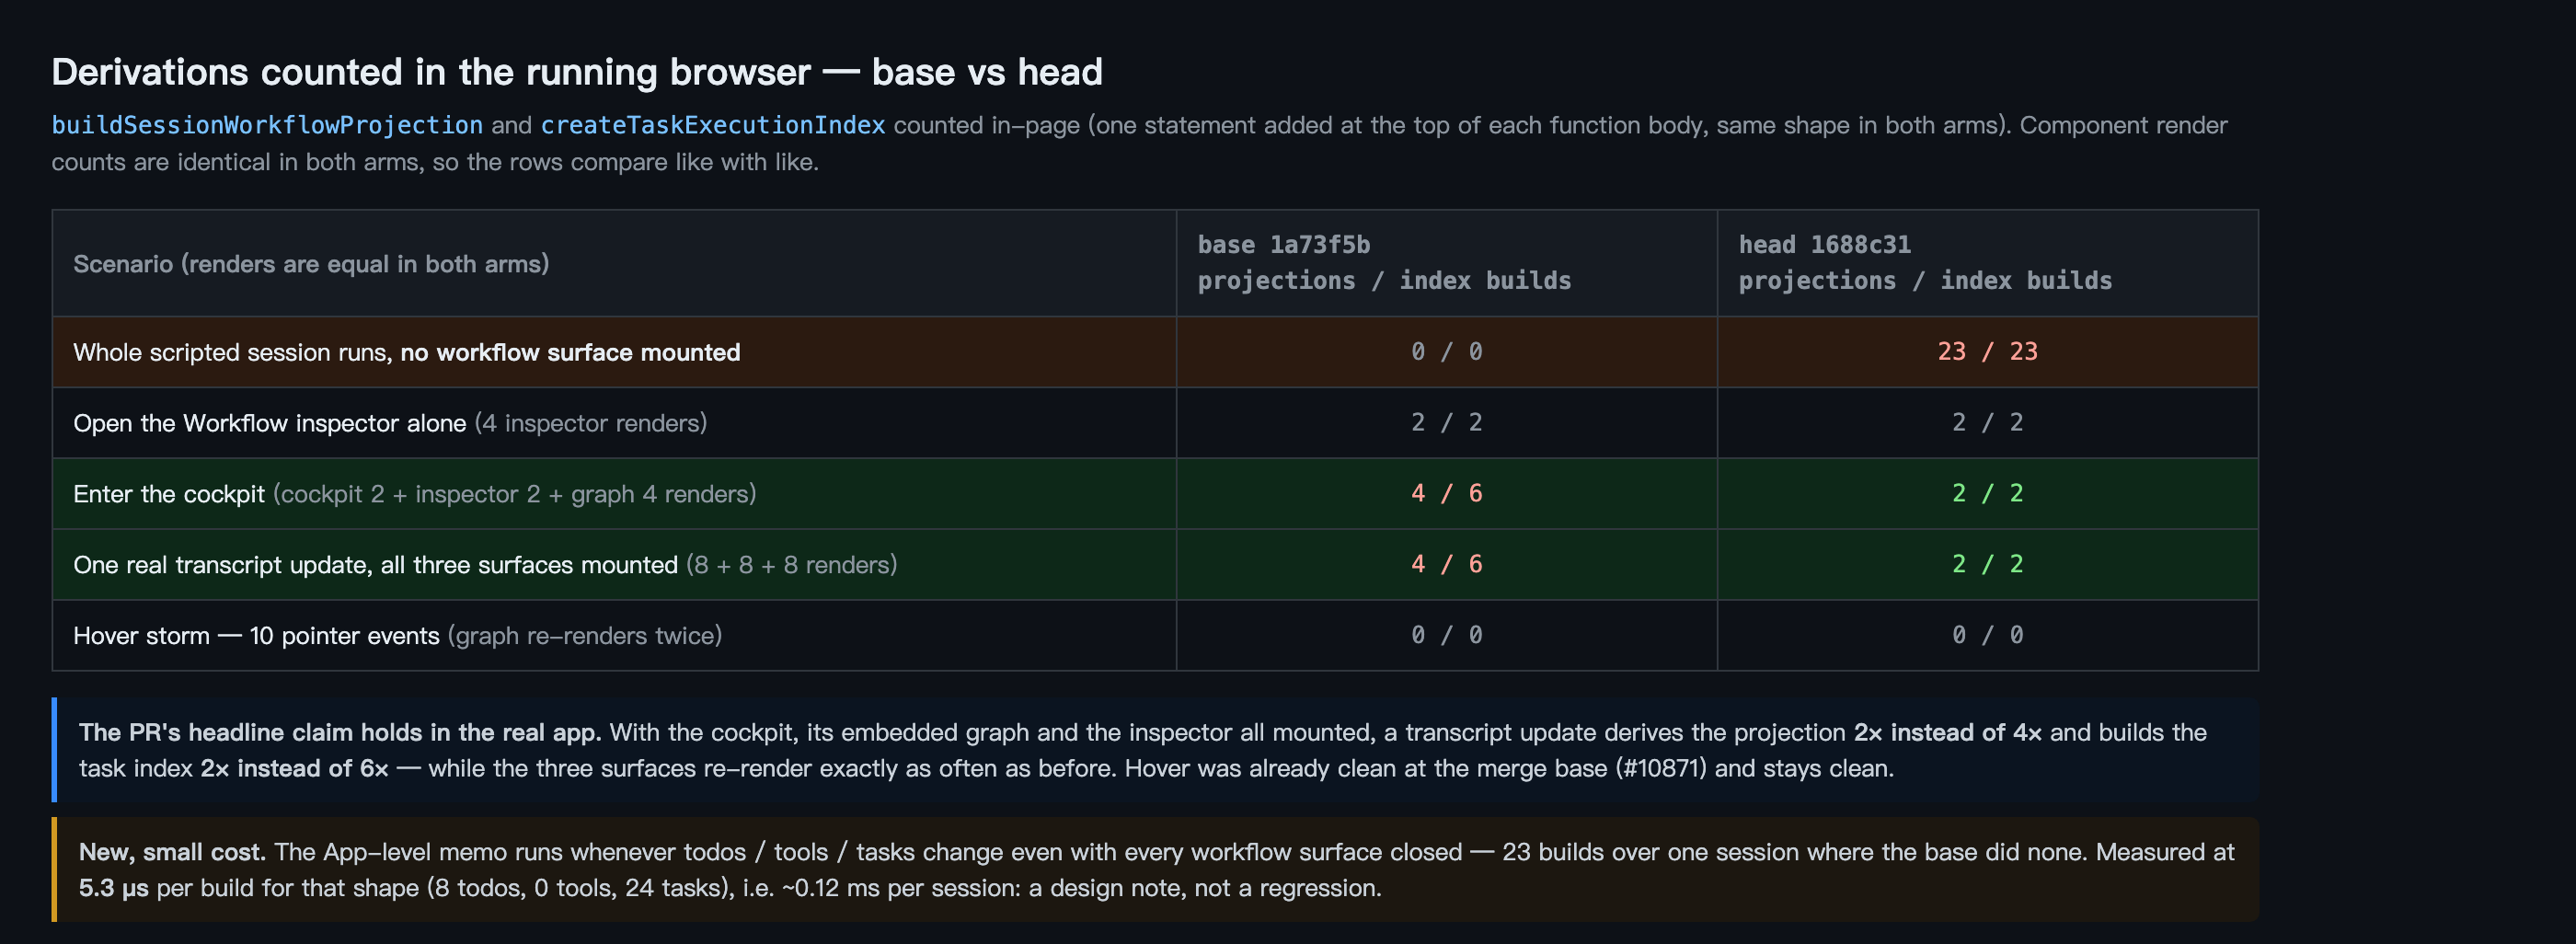
With the cockpit, its embedded graph and the inspector all mounted, a transcript update derives the projection 2× instead of 4× and builds the task index 2× instead of 6×, at identical render counts. Hover was already clean at the merge base (#10871) and stays clean. The two cockpits render the same values, so this is invisible to the user, as intended. Two smaller measurements worth recording:
2. Repo gates
The single failure is 3. The 11 open review findings — all reproduce
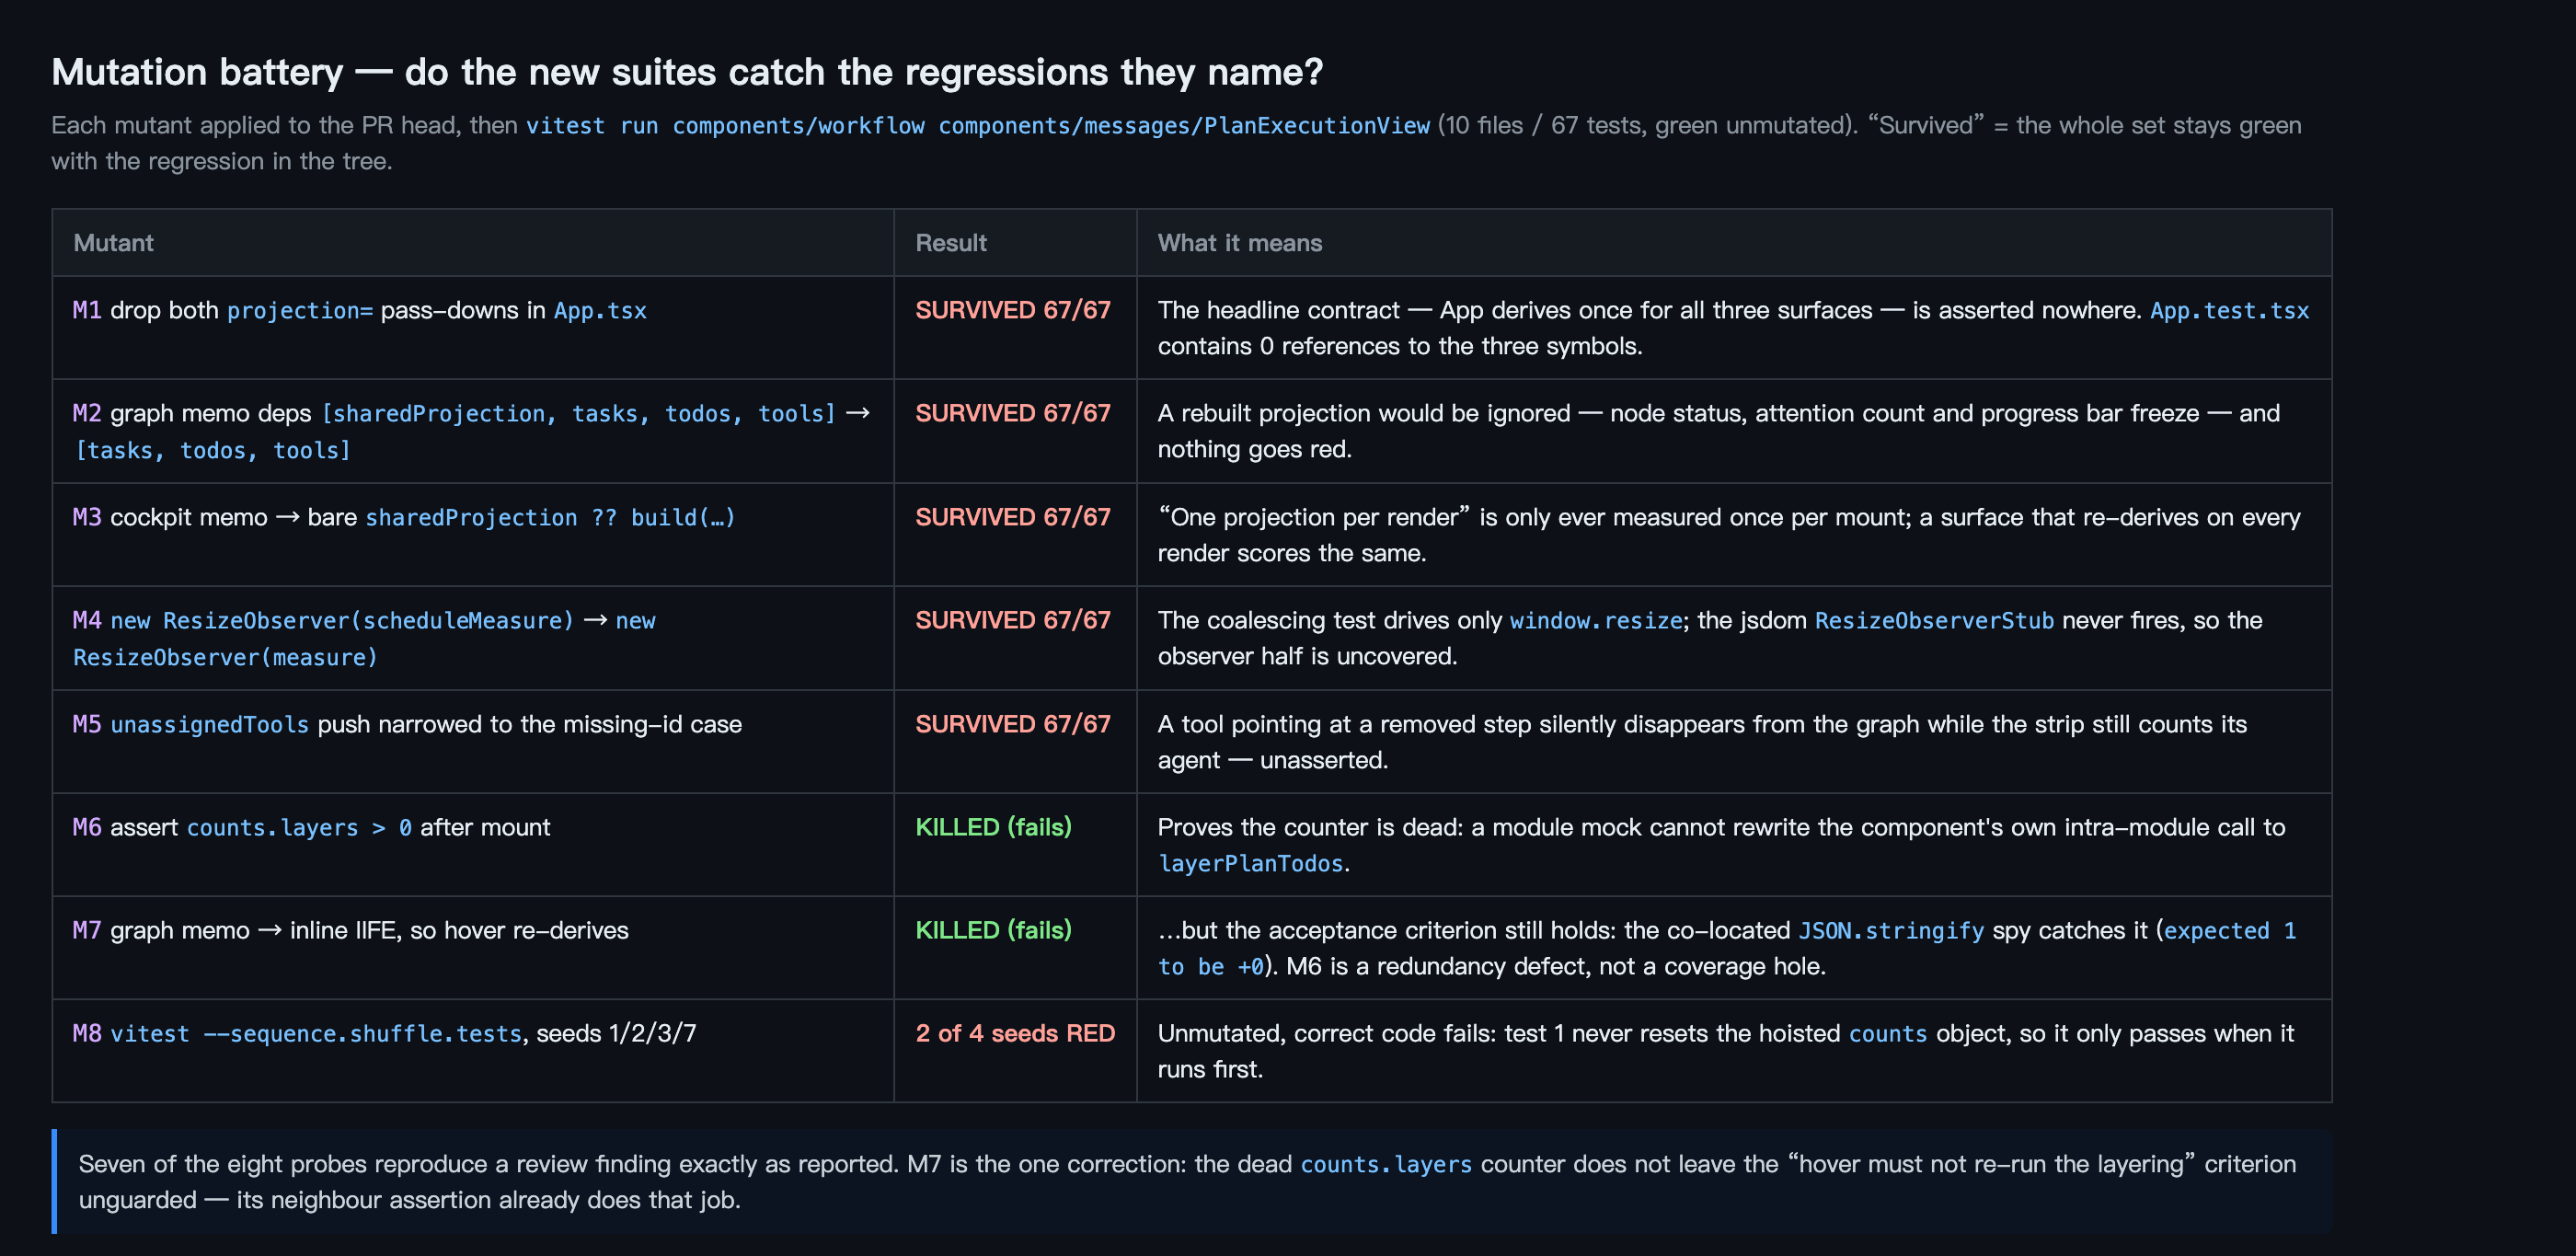
Each mutant was applied to the PR head and the suites that claim to cover the behaviour were run (
One correction to the review. The dead The other ten are real gaps in the new suites. The two I would want closed before merge are the App-level pass-down (the headline contract of the PR, currently asserted nowhere — an accidental revert of two lines in 4. The branch no longer merges
Everything above was measured on 5. Not coveredmacOS only (no Windows/Linux run); web-shell package suites only (no full-repo run, no Playwright e2e/visual suites); the post-rebase tree was not exercised. One thing a reviewer reproducing this will hit: after a full page reload the workflow surfaces show "This session has no structured workflow yet", because the replayed transcript does not carry VerdictThe perf work is correct, measurable in the real app, and user-invisible. I am happy to merge it once (a) it is rebased on 中文说明验证报告 —— 本地真实环境实测我在隔离 worktree 里重建了本 PR,并连同它的 merge base 一起,接到真实 结论:改动确实做到了它声称的事,且对用户不可见;但 11 条未解决的评审意见全部复现,并且分支已经无法干净合并。 装置
1. 性能收益成立,界面无变化
cockpit、内嵌图与 inspector 同时挂载时,一次 transcript 更新的 projection 推导从 4 次降到 2 次、task 索引构建从 6 次降到 2 次,而渲染次数完全一致。hover 在 merge base 上就已经干净(#10871),本 PR 保持干净。两臂 cockpit 读数一致,对用户不可见 —— 正是预期。 另外两个值得记录的测量:
2. 仓库门禁
唯一失败是 3. 11 条评审意见 —— 全部复现每个变异体都打在 PR head 上,然后跑声称覆盖该行为的套件(
对评审的一处更正。 死掉的 其余十条都是新套件的真实缺口。合并前我希望先补上的是两条:App 层的传递(这是本 PR 的核心契约,目前无处断言 —— 误删 4. 分支已无法干净合并
以上所有测量都是在提交时的 5. 未覆盖仅 macOS(未跑 Windows/Linux);仅 web-shell 包的套件(未跑全仓,未跑 Playwright e2e / 视觉套件);未验证 rebase 之后的树。另外,复现时会遇到一个现象:整页刷新后 workflow 面板显示 "This session has no structured workflow yet",因为回放的 transcript 不带 结论这项性能工作是正确的、在真实应用里可测量、且对用户不可见。满足两点后我乐意合并:(a) 基于 |
|
@qwen-code /resolve |

Resolve the PlanExecutionView.tsx conflict between the shared session-workflow projection refactor and main's dependency-navigation/gating work: derive stepNumberByTodo in the surviving graph-local memo, and restore the toolFormatting/toolClassification imports main's new node-face and subagent-details gating code needs.

|
Qwen Code resolved the merge conflicts and pushed the branch update. Root cause. Since the PR last merged main (base Semantic, not adjacent. Both sides changed the same memo. The resolution keeps the PR's projection structure and re-adds main's step-number derivation to the surviving graph-local memo: const { stepNumberByTodo, topology, … } = useMemo(() => {
const stepNumberByTodo = new Map(
todos.map((todo, index) => [todo.id, index + 1]),
);
const topology = …; // unchanged PR code
return { stepNumberByTodo, topology, … };
}, [projection, todos]);Imports: kept the PR's Load-bearing.
Not verified. No build/typecheck/tests run. Two non-conflicted dependencies for CI: (1) main's 中文说明根因:自 PR 上次合并 main(基点 语义冲突:解决保留 PR 的 projection 结构,把 main 的编号派生放回幸存的图形局部 memo(见上方代码)。导入同时保留两侧:PR 的 关键约束: 未验证:未运行构建/类型检查/测试。两处交由 CI:① main 的 |

Verification report, round 2 — the merged head
|
| Scenario | Surface renders cockpit / inspector / graph |
base e5969d6 |
head 6c44841 |
|---|---|---|---|
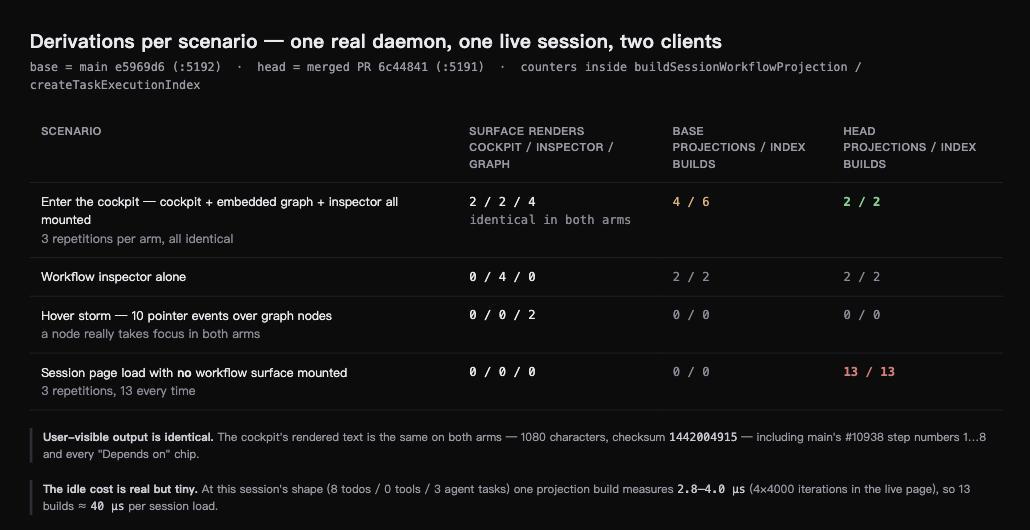
| Enter the cockpit — cockpit, its embedded graph and the inspector all mounted (3 repetitions per arm) | 2 / 2 / 4 — identical in both arms | 4 projections / 6 index builds | 2 / 2 |
| Workflow inspector alone | 0 / 4 / 0 | 2 / 2 | 2 / 2 |
| Hover storm, 10 pointer events over graph nodes | 0 / 0 / 2 | 0 / 0 | 0 / 0 |
| Session page load with no workflow surface mounted (3 repetitions) | 0 / 0 / 0 | 0 / 0 | 13 / 13 |
With all three surfaces mounted, the merged head derives the projection 2× instead of 4× and builds the task index 2× instead of 6×, at identical render counts — the same result my first report measured before the merge. Hover was already clean at the base and stays clean.
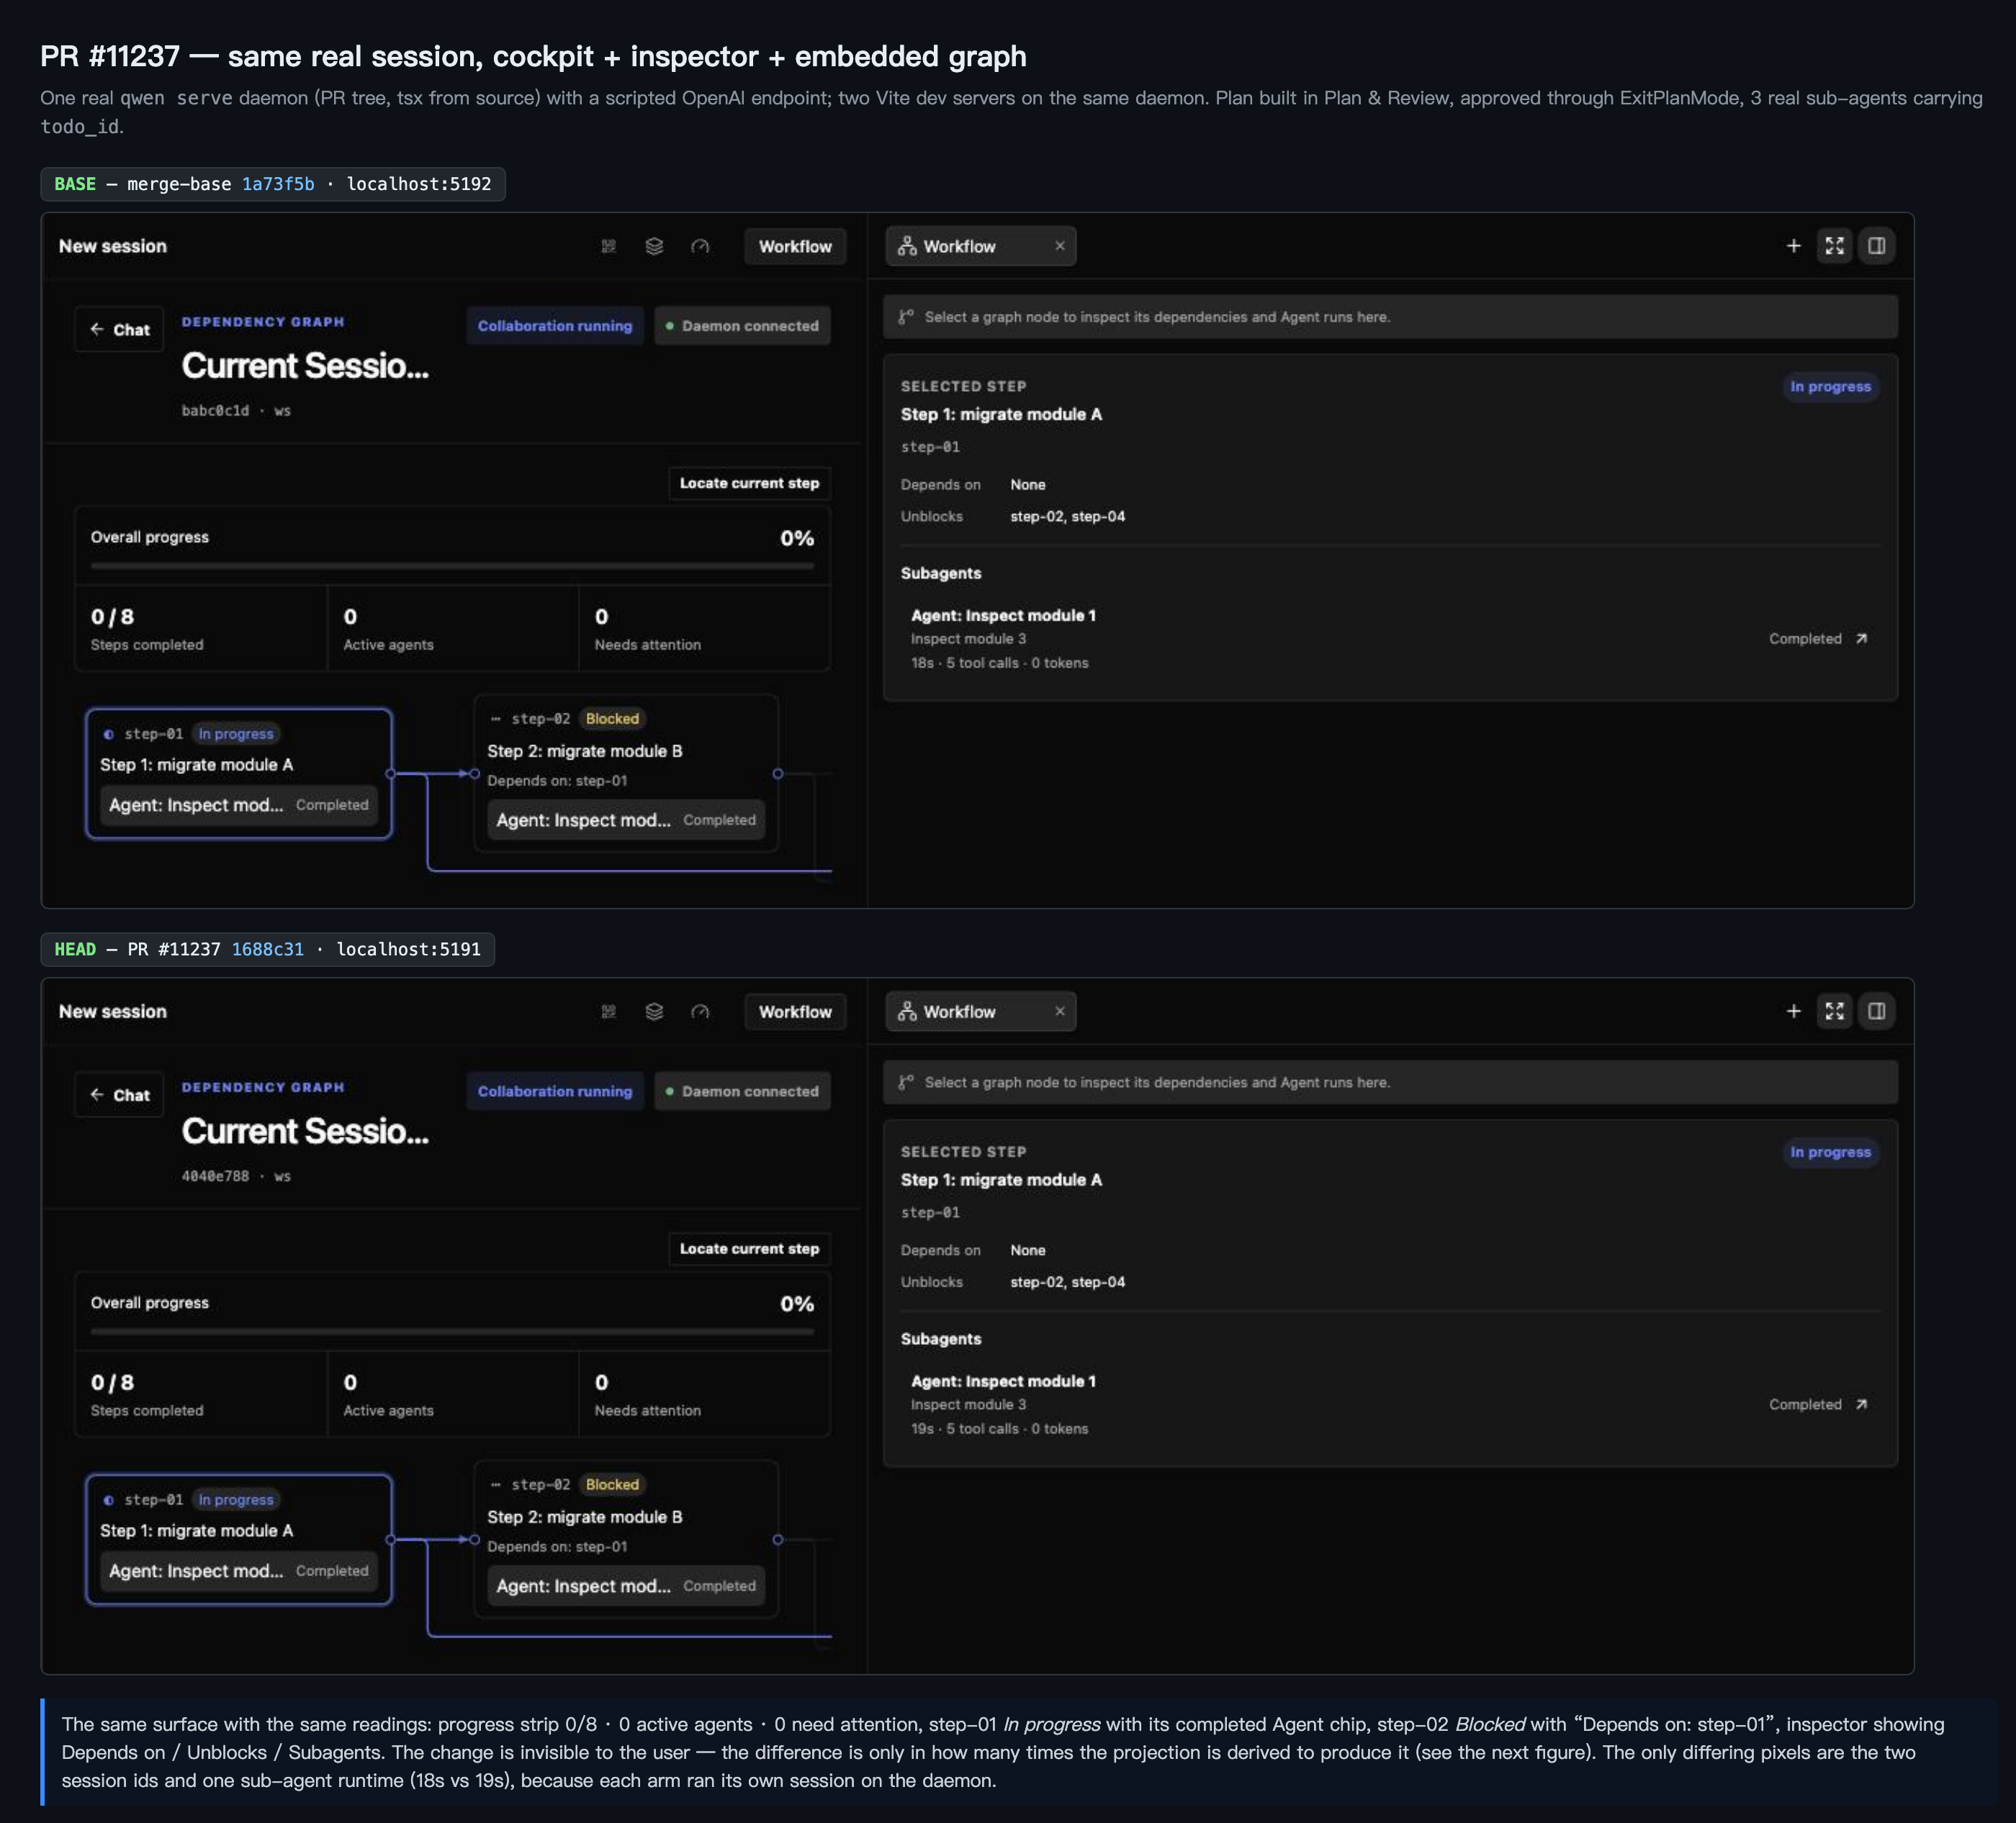
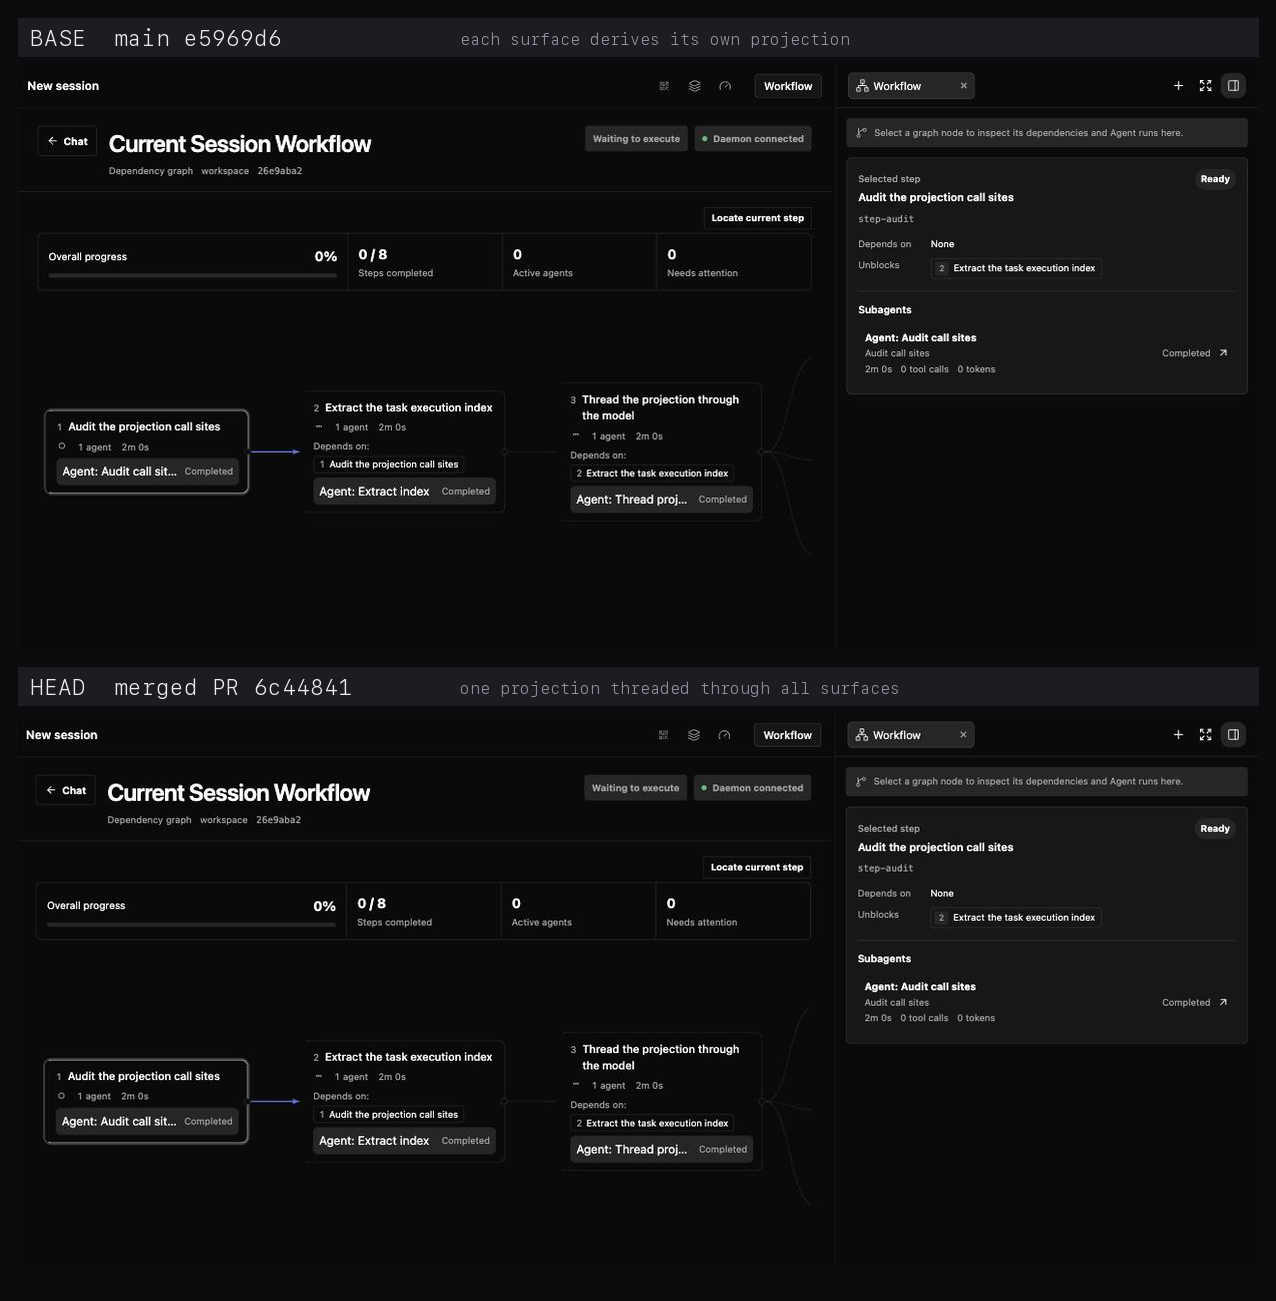
And it is invisible to the user. The cockpit's rendered text is the same on both arms — 1080 characters, checksum 1442004915 — including main's step numbers 1…8 and every "Depends on" chip. The two screenshots above are the same session, side by side.
The one real cost is unchanged and still small: the App-level memo runs on every todos/tools/tasks change even with every workflow surface closed — 13 builds per session load where the base does none. At this session's shape (8 todos / 0 tools / 3 agent tasks) a build measures 2.8–4.0 µs (4×4000 iterations in the live page), so ~40 µs per load. A design note, not a regression.
3. Repo gates — the ones the resolve bot skipped
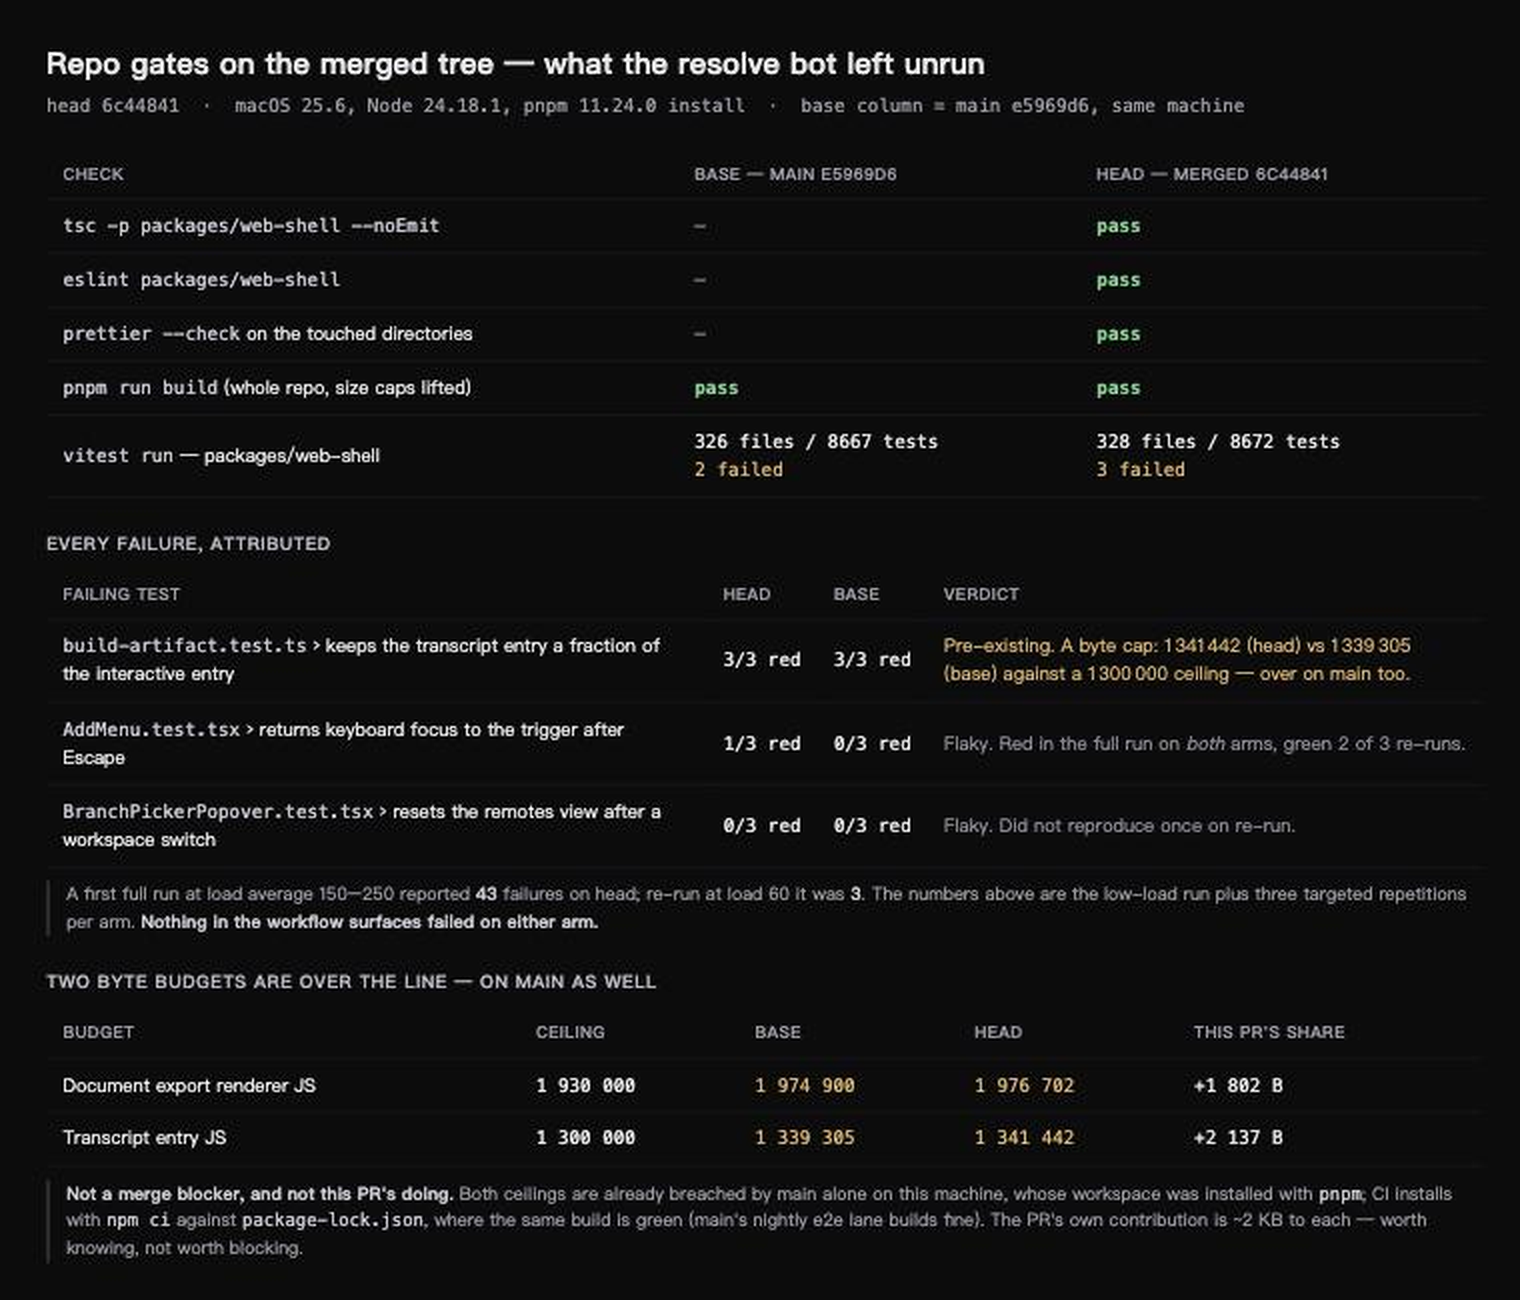
Typecheck, ESLint, Prettier and the whole-repo build all pass on the merged tree. The web-shell suite is 328 files / 8672 tests with 3 failures, and none of them belongs to this PR:
build-artifact.test.ts › keeps the transcript entry a fraction of the interactive entry— 3/3 red on both arms. It is a byte cap: 1 341 442 (head) vs 1 339 305 (base) against a 1 300 000 ceiling, so it is already over onmain.AddMenu.test.tsx › returns keyboard focus to the trigger after Escape— flaky; red in the full run on both arms, green in 2 of 3 re-runs.BranchPickerPopover.test.tsx › resets the remotes view after a workspace switch— flaky; did not reproduce once in three re-runs.
Worth recording about that first one: two byte budgets are breached on this machine — the document export renderer (1 976 702 vs a 1 930 000 cap) and the transcript entry above — and both are breached by main alone. My workspace was installed with pnpm; CI installs with npm ci against package-lock.json, where the same build is green (main's nightly e2e lane builds fine) and neither budget runs on pull requests. This PR's own share is +1 802 B and +2 137 B. Not a blocker and not this PR's doing — but if anyone tightens those caps later, this is the arithmetic.
One caveat on method: a first full run while this machine was at load average 150–250 reported 43 failures on head; re-run at load 60 it was 3. The numbers above are the low-load run plus three targeted repetitions per arm.
4. The two blocking review gaps are unchanged
Mutation applied to 6c44841 |
What it breaks for a user | Result |
|---|---|---|
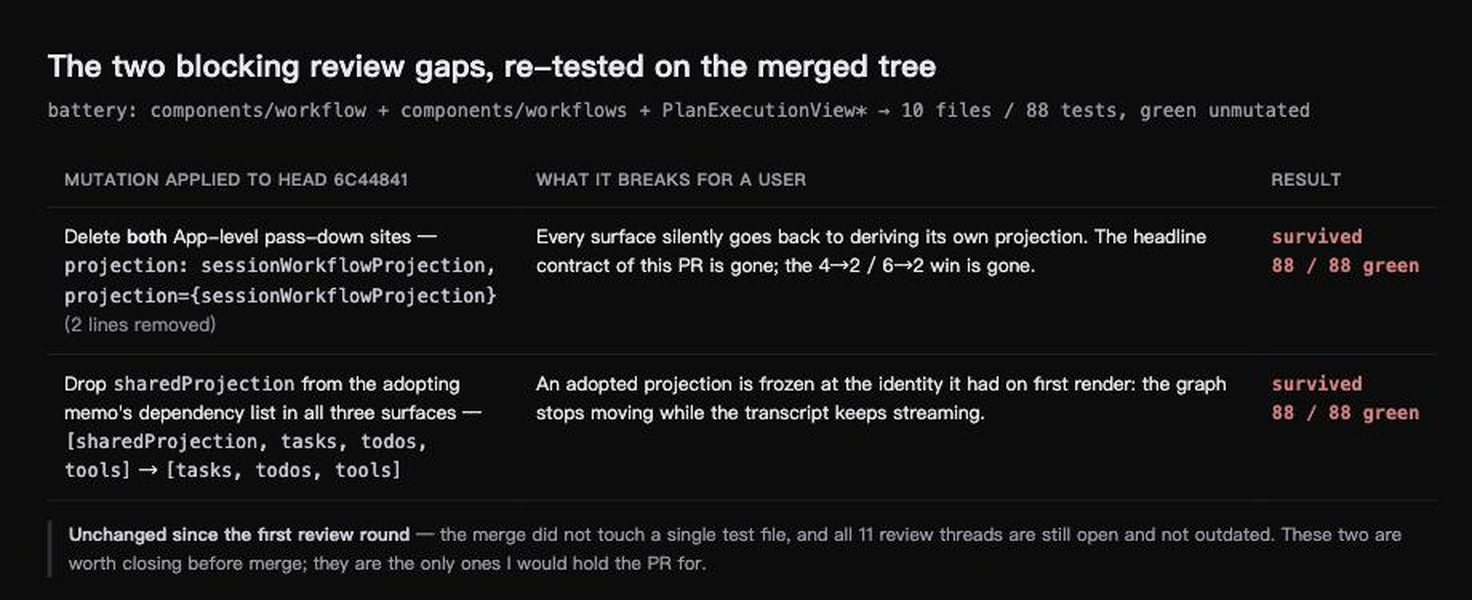
Delete both App-level pass-down sites (projection: sessionWorkflowProjection, and projection={sessionWorkflowProjection} — 2 lines) |
Every surface silently goes back to deriving its own projection; the headline contract of this PR is gone, and so is the 4→2 / 6→2 win | survived, 88/88 green |
Drop sharedProjection from the adopting memo's dependency list in all three surfaces |
An adopted projection freezes at the identity it had on first render: the graph stops moving while the transcript keeps streaming | survived, 88/88 green |
Battery: components/workflow + components/workflows + PlanExecutionView* → 10 files / 88 tests, green unmutated. This is the same result as round 1 — expected, because the merge did not touch a test file, and all 11 review threads are still open and not outdated.
5. Not covered
macOS only (no Windows or Linux run). web-shell package suites only — no Playwright e2e or visual suites, no full-repo vitest. This round re-tested the two findings I called blocking, not all eleven; the other nine anchor on test files the merge left byte-identical, so I take round 1's results as standing. One thing a reviewer reproducing this will notice: the inspector reports "0 active Agents" while three agent tasks are genuinely running — identical on both arms, unrelated to this PR.
Verdict
The merge is sound and I would not ask for it to be redone. Of the two things I asked for last time, (a) the rebase onto main with stepNumberByTodo folded in is done, and now verified; (b) real assertions for the App-level pass-down and for the adopting memo's freshness are still open. Close (b) and this is ready to merge from my side; the remaining findings are worth a follow-up sweep but should not hold it.
中文说明
验证报告 · 第二轮 —— 合并后的 head 6c4484138c
在我的第一轮报告之后,@qwen-code /resolve 把 main 合进本分支并推出了 6c44841,并明确写着 "未验证。 未运行构建 / 类型检查 / 测试。" 本轮就是把那棵合并后的树重新构建,再接回真实 qwen serve daemon + 真实浏览器,与它的 main 父提交并排跑,回答被留下的三个问题:这次冲突解决是否等价、性能收益在合并后是否还成立、仓库门禁是否通过。
结论:解决是正确的——我从两个方向以及运行中的应用里都做了核对;收益完整保留在 4→2 / 6→2,渲染次数一致、界面输出逐字节相同;类型检查、lint、格式化、构建与包内测试全部通过。上一轮我判为阻塞的两条评审缺口原样未动,因为这次合并没有改动任何一个测试文件。
装置
- 在合并后的 head
6c44841与它的main父提交e5969d6(即6c44841^2,同一棵树但不含本 PR)各检出 worktree,均用 pnpm 11.24.0 安装并完整构建。macOS 25.6、Node 24.18.1。 - 两臂共用一个真实 daemon(来自 head 树):
node scripts/dev.js serve --port 4180 --workspace <scratch>,隔离QWEN_HOME,experimental.sessionWorkflow: true、tools.todoWrite.enabled: true、Plan 模式。 - 模型用仓库自带的脚本化端点(
integration-tests/fake-openai-server.ts),会话完全确定:todo_write写入 8 步带blockedBy的计划 →exit_plan_mode→ 在浏览器里批准 → 派出 3 个带todo_id的真实后台子智能体,每个都被我从外部控制的闸门挂住。是真的 daemon agent task 和真的子进程,不是夹具。 - 两个 Vite dev server 接同一个 daemon —— head 在
:5191、base 在:5192,两臂只差被审查的客户端代码,读的是同一个会话。 - 计数:在
buildSessionWorkflowProjection、createTaskExecutionIndex以及三个 surface 组件的函数体首行各加一条自增语句,由页面读出。两臂形状完全一致,跑门禁前已全部回滚(git status干净)。 - 下面所有对照都是在会话冻结后(三个子智能体均已结束)采集的,两臂看到的数据完全相同。
1. 冲突解决是等价的 —— 从两个方向核对
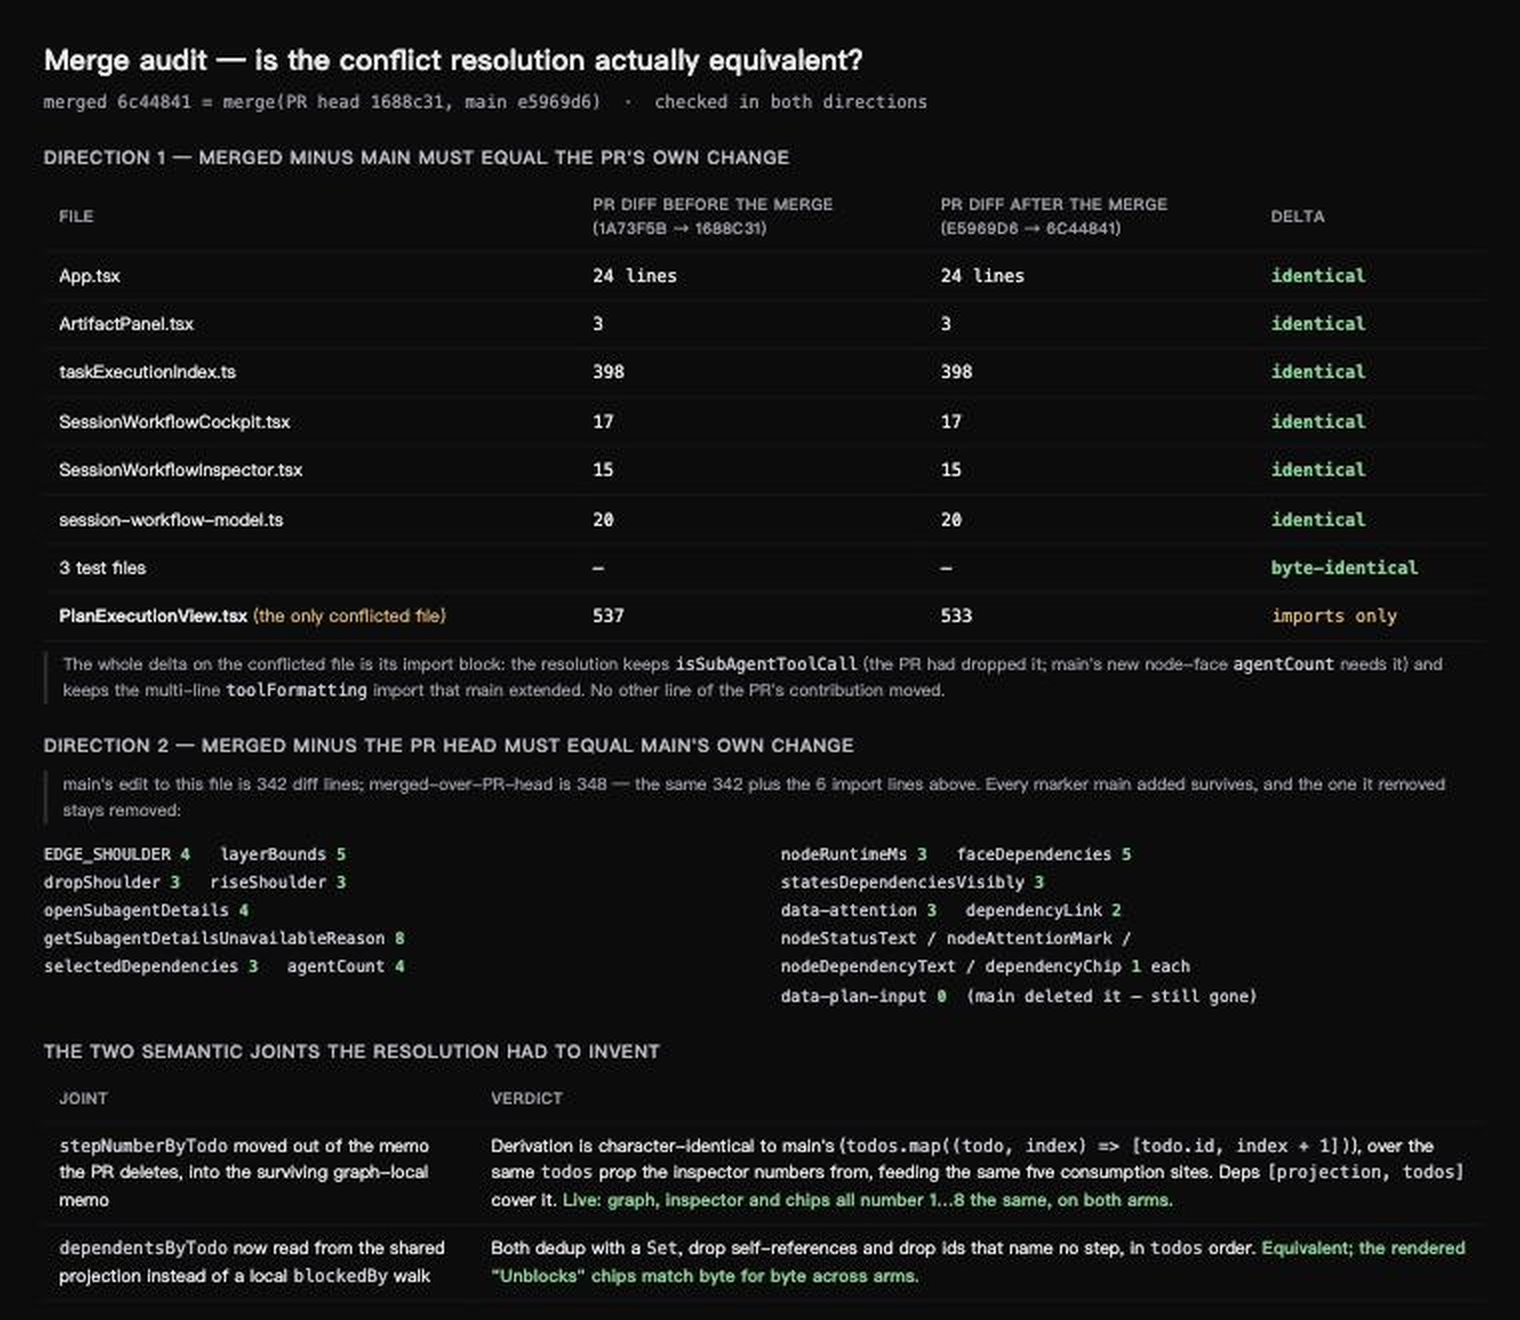
合并结果 − main 在十个文件中的九个上与 PR 自身的改动逐字节相同,三个测试文件全部在内。唯一冲突的 PlanExecutionView.tsx 上,全部差异就是它的 import 块:解决保留了 isSubAgentToolCall(重构曾删掉它,但 main 新的节点面 agentCount 需要),并保留了 main 扩充过的多行 toolFormatting 导入。反方向看,合并结果 − PR head 等于 main 自己那 342 行改动加上同样这几行 import。main 在 #10938 与 #11434 中新增的标记全部存活,而它删掉的 data-plan-input 依然不存在。
需要「发明」的两处语义接缝都成立:
stepNumberByTodo的推导与 main 的逐字符相同,作用在 inspector 用来编号的同一个todosprop 上,供给同样的五个消费点,且todos在幸存 memo 的依赖列表里。feat(web-shell): make Session Workflow dependencies navigable and quiet its chrome #10938 要求「图、inspector、chips 对同一步给出相同编号」的约束得以保留 —— 而且我是在运行中的应用里核对的,不只是读代码。dependentsByTodo改为从共享 projection 读取,而不再做一次局部的blockedBy遍历。两者都用Set去重、丢弃自引用、丢弃指不到任何步骤的 id,且顺序都按todos。
2. 在运行中的应用里:收益完整,界面无变化
| 场景 | surface 渲染次数 cockpit / inspector / graph |
base e5969d6 |
head 6c44841 |
|---|---|---|---|
| 进入 cockpit —— cockpit、内嵌图与 inspector 全部挂载(每臂 3 次重复) | 2 / 2 / 4 —— 两臂完全相同 | 4 次 projection / 6 次索引构建 | 2 / 2 |
| 只打开 Workflow inspector | 0 / 4 / 0 | 2 / 2 | 2 / 2 |
| Hover 风暴,10 次指针事件划过图节点 | 0 / 0 / 2 | 0 / 0 | 0 / 0 |
| 会话页加载,未挂载任何 workflow 界面(3 次重复) | 0 / 0 / 0 | 0 / 0 | 13 / 13 |
三个界面同时挂载时,合并后的 head 把 projection 推导从 4 次降到 2 次、task 索引构建从 6 次降到 2 次,而渲染次数完全一致 —— 与我第一轮在合并前测到的结果相同。hover 在 base 上本就干净,合并后保持干净。
而且对用户不可见。 cockpit 渲染出的文本两臂完全相同 —— 1080 个字符、校验和 1442004915 —— 包含 main 的 1…8 步骤编号和每一个「Depends on」chip。上面两张截图就是同一个会话的并排对比。
唯一的真实代价未变且仍然很小:App 层的 memo 在 todos/tools/tasks 变化时都会跑,即使所有 workflow 界面都关着 —— 一次会话加载跑 13 次,base 是 0 次。在本会话的形状下(8 todos / 0 工具 / 3 个 agent task)单次耗时 2.8–4.0 µs(页面内 4×4000 次迭代实测),整次加载约 40 µs。属于设计备注,不是回归。
3. 仓库门禁 —— 机器人跳过的那些
类型检查、ESLint、Prettier 与全仓构建在合并后的树上全部通过。web-shell 套件 328 文件 / 8672 用例,3 条失败,没有一条属于本 PR:
build-artifact.test.ts › keeps the transcript entry a fraction of the interactive entry—— 两臂都是 3/3 红。它是一个字节上限:1 341 442(head)对 1 339 305(base),上限 1 300 000,也就是说main本身就已超标。AddMenu.test.tsx › returns keyboard focus to the trigger after Escape—— 抖动;全量跑时两臂都红,重跑 3 次里绿 2 次。BranchPickerPopover.test.tsx › resets the remotes view after a workspace switch—— 抖动;重跑 3 次一次都没复现。
关于第一条值得记录:本机上有两个字节预算被突破 —— 文档导出渲染器(1 976 702,上限 1 930 000)与上面那个 transcript 入口 —— 而且都是 main 自己就已突破。我的工作区是用 pnpm 安装的;CI 用 npm ci 配 package-lock.json,同一个构建在那边是绿的(main 的 nightly e2e 腿构建正常),而且这两个预算都不在 PR 门禁上。本 PR 自身的份额是 +1 802 B 与 +2 137 B。不构成阻塞、也不是本 PR 造成的 —— 但将来谁要收紧这两个上限,这就是账。
方法上的一个说明:第一次全量跑时本机负载 150–250,head 报了 43 条失败;负载降到 60 重跑只剩 3 条。上表用的是低负载那次,外加每臂三次定向重复。
4. 两条阻塞性评审缺口原样未动
打在 6c44841 上的变异 |
对用户意味着什么 | 结果 |
|---|---|---|
删掉 App 层两处传递(projection: sessionWorkflowProjection, 与 projection={sessionWorkflowProjection},共 2 行) |
每个界面都悄悄退回各自推导 projection;本 PR 的核心契约没了,4→2 / 6→2 的收益也没了 | 存活,88/88 全绿 |
从三个界面的采纳 memo 依赖列表里去掉 sharedProjection |
被采纳的 projection 冻结在首次渲染时的身份:transcript 还在流,图却不动了 | 存活,88/88 全绿 |
变异靶场:components/workflow + components/workflows + PlanExecutionView*,共 10 文件 / 88 用例,未变异时全绿。结果与第一轮一致 —— 这是预期的,因为合并没有动任何测试文件,且 11 条评审 thread 至今全部未解决、也未过期。
5. 未覆盖
仅 macOS(未跑 Windows / Linux)。仅 web-shell 包内套件 —— 未跑 Playwright e2e 与视觉套件,未跑全仓 vitest。本轮只复测了我判为阻塞的那两条,而非全部十一条;其余九条锚定的测试文件在合并前后逐字节相同,因此沿用第一轮的结论。复现时会看到一个现象:三个 agent task 确实在运行时,inspector 却显示「0 active Agents」—— 两臂表现一致,与本 PR 无关。
结论
这次合并是稳的,我不会要求重做。上一轮我提的两点里,(a)「基于 main 合并并把 stepNumberByTodo 收进来」已完成,且本轮已验证;(b)「给 App 层传递与采纳 memo 的新鲜度补上真实断言」仍未完成。把 (b) 补上,从我这边就可以合并了;其余意见值得后续统一清理,但不必卡住本 PR。
|
Qwen Code review did not complete successfully. The review pipeline failed before a review could be posted. A transient error is retried automatically; if you are seeing this, retry with |


|
@qwen-code /triage |
|
Sandboxed verification: ❌ not passed — findings reported (agent verdict) - workflow run Ran the PR in an isolated, token-free container: A/B against the base build, mock-free harness assertions, targeted gates. Advisory evidence for human reviewers — not a review, an approval, or a CI check. Scripted assertions: 95 passed · 2 failed · 97 total Flakiness gate: ✅ 3 changed test file(s) x 5 identical rounds, no divergence 中文 — 判定:❌ 不通过 · 报告了发现(agent 判定)沙箱验证在隔离、无凭证的容器中执行了该 PR 的代码(与 base 构建 A/B 对照、无 mock harness 断言、定向门禁)。仅作为评审证据,不构成评审、批准或 CI 检查。 脚本断言:95 通过 · 2 失败 · 97 总计 抖动门:✅ 3 changed test file(s) x 5 identical rounds, no divergence Verification reportPR #11237 — deep verification reportVerdict: 中文摘要
Central claim and A/BCentral claim: one session-workflow projection per render, shared by the cockpit, the artifact-panel inspector and the graph embedded in the cockpit (issue #10865's remaining acceptance criterion). Secondary claims: (a) the extraction into Arms:
Witness: Other scenarios (same harness, both arms):
Cost in milliseconds (
Witness: Extraction is behaviour-preserving
Behavioural equivalence (the "invisible" claim)
Within head, standalone vs shared-projection renders are byte-identical for all 6 fixtures on both the graph and the inspector, and for the cockpit+inspector tree (15309 B vs 15309 B) — the "they cannot disagree" claim holds. Mutation matrixSuites collected per run: 11 files / 95 tests (the workflow + PlanExecutionView suites). Positive control M0 (off-by-one
The PR's own "sanity of the spies" claim (M1) is independently confirmed. Findings1. Duplicate todo ids change the graph's "Needs attention" count (1 → 2) — SuggestionThe PR states the change "is intended to be invisible" and asks reviewers to confirm the surfaces "read the same values as before". For a plan whose todo ids repeat, they do not.
Measured through the real components (cross-arm DOM diff): Reachable: Fixture that would pin it: the Minimal suggested fix (not applied — measured only as M8)Either dedupe when building 2.
|
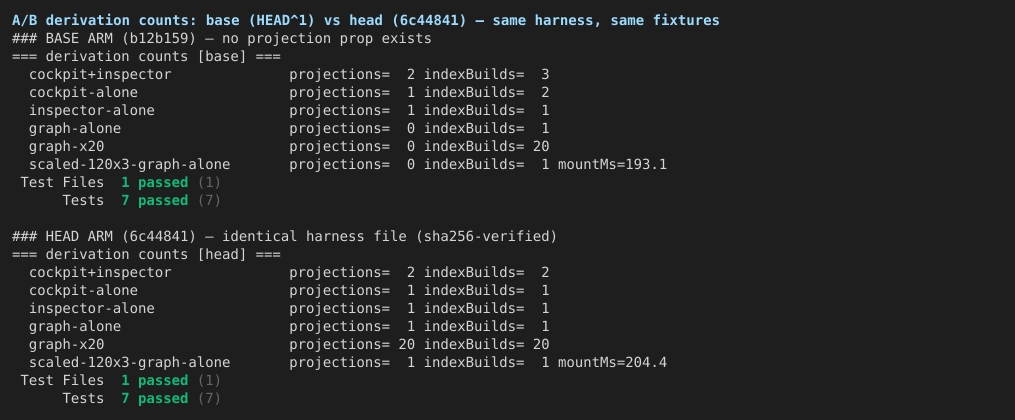
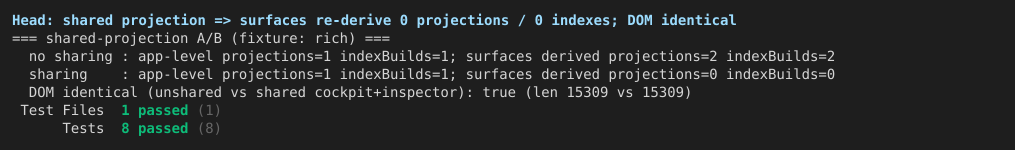
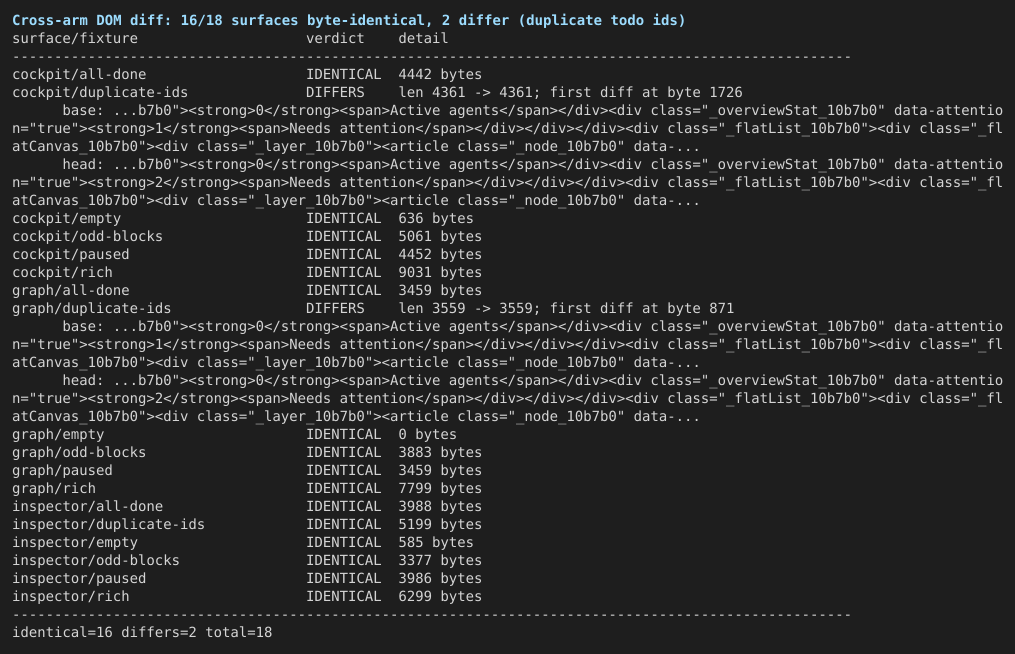
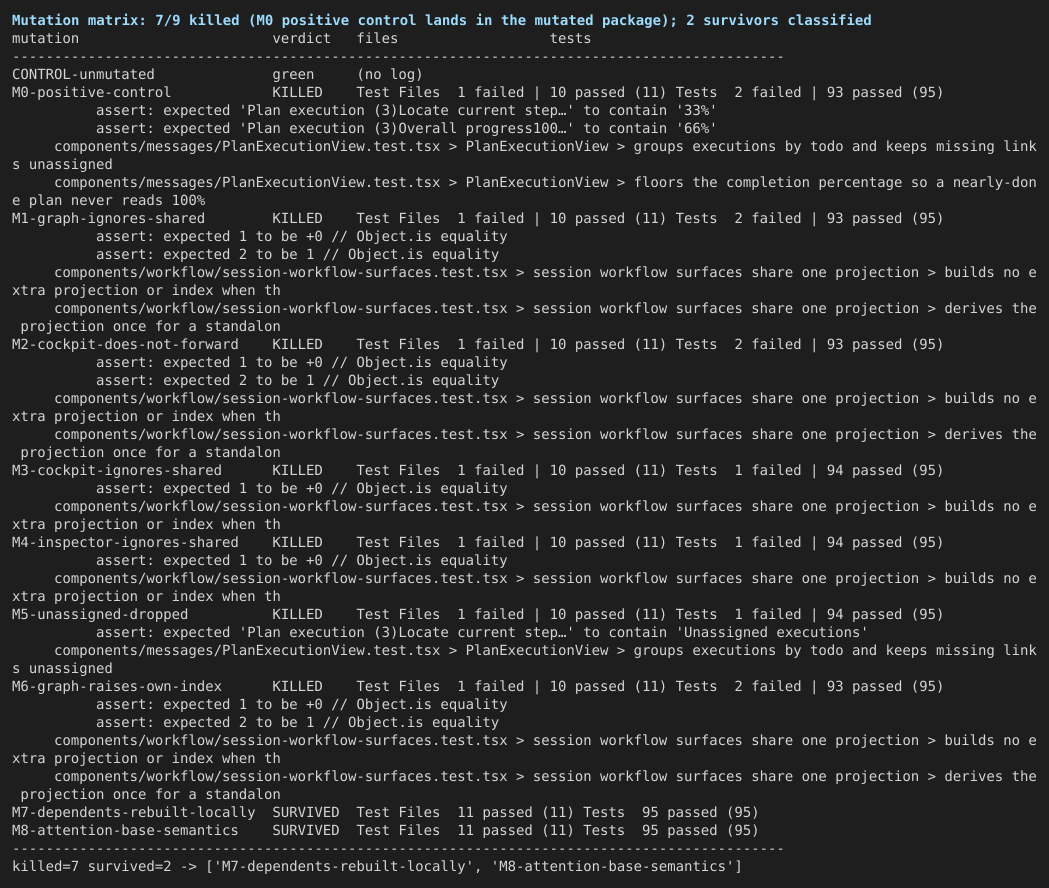
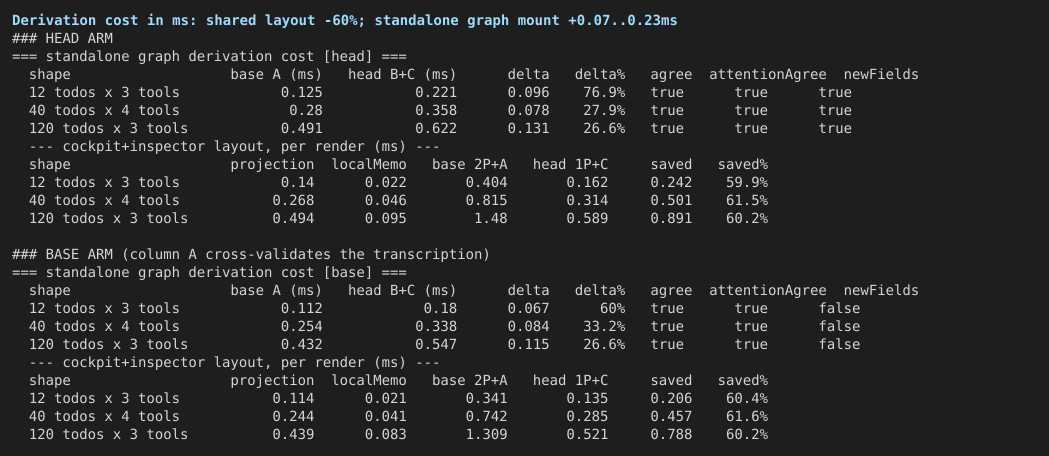
|
Re-ran the gate at Still missing: Why no new @now-ing — restructure the body and re-trigger
One substantive thing to fix alongside the body, so it doesn't cost another round — recorded here, not as a Stage 2 review, because this run stopped at the gate: the PR's headline contract has no test that fails when it's removed. Deleting both A maintainer call, not mine: @wenshao approved this head 22 s before triggering the run. Size (informational only): 1008 production lines / 393 test lines, which is past the 1000-line advisory — but most of it is relocation ( 中文说明在 仍缺失的小节: 为什么没有新的 @now-ing —— 按模板重组描述后再触发
一处建议与描述一起修的实质问题(记录在此,而非作为 Stage 2 审查,因为本次在门禁处就停了):本 PR 的核心契约没有任何测试能在它被移除时失败。删掉 这一条属于维护者的判断,不是我的:@wenshao 在触发本次运行前 22 秒批准了这个 head。 规模(仅供参考):生产代码 1008 行 / 测试 393 行,超过 1000 行的大 PR 提示线——但其中大部分是搬迁( — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
|
Triage re-run completed without a new review.
The stage comments above were updated with the latest result. View workflow run. 上方各阶段评论已更新为最新结果。查看工作流运行。 |

Independent verification at head
|
| graph used to compute | projection supplies | verdict |
|---|---|---|
todosById |
same new Map(todos.map(...)) |
identical |
toolsByTodo / unassigned |
same loop, !todoId || !todosById.has(todoId) ≡ !todoId || !knownIds.has(todoId) |
identical |
statesByTodo |
same getPlanNodeStateFromIndex(todo, todosById, toolsByTodo.get(id) ?? [], taskIndex) |
identical |
completedCount |
same filter(status === 'completed').length |
identical |
progressPercent |
same todos.length === 0 ? 0 : Math.floor(...) |
identical — Math.floor, not Math.round |
activeAgentCount |
activeAgents.length where activeAgents = getActiveAgentsFromIndex(tools, taskIndex) |
identical |
attentionCount |
attentionTodos.length where attentionTodos = todos.filter(t => states.get(t.id)?.attention) |
identical |
dependentsByTodo |
same new Set(blockedBy ?? []) walk with the same dependencyId === todo.id || !todosById.has(dependencyId) skip |
identical |
Two of these are worth calling out because they are the ones a refactor like this usually gets wrong. The Math.floor in progressPercent is load-bearing — it feeds aria-valuenow, and rounding would report 100% completion on a long plan while a step is still outstanding; it survives. And dependentsByTodo keeps the self-dependency and unknown-id filter, so the graph's downstream-step set is the same set of edges its topology already serialized.
The memo dependency list changed from [taskIndex, todos, tools] to [projection, todos], which is still correct: the projection is itself memoized on [sharedProjection, tasks, todos, tools] and carries taskIndex, so it changes whenever any of the old inputs did.
I also traced the new optional projection prop through every hop to make sure it is not a declared-but-never-forwarded switch. App puts it in the workflow object it hands ArtifactPanel; ArtifactPanel reaches <SessionWorkflowInspector {...workflow} /> by spread; SessionWorkflowCockpit passes its resolved projection into PlanExecutionView explicitly. All three surfaces really do receive the shared object.
3. Executed evidence
Built the head commit in an isolated worktree (npm run generate && npm run build, both exit 0) and ran the suites:
- The PR's three suites: 6/6 passed —
PlanExecutionView.derivation.test.tsx(2),session-workflow-surfaces.test.tsx(3),session-workflow-model.index.test.ts(1). - The whole
@qwen-code/web-shellsuite: 8671 passed / 1 failed of 8672 across 328 files, 259 s. - Real-Chromium Playwright arm on this PR's exact surface:
client/e2e/visuals/session-workflow.spec.ts— 2 passed (18.6 s), light and dark. That spec is the relevant one here because it does not just screenshot: it asserts the canvas renders 4 nodes and 3 edges, and then asserts the1m 14sruntime is visible both on the node face and in the inspector's agent row. That second pair is the tool-call ↔ task linkage, which is precisely what threading one sharedtaskIndexcould have broken silently while still drawing a plausible graph. Playwright started its own dev server (13[WebServer]lines) on a port no spec uses.
About the one failure, since a green claim that hides it would be worthless. It is BranchPickerPopover.test.tsx > resets the remotes view and restores no focus after a workspace switch — an activeElement assertion. That file is not in this PR's changed set, and it is green three independent ways: 139/139 passed in isolation, twice, and 144/144 when run together with both of this PR's new test files (so the new files do not pollute it). The owning CI lane, Test (ubuntu-latest, Node 22.x), is success at this same head. It is a load-sensitive focus flake under a 259 s / 8672-test run, not a regression from this PR.
4. Mutation witnesses — the counting tests actually count
A derivation-count assertion is exactly the kind of test that can pass while measuring nothing, so I broke the sharing on purpose, once per surface, and restored:
| mutation | result |
|---|---|
| none (head as-is) | 3/3 passed |
SessionWorkflowCockpit ignores sharedProjection and rebuilds |
1 failed — expected 1 to be +0 on builds no extra projection or index when the app passes one down; the two standalone cases still pass, correctly |
PlanExecutionView (the embedded graph) ignores sharedProjection and rebuilds |
2 failed — the shared case expected 1 to be +0, and derives the projection once for a standalone cockpit tree expected 2 to be 1 |
The second row is the one that matters: 2 → 1 is the graph's own private rebuild being counted and then caught, which is the deduplication this PR claims. Restoration is witnessed, not assumed — git diff --exit-code <head> -- packages/web-shell returns 0 and git status --porcelain is empty afterwards.
5. CI, stated precisely
Product lanes at this head are green: Lint & Static success, Test (ubuntu-latest, Node 22.x) success, Capture web-shell visuals success, web-shell E2E Smoke success, Desktop Shell (ubuntu-22.04) and (windows-2022) success, Integration Tests (no-AK, No Sandbox) success; Test (macos), Test (windows) and build-cli are skipped, not failing. Lane census total_count=42, items_fetched=42, match.
I am deliberately not writing "CI is green". The rollup reads statusCheckRollup.state = FAILURE and mergeStateStatus = BLOCKED, and the single non-green run in the census is the bot lane review-pr (completed / failure), whose latest run under that name is skipped — so a per-lane dedup hides the failure the rollup still counts. That lane is review infrastructure, not a product test.
6. The one thing still blocking this PR is not code
reviewDecision = CHANGES_REQUESTED comes from the triage bot's 2026-09-07 review at the then-head a0e85e8063c3, which is a description-template gate and says so itself — "nothing in this pass is a judgment on the code itself". A maintainer has since approved the current head (wenshao, APPROVED at 6c4484138c2c, 2026-09-18T22:09:29Z, which is after the head commit's 2026-09-18T03:52:19Z).
The description was reworked afterwards (updated_at 2026-09-18T22:52:29Z) and now carries What this PR does, Why it's needed, Reviewer Test Plan and How to verify. Four template sections are still absent as headings: ### Evidence (Before & After), ### Tested on, ## Risk & Scope, ## Linked Issues (Fixes #10865 is at the top of the body rather than under the last one). Whether that gate is now satisfied is a maintainer's call, not mine — I am flagging it because it, not the code, is what keeps mergeStateStatus at BLOCKED with auto-merge armed since 2026-09-18T22:09:39Z.
One observation the triage bot already made at the stale head is still accurate at this one, so I am not re-filing it, only confirming it: the new app-level memo is gated on sessionWorkflowEnabled alone. planAgentTools short-circuits to [] when no workflow surface is open, but environmentAgentTasks is a plain memo over messages, so a chat-only session with the experimental flag on now pays one buildSessionWorkflowProjection plus one createTaskExecutionIndex per message update where before it paid nothing. That is a deliberate-trade-off question for the author, not a correctness defect.
Conclusion
No Critical found. The refactor does what it says: one projection and one task-execution index per render, shared by the cockpit, the inspector and the embedded graph, with the extraction verified behaviour-preserving function by function and every handed-over derivation checked against its original. The perf claim is pinned by tests that fail when the sharing is broken, and the surfaces still render and link correctly in a real browser.
As of the state read immediately before posting, this comment carries no approval and requests no changes. I am not approving here because the outstanding blocker is the documentation gate above, which only a maintainer can waive — and a maintainer already has approved, so an additional approval from me would not change reviewDecision while the bot's review stands undismissed.
中文说明
在 head 6c4484138c2c 的独立检出上完整验证了这个 PR 自己的保证,并用变异测试证明这些检查不是空转。代码改动中没有发现阻塞合并的缺陷。
先确认范围。 merge_base(base, head) == base(e5969d67d4fb),分支未分叉;三点 diff 与 GitHub 自身数字完全一致 —— 10 个文件,+931 / −470。覆盖是文件完备的:7/7 个生产文件都按 head blob 读过,而不是只看补丁。其余 3 个是测试。
1. 抽取是行为等价的,逐个函数比对。 把现在位于 taskExecutionIndex.ts 的每个函数与合并基线上 PlanExecutionView.tsx 里的原实现做空白归一化比对:18 个全部对上 —— 14 个逐字节相同,3 个只差新增的 export,1 个只是把 return cond ? tool : undefined 改写成 if (cond) return tool; return undefined。 语义零差异。编译层面:PlanExecutionView.tsx 导入或再导出的 16 个符号在新模块中全部存在;也没有引入循环依赖。
2. 图交出去的每一项推导都语义相同。 八项逐一核对(见上表)。其中两项最值得点出:progressPercent 保留了 Math.floor(它喂给 aria-valuenow,取整会在长计划仍有步骤未完成时报出 100%);dependentsByTodo 保留了自依赖与未知 id 的过滤条件。memo 依赖从 [taskIndex, todos, tools] 改为 [projection, todos] 仍然正确。我也把新增的可选 projection prop 沿每一跳追到底,确认它不是"声明了却从未转发"的空开关 —— ArtifactPanel 是通过 {...workflow} 展开传给 SessionWorkflowInspector 的。
3. 执行证据。 在隔离 worktree 中构建 head(npm run generate && npm run build 均 exit 0):PR 自带的三个套件 6/6 通过;@qwen-code/web-shell 整套 8672 个测试通过 8671、失败 1(328 个文件,259 秒);真实 Chromium 的 Playwright 臂 session-workflow.spec.ts 2 passed (18.6s)(明暗两套主题)。该 spec 之所以关键,是因为它不只截图:它断言画布渲染出 4 个节点、3 条边,并断言 1m 14s 运行时长同时出现在节点面和 inspector 的 agent 行上 —— 后者正是"共享同一个 taskIndex"最可能悄悄弄坏、却仍能画出看似正常图形的工具调用↔任务关联。
关于那一个失败。 它是 BranchPickerPopover.test.tsx 里的一个 activeElement 断言,该文件不在本 PR 的改动集内,并且三种方式独立复现为绿:单独运行 139/139 通过,两次;与本 PR 两个新测试文件一起运行 144/144 通过(说明新文件没有污染它);同一 head 上归属的 CI lane Test (ubuntu-latest, Node 22.x) 为 success。它是 259 秒 / 8672 测试负载下的焦点时序偶发失败,不是本 PR 引入的回归。
4. 变异见证 —— 计数测试真的在计数。
| 变异 | 结果 |
|---|---|
| 无(head 原样) | 3/3 通过 |
SessionWorkflowCockpit 忽略 sharedProjection 自行重建 |
1 失败 —— expected 1 to be +0;两个 standalone 用例仍正确通过 |
PlanExecutionView(内嵌图)忽略 sharedProjection 自行重建 |
2 失败 —— 共享用例 expected 1 to be +0,standalone cockpit 用例 expected 2 to be 1 |
第二行最关键:2 → 1 正是图自己那次私有重建被计入并被抓住,也就是本 PR 声称消除的那一次。恢复是有见证的:git diff --exit-code <head> -- packages/web-shell 返回 0,git status --porcelain 为空。
5. CI 的精确表述。 该 head 上生产 lane 全绿(Lint & Static、Test (ubuntu-latest, Node 22.x)、Capture web-shell visuals、web-shell E2E Smoke、两个 Desktop Shell、Integration Tests (no-AK, No Sandbox) 均为 success;Test (macos)、Test (windows)、build-cli 为 skipped 而非失败)。lane 普查 total_count=42、items_fetched=42,一致。
我刻意不写"CI 全绿":rollup 读作 statusCheckRollup.state = FAILURE、mergeStateStatus = BLOCKED,普查中唯一非绿的运行是机器人 lane review-pr(completed / failure),而该名称下最新一次运行是 skipped —— 按 lane 去重会掩盖 rollup 仍然计入的那次失败。该 lane 属于评审基础设施,不是产品测试。
6. 唯一还阻塞这个 PR 的不是代码。 reviewDecision = CHANGES_REQUESTED 来自 triage 机器人 2026-09-07 在当时 head a0e85e8063c3 上的评审,那是描述模板关卡,它自己也这么写 —— "nothing in this pass is a judgment on the code itself"。维护者随后已批准当前 head(wenshao,APPROVED @ 6c4484138c2c,2026-09-18T22:09:29Z,晚于 head 提交的 2026-09-18T03:52:19Z)。描述在此之后被重写过(updated_at 2026-09-18T22:52:29Z),现已包含 What this PR does、Why it's needed、Reviewer Test Plan、How to verify;仍有四个模板章节作为标题缺失:### Evidence (Before & After)、### Tested on、## Risk & Scope、## Linked Issues。这道关卡是否已满足属于维护者判断,我只是指出:让 mergeStateStatus 停在 BLOCKED(且自 2026-09-18T22:09:39Z 起已开启自动合并)的是它,而不是代码。
triage 机器人在旧 head 上提过的一条观察在当前 head 依然成立,所以我不再重复提交,只作确认:新的 app 级 memo 只以 sessionWorkflowEnabled 为条件。planAgentTools 在没有工作流界面时会短路成 [],但 environmentAgentTasks 是对 messages 的普通 memo,因此开着该实验开关的纯聊天会话,现在每次消息更新都会付出一次 buildSessionWorkflowProjection 加一次 createTaskExecutionIndex,而此前是零。这是留给作者权衡的取舍问题,不是正确性缺陷。
结论:未发现 Critical。 按发帖前即时读到的状态,本条评论不含批准、也不要求修改。我不在此批准,是因为尚未解除的阻塞是上面那道文档关卡,只有维护者能豁免 —— 而维护者已经批准过,在机器人评审未被 dismiss 的情况下,我再加一个批准也不会改变 reviewDecision。
— independent verification by qqqys; built and executed at head 6c4484138c2c3f0669cd727b098304192535f8d7
This branch has not been deployed
6 participants


perf(web-shell): derive the session workflow projection once per render
Fixes #10865
What this PR does
One session workflow projection per render, shared by every surface.
Appbuilds the projection once (memoized on the same inputs the cockpit already receives) and hands the same object to the cockpit, the artifact-panel inspector, and the graph embedded in the cockpit. Each surface accepts an optionalprojectionprop and falls back to deriving from raw props, so standalone mounts (ToolApproval,TasksStatusMessage, isolated tests) are unchanged.To make the sharing possible without a circular import, the task-execution lookups
PlanExecutionViewowned — the index, its walkers, the node-state / attention / active-agent derivations — move to a sharedtaskExecutionIndexmodule that both the projection (session-workflow-model) and the graph now depend on.PlanExecutionViewre-exports them, so every existing import path keeps working.The projection now carries what the graph used to recompute privately:
taskIndex— the singlecreateTaskExecutionIndexbuild; the graph's executions read live status through it instead of raising their own;unassignedTools— tools whosetodo_idis missing or outside the plan, previously collected in the graph and dropped by the projection;toolsByTodo), node states, counts and its dependents map now come from the projection — the dependents map used to be a third copy of the sameblockedBywalk (after the projection's own and the one perf(web-shell): derive the session workflow projection once #10871 replaced in the inspector).What remains graph-local in
PlanExecutionViewis genuinely graph-specific: the topological layering, the topology serialization and the edge budget — still one memoized derivation that hover cannot re-run.Why it's needed
Follow-up to #10871 (merged). That PR made each derivation cheap — one index build per projection instead of one per todo and per tool — and memoized each surface's own derivation. What it left in place is that a single render still ran that derivation three times: the cockpit, the inspector (auto-opened beside it,
App.tsx→ArtifactPanel.tsx) and the embedded graph each built their own projection, each with its own index and its own copies of the grouping, node-state, count and dependents walks. The issue's remaining acceptance criterion is exactly this: one projection for the cockpit, the inspector and the embedded graph per render.Wiring the projection through
PlanExecutionViewalso removes the last semantic duplication inside the graph: its derived block re-derived an equivalent set from raw props inline, so any future divergence between the projection and the graph had two places to happen. They now cannot disagree — they read one object.Reviewer Test Plan
How to verify
The behavioural guarantees are pinned by tests rather than by inspection:
session-workflow-surfaces.test.tsx— mounts the cockpit (with its embedded graph) and the inspector together:buildSessionWorkflowProjectionandcreateTaskExecutionIndexboth count 0 extra calls, and both surfaces render their content from the shared object;PlanExecutionView.derivation.test.tsx:data-focused(the re-render happened) whilelayerPlanTodosandJSON.stringifycall counts stay flat — no topological re-sort, no topology re-serialization per hover;requestAnimationFrame, and that frame runs one measure pass (onegetBoundingClientRectbatch over the graph container and its nodes, not one per schedule call).session-workflow-model.index.test.ts(from perf(web-shell): derive the session workflow projection once #10871) — the projection still builds the task index exactly once; its mock now points at the extractedtaskExecutionIndexmodule, which is what the projection actually imports.Sanity of the spies: temporarily making
PlanExecutionViewignore the passed-in projection turns the surfaces suite red (1 extra projection + 1 extra index where 0 are expected, and 2 where 1 is expected for the standalone tree) — the counts fail on reintroduction, not just on absence.Manual check if you prefer: enable
experimental.sessionWorkflow, open the Workflow cockpit with a plan that has dependencies and agent steps, and confirm the graph, the inspector summary, the progress strip and the unassigned bucket all read the same values as before — the change is intended to be invisible. Everything in the existingPlanExecutionView,SessionWorkflowCockpit,SessionWorkflowInspectorandsession-workflow-modelsuites stays green, including the CSS source-shape guards.Not covered / out of scope
getAgentToolsForPlan's full-message rescan (issue problem 7) is untouched — it is memoized at theApplevel on the same message list and is a separate, self-contained change if it is wanted.中文说明
本 PR 做了什么
每次渲染只推导一份 session workflow projection,全部 surface 共享。
App层用 useMemo 构建一次(输入与 cockpit 现有 props 相同),把同一个对象传给 cockpit、artifact 面板里的 inspector、以及 cockpit 内嵌的依赖图。每个 surface 都接受可选的projectionprop,未传入时回退为从原始 props 自行推导——独立挂载场景(ToolApproval、TasksStatusMessage、隔离的测试)行为不变。为了让共享不产生循环依赖,原先由
PlanExecutionView持有的 task-execution 查询(索引本身、各类遍历、节点状态 / attention / 活跃 agent 推导)抽取到共享模块taskExecutionIndex,projection(session-workflow-model)与依赖图都改为依赖它。PlanExecutionView对这些导出做了 re-export,所有既有 import 路径不受影响。projection 现在携带图内此前各自重算的内容:
taskIndex—— 唯一一次createTaskExecutionIndex构建;图内的执行列表直接经由它读实时状态,不再自建;unassignedTools——todo_id缺失或指向计划外的工具,此前只在图内收集、projection 直接丢弃;toolsByTodo)、节点状态、各类计数、dependents 映射全部改从 projection 读取——dependents 映射此前是同一blockedBy遍历的第三份拷贝(projection 自身一份、perf(web-shell): derive the session workflow projection once #10871 在 inspector 里替换掉的那份之外又一份)。PlanExecutionView里保留的只剩真正图专属的部分:拓扑分层、拓扑序列化与边数预算——仍是单份 memo 化推导,hover 不会重跑。为什么需要
这是 #10871(已合并)的后续。那个 PR 让每次推导变便宜了——每个 projection 只建一次索引而不是每个 todo、每个 tool 各建一次——并把每个 surface 各自的推导 memo 化。它遗留的问题是:一次渲染仍会把这套推导跑三遍——cockpit、inspector(进入 cockpit 时自动在旁边打开)与内嵌图各建一份 projection,各自带自己的索引和各自的分组 / 节点状态 / 计数 / dependents 遍历。issue 剩下的验收标准正是这一点:cockpit、inspector 与内嵌图每次渲染共享一个 projection。
把 projection 接进
PlanExecutionView还消除了图内部最后一处语义重复:它的派生块此前用原始 props 内联重推一份等价集合,projection 与图之间未来任何行为分歧都有两个可以发生的地方;现在它们读同一个对象,不可能不一致。审查者验证计划
行为保证由测试钉住,而非人工检查:
session-workflow-surfaces.test.tsx—— 同时挂载 cockpit(含内嵌图)与 inspector:buildSessionWorkflowProjection与createTaskExecutionIndex的 spy 计数均为 0,且两个 surface 都基于共享对象正常渲染;PlanExecutionView.derivation.test.tsx:data-focused(确实发生了 re-render),而layerPlanTodos与JSON.stringify的调用计数保持不变——hover 不重跑拓扑排序、不重新序列化拓扑;requestAnimationFrame,该帧只跑一轮 measure(对图容器和各节点各读一次getBoundingClientRect,而不是每次调度一轮)。session-workflow-model.index.test.ts(perf(web-shell): derive the session workflow projection once #10871 引入)—— projection 每次仍然只建一次 task index;其 mock 路径已改为指向抽取后的taskExecutionIndex模块(projection 实际 import 的模块)。spy 的锋利度验证:临时让
PlanExecutionView无视传入的 projection,surfaces 套件立刻变红(共享场景多出 1 次 projection + 1 次 index,独立树场景 2 次而非 1 次)——计数在回退引入时会失败,而不是只对"不存在"敏感。偏好手动验证的话:开启
experimental.sessionWorkflow,打开 Workflow cockpit(计划带依赖与 agent 步骤),确认图、inspector 摘要、进度条与 unassigned 分组的读数与之前完全一致——本变更应当是不可见的。现有PlanExecutionView、SessionWorkflowCockpit、SessionWorkflowInspector、session-workflow-model套件全部保持绿色,包括 CSS 源形状守卫测试。未覆盖 / 范围之外
getAgentToolsForPlan的全消息重扫(issue 问题 7)未动——它在App层以同一消息列表为依赖做了 memoize,若需要是一个独立、内聚的后续变更。