fix(serve): load persisted MCP config after ACP preheat at startup - #11145
Conversation


Reconcile workspace MCP configuration once the primary runtime bridge
finishes preheating so persisted mcpServers settings are available
without a manual reload.

Fixes QwenLM#7771


 qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
@kabishou11 thanks for the PR — but the description is a single sentence and is missing every heading from the PR template: ## What this PR does, ## Why it's needed, ## Reviewer Test Plan (with ### How to verify, ### Evidence (Before & After), ### Tested on), ## Risk & Scope, ## Linked Issues, and the Chinese <details> translation.
All we currently have is:
Load persisted MCP configuration into the workspace runtime after ACP preheat at qwen serve startup. Fixes #7771
That is not enough to review a startup-ordering change in the serve daemon. Please fill the template in, and in particular:
- Why it's needed / How to verify — what actually goes wrong today? Give a
qwen servereproduction: start the daemon with a persisted MCP configuration and show the servers missing before your change and present after it. There is no before/after evidence at the moment. - Linked Issues — see below.
One thing worth settling before you rewrite the description: #7771 is not about this codebase. That issue is filed against the Qwen Desktop Electron app — it quotes sparkMcp.Proxy, the mcp_client_update_config IPC handler and AppData\Roaming\Qwen\settings.json, and states plainly "This issue was found in the Qwen Desktop app, not the Qwen Code CLI." None of those symbols exist in this repository. Your change is in the CLI's qwen serve HTTP-bridge daemon, which is a different startup path with its own MCP reconciliation (the workspace runtime coordinator already reconciles and initializes MCP config on demand).
So either the qwen serve daemon genuinely has the same gap — in which case prove it with a reproduction of its own, and reference #7771 without a closing keyword, since this PR would not close it — or the link is accidental. Either way Fixes #7771 would auto-close a desktop-app bug report on merge, which is the wrong outcome.
中文说明
@kabishou11 感谢提交 PR。不过目前的描述只有一句话,缺少 PR 模板 要求的全部小节:## What this PR does、## Why it's needed、## Reviewer Test Plan(含 ### How to verify、### Evidence (Before & After)、### Tested on)、## Risk & Scope、## Linked Issues,以及中文 <details> 翻译。
现有内容只有:
Load persisted MCP configuration into the workspace runtime after ACP preheat at qwen serve startup. Fixes #7771
对于一个改动 serve 守护进程启动时序的 PR,这些信息不足以完成 review。请补全模板,尤其是:
- Why it's needed / How to verify:现在的实际故障是什么?请给出
qwen serve的复现——在已有持久化 MCP 配置的情况下启动守护进程,展示改动前 server 缺失、改动后 server 存在。目前完全没有 before/after 证据。 - Linked Issues:见下。
在重写描述之前,有一件事需要先厘清:#7771 并不是针对本仓库的问题。 那个 issue 提交的对象是 Qwen Desktop(Electron)应用——它引用了 sparkMcp.Proxy、mcp_client_update_config IPC handler 以及 AppData\Roaming\Qwen\settings.json,并明确写了 "This issue was found in the Qwen Desktop app, not the Qwen Code CLI."。这些符号在本仓库中都不存在。而你改动的是 CLI 的 qwen serve HTTP-bridge 守护进程,那是另一条启动路径,也有自己的 MCP reconciliation(workspace runtime coordinator 已经会按需 reconcile 并 initialize MCP 配置)。
因此有两种可能:要么 qwen serve 确实存在同样的缺口——那么请用它自己的复现来证明,并以不带关闭关键字的方式引用 #7771,因为本 PR 并不会关闭它;要么这个关联是误加的。无论哪种情况,Fixes #7771 都会在合并时自动关闭一个桌面应用的 bug 报告,这是不对的。
— Qwen Code · qwen3.8-max-2026-09-02

|
@qwen-code /triage — PR description updated to the full template; Linked Issues now uses Relates to #7771 (no auto-close). Please re-run from the description gate. |

qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
@kabishou11 the description is now complete — every template heading is there, and I appreciate how plainly you scoped it: saying outright that #7771 is a Qwen Desktop report and that this PR does not close it is exactly the right call. That gate is cleared, and this review supersedes my earlier one, which was only about the template.
I can't take this into code review yet. Reading the surrounding code turned up one evidence gap and two problems in the change itself — the second of which I'd want fixed regardless of how the first goes.
1. The startup gap is real, but not the one the PR describes — and there's no reproduction.
Credit where due: the core premise holds. Nothing on main starts workspace-scope MCP discovery at daemon boot. The ACP child's bootstrap Config is initialized with skipMcpDiscovery: true (acpAgent.ts:2756-2763), and the dedicated workspace discovery Config is only ever created by initializeWorkspaceMcpDiscovery(), which is reachable solely from control ext-methods behind HTTP routes or from prepareMcpRevision(). ensure() and reconcileMcpConfiguration() are both HTTP-only (routes/workspace-runtime.ts:64, routes/workspace-mcp-config.ts:100). So right after preheat, discoveryState is not_started. That part is accurate.
But the described symptom isn't. The workspace status is built from getWorkspaceMcpConfig() = workspaceMcpDiscoveryConfig ?? this.config (acpAgent.ts:3762-3769), and buildWorkspaceMcpStatus lists config.getMcpServers() — so with no discovery Config yet, it falls back to the bootstrap Config and the persisted servers are listed. What's absent is discovery and connection state, not the servers. So "operators see configured MCP servers missing" and "empty/stale MCP proxy view" overstate it: the view is populated from settings, with discoveryState: 'not_started'.
That distinction matters, because it changes what a reproduction has to show. #7771 is a different product (Electron IPC, AppData\Roaming\Qwen\settings.json), and I found no issue in this repo reporting the daemon behaviour. Could you capture it on a real daemon? Persist an mcpServers entry, start qwen serve, and before creating a session or opening the Web Shell, fetch the workspace MCP status and paste the JSON — then paste it again after your change. If what you're fixing is discoveryState sitting at not_started, show that; if it's genuinely servers missing from the list, that contradicts the code above and I'd want to see it.
2. registry?.primary is a throwing getter, and it throws into the preheat failure handler.
WorkspaceRegistry.primary isn't a field — it's get primary() { return requirePrimaryRuntime(); } (workspace-registry.ts:361), which throws WorkspaceGenerationClosedError('Primary workspace runtime is unavailable.') when the primary entry isn't active (workspace-registry.ts:330). Optional chaining protects against registry being undefined; it does nothing about a getter that throws.
Your call sits inside preheat's .then(), right after startup.preheat.status = 'succeeded', and the adjacent .catch() is the preheat failure handler. So if the primary generation has closed by the time preheat resolves — start-then-stop, or a runtime torn down mid-startup — the throw lands there and a successful preheat is rewritten to status: 'failed', printing qwen serve: ACP preheat failed, will retry on first session: Primary workspace runtime is unavailable. That corrupts precisely the startup observability the surrounding tests exist to protect. Your if (!primary?.trusted) return; shows you intended a quiet skip; the getter fires before it. The file already has non-throwing idioms: workspaceRegistry.primaryEntry.current?.runtime (run-qwen-serve.ts:7883), or registry?.list() ?? [] as the neighbouring drain code does (run-qwen-serve.ts:9113).
3. reconcileMcpConfiguration() re-enables the bootstrap MCP spawn that boot deliberately skips.
This is the one I'd most want a maintainer's eye on. Because the runtime is live when preheat resolves, scheduleMcpReconciliation() takes its live branch and runs bridge.reloadWorkspaceMcp() first (workspace-runtime-coordinator.ts:323), before prepareMcpRevision(). In the child, reloadWorkspaceMcpDiscovery() iterates liveConfigs, and that set explicitly includes this.config — the bootstrap Config (acpAgent.ts:3977-3985) — calling config.reinitializeMcpServers(mcpServers) on each (acpAgent.ts:4021). That goes to refreshMcpServers(), whose !this.initialized no-op branch does not apply here (the bootstrap Config was already initialize()d, it only skipped discovery), so it runs discoverAllMcpToolsIncremental(this) on the bootstrap Config (config.ts:6678-6681).
That is exactly the bootstrap-level MCP subprocess spawn the W119 comment at acpAgent.ts:2758-2760 says boot avoids on purpose — "each session runs its own pool-routed discovery, so bootstrap-level spawns would be redundant subprocess leaks." As written, this would make that happen on every qwen serve startup.
It also points at the fix. ensure() is the existing primitive for this: it reaches prepareMcpRevision(), which calls initializeWorkspaceMcp() when discovery is not_started, creating the separate workspace discovery Config and running discovery there — bootstrap Config untouched, no W119 regression. If the goal is "workspace MCP discovery should start at daemon boot", that's the path that was designed for it, and it prepares Skills too rather than leaving them at not_started.
Smaller notes for the same pass:
- The
!primary?.trustedguard is unreachable: preheat is already disabled for untrusted workspaces atrun-qwen-serve.ts:4703-4706, which setspreheat.status = 'not_scheduled'. When your code runs, the workspace is trusted. makeFakeBridge()atrun-qwen-serve.test.ts:16271is shared by roughly eight tests in therunQwenServe startup observabilityblock. AddinggetWorkspaceRuntimeLifecycleSnapshotflipssupportsWorkspaceRuntimeLifecycle()false→true for all of them, so siblings now build a realWorkspaceRuntimeCoordinatorand exercisebeginDrain()during close against a mock hardcoded toruntimeLive: true. This file's own precedent is the opposite —run-qwen-serve.test.ts:14659adds the identical mock shape per-test viaObject.assign, keeping the shared factory minimal. Scoping it to your test keeps the blast radius at one.
On test evidence: there is none yet. Qwen Code CI, Serve A/B, tui-parity and SDK Java are all at action_required with zero jobs executed — normal for a first-time contributor, pending a maintainer approving fork CI. So the new unit test has never run and nothing has typechecked or linted this diff. Worth flagging since point 3 above is the kind of thing a green suite wouldn't catch anyway: the new test asserts reloadWorkspaceMcp was called, which is exactly the call I'm concerned about.
A before/after from a real daemon plus the getter fix would get this into code review; on point 3 I'd suggest switching to the ensure()/initialize path rather than defending the reload. Re-run with @qwen-code /triage when ready.
中文说明
@kabishou11 PR 描述现在完整了——模板要求的标题都在。也很感谢你把范围写得清楚:直接说明 #7771 是 Qwen Desktop 的问题、本 PR 不关闭它,这个处理完全正确。那道关卡已经过了,本次评审取代我上一条只针对模板的意见。
但我还不能进入代码审查。读周边代码时发现一个证据缺口和改动本身的两个问题——第二个无论第一个怎么走都需要修。
1. 启动缺口确实存在,但不是 PR 描述的那一个,而且没有复现。
先说成立的部分:在 main 上,守护进程启动时确实没有任何路径启动 workspace 级别 的 MCP discovery。ACP 子进程的 bootstrap Config 是用 skipMcpDiscovery: true 初始化的(acpAgent.ts:2756-2763),而专用的 workspace discovery Config 只由 initializeWorkspaceMcpDiscovery() 创建,后者只能从 HTTP 路由后面的控制 ext-method、或从 prepareMcpRevision() 到达。ensure() 和 reconcileMcpConfiguration() 都只有 HTTP 入口(routes/workspace-runtime.ts:64、routes/workspace-mcp-config.ts:100)。所以 preheat 之后 discoveryState 确实是 not_started。这一点你说得对。
但描述的症状不对。workspace 状态是由 getWorkspaceMcpConfig() = workspaceMcpDiscoveryConfig ?? this.config 构建的(acpAgent.ts:3762-3769),而 buildWorkspaceMcpStatus 列的是 config.getMcpServers()——所以在还没有 discovery Config 时,它会回落到 bootstrap Config,持久化的 server 是被列出来的。缺的是 discovery 和连接状态,不是 server 本身。因此"运维者看到已配置的 MCP server 缺失""MCP proxy 视图为空/过期"是说过头了:视图是拿 settings 填上的,只是 discoveryState: 'not_started'。
这个区别很重要,因为它决定了复现要证明什么。#7771 是另一个产品(Electron IPC、AppData\Roaming\Qwen\settings.json),我也在本仓库里没找到报告该守护进程行为的 issue。能否在真实守护进程上抓一次?持久化一条 mcpServers 配置,启动 qwen serve,在创建 session、打开 Web Shell 之前请求 workspace MCP 状态并贴出 JSON——改动之后再贴一次。如果你修的是 discoveryState 停在 not_started,就展示这个;如果确实是列表里没有 server,那与上面的代码相矛盾,我更想看到证据。
2. registry?.primary 是会抛异常的 getter,而它抛进了 preheat 的失败处理分支。
WorkspaceRegistry.primary 不是字段——它是 get primary() { return requirePrimaryRuntime(); }(workspace-registry.ts:361),当 primary entry 不是 active 时会抛 WorkspaceGenerationClosedError('Primary workspace runtime is unavailable.')(workspace-registry.ts:330)。可选链只能防 registry 为 undefined,对会抛异常的 getter 毫无作用。
你的调用位于 preheat 的 .then() 内部,紧跟在 startup.preheat.status = 'succeeded' 之后,而相邻的 .catch() 正是 preheat 的失败处理器。所以如果 preheat resolve 时 primary generation 已经关闭——启动后立刻停止,或启动过程中 runtime 被拆除——异常会落到那里,一次成功的 preheat 被改写成 status: 'failed',并在 stderr 打出 qwen serve: ACP preheat failed, will retry on first session: Primary workspace runtime is unavailable.。这恰好破坏了周边测试要保护的启动可观测性。你写的 if (!primary?.trusted) return; 说明本意是安静跳过,但 getter 在判断之前就抛了。本文件已有不抛异常的写法:workspaceRegistry.primaryEntry.current?.runtime(run-qwen-serve.ts:7883),或像相邻 drain 代码那样用 registry?.list() ?? [](run-qwen-serve.ts:9113)。
3. reconcileMcpConfiguration() 会重新打开 boot 刻意跳过的 bootstrap MCP spawn。
这一条最希望 maintainer 看一下。因为 preheat resolve 时 runtime 已经是 live,scheduleMcpReconciliation() 走 live 分支,先执行 bridge.reloadWorkspaceMcp()(workspace-runtime-coordinator.ts:323),然后才是 prepareMcpRevision()。在子进程里,reloadWorkspaceMcpDiscovery() 会遍历 liveConfigs,而这个集合明确包含 this.config——也就是 bootstrap Config(acpAgent.ts:3977-3985)——并对每个调用 config.reinitializeMcpServers(mcpServers)(acpAgent.ts:4021)。它进到 refreshMcpServers(),而其中的 !this.initialized 空操作分支在这里不适用(bootstrap Config 已经 initialize() 过了,只是跳过了 discovery),于是会在 bootstrap Config 上执行 discoverAllMcpToolsIncremental(this)(config.ts:6678-6681)。
而这正是 acpAgent.ts:2758-2760 的 W119 注释说 boot 要刻意避免的 bootstrap 级 MCP 子进程 spawn——"each session runs its own pool-routed discovery, so bootstrap-level spawns would be redundant subprocess leaks"。按现在的写法,这会在每次 qwen serve 启动时发生。
它也指向了修法。ensure() 就是为此设计的现有原语:它会走到 prepareMcpRevision(),在 discovery 为 not_started 时调用 initializeWorkspaceMcp(),创建独立的 workspace discovery Config 并在那里跑 discovery——bootstrap Config 不受影响,没有 W119 回归。如果目标是"守护进程启动时就该开始 workspace MCP discovery",这才是设计好的路径,而且它会连 Skills 一起准备,不会把 Skills 留在 not_started。
同批可以一起处理的小问题:
!primary?.trusted这个判断走不到:run-qwen-serve.ts:4703-4706已经对未受信工作区关掉了 preheat,并把preheat.status设为'not_scheduled'。等你的代码执行时,工作区一定是 trusted 的。run-qwen-serve.test.ts:16271的makeFakeBridge()被runQwenServe startup observability这个 block 里大约八个测试共用。往里加getWorkspaceRuntimeLifecycleSnapshot会让所有这些测试的supportsWorkspaceRuntimeLifecycle()从 false 变成 true,于是兄弟测试现在会构造真实的WorkspaceRuntimeCoordinator,并在 close 时执行beginDrain(),而 mock 又硬编码为runtimeLive: true。本文件自己的惯例相反——run-qwen-serve.test.ts:14659用Object.assign按单个测试加上完全相同的 mock 形状,保持共享工厂最小化。收窄到你这一个测试,影响面就只有一个。
关于测试证据: 目前还没有。Qwen Code CI、Serve A/B、tui-parity、SDK Java 全部停在 action_required,执行的 job 数为零——这对首次贡献者是正常状态,需要 maintainer 批准才能跑 fork CI。所以新增单测从未运行过,这个 diff 也没经过 typecheck 和 lint。这一点值得强调,因为上面第 3 条正是绿色测试也抓不到的那类问题:新测试断言的是 reloadWorkspaceMcp 被调用过,而那恰好就是我所担心的那个调用。
有了真实守护进程的前后对比、并修掉 getter 问题,就可以进入代码审查;第 3 条我建议改用 ensure()/initialize 路径,而不是为 reload 辩护。准备好后用 @qwen-code /triage 重跑。
— Qwen Code · qwen3.8-max-2026-09-02

Use the non-throwing primary runtime lookup and coordinator.ensure() so
startup discovery runs on the workspace Config without re-enabling
bootstrap MCP spawn.
|
Thanks for the detailed Stage 1b notes — addressed on
Local: Fork CI is still likely |

|
Verified the mechanism chain on current The placement is also correct — One suggestion (non-blocking): |
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed. Suggestions are inline.
Not reviewed: build-and-test — the automated test-efficacy harness was inconclusive (harnessValidated: null; 4 hunk-necessity probes skippedForBaseline, mutants not run, its runner dying on the vitest build-prerequisite guard in a tree lacking the git-ignored generated file); the ground was covered by hand instead — whole-change revert went RED, positive control green, and one surviving mutant was measured and filed as R1-3.
Not explored to full depth (tool budget reached): "agent reverse-audit (round 1)": whether workspace-scope discovery on the separate discovery Config actually reaches sessions that channel workers start in the same boot window ( manager.startI…; "agent reverse-audit (round 2)": I did not read queryWorkspaceStatus in workspace-service/index.ts to determine its liveness predicate — i.e. whether the bridge can report runtimeLive: tru…; "agent reverse-audit (round 2)": I did not walk publishLiveDiscovery (run-qwen-serve.ts:8258) or attachLiveDiscoveryControl (:8462) for an ordering interaction with the new warm-up, which n…; "agent reverse-audit (round 2)": I did not verify whether a boot ensure() that overlaps ensureChannelWorkerManager().startInitial() (run-qwen-serve.ts:8917-8921, awaiting inside completeRu…; "agent 6c": whether MCP discovery ( reloadWorkspaceMcp / initializeWorkspaceMcp ) is gated on workspaceTrusted inside the agent or bridge, and whether qwen serve can …, and 1 more.
Not reviewed: reverse audit — stopped before round 3 by the review time budget.
Test Plan (not a blocker): 10 passed — this review observed 28684 passed.
中文说明
仅完成部分审查,审查缺口已披露。 建议见行内评论。
未审查(原文为英文):build-and-test — the automated test-efficacy harness was inconclusive (harnessValidated: null; 4 hunk-necessity probes skippedForBaseline, mutants not run, its runner dying on the vitest build-prerequisite guard in a tree lacking the git-ignored generated file); the ground was covered by hand instead — whole-change revert went RED, positive control green, and one surviving mutant was measured and filed as R1-3.
未探索到全部深度(达到工具调用预算):"agent reverse-audit (round 1)":whether workspace-scope discovery on the separate discovery Config actually reaches sessions that channel workers start in the same boot window ( manager.startI…;"agent reverse-audit (round 2)":I did not read queryWorkspaceStatus in workspace-service/index.ts to determine its liveness predicate — i.e. whether the bridge can report runtimeLive: tru…;"agent reverse-audit (round 2)":I did not walk publishLiveDiscovery (run-qwen-serve.ts:8258) or attachLiveDiscoveryControl (:8462) for an ordering interaction with the new warm-up, which n…;"agent reverse-audit (round 2)":I did not verify whether a boot ensure() that overlaps ensureChannelWorkerManager().startInitial() (run-qwen-serve.ts:8917-8921, awaiting inside completeRu…;"agent 6c":whether MCP discovery ( reloadWorkspaceMcp / initializeWorkspaceMcp ) is gated on workspaceTrusted inside the agent or bridge, and whether qwen serve can …,另有 1 条。
未审查:反向审计——评审时间预算不足,未能开始第 3 轮。
Test Plan(非阻断):10 passed — this review observed 28684 passed。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| void getWorkspaceRuntimeCoordinatorIfSupported?.(runtime) | ||
| ?.ensure() |
There was a problem hiding this comment.
[Suggestion] R1-1: ensure() is the client-request primitive, and its first act is bridge.preheat({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }) (workspace-runtime-coordinator.ts:22,180). That writes keepAliveUntil = boot + 600000, and resolvedChannelIdleTimeoutMs() is Math.max(configured, keepAliveUntil - now, pending) (acp-bridge/src/bridge.ts:3651), so the boot preheat's own finally now arms an idle timer it deliberately did not arm before: settleReleasedRuntimeWork('channel preheat', resolvedChannelIdleTimeoutMs() > 0) (bridge.ts:14699-14702) evaluated false while --channel-idle-timeout-ms was unset — channelIdleTimeoutMs(undefined) returns 0 (run-qwen-serve.ts:2313-2317) — and evaluates 600000 after this change. A daemon that boots, preheats and serves zero sessions therefore kills its own warm channel at boot+10min, taking the ACP child, the workspace discovery Config and the MCP subprocesses this PR just started down with it; the first session then pays the cold spawn the preheat exists to avoid and discoveryState is back to not_started, which is the very symptom this PR sets out to fix. Symmetrically, an operator who set a short timeout to bound memory gets ten minutes instead, for the first ten minutes of every boot. The keep-alive is not needed to reach the goal: right after a successful preheat the runtime is already live, and the MCP-only path preheats only when !snapshot.runtimeLive (workspace-runtime-coordinator.ts:302,544-546). ensure() also runs prepareSkills() — an invalidateWorkspaceSkillsStatus() plus an IPC round trip (:508-513) — which the description neither claims nor the test asserts, and Risk & Scope names only the bootstrap-spawn risk.
Witness:
real-daemon A/B, identical script both arms, ZERO HTTP requests, isolated HOME/QWEN_HOME
arm proof: scheduleWorkspaceMcpDiscoveryAfterPreheat present in the PR dist, absent from the base dist
BASE (1b604721b): /acp WebSocket transport enabled on /acp  -> no kill line, channel alive for the whole 11.5 min
PR   (089e8cf44): qwen serve: idle timeout (599740ms) expired, killing channel
                  qwen serve: channel exited (code=0, signal=none, transport=ndjson_unexpected_eof, 0 session(s) torn down)
second arm, operator-set bound --channel-idle-timeout-ms 8000, 105 s window:
BASE: qwen serve: idle timeout (8000ms) expired, killing channel
PR  : no kill line within 105 s
unit level, same mechanism: PROBE[ALIVE-CONTROL] preheatCalls=2 args=["null","{\"keepAliveMs\":600000}"] ensureCalls=1
The fix spans two files, so there is no one-click block: give the coordinator a preparation-only entry point (or an ensure({ keepAliveMs }) option) that skips the redundant preheat when getWorkspaceRuntimeLifecycleSnapshot().runtimeLive is already true — which it always is at this call site, since the hook runs inside preheat's .then — and call that here instead. If reaping the preheated child at boot+10min genuinely is the intended behaviour, recording it in Risk & Scope is enough.
A narrower boot keep-alive still has to cover the poll budget it exists to protect: MCP_PREPARE_TIMEOUT_MS = 2 * 60_000 (packages/cli/src/serve/workspace-runtime-coordinator.ts:23) is the deadline prepareMcpRevision polls against, so dropping below roughly two minutes lets the channel be reaped mid-poll when channelIdleTimeoutMs is 0; and ENSURE_KEEP_ALIVE_MS = 10 * 60_000 (:22) is shared by the client ensure route (routes/workspace-runtime.ts:30), prepareSkillsRevision (:499) and runMcpRuntimeMutation (:398), so keep the change at the boot call site rather than retuning the constant, whose documented contract is "0 or unset = reap after work drains; keepalive windows may extend it (default)" (packages/cli/src/commands/serve.ts:585-587).
Please pin the chosen behaviour with a test that goes red if the boot path reaches ensure() again — a boot case that does not stub WorkspaceRuntimeCoordinator.prototype.ensure and asserts the fake bridge's preheat is never called with a keepAliveMs after the startup preheat (the mirror of server.test.ts:5898, which pins { keepAliveMs: 600_000 } for the route path). The current test stubs ensure wholesale, so it cannot observe this either way.
中文说明
ensure() 是面向客户端请求的原语,它的第一步就是 bridge.preheat({ keepAliveMs: ENSURE_KEEP_ALIVE_MS })(workspace-runtime-coordinator.ts:22,180)。这会把 keepAliveUntil 写成 boot + 600000,而 resolvedChannelIdleTimeoutMs() 是 Math.max(configured, keepAliveUntil - now, pending)(acp-bridge/src/bridge.ts:3651),于是 boot preheat 自己 finally 里那个原本刻意不启动的空闲定时器现在被启动了:settleReleasedRuntimeWork('channel preheat', resolvedChannelIdleTimeoutMs() > 0)(bridge.ts:14699-14702)在未传 --channel-idle-timeout-ms 时求值为 false(channelIdleTimeoutMs(undefined) 返回 0,run-qwen-serve.ts:2313-2317),改动之后变成 600000。
因此一个启动、preheat 成功、但一个 session 都没服务的守护进程,会在 boot+10min 杀掉自己的热通道,连带 ACP 子进程、workspace discovery Config 以及本 PR 刚启动的 MCP 子进程一起消失;第一个 session 随后要付出 preheat 本来要避免的冷启动代价,而 discoveryState 又回到 not_started——正是本 PR 想修的症状。反过来,为了限制内存而配置了较短 timeout 的运维者,在每次启动后的前十分钟里得到的是十分钟。这个 keep-alive 对达成目标并非必需:preheat 成功后 runtime 已经是 live,而 MCP-only 路径只在 !snapshot.runtimeLive 时才 preheat(workspace-runtime-coordinator.ts:302,544-546)。另外 ensure() 还会跑 prepareSkills()——一次 invalidateWorkspaceSkillsStatus() 加一次 IPC 往返(:508-513)——描述里没有声明,测试也没有断言,而 Risk & Scope 只提到了 bootstrap spawn 的风险。
修法跨两个文件,所以没有一键 suggestion:给 coordinator 增加一个只做准备的入口(或 ensure({ keepAliveMs }) 选项),在 getWorkspaceRuntimeLifecycleSnapshot().runtimeLive 已经为 true 时跳过多余的 preheat——在这个调用点它必然为 true,因为 hook 就在 preheat 的 .then 里——然后改调它。如果 boot+10min 回收 preheat 子进程确实是预期行为,把它写进 Risk & Scope 也可以。
约束:更窄的 boot keep-alive 仍要覆盖它所保护的轮询预算——MCP_PREPARE_TIMEOUT_MS = 2 * 60_000(packages/cli/src/serve/workspace-runtime-coordinator.ts:23)是 prepareMcpRevision 轮询的截止时间,低于约两分钟会在 channelIdleTimeoutMs 为 0 时被中途回收;而 ENSURE_KEEP_ALIVE_MS = 10 * 60_000(:22)被客户端 ensure 路由(routes/workspace-runtime.ts:30)、prepareSkillsRevision(:499)和 runMcpRuntimeMutation(:398)共用,所以请在 boot 调用点修改,不要调整这个常量,其文档契约是「0 or unset = reap after work drains; keepalive windows may extend it (default)」(packages/cli/src/commands/serve.ts:585-587)。
请用一个「boot 路径重新走回 ensure() 就会变红」的测试把选定的行为钉住:一个不 stub WorkspaceRuntimeCoordinator.prototype.ensure 的 boot 用例,断言启动 preheat 之后 fake bridge 的 preheat 不会再带 keepAliveMs 被调用(对应 server.test.ts:5898,那里为路由路径钉住了 { keepAliveMs: 600_000 })。当前测试整体 stub 了 ensure,两种情况都观察不到。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| ?.ensure() | ||
| .catch(() => undefined); |
There was a problem hiding this comment.
[Suggestion] R1-2: every exit of this new boot step is silent, so nothing distinguishes "discovery was never scheduled" from "discovery ran and failed". ensure() rejects without recording any capability status when its own preheat fails, when status.runtimeLive is false, or when assertAcceptingWork() hits a closed or draining generation guard (workspace-runtime-coordinator.ts:173-232, 677-682); only errors raised inside prepareMcpRevision reach recordMcpError, and even those just mutate status fields — they never log (:640-703). So an operator who follows this PR's own "How to verify" (persist mcpServers, start qwen serve, read workspace MCP status before any session) and sees discoveryState: 'not_started' has no breadcrumb separating "the fix did not run", "the fix ran and failed" and "this build predates the fix". The adjacent preheat failure handler in this very same callback chain does log — qwen serve: ACP preheat failed, will retry on first session: ${message} (:8958-8967) — and the other boot-time background publish warns and arms a retry (publishLiveDiscovery, :8220-8250), which makes this the only silent boot step in a block whose tests are named runQwenServe startup observability. The sole residue is capabilities.mcp.state on GET /workspace/runtime/status, which the next reconcileMcpConfiguration() overwrites.
Witness:
probe in a scratch tree at 089e8cf44 — real ensure(), fake bridge whose workspace commands reject,
stderr collector + daemon-log file read back:
PROBE[R1-2] ensureCalls=1 stderrDiscoveryLines=[] daemonLogDiscoveryLines=[] statusHttp=200
  capabilities={"mcp":{"state":"error","revision":0,"runtimeEpoch":1,
               "error":{"code":"mcp_prepare_failed","message":"probe: status unavailable"}},
                "skills":{"state":"error","revision":0,"runtimeEpoch":1,
               "error":{"code":"skills_prepare_failed","message":"probe: status unavailable"}}}
both capabilities failed at boot; the only residue anywhere was the status body
| ?.ensure() | |
| .catch(() => undefined); | |
| ?.ensure() | |
| .catch((err) => { | |
| const message = err instanceof Error ? err.message : String(err); | |
| writeStderrLine( | |
| `qwen serve: workspace MCP discovery after preheat failed: ${message}`, | |
| ); | |
| }); |
That mirrors the const message = … / writeStderrLine shape of the preheat catch four lines below and uses only symbols already in scope; daemonLog.warn is also in scope (:3948) if you would rather it land in the daemon log, but it takes a context object rather than an Error. Worth deciding whether the expected drain and generation-closed races — which handle.close() in the new test's own finally can produce — should stay quiet rather than print on every shutdown.
The logging must not be able to throw into the preheat chain: its .catch sets startup.preheat.status = 'failed' and prints ACP preheat failed, will retry on first session (run-qwen-serve.ts:8958-8967), so a synchronous throw from this helper would rewrite a successful preheat — exactly the regression the non-throwing primary lookup was introduced to avoid.
Please add the test that pins the new line: a sibling of starts workspace MCP discovery after ACP preheat succeeds (run-qwen-serve.test.ts:16528) that makes ensure reject, then asserts preheat status is still 'succeeded' and that the diagnostic was written (the stderr-collector pattern from the sibling at :16396). Removing the log must turn that second assertion red.
中文说明
这个新的 boot 步骤的每一个出口都是静默的,因此无法区分「discovery 从未被调度」和「discovery 跑了但失败了」。当 ensure() 自身的 preheat 失败、status.runtimeLive 为 false、或 assertAcceptingWork() 撞上已关闭/正在 drain 的 generation guard 时,它 reject 且不会记录任何 capability 状态(workspace-runtime-coordinator.ts:173-232, 677-682);只有 prepareMcpRevision 内部抛出的错误才会走到 recordMcpError,而那也只是修改状态字段,从不打日志(:640-703)。所以一位按照本 PR 自己的「How to verify」操作的运维者(持久化 mcpServers、启动 qwen serve、在建任何 session 之前读 workspace MCP 状态)看到 discoveryState: 'not_started' 时,没有任何线索能区分「修复没跑」「修复跑了但失败」和「这个构建早于该修复」。就在同一条回调链里,相邻的 preheat 失败处理是打日志的——qwen serve: ACP preheat failed, will retry on first session: ${message}(:8958-8967)——另一个 boot 期后台发布也会 warn 并挂上重试(publishLiveDiscovery,:8220-8250),这使得它成为这个测试块(名为 runQwenServe startup observability)里唯一静默的 boot 步骤。唯一的残留是 GET /workspace/runtime/status 上的 capabilities.mcp.state,而下一次 reconcileMcpConfiguration() 会把它覆盖掉。
上面的一键 suggestion 复用了下方四行处 preheat catch 的 const message = … / writeStderrLine 写法,只用到已在作用域内的符号;如果更希望写进守护进程日志,daemonLog.warn 也在作用域内(:3948),但它接收的是一个上下文对象而不是 Error。另外值得决定:预期内的 drain 与 generation-closed 竞态(新测试自己 finally 里的 handle.close() 就会触发)是否应该保持安静,而不是每次关闭都打印。
约束:日志本身不能抛进 preheat 链——它的 .catch 会把 startup.preheat.status 置为 'failed' 并打印 ACP preheat failed, will retry on first session(run-qwen-serve.ts:8958-8967),所以这个 helper 里的同步抛错会把一次成功的 preheat 改写成失败,而那正是引入非抛异常 primary 查找要避免的回归。
请补上钉住这行新代码的测试:在 starts workspace MCP discovery after ACP preheat succeeds(run-qwen-serve.test.ts:16528)旁边加一个用例,让 ensure reject,然后断言 preheat 状态仍是 'succeeded'且诊断信息被写出(可复用 :16396 那个兄弟用例的 stderr 收集写法)。删掉这行日志,第二个断言必须变红。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| expect(await waitForPreheatStatus(handle, 'succeeded')).toMatchObject({ | ||
| status: 'succeeded', | ||
| }); | ||
| await vi.waitFor(() => expect(ensureSpy).toHaveBeenCalledOnce()); |
There was a problem hiding this comment.
[Suggestion] R1-3: this asserts only that ensure() was called, never when it was called or which runtime it was called on — and both of those are the change's actual claims. vi.waitFor is a retry-until-true poll and waitForPreheatStatus(handle, 'succeeded') runs before it, while the installed bridge preheats with () => Promise.resolve() (line 16532), so the hook and the preheat resolution land in the same tick and any earlier call satisfies both assertions. On the target: the spy is on the prototype and the fixture registers exactly one workspace (workspace: tmpDir, maxSessions: 1), so registry?.primaryEntry.current?.runtime and "the only runtime in the registry" are the same object — a regression that resolves registry.list()[0], an internal/managed-scratch runtime, or a superseded generation passes identically while boot discovery is aimed at the wrong workspace.
Witness:
measured in a scratch tree at 089e8cf44, not inferred:
MUTANT  scheduleWorkspaceMcpDiscoveryAfterPreheat(app) hoisted out of .then(() => ...)
        to immediately after startup.preheat.status = 'running'
        -> run-qwen-serve.test.ts: 379 passed (379), including this test
CONTROL whole-change revert (PR test file on base sources)
        -> RED, AssertionError: expected "ensure" to be called once, but got 0 times  (line 16564)
CONTROL positive (PR sources in the base tree) -> 1 passed
So the hoisted mutant — discovery starting concurrently with ACP preheat instead of after it, and also firing on the .catch path when preheat failed — ships green, and any future refactor that reintroduces that ordering inherits a passing suite.
The fix spans this test's setup and its assertions, so no one-click block. Give the test a preheat it controls, and assert the ordering and the target:
let resolvePreheat!: () => void;
const bridge = installInternalBridge(
  () => new Promise<void>((resolve) => (resolvePreheat = resolve)),
);
// … after `const handle = await runQwenServe(…)`:
expect(ensureSpy).not.toHaveBeenCalled();
resolvePreheat();
expect(await waitForPreheatStatus(handle, 'succeeded')).toMatchObject({
  status: 'succeeded',
});
await vi.waitFor(() => expect(ensureSpy).toHaveBeenCalledOnce());
expect(
  (ensureSpy.mock.instances[0] as unknown as { runtime: { workspaceCwd: string } })
    .runtime.workspaceCwd,
).toBe(canonicalizeWorkspace(tmpDir));
For the "which runtime" half to be a real distinction rather than a tautology, the fixture needs a second (non-primary) workspace; without one, the identity assertion documents the intent but cannot fail on a list()[0] regression.
waitForPreheatStatus polls a fixed budget — for (let i = 0; i < 20; i++) with a 10 ms sleep (:16316-16320) — and throws preheat status did not become succeeded when it expires, so the deferred version must call resolvePreheat() before awaiting 'succeeded' or the helper times out at roughly 200 ms. Also keep asserting call ordering only, never awaiting discovery completion: the production call is fire-and-forget with errors swallowed (run-qwen-serve.ts:8939-8941), so a test that awaited it would pin a guarantee the code deliberately does not make. The getWorkspaceRuntimeLifecycleSnapshot stub must stay even though its return value is never read — getWorkspaceRuntimeCoordinatorIfSupported returns undefined unless the bridge exposes that method (workspace-runtime-coordinator.ts:60-64).
With the ordering assertion added, hoisting scheduleWorkspaceMcpDiscoveryAfterPreheat(app) above bridge.preheat() must turn this test red; today it stays green under exactly that mutation (measured: 379/379).
中文说明
这里只断言了 ensure() 被调用过,没有断言它何时被调用、也在哪个 runtime 上被调用——而这两点恰恰是本次改动的核心主张。vi.waitFor 是一个「重试直到为真」的轮询,而 waitForPreheatStatus(handle, 'succeeded') 在它之前执行;同时测试装的 bridge 用 () => Promise.resolve() 做 preheat(第 16532 行),所以 hook 与 preheat 的 resolve 落在同一个 tick,任何更早的调用都能同时满足这两个断言。关于「哪个 runtime」:spy 挂在 prototype 上,而 fixture 只注册了一个 workspace(workspace: tmpDir、maxSessions: 1),所以 registry?.primaryEntry.current?.runtime 和「注册表里唯一的 runtime」是同一个对象——如果回归成解析 registry.list()[0]、某个 internal/managed-scratch runtime、或一个已被取代的 generation,测试同样通过,而 boot discovery 已经指向了错误的 workspace。
上面的 witness 是在 089e8cf44 的 scratch tree 里实测的,不是推断:把 scheduleWorkspaceMcpDiscoveryAfterPreheat(app) 从 .then(() => ...) 里提到 startup.preheat.status = 'running' 之后,run-qwen-serve.test.ts 仍然 379 passed (379),包含本用例;而整体回滚对照(把 PR 的测试文件放到 base 源码上)会变红(expected "ensure" to be called once, but got 0 times),正向对照(把 PR 源码放进 base tree)为 1 passed。也就是说,那个被提升的变异体——discovery 与 ACP preheat 并发启动而不是在其之后,并且在 preheat 失败时也会从 .catch 路径触发——是绿灯通过的。
修改跨这个测试的 setup 和断言,所以没有一键 suggestion;上面给了可直接采用的写法:用受控的 deferred preheat 断言时序,再用 ensureSpy.mock.instances[0] 断言目标 runtime 的 workspaceCwd。要让「哪个 runtime」成为真正的区分而不是同义反复,fixture 需要第二个(非 primary)workspace;否则该身份断言只表达了意图,无法在 list()[0] 回归时失败。
约束:waitForPreheatStatus 的轮询预算是固定的——for (let i = 0; i < 20; i++),每次 sleep 10 ms(:16316-16320)——超时即抛 preheat status did not become succeeded,所以 deferred 版本必须在 await 'succeeded' 之前调用 resolvePreheat(),否则大约 200 ms 就会超时。另外请只断言调用时序,绝不要 await discovery 完成:生产代码是 fire-and-forget 且吞掉错误(run-qwen-serve.ts:8939-8941),await 它会钉住一个代码刻意不提供的保证。getWorkspaceRuntimeLifecycleSnapshot 这个 stub 必须保留,尽管它的返回值从不被读取——除非 bridge 暴露该方法,getWorkspaceRuntimeCoordinatorIfSupported 会返回 undefined(workspace-runtime-coordinator.ts:60-64)。
加上时序断言后,把 scheduleWorkspaceMcpDiscoveryAfterPreheat(app) 提到 bridge.preheat() 之上必须让本用例变红;今天它在完全相同的变异下仍然是绿的(实测 379/379)。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| .mockResolvedValue({ | ||
| runtimeLive: true, | ||
| } as never); |
There was a problem hiding this comment.
[Suggestion] R1-4: the spy resolves, so nothing in the suite ever makes ensure() reject — which means the .catch(() => undefined) guard this diff adds can be deleted and every test still passes. Rejection is an ordinary boot state, not an exotic one: assertAcceptingWork() throws WorkspaceDrainingError when the generation is draining or disposed and WorkspaceGenerationClosedError on a closed generation (workspace-runtime-coordinator.ts:676-682); ensure throws WorkspaceRuntimeInitializationError('ACP preheat completed without a live runtime') (:188-193) and ('Workspace runtime stopped during Skills/MCP preparation') (:227-233); it times out after DEFAULT_ENSURE_TIMEOUT_MS = 60_000 (:21); and bridge.preheat throws AcpSessionBridge is shutting down once shuttingDown is set (bridge.ts:14657-14659). The coordinator's own suite already has a case named rejects ensure when the runtime stops during Skills preparation (workspace-runtime-coordinator.test.ts:968). Remove the guard and that rejection becomes unhandled at boot — and this file records the consequence itself: "the serve fast path installs no process-level unhandledRejection handler before the runtime builds … without the import's .catch the rejection escapes and Node's default is to exit" (:11719-11721). On Node ≥22, the package's stated floor, the daemon prints qwen serve listening on … and then dies with no stderr explanation while the suite stays green. process.on('uncaughtExceptionMonitor', …) (run-qwen-serve.ts:9518) is a monitor and does not keep the process alive.
Witness:
mutation measured in a scratch tree at 089e8cf44 — real ensure(), NO spy, process.on('unhandledRejection') recorder:
MUTANT (.catch(() => undefined) removed): PROBE[R1-8b] unhandledRejections=1 detail=["WorkspaceDrainingError"] bridgePreheatCalls=1
INTACT                                  : PROBE[R1-8b] unhandledRejections=0 detail=[]                      bridgePreheatCalls=1
produced by nothing but start-then-stop
with the mutant applied the whole block still passed: Tests 13 passed | 369 skipped (382)
runtime check: node -e "Promise.reject(new Error('boom'))" on v22.23.2 prints the error and exits 1
The new case belongs beside the one this diff adds; it needs no one-click block. Note the trap the verifier measured first-hand — mockRejectedValue will not work here: rejections returned from vi.fn().mockRejectedValue(...) and from a prototype spy's mockRejectedValue are not surfaced as unhandledRejection in this harness (PROBE[SOURCES] count=1 detail=["Error: inline boom"] protoSpyCalls=1 mockedCalls=1 — only a voided Promise.reject is recorded), so a test written that way stays green with the guard removed. Use mockImplementation(async () => { throw … }), or no spy at all:
it('does not leak an unhandled rejection when boot MCP discovery fails', async () => {
  const rejections: unknown[] = [];
  const recordRejection = (reason: unknown) => rejections.push(reason);
  process.on('unhandledRejection', recordRejection);
  try {
    // same bridge stubs as the success case, but ensure REJECTS:
    vi.spyOn(WorkspaceRuntimeCoordinator.prototype, 'ensure').mockImplementation(
      async () => {
        throw new Error('ensure boom');
      },
    );
    // … runQwenServe, await preheat 'succeeded' …
    expect(rejections).toEqual([]);
  } finally {
    process.off('unhandledRejection', recordRejection);
  }
});
The hook only reaches ensure() when the bridge passes the lifecycle gate — return typeof bridge.getWorkspaceRuntimeLifecycleSnapshot === 'function'; (workspace-runtime-coordinator.ts:60-64) — and the local makeFakeBridge() does not define it (:16273-16286), so a rejection test must keep the per-test Object.assign(bridge, { getWorkspaceRuntimeLifecycleSnapshot: … }) stub or the coordinator is undefined and ensure is never called at all.
That case must go red when .catch(() => undefined) is removed from run-qwen-serve.ts:8941, since the rejected promise then has no handler and lands in the recorded array.
中文说明
这个 spy 是 resolve 的,所以整个测试套件里从来没有让 ensure() reject 过——也就是说,本 diff 新增的 .catch(() => undefined) 保护可以被删掉,而所有测试依然通过。reject 在 boot 阶段是常态而非罕见情况:generation 正在 drain 或已 dispose 时 assertAcceptingWork() 抛 WorkspaceDrainingError,generation 已关闭时抛 WorkspaceGenerationClosedError(workspace-runtime-coordinator.ts:676-682);ensure 会抛 WorkspaceRuntimeInitializationError('ACP preheat completed without a live runtime')(:188-193)和 ('Workspace runtime stopped during Skills/MCP preparation')(:227-233);超过 DEFAULT_ENSURE_TIMEOUT_MS = 60_000(:21)会超时;而 shuttingDown 置位后 bridge.preheat 抛 AcpSessionBridge is shutting down(bridge.ts:14657-14659)。coordinator 自己的套件里就已经有一个名为 rejects ensure when the runtime stops during Skills preparation 的用例(workspace-runtime-coordinator.test.ts:968)。删掉这个保护,该 rejection 就会在 boot 时变成未处理——而本文件自己就记录了这个后果:「the serve fast path installs no process-level unhandledRejection handler before the runtime builds … without the import's .catch the rejection escapes and Node's default is to exit」(:11719-11721)。在本包声明的下限 Node ≥22 上,守护进程会先打印 qwen serve listening on …,然后在没有任何 stderr 解释的情况下退出,而测试套件仍然是绿的。process.on('uncaughtExceptionMonitor', …)(run-qwen-serve.ts:9518)只是 monitor,不能让进程存活。
新用例应放在本 diff 新增用例旁边,不需要一键 suggestion。请注意验证者 firsthand 踩到的坑——这里 mockRejectedValue 不管用:在这个 harness 中,vi.fn().mockRejectedValue(...) 以及 prototype spy 的 mockRejectedValue 返回的 rejection 不会作为 unhandledRejection 冒出来(PROBE[SOURCES] count=1 detail=["Error: inline boom"] protoSpyCalls=1 mockedCalls=1,只有被 void 掉的 Promise.reject 才会被记录),所以那样写的测试在保护被删除后仍然是绿的。请改用 mockImplementation(async () => { throw … }),或者干脆不用 spy(写法见上方代码块)。
约束:只有当 bridge 通过 lifecycle 检查时 hook 才会走到 ensure()——return typeof bridge.getWorkspaceRuntimeLifecycleSnapshot === 'function';(workspace-runtime-coordinator.ts:60-64)——而本地的 makeFakeBridge() 并没有定义它(:16273-16286),所以 rejection 用例必须保留按测试挂载的 Object.assign(bridge, { getWorkspaceRuntimeLifecycleSnapshot: … }) stub,否则 coordinator 是 undefined,ensure 根本不会被调用。
当 run-qwen-serve.ts:8941 的 .catch(() => undefined) 被删除时,该用例必须变红,因为那时被 reject 的 promise 没有处理者,会落进被记录的数组里。
— qwen3.8-max via Qwen Code /review (v0.23.0)
|
Thanks @now-ing — glad the Agree on the catch logging nit; I will add a debug log for best-effort warm-start failures so a stuck |
Boot discovery now prepares the already-live runtime without a second
client-route keep-alive preheat, so an idle daemon is not forced to a
10-minute channel window. Warm-start failures are debug-logged.

b4b51e1 to
87e2575
Compare
|
Addressed the boot keep-alive issue on After a successful ACP preheat the runtime is already live, so the boot path now calls Also added debug logging in the boot catch for warm-start failures, and tests that pin: no post-startup |
|
Qwen Code review timed out. Qwen review timed out after 10800 seconds (of the 180-minute budget). For large PRs, retry with a longer timeout by commenting: |
|
@qwen-code /review --timeout=360 |
|
Thanks @kabishou11 — third pass on this one, and the distance from the first is substantial. Both of my earlier request-changes reviews are pinned at Template ✓ — every heading is present, and the scoping is honest. Saying outright that #7771 is a Qwen Desktop report and using Problem — real, and code-evident rather than theoretical. I re-walked the chain on There is still no live-daemon before/after JSON, and the description says so plainly instead of papering over it. I am carrying that into Stage 2 as a verification gap rather than bouncing the gate again — the mechanism is checkable by reading, and you have already been asked once. Direction — aligned. This is Size — does not trigger the core-module gate. All four files live under Approach — the scope feels right and I would not cut anything. Seventy-eight lines, one new function, one new exported type, no drive-by refactors, no formatting churn; the Risk — no elevated risk signals; none of the four files match the revert-correlated path patterns. The real risk on this PR is not in the diff, it is that no CI has run on it. That is Stage 2. Moving on to code review. 🔍 中文说明感谢 @kabishou11 —— 这是第三轮,和第一轮的差距非常大。我之前两条 request-changes 都停在 模板 ✓ —— 所有小节都齐了,范围也写得诚实。直接说明 #7771 是 Qwen Desktop 的问题、并用 问题 —— 真实存在,而且是代码可证的,不是理论加固。我在 仍然没有真实守护进程的 before/after JSON,而描述里直接写明了这一点,没有遮掩。我把它作为验证缺口带入 Stage 2,而不是再退回关卡一次——机制靠读代码可以确认,而且这一点已经问过一次了。 方向 —— 对齐。这是 规模 —— 不触发核心模块关卡。四个文件都在 方案 —— 范围合理,我不会砍任何东西。78 行、一个新函数、一个新导出类型,没有顺手重构,没有格式化噪音; 风险 —— 无升级风险信号;四个文件都不匹配与 revert 相关的路径模式。这个 PR 真正的风险不在 diff 里,而在于它从未跑过 CI。见 Stage 2。 进入代码审查 🔍 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
Code reviewMy independent proposal first. Reading only the title and the "Why it's needed" section, what I would have written is close to what is here: hook the preheat success So: the approach matches mine, and on the W119 question it is better than my first instinct, because it found the keep-alive interaction I had not thought through. All three Stage 1b blockers are genuinely fixed. I checked each against the code at this commit rather than taking the description's word:
The four No critical blockers. Beyond the three fixes I confirmed the things that would have been easy to get wrong here: sequenceDiagram
participant P1 as run-qwen-serve boot
participant P2 as WorkspaceRuntimeCoordinator
participant P3 as AcpSessionBridge
participant P4 as workspace discovery Config
P1->>P1: ACP preheat succeeds
P1->>P2: ensure with empty options
P2->>P2: snapshot says runtimeLive true
P2-->>P2: skip preheat keepAliveMs
P2->>P3: prepareMcp then prepareMcpRevision
P3->>P4: initializeWorkspaceMcp once
P4-->>P2: discoveryState completed
Suggestions (non-blocking)
Test evidenceThis is the blocking gap: no CI has executed on this commit. I fetched the real state rather than inferring it, and all four PR CI workflows are parked at
Two notes on reading that table. The The author reports Not verified: whether the new tests pass, whether the diff typechecks, whether it lints — no CI has run on Sandboxed verification would settle the behavioural half: 中文说明代码审查先说我自己的独立方案。 只看标题和"为什么需要",我会写的东西和这里很接近:挂在 preheat 成功的 所以:方案与我的相当,而在 W119 这一点上它比我的第一直觉更好,因为它发现了我没想到的 keep-alive 交互。 Stage 1b 的三个阻断问题都真正修好了。 我逐条对着本 commit 的代码核过,没有只信描述:
没有致命阻断问题。 除了上面三项,我还确认了这里最容易出错的几处: 建议(非阻断)
测试证据这是阻断性缺口:本 commit 上没有任何 CI 执行过。 我是去取真实状态而不是推断的,四个 PR CI workflow 全部停在 读这个表要注意两点。 作者报告本地 未验证:新测试是否通过、diff 是否能 typecheck、是否能过 lint—— 沙箱验证可以解决行为这一半: — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
|
Confidence: 3/5 — the code reads clean and every prior blocker is verifiably fixed, but not one line of CI has run on this commit, and I am not willing to approve a fork's behavioural change on static reading alone. Stepping back: this is a good PR from a contributor who has been unusually responsive. Two rounds of hard feedback — a template rejection, then a substantive Stage 1b that named a throwing getter, a W119 bootstrap-spawn regression, and an overstated symptom — and every point came back fixed rather than argued. Then a Going back to my independent proposal, the PR matches it and beats it on one axis. I would have solved the keep-alive problem with an explicit option; the PR solved it by inferring from the argument shape, which is less surface but worse clarity. That is a real trade, not a mistake, and it is why Suggestion 1 in Stage 2 is a suggestion rather than a blocker. If I had to maintain this in six months I would not curse the author. Seventy-eight production lines, reusing Why I am deferring rather than approving. Not because I doubt the diff — I traced all three fixes to the code at
What unblocks this. One maintainer action, in this order:
Suggestions 1–3 in Stage 2 are genuine but non-blocking and should not hold the merge. One process note so this defer is not invisible: I could not resolve an owner to hand this to. The maintainer handle is unset, the PR carries no area label for the owner map to match, and the only formal reviewer on the thread is this bot — @now-ing's helpful verification comment comes from a 中文说明Confidence: 3/5 —— 代码读起来干净,之前所有阻断问题都可验证地修好了,但这个 commit 上一行 CI 都没跑过;我不愿意仅凭静态阅读就批准一个来自 fork 的行为性改动。 退一步看:这是一个好 PR,作者响应得异常到位。两轮硬反馈——先是模板被退回,然后是实质性的 Stage 1b,点名了一个会抛异常的 getter、一处 W119 bootstrap-spawn 回归、以及一个说过头的症状——每一条都被修好而不是被辩解回来。之后 回到我的独立方案:本 PR 与它相当,并在一个维度上更好。我会用一个显式选项解决 keep-alive 问题;本 PR 用参数形状推断来解决,面积更小但清晰度更差。这是一个真实的取舍,不是错误,也正是为什么 Stage 2 的建议 1 是建议而不是阻断。 如果六个月后由我来维护,我不会骂作者。78 行生产代码,完全按设计复用 为什么我选择 defer 而不是 approve。 不是因为我怀疑这个 diff——我把三处修复都追到了
解锁条件。 一个 maintainer 动作,按此顺序:
Stage 2 的建议 1–3 是真实存在的,但非阻断,不应拖住合并。 一条流程说明,以免这次 defer 变得隐形:我无法解析出该交给谁。maintainer handle 未设置,PR 没有可供 owner map 匹配的 area label,而线程上唯一的正式 reviewer 就是本 bot——@now-ing 那条很有帮助的验证评论来自一个 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
Document EnsureOptions.skipKeepAlivePreheat and the ensure overload so
object-form live-runtime skip is no longer implicit. Log the two boot
early returns, and use skip-path wording when a live snapshot dies
before status().
Avoid polling daemon status after clearing the primary generation so
the skip-no-runtime debug assertion does not race a broken status
read.
|
Addressed Stage 2 suggestions 1–3 on
Local: coordinator 48 passed; |
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
Not explored to full depth (tool budget reached): "agent 6b": did not verify whether concurrent boot work (channel workers, conversation rehydrate, scheduled tasks) holds sessions or runtimeOperationReservations that wou…; "agent 6b": did not read the workspaceMcpStatusCache path in packages/acp-bridge/src/bridge.ts to confirm the first boot status read reaches withWorkspaceControl rath…; "agent 1c": prepareSkills() 's own body was not read, so my statement that boot ensure({}) reaches only prepareSkillsRevision (and never the workspaceSkillsRefresh c…; "agent 1d": none — I did not run the two changed test files under vitest (out of my dimension's remit and expensive against the budget); my conclusions above rest on source…; "agent 4": did not run npm run build && npm run bundle + node scripts/check-serve-fast-path-bundle.js (no dist/esbuild.json , core dist/index.js unbuilt in this wor….
Not reviewed: reverse audit — stopped before round 7 by the review time budget.
Test Plan (not a blocker): 10 passed — this review observed 28691 passed.
Deferred under the convergence posture (round 2, not a blocker) — recorded, not requested in this round:
packages/cli/src/serve/run-qwen-serve.ts:8975 — [probe] nothing pins that boot MCP discovery is gated on preheat success - moving the call to .finally() or hoisting it into completeRuntimeStartup ships green (mutants M1/M2 measured)
中文说明
仅完成部分审查,审查缺口已披露。
未探索到全部深度(达到工具调用预算):"agent 6b":did not verify whether concurrent boot work (channel workers, conversation rehydrate, scheduled tasks) holds sessions or runtimeOperationReservations that wou…;"agent 6b":did not read the workspaceMcpStatusCache path in packages/acp-bridge/src/bridge.ts to confirm the first boot status read reaches withWorkspaceControl rath…;"agent 1c":prepareSkills() 's own body was not read, so my statement that boot ensure({}) reaches only prepareSkillsRevision (and never the workspaceSkillsRefresh c…;"agent 1d":none — I did not run the two changed test files under vitest (out of my dimension's remit and expensive against the budget); my conclusions above rest on source…;"agent 4":did not run npm run build && npm run bundle + node scripts/check-serve-fast-path-bundle.js (no dist/esbuild.json , core dist/index.js unbuilt in this wor…。
未审查:反向审计——评审时间预算不足,未能开始第 7 轮。
Test Plan(非阻断):10 passed — this review observed 28691 passed。
收敛姿态下延后(第 2 轮,非阻断)——已记录,本轮不要求修改:共 1 条(原文未翻译,列表见上方英文部分)。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| const skipKeepAlivePreheat = | ||
| snapshot.runtimeLive && | ||
| options.keepAliveMs === undefined && |
There was a problem hiding this comment.
[Critical] R1-1: (fix-induced) [fails-closed] [regression] The round-1 fix for R1-1 removed the boot keep-alive entirely instead of scoping it, so the preparation this boot step triggers now reaps the very runtime it was scheduled to warm. skipKeepAlivePreheat arms no window at all, and under the default channel-idle policy nothing else holds the preheated ACP child open: the first workspace-control status read the preparation issues drains with resolvedChannelIdleTimeoutMs() === 0, startIdleTimer takes its timeoutMs <= 0 branch and kills the channel before initializeWorkspaceMcp() is ever reached. Boot MCP discovery does not happen, the warm child the preheat paid for is destroyed, the first session pays a cold spawn and a full re-discovery, and startup.preheat.status still reports succeeded.
On a default qwen serve boot, channelIdleTimeoutMs(undefined) returns 0 and the flag's own documented policy is "0 or unset = reap after work drains; keepalive windows may extend it (default)" (packages/cli/src/commands/serve.ts:585-587). Boot bridge.preheat() passes no keepAliveMs, so keepAliveUntil stays 0 and preheat's own finally deliberately arms no timer (settleReleasedRuntimeWork('channel preheat', resolvedChannelIdleTimeoutMs() > 0) evaluates false, bridge.ts:14697-14702) — that is why the warm child survives boot on main. Preheat resolves, the new hook calls ensure({}), snapshot.runtimeLive is true so the skip fires, and prepareSkillsRevision / prepareMcpRevision then issue the first workspace-control reads this daemon has made. Each runs through withWorkspaceControl, whose finally calls startIdleTimer(ci, 'workspace control') once hasNoChannelWork(ci) (bridge.ts:3861-3881) — true here, because there are zero sessions, zero reservations, and workspaceMcpDiscoveryInFlight is still false, beginWorkspaceMcpDiscovery only running inside initializeWorkspaceMcp, which the poll loop never reaches. startIdleTimer computes 0 and calls killChannelWithLog (bridge.ts:3657-3663). prepareMcpRevision then records mcpStatus = 'stale' and ensure() rejects with "Workspace runtime stopped during Skills/MCP preparation", which the boot .catch() reduces to a debug line that is itself invisible (R1-2). An operator following this PR's own "How to verify" is served from workspaceMcpStatusCache with source: 'cache'. A daemon configured with a short --channel-idle-timeout-ms is also worse off than at the round-1 anchor, where numeric ensure() guaranteed a ten-minute window.
Witness:
(1) real bridge + real coordinator probe, channelIdleTimeoutMs UNSET, four arms, 3/3 repeats identical:
PR ensure({})            -> extMethods=[status/workspace/skills, status/workspace/mcp]
                            channelsKilled=[0] postSnapshot{state:"cold",runtimeLive:false}
                            ensure REJECTED cause="Workspace runtime stopped during Skills/MCP preparation"
                            capabilities{mcp:"stale",skills:"stale"}
num ensure() (r1 anchor) -> extMethods=[skills, mcp, control/workspace/mcp/initialize, mcp]
                            channelsKilled=[] runtimeLive:true mcp:"ready" skills:"ready"
fix ensure({keepAliveMs:600000}) -> identical to numeric: initialize sent, channelsKilled=[], ready
BASE preheat only (no ensure)    -> channelsKilled=[] runtimeLive:true mcp:"not_started"
qwen/control/workspace/mcp/initialize is NEVER sent on the PR arm.
(2) paired real-daemon A/B, one script both arms, isolated HOME/QWEN_HOME, ZERO HTTP requests,
    stderr snapshotted 30 s after boot and before any shutdown:
ARM a (PR)  : qwen serve: /acp WebSocket transport enabled on /acp
              qwen serve: channel exited (code=0, signal=none, transport=ndjson_unexpected_eof, 0 session(s) torn down)
ARM b (base): qwen serve: /acp WebSocket transport enabled on /acp
              --- channel-exit lines in that window --- NONE
Do not let boot workspace work run unheld. The measured-good arm is void coordinator.ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }).catch(...) at run-qwen-serve.ts:8955, which the new options.keepAliveMs === undefined conjunct already routes to the preheat branch and which behaves identically to the round-1 numeric call: one spawn, no kill, discovery reaches ready. If a ten-minute daemon-wide lease at boot is not wanted, hold the channel for the preparation instead through pendingKeepAliveDeadlines (which resolvedChannelIdleTimeoutMs() also reads, and which preheat deletes in its finally) with a bound of at least MCP_PREPARE_TIMEOUT_MS. If the maintainer position is that the warm child should be reaped at boot, then this step cannot achieve its stated outcome and run-qwen-serve.ts:8955 should be dropped rather than left to fail into an invisible debug line.
Two same-root clauses ride with this fix, both measured, so they do not return as separate findings next round:
- The new JSDoc at
:31-33— "so daemon boot after ACP warm-up does not re-arm the HTTP 10-minute window" — is already false without any race, becausesnapshot.runtimeLive &&means a boot hook that finds the channel already reaped takes the non-skip branch and armsoptions.keepAliveMs ?? ENSURE_KEEP_ALIVE_MSitself (measuredPROBE_P5_ARMED_600K 1, andPROBE_P1_PREHEAT_CALLS [{"keepAliveMs":600000},{"keepAliveMs":600000}]), and it becomes false by design once the fix above lands. Correct that sentence in the same change; and sinceskipKeepAlivePreheathas no production writer, decide there whether the whole skip option stays as documented defensive surface or goes. Relatedly, the skip-path message'Runtime is not live after skipping keep-alive preheat'at:224-226cannot fire in shipped code — there is noawaitbetween the:200snapshot read and the:220status()read, measured 0 of 240 faithful-bridge rows — so if the option goes, that arm and its test go with it. - The new boot test currently pins the defect as correct and blocks three separate remediations. Against the fix arm the assertions go red in this order:
expect(ensureSpy).toHaveBeenCalledWith({})atrun-qwen-serve.test.ts:16581first, thenexpect(bridge.preheat).toHaveBeenCalledTimes(1)at:16585(:16573does not go red — it runs beforeresolvePreheat()), then the'keepAliveMs' in argscan at:16586-16596. Arming the lease in the startup preheat instead is blocked too, at:16574. So invert the scan to a value pin rather than deleting it or making it a presence pin:expect(bridge.preheat).toHaveBeenNthCalledWith(2, { keepAliveMs: 600_000 })passes with the fix, reddens when only the boot call is reverted toensure({}), and reddens when boot arms{ keepAliveMs: 0 }— whereas a presence-only inversion stays green under a zero-valued arming, becausebridge.ts:14662-14668gates onrawKeepAliveMs > 0.
The fix must not violate this: keepAliveUntil is process-wide bridge state that only ever grows — let keepAliveUntil = 0; (packages/acp-bridge/src/bridge.ts:3003), written solely by keepAliveUntil = Math.max(keepAliveUntil, Date.now() + keepAliveMs) (:14684-14687) and feeding Math.max(configured, keepAliveUntil - now, pendingKeepAliveMs) (:3651) — so arming ENSURE_KEEP_ALIVE_MS = 10 * 60_000 (workspace-runtime-coordinator.ts:22) at boot holds the child ten minutes daemon-wide against the documented default at packages/cli/src/commands/serve.ts:585-587, and any window must be at least MCP_PREPARE_TIMEOUT_MS = 2 * 60_000, the deadline prepareMcpRevision polls against (:578).
Please pin the fix with a test that fails without it: a coordinator case whose harness bridge models the reap — a workspace-control read that drains with no keep-alive armed flips runtimeLive to false, mirroring bridge.ts:3657-3663 plus :3874-3879 — asserting that ensure on an already-live runtime still reaches initializeWorkspaceMcp and leaves runtimeLive: true with capabilities.mcp.state === 'ready'. Remove the hold and that test must go red; today both new tests mock the bridge, so neither can observe the reap.
中文说明
第一轮 R1-1 的修复把启动期的 keep-alive 整个去掉了,而不是把它收窄,于是这个启动步骤所触发的准备工作,现在会回收掉它本来要预热的那个 runtime。skipKeepAlivePreheat 完全没有挂上任何窗口,而在默认的 channel 空闲策略下也没有别的东西撑着这个已预热的 ACP 子进程:准备工作发出的第一个 workspace-control 状态读取在排空时 resolvedChannelIdleTimeoutMs() === 0,startIdleTimer 走进 timeoutMs <= 0 分支,在 initializeWorkspaceMcp() 被调用之前就把 channel 杀掉了。启动期的 MCP discovery 没有发生,preheat 花钱预热的子进程被销毁,第一个 session 要付冷启动和一次完整重新 discovery 的代价,而 startup.preheat.status 仍然报告 succeeded。
默认的 qwen serve 启动下,channelIdleTimeoutMs(undefined) 返回 0,而这个参数自己的文档契约是「0 or unset = reap after work drains; keepalive windows may extend it (default)」(packages/cli/src/commands/serve.ts:585-587)。启动时的 bridge.preheat() 不传 keepAliveMs,所以 keepAliveUntil 保持 0,preheat 自己的 finally 也刻意不挂定时器(settleReleasedRuntimeWork('channel preheat', resolvedChannelIdleTimeoutMs() > 0) 求值为 false,bridge.ts:14697-14702)——这正是 main 上预热子进程能在启动后存活的原因。preheat resolve 之后,新的 hook 调用 ensure({}),snapshot.runtimeLive 为 true 于是跳过生效,接着 prepareSkillsRevision / prepareMcpRevision 发出这个守护进程的第一批 workspace-control 读取。每一次都经过 withWorkspaceControl,其 finally 在 hasNoChannelWork(ci) 成立时调用 startIdleTimer(ci, 'workspace control')(bridge.ts:3861-3881)——这里成立,因为没有 session、没有 reservation,而 workspaceMcpDiscoveryInFlight 仍为 false(beginWorkspaceMcpDiscovery 只在 initializeWorkspaceMcp 内部执行,而轮询循环根本到不了那里)。startIdleTimer 算出 0 并调用 killChannelWithLog(bridge.ts:3657-3663)。随后 prepareMcpRevision 记录 mcpStatus = 'stale',ensure() 以「Workspace runtime stopped during Skills/MCP preparation」reject,而启动处的 .catch() 把它压缩成一行本身不可见的 debug 日志(见 R1-2)。一位按本 PR 自己的「How to verify」操作的运维者,拿到的是 workspaceMcpStatusCache 里 source: 'cache' 的载荷。配置了较短 --channel-idle-timeout-ms 的守护进程也比第一轮锚点时更糟——那时数值形式的 ensure() 保证了十分钟窗口。
证据:
(1) 真实 bridge + 真实 coordinator 探针,channelIdleTimeoutMs 未设置,四个 arm,3/3 次重复结果一致:
PR ensure({})            -> extMethods=[status/workspace/skills, status/workspace/mcp]
                            channelsKilled=[0] postSnapshot{state:"cold",runtimeLive:false}
                            ensure REJECTED cause="Workspace runtime stopped during Skills/MCP preparation"
                            capabilities{mcp:"stale",skills:"stale"}
num ensure() (第一轮锚点) -> extMethods=[skills, mcp, control/workspace/mcp/initialize, mcp]
                            channelsKilled=[] runtimeLive:true mcp:"ready" skills:"ready"
fix ensure({keepAliveMs:600000}) -> 与数值形式一致:发出 initialize,channelsKilled=[],ready
BASE 只 preheat(不 ensure)    -> channelsKilled=[] runtimeLive:true mcp:"not_started"
PR arm 上 qwen/control/workspace/mcp/initialize 从未被发出。
(2) 配对的真实守护进程 A/B,两侧同一脚本,隔离的 HOME/QWEN_HOME,零 HTTP 请求,
    启动后 30 秒、任何 shutdown 之前抓取 stderr:
ARM a (PR)  : qwen serve: /acp WebSocket transport enabled on /acp
              qwen serve: channel exited (code=0, signal=none, transport=ndjson_unexpected_eof, 0 session(s) torn down)
ARM b (base): qwen serve: /acp WebSocket transport enabled on /acp
              --- 该窗口内的 channel-exit 行 --- 无
不要让启动期的 workspace 工作在无人持有的情况下运行。实测可用的方案是在 run-qwen-serve.ts:8955 改成 void coordinator.ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }).catch(...)——新增的 options.keepAliveMs === undefined 这一项已经会把它路由到 preheat 分支,其行为与第一轮的数值调用完全一致:一次 spawn、不被杀、discovery 到达 ready。如果不希望启动时挂上十分钟的全守护进程租约,就改用 pendingKeepAliveDeadlines 在准备工作期间持有 channel(resolvedChannelIdleTimeoutMs() 也会读它,而 preheat 在其 finally 里删除它),下限不低于 MCP_PREPARE_TIMEOUT_MS。如果 maintainer 的立场就是启动时应当回收这个热子进程,那么这个步骤无法达成它声称的结果,应当直接删掉 run-qwen-serve.ts:8955,而不是留着它失败进一行看不见的 debug 日志。
有两条同根因的条款随本修复一起处理,均已实测,以免下一轮作为独立发现再次出现:
:31-33新增的 JSDoc——「so daemon boot after ACP warm-up does not re-arm the HTTP 10-minute window」——在没有任何竞态的情况下就已经是假的:snapshot.runtimeLive &&意味着一个发现 channel 已被回收的启动 hook 会走非跳过分支,自己挂上options.keepAliveMs ?? ENSURE_KEEP_ALIVE_MS(实测PROBE_P5_ARMED_600K 1,以及PROBE_P1_PREHEAT_CALLS [{"keepAliveMs":600000},{"keepAliveMs":600000}]),而上面的修复落地后它会变成设计上的假。请在同一次改动里修正这句话;并且由于skipKeepAlivePreheat没有任何生产写入者,请在那里一并决定整个 skip 选项是作为有文档的防御性表面保留,还是删除。相关地,:224-226的跳过路径消息'Runtime is not live after skipping keep-alive preheat'在实际代码中不可能触发——:200的快照读取与:220的status()读取之间没有await,实测 240 行忠实 bridge 组合中 0 行触发——所以如果该选项被删除,那个分支和它的测试应一起删除。- 新的启动测试目前把该缺陷钉成了正确行为,并且挡住了三种不同的修法。在修复 arm 下断言按此顺序变红:先是
run-qwen-serve.test.ts:16581的expect(ensureSpy).toHaveBeenCalledWith({}),然后是:16585的expect(bridge.preheat).toHaveBeenCalledTimes(1)(:16573不会变红——它在resolvePreheat()之前执行),最后是:16586-16596的'keepAliveMs' in arg扫描。改为在启动 preheat 处挂租约同样被挡住,位置在:16574。所以请把这个扫描反转成值断言,而不是删掉它或改成存在性断言:expect(bridge.preheat).toHaveBeenNthCalledWith(2, { keepAliveMs: 600_000 })在修复后通过,在只把启动调用改回ensure({})时变红,在启动挂{ keepAliveMs: 0 }时也变红——而仅做存在性反转在零值挂载下仍然是绿的,因为bridge.ts:14662-14668以rawKeepAliveMs > 0为条件。
修复不得违反这一点:keepAliveUntil 是进程级、只增不减的 bridge 状态——let keepAliveUntil = 0;(packages/acp-bridge/src/bridge.ts:3003),唯一写入点是 keepAliveUntil = Math.max(keepAliveUntil, Date.now() + keepAliveMs)(:14684-14687),并参与 Math.max(configured, keepAliveUntil - now, pendingKeepAliveMs)(:3651)——因此在启动时挂 ENSURE_KEEP_ALIVE_MS = 10 * 60_000(workspace-runtime-coordinator.ts:22)会让子进程在全守护进程范围内被持有十分钟,与 packages/cli/src/commands/serve.ts:585-587 的文档默认值相冲突;任何窗口都不得小于 MCP_PREPARE_TIMEOUT_MS = 2 * 60_000,即 prepareMcpRevision 轮询所用的截止时间(:578)。
请用一个「去掉修复就会变红」的测试把它钉住:一个 coordinator 用例,其 harness bridge 建模这次回收——一个在没挂 keep-alive 的情况下排空的 workspace-control 读取会把 runtimeLive 翻成 false,对应 bridge.ts:3657-3663 加 :3874-3879——断言在已 live 的 runtime 上 ensure 仍然到达 initializeWorkspaceMcp,并保持 runtimeLive: true 与 capabilities.mcp.state === 'ready'。去掉这个持有,该测试必须变红;今天两个新测试都 mock 了 bridge,因此都观察不到这次回收。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| import { | ||
| createDebugLogger, | ||
| type AuthType, |
There was a problem hiding this comment.
[Critical] R2-1: [fails-closed] [regression] Adding createDebugLogger here turned a type-only import of the core barrel into a runtime one, which pulls @qwen-code/qwen-code-core's whole barrel — the core shell tool runtime plus four forbidden vendor packages — into the static closure of a serve pre-listen root. The repository's own bundle-closure gate fails on this diff, so the CI step Check serve fast-path bundle closure goes red and qwen serve cannot ship as written.
packages/cli/src/serve/run-qwen-serve.ts is one of the three SERVE_PRE_LISTEN_ROOTS in scripts/check-serve-fast-path-bundle.js, and that guard fails when any input in the roots' static closure matches FORBIDDEN_SOURCE_INPUTS (which includes "Core shell tool runtime": packages/core/src/tools/shell.ts) or FORBIDDEN_VENDOR_PACKAGES (glob, chokidar, @iarna/toml, fzf). packages/core/src/index.ts re-exports ./tools/shell.js, and that module is not tree-shakeable — it has a module-scope createDebugLogger('SHELL') and packages/core/package.json declares no "sideEffects": false. The diff deleted import type { AuthType, ProviderSetupInputs, TelemetryRuntimeConfig, TelemetrySettings } from '@qwen-code/qwen-code-core', which was erased at build time and is what kept the barrel out of this file's pre-listen() closure, and nothing re-establishes that erasure. Beyond the gate: packages/cli/src/serve/fast-path.ts reaches this file only through await import('./run-qwen-serve.js') precisely so the daemon can listen() before core loads, so a static barrel import makes the pre-listen path evaluate all of core first and regresses the processToListenMs / runQwenServeToListenMs this same file reports. No unit test or lint rule catches it — eslint.config.js has no no-restricted-imports entry for the core barrel in serve files, and fast-path.test.ts's forbiddenExternalImports list omits it — so apart from that one CI step it ships silently.
Witness:
The authoritative gate, run at this commit (DEV=true node esbuild.config.js to produce
dist/esbuild.json, then node scripts/check-serve-fast-path-bundle.js):

INTACT PR: Serve fast-path bundle closure includes pre-listen runtime modules:
 - Core shell tool runtime input: packages/core/src/tools/shell.ts
   static path: dist/chunks/run-qwen-serve-JTCTK23A.js -> dist/chunks/chunk-BEMNIFZZ.js
 - @iarna/toml vendor package (13 inputs) ... chunk-BEMNIFZZ.js (6202805 bytes)
 - chokidar vendor package (2 inputs) ... chunk-BEMNIFZZ.js (6202805 bytes)
 - glob vendor package (14 inputs) ... chunk-BCSHNYZI.js (213905 bytes)
 - fzf vendor package ... chunk-JB3DAHN3.js (608668 bytes)
 GATE_EXIT=1
REVERTED (only this import restored to `import type { ... }` plus a local logger stub,
          same tree, same harness, rebuilt):
 Startup bundle closure checks passed.
 GATE_EXIT_AFTER_FIX=0

33 offenders, all attributable to this one import. Independently re-checked:
packages/cli/dist/src/serve/run-qwen-serve.js:29 is
  import { createDebugLogger, } from '@qwen-code/qwen-code-core';
and bundling that file as-is yields 3517 inputs / 36.1 MB including chokidar and
@iarna/toml, versus 1649 inputs / 21.2 MB with the barrel marked external.
.github/workflows/ci.yml:1201-1203 runs exactly this script.
Keep the pre-listen root off the barrel. Restore import type { AuthType, ProviderSetupInputs, TelemetryRuntimeConfig, TelemetrySettings } from '@qwen-code/qwen-code-core'; and obtain the logger without it — either add a "./debugLogger" entry to packages/core/package.json exports (following the existing ./envVarResolver and ./memoryScopes entries) and import from @qwen-code/qwen-code-core/debugLogger, or import the already-allowed narrow path @qwen-code/qwen-code-core/dist/src/utils/debugLogger.js, or resolve it lazily through the existing serve/core-runtime.ts shim / the let-injected pattern this file already uses for getWorkspaceRuntimeCoordinatorIfSupported. Dropping the new import entirely and logging these three boot diagnostics through the daemonLog already in scope would fix R1-2's channel half at the same time.
The fix must not violate this: packages/cli/src/serve/types.ts:17-19 — "Type-only, so it is erased before the serve fast-path bundle closure check ever sees it." — states the invariant this file's own comment at :88-92 repeats for dynamic imports, and packages/core/package.json currently exports no ./debugLogger subpath (the exported set is ./transcriptRecords, ./envVarResolver, ./goalWire, ./memoryScopes, ./subSessionConstants, ./toolWriteOrigin, ./userPromptSubmitContext, ./noFollowOpen, ./conversationsRuntimeMarker), so the subpath fix must add an entry there.
Please pin this with a check that fails without the fix: npm run check:serve-fast-path-bundle must go red if the barrel value import is restored, and is green after it (measured GATE_EXIT 1 then 0). No packages/cli unit test pins this file's static import closure today, so that CI step is the only witness; optionally add '@qwen-code/qwen-code-core' to the forbiddenExternalImports array of packages/cli/src/serve/fast-path.test.ts, which already computes graph.externalValueImports — it must go red against this diff and green after the fix. Note that if the three call sites move to daemonLog, two of the new tests break, since they read qwenCore.Storage.getDebugLogPath(debugSessionId) and assert the exact skip messages.
中文说明
在这里加入 createDebugLogger,把原本 type-only 的 core barrel 导入变成了运行时导入,于是 @qwen-code/qwen-code-core 的整个 barrel——core shell tool runtime 加上四个被禁止的 vendor 包——被拉进了 serve pre-listen root 的静态闭包。仓库自己的 bundle 闭包关卡在这个 diff 上失败,因此 CI 步骤 Check serve fast-path bundle closure 会变红,qwen serve 按现在的写法无法发布。
packages/cli/src/serve/run-qwen-serve.ts 是 scripts/check-serve-fast-path-bundle.js 中三个 SERVE_PRE_LISTEN_ROOTS 之一,而该关卡在这些 root 的静态闭包中任何输入命中 FORBIDDEN_SOURCE_INPUTS(包含「Core shell tool runtime」:packages/core/src/tools/shell.ts)或 FORBIDDEN_VENDOR_PACKAGES(glob、chokidar、@iarna/toml、fzf)时即失败。packages/core/src/index.ts 再导出了 ./tools/shell.js,而该模块不可被 tree-shake——它有一个模块级的 createDebugLogger('SHELL'),且 packages/core/package.json 没有声明 "sideEffects": false。本 diff 删掉了 import type { AuthType, ProviderSetupInputs, TelemetryRuntimeConfig, TelemetrySettings } from '@qwen-code/qwen-code-core'——它在构建时被擦除,正是它让 barrel 不进入本文件 listen() 之前的闭包——而没有任何东西重新建立这种擦除。除关卡之外:packages/cli/src/serve/fast-path.ts 只通过 await import('./run-qwen-serve.js') 到达本文件,目的就是让守护进程能在 core 加载之前 listen(),因此静态的 barrel 导入会让 pre-listen 路径先求值整个 core,并使本文件自己上报的 processToListenMs / runQwenServeToListenMs 退化。没有单测或 lint 规则能抓到它——eslint.config.js 没有针对 serve 文件中 core barrel 的 no-restricted-imports 条目,fast-path.test.ts 的 forbiddenExternalImports 列表也没有它——所以除了那一个 CI 步骤之外,它会静默发布。
证据:
权威关卡,在本 commit 上运行(DEV=true node esbuild.config.js 生成 dist/esbuild.json,
然后 node scripts/check-serve-fast-path-bundle.js):

INTACT PR: Serve fast-path bundle closure includes pre-listen runtime modules:
 - Core shell tool runtime input: packages/core/src/tools/shell.ts
   static path: dist/chunks/run-qwen-serve-JTCTK23A.js -> dist/chunks/chunk-BEMNIFZZ.js
 - @iarna/toml vendor package (13 inputs) ... chunk-BEMNIFZZ.js (6202805 bytes)
 - chokidar vendor package (2 inputs) ... chunk-BEMNIFZZ.js (6202805 bytes)
 - glob vendor package (14 inputs) ... chunk-BCSHNYZI.js (213905 bytes)
 - fzf vendor package ... chunk-JB3DAHN3.js (608668 bytes)
 GATE_EXIT=1
REVERTED(只把这一处导入改回 `import type { ... }` 并加一个本地 logger 桩,
          同一棵树、同一套 harness、重新构建):
 Startup bundle closure checks passed.
 GATE_EXIT_AFTER_FIX=0

33 处 offender,全部可归因于这一处导入。独立复核:
packages/cli/dist/src/serve/run-qwen-serve.js:29 是
  import { createDebugLogger, } from '@qwen-code/qwen-code-core';
直接打包该文件得到 3517 个输入 / 36.1 MB,包含 chokidar 与 @iarna/toml;
而把该 barrel 标为 external 后为 1649 个输入 / 21.2 MB。
.github/workflows/ci.yml:1201-1203 运行的正是这个脚本。
请把 pre-listen root 与 barrel 隔离。恢复 import type { AuthType, ProviderSetupInputs, TelemetryRuntimeConfig, TelemetrySettings } from '@qwen-code/qwen-code-core';,并用不经过 barrel 的方式取得 logger——要么在 packages/core/package.json 的 exports 中新增 "./debugLogger" 条目(参照已有的 ./envVarResolver 与 ./memoryScopes),从 @qwen-code/qwen-code-core/debugLogger 导入;要么导入已被允许的窄路径 @qwen-code/qwen-code-core/dist/src/utils/debugLogger.js;要么通过已有的 serve/core-runtime.ts shim、或本文件对 getWorkspaceRuntimeCoordinatorIfSupported 已在使用的那套 let 注入方式延迟解析。也可以完全去掉这个新导入,把这三条启动诊断改用在作用域内的 daemonLog——那样会同时修掉 R1-2 的通道那一半。
修复不得违反这一点:packages/cli/src/serve/types.ts:17-19——「Type-only, so it is erased before the serve fast-path bundle closure check ever sees it.」——正是本文件 :88-92 注释针对动态导入重复的那条不变量;而 packages/core/package.json 目前没有导出 ./debugLogger 子路径(已导出的集合是 ./transcriptRecords、./envVarResolver、./goalWire、./memoryScopes、./subSessionConstants、./toolWriteOrigin、./userPromptSubmitContext、./noFollowOpen、./conversationsRuntimeMarker),所以子路径方案必须在那里新增条目。
请用一个「去掉修复就会失败」的检查钉住它:如果把 barrel 的值导入恢复回去,npm run check:serve-fast-path-bundle 必须变红,修复后为绿(实测 GATE_EXIT 先 1 后 0)。目前没有任何 packages/cli 单测钉住本文件的静态导入闭包,所以那个 CI 步骤是唯一的见证;也可以选择把 '@qwen-code/qwen-code-core' 加入 packages/cli/src/serve/fast-path.test.ts 的 forbiddenExternalImports 数组——它已经计算 graph.externalValueImports——该断言必须在本 diff 上变红、修复后变绿。注意:如果把三个调用点改到 daemonLog,两个新测试会失败,因为它们读取 qwenCore.Storage.getDebugLogPath(debugSessionId) 并断言精确的 skip 文案。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| debugLogger.debug( | ||
| `workspace MCP discovery after preheat failed: ${message}`, | ||
| ); |
There was a problem hiding this comment.
[Suggestion] R1-2: still stands. The diagnostic this round added in answer to R1-2 cannot reach an operator, on two independent counts: debugLogger.debug is a no-op in a daemon because nothing in the serve process ever binds a debug-log session, and the line prints only err.message, which for every ensure failure is the constant wrapper string while the real reason sits in err.cause. So an operator who follows this PR's own "How to verify" and sees discoveryState: 'not_started' still has no breadcrumb separating "the fix did not run", "the fix ran and failed" and "this build predates the fix".
writeLog returns early unless QWEN_DEBUG_LOG_FILE is truthy (packages/core/src/utils/debugLogger.ts:44-49, :119-121) and debug additionally returns early when getActiveSession() is null (:283-290); QWEN_DEBUG_LOG_FILE is only set under --debug (packages/cli/src/config/config.ts:1491-1493) and setDebugLogSession has no non-test caller in packages/cli/src. Even with the env var set explicitly the daemon process never binds a session — only the spawned ACP child does, via Config construction. And when the line is not dropped, its content is not useful: ensure reports every preparation failure as WorkspaceRuntimeInitializationError, whose message is the constant "Workspace runtime failed to initialize" with the reason in cause (workspace-runtime-coordinator.ts:49-55), so the two distinguishing messages this diff introduced never appear in any log. Meanwhile the sibling failure ten lines below writes writeStderrLine('qwen serve: ACP preheat failed, will retry on first session: …') and records startup.preheat.error, the rest of the startup family uses daemonLog.info/warn — the log whose path qwen serve prints at startup — and GET /workspace/runtime/status shows only not_started/stale, indistinguishable from "boot discovery was never attempted". This sits in a block of tests named runQwenServe startup observability. It also interacts with the missing shuttingDown guard reported separately: once this branch is escalated to an operator-visible channel, an ordinary shutdown that races a boot starts emitting a spurious failure warning, so the two are worth fixing together.
Witness:
Real daemon, QWEN_DEBUG_LOG_FILE=1 set explicitly, whole temp QWEN_HOME grepped after a
30 s boot in which the boot step demonstrably failed:
  --- QWEN_SERVE (daemon-side debugLogger) lines anywhere in QWEN_HOME --- NONE
  --- boot discovery diagnostic anywhere in the temp home --- NONE
  (the ACP child wrote /tmp/.../qwen/debug/<sessionId>.txt; the daemon wrote nothing)
Content half, measured rather than read:
  ensureError      = "WorkspaceRuntimeInitializationError: Workspace runtime failed to initialize"
  ensureErrorCause = "Error: Workspace runtime stopped during Skills/MCP preparation"
and the catch site keeps only the former.
Keep the two benign skip branches at debug level — they are expected conditions — but escalate the failure branch to the channel the sibling uses, and append the cause:
void coordinator.ensure({}).catch((err) => {
  const cause =
    err instanceof Error && err.cause instanceof Error
      ? `${err.message}: ${err.cause.message}`
      : err instanceof Error
        ? err.message
        : String(err);
  daemonLog.warn('workspace MCP discovery after preheat failed', {
    workspace: runtime.workspaceCwd,
    error: cause,
  });
});
DaemonLogger has info/warn/error/raw and no debug level (daemon-logger.ts:202-208), so escalating is not a duplicate channel. If R2-1's fix already moves these call sites off createDebugLogger, land the two together.
The fix must not violate this: the logging cannot be allowed to throw into the preheat chain, because this callback runs inside preheat's .then() and the adjacent .catch sets startup.preheat.status = 'failed' and prints "ACP preheat failed, will retry on first session" — a synchronous throw here would rewrite a succeeded preheat, exactly the regression the non-throwing primary lookup was introduced to avoid. debugLogger.debug cannot throw synchronously (writeLog ends in void ensureDebugDirExists().then(...).catch(...), debugLogger.ts:139-151); a daemonLog.warn call must preserve that property. It is also worth deciding whether the expected drain and generation-closed races should stay quiet rather than print on every shutdown.
Please pin this with a test that fails without it: does not leak an unhandled rejection when boot MCP discovery fails already mocks ensure to throw but asserts only that rejections is empty, so replacing the catch body with .catch(() => {}) or dropping just the log call leaves it green today. Extend it to assert the operator-visible line is emitted, and have the spy reject with new WorkspaceRuntimeInitializationError(new Error('cause detail')) so the same assertion pins the cause. No current test covers the failure-branch message text at all — the two log-assertion tests cover only the "lifecycle is not supported" and "no primary runtime" skip branches.
中文说明
R1-2 仍然成立。本轮为回应 R1-2 而加的诊断无法到达运维者,有两个独立原因:debugLogger.debug 在守护进程里是空操作,因为 serve 进程从不绑定 debug-log session;而这行只打印 err.message——对每一次 ensure 失败而言它都是那个固定的包装字符串,真正的原因在 err.cause 里。所以一位按本 PR 自己的「How to verify」操作、看到 discoveryState: 'not_started' 的运维者,仍然没有任何线索能区分「修复没跑」「修复跑了但失败」和「这个构建早于该修复」。
writeLog 在 QWEN_DEBUG_LOG_FILE 非真时提前返回(packages/core/src/utils/debugLogger.ts:44-49、:119-121),而 debug 在 getActiveSession() 为 null 时还会再提前返回一次(:283-290);QWEN_DEBUG_LOG_FILE 只在 --debug 下被设置(packages/cli/src/config/config.ts:1491-1493),且 setDebugLogSession 在 packages/cli/src 中没有非测试调用方。即便显式设置该环境变量,守护进程也从不绑定 session——只有被拉起的 ACP 子进程会通过构造 Config 绑定。而当这行没有被丢弃时,它的内容也没用:ensure 把每一次准备失败都报成 WorkspaceRuntimeInitializationError,其 message 是固定的「Workspace runtime failed to initialize」,原因在 cause 中(workspace-runtime-coordinator.ts:49-55),于是本 diff 引入的两条可区分消息永远不会出现在任何日志里。与此同时,下方十行处的同类失败会写 writeStderrLine('qwen serve: ACP preheat failed, will retry on first session: …') 并记录 startup.preheat.error,启动路径的其余部分用 daemonLog.info/warn——也就是 qwen serve 启动时打印路径的那个日志——而 GET /workspace/runtime/status 只显示 not_started/stale,与「启动 discovery 根本没尝试过」无法区分。这处代码正位于名为 runQwenServe startup observability 的测试块中。它还与另一处单独报告的缺失 shuttingDown 判断相互作用:一旦这个分支被提升到运维者可见的通道,一次与启动竞态的普通 shutdown 就会开始发出虚假的失败告警,所以两者值得一起修。
证据:
真实守护进程,显式设置 QWEN_DEBUG_LOG_FILE=1,在启动步骤确实失败的一次 30 秒启动之后
对整个临时 QWEN_HOME 做 grep:
  --- QWEN_HOME 中任何位置的 QWEN_SERVE(守护进程侧 debugLogger)行 --- 无
  --- 临时 home 中任何位置的启动 discovery 诊断 --- 无
  (ACP 子进程写了 /tmp/.../qwen/debug/<sessionId>.txt;守护进程什么都没写)
内容那一半,实测而非阅读:
  ensureError      = "WorkspaceRuntimeInitializationError: Workspace runtime failed to initialize"
  ensureErrorCause = "Error: Workspace runtime stopped during Skills/MCP preparation"
而 catch 处只保留了前者。
两个良性的 skip 分支保持 debug 级别即可——它们是预期内的状态——但请把失败分支提升到同类代码使用的通道,并把 cause 一并拼上(代码见上)。DaemonLogger 有 info/warn/error/raw 而没有 debug 级别(daemon-logger.ts:202-208),所以提升不是重复通道。如果 R2-1 的修复已经把这些调用点从 createDebugLogger 移走,请把两者一起落地。
修复不得违反这一点:日志本身不能被允许抛进 preheat 链,因为这个回调运行在 preheat 的 .then() 内部,而相邻的 .catch 会把 startup.preheat.status 置为 'failed' 并打印「ACP preheat failed, will retry on first session」——此处的同步抛错会把一次成功的 preheat 改写成失败,而那正是引入非抛异常 primary 查找要避免的回归。debugLogger.debug 不会同步抛错(writeLog 以 void ensureDebugDirExists().then(...).catch(...) 结束,debugLogger.ts:139-151);改成 daemonLog.warn 必须保持这一性质。另外值得决定:预期内的 drain 与 generation-closed 竞态是否应保持安静,而不是每次关闭都打印。
请用一个「去掉修复就会变红」的测试钉住它:does not leak an unhandled rejection when boot MCP discovery fails 已经把 ensure mock 成抛错,但只断言 rejections 为空,所以今天把 catch 体换成 .catch(() => {})、或只删掉那行日志,它仍然是绿的。请扩展它,断言运维者可见的那一行被写出,并让 spy 以 new WorkspaceRuntimeInitializationError(new Error('cause detail')) reject,从而同一个断言也钉住 cause。目前没有任何测试覆盖失败分支的文案——两个日志断言测试只覆盖「lifecycle is not supported」和「no primary runtime」这两个 skip 分支。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| export type EnsureOptions = { | ||
| timeoutMs?: number; | ||
| keepAliveMs?: number; |
There was a problem hiding this comment.
[Suggestion] R2-2: EnsureOptions.timeoutMs and .keepAliveMs are declared, documented and read but set by no caller anywhere in the repository, and the exported type has zero importers — the dead-switch shape AGENTS.md names explicitly. Worse, skipKeepAlivePreheat's default is derived from the argument's syntactic form, so ensure(30_000) and ensure({ timeoutMs: 30_000 }) — the same intent, two spellings — silently differ by a ten-minute keep-alive renewal, with no type error and no failing test. The sole production object-form caller passes a bare {}, so the flag that changes behaviour is invisible where it is used.
The trap is concrete: a maintainer bounds the client-facing warm-up by rewriting await coordinator.ensure() as await coordinator.ensure({ timeoutMs: 30_000 }) in routes/workspace-runtime.ts:64 — the route whose whole purpose is the renewal. Both spellings type-check and look equivalent, but options.skipKeepAlivePreheat ?? typeof timeoutMsOrOptions !== 'number' now defaults the skip to true, so on an already-live runtime bridge.preheat({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }) is never issued and keepAliveUntil is never extended: the ACP child becomes reapable the moment the route's own workspace-control work settles. Two further traps are measured: ensure({ skipKeepAlivePreheat: true, keepAliveMs: 60_000 }) discards the explicit true (keepAliveMs wins by precedence, and the JSDoc describes a default rather than an override), and ensure({ keepAliveMs: 0 }) makes the === undefined conjunct false so the preheat runs as preheat({ keepAliveMs: 0 }), which bridge.ts:14662-14668 treats as no window at all while ensure proceeds as if one had been requested. The exported type also advertises configurability the only HTTP surface explicitly forbids — routes/workspace-runtime.ts:56-62 rejects any request body with "Workspace runtime ensure does not accept parameters".
Witness:
Sweep over the real population (whole repo, dist/ excluded):
  EnsureOptions importers: 2 hits, both inside workspace-runtime-coordinator.ts
                           (:26 declaration, :191 parameter type) - ZERO external importers
  production callers of coordinator.ensure: 2 - routes/workspace-runtime.ts:64 `ensure()`;
                                                run-qwen-serve.ts:8955 `ensure({})`
  `skipKeepAlivePreheat` writers: 4, all in workspace-runtime-coordinator.test.ts
  `timeoutMs` / `keepAliveMs` writers: 0 (no caller, production or test)
The trap, measured on a mock-bridge harness with a live runtime:
  live ensure()                                               -> preheat calls=1 args=[[{"keepAliveMs":600000}]]
  live ensure(30_000)                                         -> preheat calls=1 args=[[{"keepAliveMs":600000}]]
  live ensure({})                                             -> preheat calls=0 args=[]
  live ensure({timeoutMs:30_000})                             -> preheat calls=0 args=[]   <-- the look-alike rewrite
  live ensure({skipKeepAlivePreheat:true,keepAliveMs:60_000})  -> preheat calls=1 args=[[{"keepAliveMs":60000}]]
  live ensure({keepAliveMs:0})                                -> preheat calls=1 args=[[{"keepAliveMs":0}]]
Shrink the option to what the one caller needs and make the switch explicit where it is used. Reduce the type to { skipKeepAlivePreheat?: boolean } (the numeric parameter already covers timeoutMs), compute the skip as snapshot.runtimeLive && options.skipKeepAlivePreheat === true so it is opt-in rather than form-derived, restore this.bridge.preheat({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }), delete the "(unless keepAliveMs is set)" clause from both doc comments, and have the boot site say what it means: void coordinator.ensure({ skipKeepAlivePreheat: true }).catch(...). If a keep-alive override is genuinely wanted, keep it, validate keepAliveMs > 0, and add a test that sets it. Note the interaction with R1-1: if its fix arms a window at boot via keepAliveMs, this option's shape has to be decided in the same change.
The fix must not violate this: const ENSURE_KEEP_ALIVE_MS = 10 * 60_000; (workspace-runtime-coordinator.ts:22) is what the no-argument path must keep passing to bridge.preheat — pinned as { keepAliveMs: 600_000 } by routes/workspace-runtime.test.ts:102, server.test.ts:5898 and workspace-runtime-coordinator.test.ts:876-878 — and res.status(200).json(await coordinator.ensure()); (routes/workspace-runtime.ts:64) is a shipped caller of that form. Three other in-file sites depend on the same constant (:433, :534, :581).
Please pin the chosen shape with a test that fails without it: run-qwen-serve.test.ts asserts expect(ensureSpy).toHaveBeenCalledWith({}) at :16581, which must become { skipKeepAlivePreheat: true } under the explicit-flag fix — that assertion is then what goes red if the call site reverts to the opaque {}. The two existing coordinator cases (expect(harness.preheat).not.toHaveBeenCalled() and expect(harness.preheat).toHaveBeenCalledWith({ keepAliveMs: 600_000 })) must stay green. For the pure-deletion half there is nothing to pin beyond npm run typecheck still passing. AGENTS.md § Code Review: "For every added field, option, or optional parameter, grep its read sites, including outside the diff. A foo?: boolean that is declared and read but never set by any caller is a dead switch." AGENTS.md § Simplicity First: "No 'flexibility' or 'configurability' that wasn't requested."
中文说明
EnsureOptions.timeoutMs 与 .keepAliveMs 被声明、被写进文档、也被读取,但整个仓库里没有任何调用方设置它们,而这个导出的类型没有任何 importer——正是 AGENTS.md 明确点名的 dead switch 形态。更糟的是,skipKeepAlivePreheat 的默认值由参数的语法形式推导,于是 ensure(30_000) 与 ensure({ timeoutMs: 30_000 })——同一个意图、两种写法——会静默地相差一次十分钟的 keep-alive 续期,既没有类型错误也没有测试失败。唯一的生产端对象形式调用方传的是一个裸 {},所以这个改变行为的开关在使用处是看不见的。
这个陷阱很具体:某位维护者为了给面向客户端的预热加上界,把 routes/workspace-runtime.ts:64 里的 await coordinator.ensure() 改写成 await coordinator.ensure({ timeoutMs: 30_000 })——而那个路由的全部目的就是续期。两种写法都能通过类型检查、看起来等价,但 options.skipKeepAlivePreheat ?? typeof timeoutMsOrOptions !== 'number' 现在把 skip 默认为 true,于是在已 live 的 runtime 上 bridge.preheat({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }) 不再被发出,keepAliveUntil 也不再被延长:该路由自己的 workspace-control 工作一排空,ACP 子进程就变得可被回收。另外两个陷阱也已实测:ensure({ skipKeepAlivePreheat: true, keepAliveMs: 60_000 }) 会丢弃显式的 true(按优先级 keepAliveMs 胜出,而 JSDoc 描述的是默认值而非覆盖),ensure({ keepAliveMs: 0 }) 会让 === undefined 这一项为 false,于是 preheat 以 preheat({ keepAliveMs: 0 }) 执行,而 bridge.ts:14662-14668 把它当作完全没有窗口,ensure 却按已请求窗口继续执行。这个导出类型还宣称了一种唯一的 HTTP 表面明确禁止的可配置性——routes/workspace-runtime.ts:56-62 会以「Workspace runtime ensure does not accept parameters」拒绝任何请求体。
证据:
对真实总体做扫描(整个仓库,排除 dist/):
  EnsureOptions 的 importer:2 处,都在 workspace-runtime-coordinator.ts 内部
                           (:26 声明、:191 参数类型)—— 外部 importer 为零
  coordinator.ensure 的生产调用方:2 处 —— routes/workspace-runtime.ts:64 `ensure()`;
                                          run-qwen-serve.ts:8955 `ensure({})`
  `skipKeepAlivePreheat` 的写入方:4 处,全部在 workspace-runtime-coordinator.test.ts
  `timeoutMs` / `keepAliveMs` 的写入方:0(生产与测试都没有)
在 mock-bridge harness、live runtime 下实测该陷阱:
  live ensure()                                               -> preheat calls=1 args=[[{"keepAliveMs":600000}]]
  live ensure(30_000)                                         -> preheat calls=1 args=[[{"keepAliveMs":600000}]]
  live ensure({})                                             -> preheat calls=0 args=[]
  live ensure({timeoutMs:30_000})                             -> preheat calls=0 args=[]   <-- 看似等价的改写
  live ensure({skipKeepAlivePreheat:true,keepAliveMs:60_000})  -> preheat calls=1 args=[[{"keepAliveMs":60000}]]
  live ensure({keepAliveMs:0})                                -> preheat calls=1 args=[[{"keepAliveMs":0}]]
请把这个选项收窄到唯一调用方真正需要的程度,并在使用处把开关写明白。把类型缩减为 { skipKeepAlivePreheat?: boolean }(数值参数已经覆盖 timeoutMs),把 skip 计算成 snapshot.runtimeLive && options.skipKeepAlivePreheat === true,使其成为显式选择而非由形式推导;恢复 this.bridge.preheat({ keepAliveMs: ENSURE_KEEP_ALIVE_MS });从两处文档注释中删掉「(unless keepAliveMs is set)」这一句;并让启动处说明自己的意图:void coordinator.ensure({ skipKeepAlivePreheat: true }).catch(...)。如果确实需要 keep-alive 覆盖,就保留它、校验 keepAliveMs > 0,并补一个设置它的测试。注意与 R1-1 的交互:如果 R1-1 的修复通过 keepAliveMs 在启动时挂窗口,那么这个选项的形状必须在同一次改动中一并决定。
修复不得违反这一点:const ENSURE_KEEP_ALIVE_MS = 10 * 60_000;(workspace-runtime-coordinator.ts:22)是无参路径必须继续传给 bridge.preheat 的值——由 routes/workspace-runtime.test.ts:102、server.test.ts:5898 与 workspace-runtime-coordinator.test.ts:876-878 以 { keepAliveMs: 600_000 } 钉住——而 res.status(200).json(await coordinator.ensure());(routes/workspace-runtime.ts:64)是该形式的已发布调用方。文件内另有三处依赖同一常量(:433、:534、:581)。
请用一个「去掉就会失败」的测试钉住选定的形状:run-qwen-serve.test.ts 在 :16581 断言 expect(ensureSpy).toHaveBeenCalledWith({}),在显式开关的修法下必须改成 { skipKeepAlivePreheat: true }——那时它就是调用点退回不透明 {} 时会变红的那条断言。两个已有的 coordinator 用例(expect(harness.preheat).not.toHaveBeenCalled() 与 expect(harness.preheat).toHaveBeenCalledWith({ keepAliveMs: 600_000 }))必须保持绿色。纯删除那一半除了 npm run typecheck 仍需通过之外没有可钉的行为。AGENTS.md § Code Review:「For every added field, option, or optional parameter, grep its read sites, including outside the diff. A foo?: boolean that is declared and read but never set by any caller is a dead switch.」AGENTS.md § Simplicity First:「No 'flexibility' or 'configurability' that wasn't requested.」
— qwen3.8-max via Qwen Code /review (v0.23.0)
| const scheduleWorkspaceMcpDiscoveryAfterPreheat = ( | ||
| app: Application, | ||
| ): void => { |
There was a problem hiding this comment.
[Suggestion] R2-3: this is the only deferred-startup callback in its closure that does not check shuttingDown before starting work, although the preheat it follows is a multi-second async operation and every sibling deferred path gates on it. A shutdown that lands while preheat is in flight still fires coordinator.ensure({}), and the resulting drain error is recorded as a boot failure.
shuttingDown is in scope (declared at run-qwen-serve.ts:8493) and every sibling deferred path gates on it — startRuntime's .then (:9003), scheduleRuntimeStartFallback (:9020, :9027), scheduleRuntimeStartAfterHealth (:9034, :9043) and :9053. handle.close()/SIGTERM during the preheat sets shuttingDown = true (:9136) and drains the primary coordinator via beginRuntimeCoordinatorDrains (:9141-9153). When the preheat promise resolves afterwards this callback still fires ensure({}), which throws WorkspaceDrainingError from assertAcceptingWork and is recorded as "workspace MCP discovery after preheat failed: …" — a failure diagnostic for an ordinary shutdown. Today that line is invisible (R1-2), so the cost is latent; the moment R1-2's fix escalates the failure branch to daemonLog.warn or stderr, every shutdown that races a boot emits a spurious operator-visible warning. The other outcome worth naming was measured and does not hold: the in-flight ensure does not delay the shutdown seal, because prepareMcpRevision's poll loop checks this.draining || this.disposed each iteration and its 250 ms timer is unref'd.
Witness:
Probe on a real runQwenServe: pending preheat, waitForPreheatStatus(handle,'running'),
then handle.close(), then resolve the preheat. Intact vs the suggested one-line fix:
  INTACT: PROBE-F6 { "ensureCalls": 1, "ensureArgs": [[{}]], "closeMs": 8,
            "discoveryLines": ["... [DEBUG] [QWEN_SERVE] workspace MCP discovery after preheat failed:
                                Workspace \"/tmp/qws-probe-f6-ec0fac\" is being removed"] }
  FIXED (`if (shuttingDown) return;` as the callback's first line):
          PROBE-F6 { "ensureCalls": 0, "ensureArgs": [], "closeMs": 7, "discoveryLines": [] }
Every sibling gate named above was verified present as quoted.
| const scheduleWorkspaceMcpDiscoveryAfterPreheat = ( | |
| app: Application, | |
| ): void => { | |
| const scheduleWorkspaceMcpDiscoveryAfterPreheat = ( | |
| app: Application, | |
| ): void => { | |
| if (shuttingDown) return; |
Worth landing together with R1-2's escalation, so the shutdown race is quiet before the failure branch becomes operator-visible.
The guard must not change the two benign skip branches' messages, which two new tests pin exactly: run-qwen-serve.test.ts asserts "workspace MCP discovery after preheat skipped: workspace runtime lifecycle is not supported" and "…skipped: no primary runtime" by reading qwenCore.Storage.getDebugLogPath(debugSessionId). shuttingDown is a closure variable in the same scope (run-qwen-serve.ts:8493), so reading it adds no plumbing.
Please pin the guard with a test that fails without it: install a bridge whose preheat returns a pending promise, spy on WorkspaceRuntimeCoordinator.prototype.ensure, call handle.close(), then resolve the preheat and assert the spy was not called and no "…after preheat failed" line was written. Removing the guard makes the spy fire and the diagnostic appear, so the test goes red. No current test covers shutdown-during-preheat. One caution from a measured mutation elsewhere in this round: a spy assertion alone is not sufficient in this file's fixtures unless the bridge also exposes getWorkspaceRuntimeLifecycleSnapshot, or getWorkspaceRuntimeCoordinatorIfSupported returns undefined and the spy stays uncalled even with the gate removed.
中文说明
这是其所在闭包中唯一一个在开始工作前不检查 shuttingDown 的延迟启动回调,而它所跟随的 preheat 是一个耗时数秒的异步操作,且每一个同类的延迟路径都有这道判断。一次落在 preheat 进行中的关闭,仍然会触发 coordinator.ensure({}),而由此产生的 drain 错误会被记录成一次启动失败。
shuttingDown 在作用域内(声明于 run-qwen-serve.ts:8493),而每一个同类延迟路径都会判断它——startRuntime 的 .then(:9003)、scheduleRuntimeStartFallback(:9020、:9027)、scheduleRuntimeStartAfterHealth(:9034、:9043)以及 :9053。preheat 期间的 handle.close()/SIGTERM 会把 shuttingDown 置为 true(:9136),并通过 beginRuntimeCoordinatorDrains(:9141-9153)排空 primary coordinator。之后 preheat promise resolve 时,这个回调仍会触发 ensure({}),它从 assertAcceptingWork 抛出 WorkspaceDrainingError,并被记录为「workspace MCP discovery after preheat failed: …」——一次普通关闭被记成了失败诊断。今天这一行是不可见的(见 R1-2),所以代价是潜在的;一旦 R1-2 的修复把失败分支提升到 daemonLog.warn 或 stderr,每一次与启动竞态的关闭都会发出一条虚假的、运维者可见的告警。另一个值得一提的结果经实测并不成立:进行中的 ensure 不会拖延关闭封口,因为 prepareMcpRevision 的轮询循环每轮都检查 this.draining || this.disposed,且其 250 ms 定时器是 unref 的。
证据:
在真实 runQwenServe 上的探针:preheat 挂起,waitForPreheatStatus(handle,'running'),
然后 handle.close(),再 resolve preheat。原始代码与建议的一行修复对比:
  INTACT: PROBE-F6 { "ensureCalls": 1, "ensureArgs": [[{}]], "closeMs": 8,
            "discoveryLines": ["... [DEBUG] [QWEN_SERVE] workspace MCP discovery after preheat failed:
                                Workspace \"/tmp/qws-probe-f6-ec0fac\" is being removed"] }
  FIXED(把 `if (shuttingDown) return;` 作为回调第一行):
          PROBE-F6 { "ensureCalls": 0, "ensureArgs": [], "closeMs": 7, "discoveryLines": [] }
上面引用的每一处同类判断都已核实存在。
修复代码见上方的一键 suggestion。建议与 R1-2 的提升一起落地,使关闭竞态在失败分支变得运维者可见之前先安静下来。
这道判断不得改变两个良性 skip 分支的文案——有两个新测试精确钉住了它们:run-qwen-serve.test.ts 通过读取 qwenCore.Storage.getDebugLogPath(debugSessionId) 断言「workspace MCP discovery after preheat skipped: workspace runtime lifecycle is not supported」与「…skipped: no primary runtime」。shuttingDown 是同一作用域内的闭包变量(run-qwen-serve.ts:8493),读取它不需要额外接线。
请用一个「去掉就会变红」的测试钉住这道判断:装一个 preheat 返回挂起 promise 的 bridge,spy WorkspaceRuntimeCoordinator.prototype.ensure,调用 handle.close(),然后 resolve preheat,断言 spy 未被调用且没有写出「…after preheat failed」这一行。去掉这道判断后 spy 会触发、诊断会出现,测试即变红。目前没有任何测试覆盖 preheat 期间关闭的情形。本轮另一处实测变异给出一个提醒:在本文件的 fixture 中,仅有 spy 断言是不够的——除非 bridge 同时暴露 getWorkspaceRuntimeLifecycleSnapshot,否则 getWorkspaceRuntimeCoordinatorIfSupported 返回 undefined,即使去掉这道判断 spy 也不会被调用。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| snapshot.runtimeLive && | ||
| options.keepAliveMs === undefined && |
There was a problem hiding this comment.
[Suggestion] R2-4: no test exercises the object form ensure({}) against a runtime whose snapshot reports runtimeLive: false, so this snapshot.runtimeLive term of the new skip condition is unpinned — deleting it leaves every suite green while changing behaviour. This is not the same gap as R1-1: that one is what the skip path does when the term is true, this is that nothing pins its false branch, and a fix for R1-1 that arms a scoped hold at boot leaves this mutant green.
With the term deleted, ensure({}) on a cold runtime takes the skip path and the if (!status.runtimeLive) guard fires before prepareSkills/prepareMcp, so the call rejects with "Runtime is not live after skipping keep-alive preheat" instead of preheating and starting the runtime. All four new coordinator tests set runtimeLive: true before calling the object form, and the only other object-form call in the tree is run-qwen-serve.ts:8955, whose test mocks the snapshot to { state: 'idle', runtimeLive: true }; the numeric form cannot pin the term either, because ?? typeof timeoutMsOrOptions !== 'number' already forces false there. So a regression that drops the liveness precondition ships green, and any future caller reaching the object form on a cold runtime gets a rejection instead of a start.
Witness:
Mutation executed (deleted `snapshot.runtimeLive &&` from :202, nothing else touched):
  INTACT probe: COLD ensure({}) -> preheat calls=1 args=[[{"keepAliveMs":600000}]] | resolved
  MUTANT probe: COLD ensure({}) -> preheat calls=0 args=[] | rejected:
                  WorkspaceRuntimeInitializationError | cause=Runtime is not live after skipping keep-alive preheat
  MUTANT vs the PR's own suites:
    workspace-runtime-coordinator.test.ts  Tests 48 passed (48)
    run-qwen-serve.test.ts -t "MCP discovery"  Tests 4 passed | 378 skipped
The mutant survives every test the PR added or touched, and the probe shows the mutation is
behaviourally real rather than vacuous.
Add a coordinator test for the cold-path object form:
it('keep-alive preheats a cold runtime passed the object form', async () => {
  const harness = makeRuntime();
  harness.setSnapshot({ state: 'cold', runtimeLive: false, runtimeEpoch: 0 });
  const coordinator = getWorkspaceRuntimeCoordinator(harness.runtime);

  const status = await coordinator.ensure({});

  expect(harness.preheat).toHaveBeenCalledOnce();
  expect(harness.preheat).toHaveBeenCalledWith({ keepAliveMs: 600_000 });
  expect(status.runtimeLive).toBe(true);
});
The cold-path object form must arm the same full window as the numeric form, so this test should pin keepAliveMs: 600_000 — the value of const ENSURE_KEEP_ALIVE_MS = 10 * 60_000; at workspace-runtime-coordinator.ts:22 — and not a reduced value. Whichever shape the skip option ends up taking after R1-1 and R2-2, the cold-path object form must still preheat.
That new test is the witness: it goes red if snapshot.runtimeLive && is removed from the skip condition, because preheat would not be called and ensure({}) would reject. Measured today, nothing else catches it — the mutant survives all 48 existing coordinator tests and all 4 new serve tests.
中文说明
没有任何测试在快照报告 runtimeLive: false 的 runtime 上执行对象形式 ensure({}),因此新跳过条件中的这一项 snapshot.runtimeLive 没有被钉住——删掉它,所有测试套件仍然是绿的,而行为已经改变。这与 R1-1 不是同一个缺口:R1-1 说的是该项为 true 时跳过路径的行为,这里说的是没有任何测试钉住它的 false 分支;即便 R1-1 的修复在启动时挂上一个受限的持有窗口,这个变异体仍然是绿的。
删掉该项后,冷 runtime 上的 ensure({}) 会走跳过路径,而 if (!status.runtimeLive) 这道判断会在 prepareSkills/prepareMcp 之前触发,于是调用以「Runtime is not live after skipping keep-alive preheat」reject,而不是预热并启动 runtime。四个新的 coordinator 测试在调用对象形式之前都把 runtimeLive 设为 true,而树中唯一的另一处对象形式调用是 run-qwen-serve.ts:8955,其测试把快照 mock 成 { state: 'idle', runtimeLive: true };数值形式也钉不住这一项,因为 ?? typeof timeoutMsOrOptions !== 'number' 在那里已经强制为 false。所以一个丢掉存活前置条件的回归会绿灯通过,而未来任何在冷 runtime 上使用对象形式的调用方会得到一次 reject 而不是一次启动。
证据:
已执行的变异(从 :202 删除 `snapshot.runtimeLive &&`,其他一律未动):
  INTACT probe: COLD ensure({}) -> preheat calls=1 args=[[{"keepAliveMs":600000}]] | resolved
  MUTANT probe: COLD ensure({}) -> preheat calls=0 args=[] | rejected:
                  WorkspaceRuntimeInitializationError | cause=Runtime is not live after skipping keep-alive preheat
  MUTANT 与本 PR 自己的套件:
    workspace-runtime-coordinator.test.ts  Tests 48 passed (48)
    run-qwen-serve.test.ts -t "MCP discovery"  Tests 4 passed | 378 skipped
该变异体在本 PR 新增或改动过的每一个测试下都存活,而探针表明这个变异在行为上是真实的、并非空转。
请为冷路径的对象形式补一个 coordinator 测试(代码见上)。
冷路径的对象形式必须挂上与数值形式相同的完整窗口,所以这个测试应钉住 keepAliveMs: 600_000——即 workspace-runtime-coordinator.ts:22 处 const ENSURE_KEEP_ALIVE_MS = 10 * 60_000; 的值——而不是一个缩小的值。无论 R1-1 与 R2-2 之后跳过选项最终取哪种形状,冷路径的对象形式都必须仍然预热。
这个新测试就是见证:如果从跳过条件中删掉 snapshot.runtimeLive &&,它会变红,因为那时 preheat 不会被调用而 ensure({}) 会 reject。实测表明今天没有别的东西能抓到它——该变异体在全部 48 个已有 coordinator 测试和 4 个新 serve 测试下都存活。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| await vi.waitFor(() => expect(ensureSpy).toHaveBeenCalledOnce()); | ||
| expect(ensureSpy).toHaveBeenCalledWith({}); |
There was a problem hiding this comment.
[Suggestion] R2-5: this end-to-end boot test pins the call — ensure invoked once with {}, on the primary workspace's runtime, with no extra keep-alive preheat — but never the effect. The initializeWorkspaceMcp and queryWorkspaceStatus mocks it installs a few lines above are never asserted, so nothing in the file distinguishes "boot discovery completed" from "boot discovery rejected on its first await": the very next test mocks ensure to throw and passes the same assertion shape.
ensure is spied on without a mock implementation, so the real coordinator runs against a real serve app whose workspaceService sits on makeFakeBridge(), which defines no invokeWorkspaceCommand and no Skills/MCP methods beyond the three this test assigns. If Skills/MCP preparation threw in that harness, the fire-and-forget .catch at run-qwen-serve.ts:8955 would swallow it and every assertion here would still pass, so the suite would certify "boot starts workspace MCP discovery" while the boot call never reached preparation. The only place that effect is pinned today is the coordinator unit test (expect(harness.initializeWorkspaceMcp).toHaveBeenCalledOnce()), on a different harness, so no test proves the two halves connect. To be precise about scope: the strong form of this concern is false today — instrumented, ensure({}) does complete in that harness and both capabilities reach ready — so the defect is assertion strength, not a test that is currently vacuous.
Witness:
Instrumented copy of this test, product code unmodified:
  PROBE_ENSURE_SETTLED [{"status":"fulfilled","capabilities":{
      "mcp":{"state":"ready","revision":0,"runtimeEpoch":1},
      "skills":{"state":"ready","revision":0,"runtimeEpoch":1}}}]
  PROBE_INIT_MCP_CALLS 0
  PROBE_QUERY_STATUS_CALLS 2
  PROBE_SUGGESTED_ASSERTION red: AssertionError: expected "spy" to be called once, but got 0 times
Assert the effect this test already has mocks for, but not through initializeWorkspaceMcp: assert the coordinator's status reaches capabilities.mcp.state === 'ready', or await the spied promise, or assert bridge.queryWorkspaceStatus was called. The obvious-looking assertion is a trap here — expect(bridge.initializeWorkspaceMcp).toHaveBeenCalledOnce() is red on healthy code, measured PROBE_INIT_MCP_CALLS 0 above, because this fixture's queryWorkspaceStatus returns discoveryState: 'completed' on the first read, so prepareMcpRevision breaks out of its loop before requesting initialization (workspace-runtime-coordinator.ts:611-618). Filing it as written would hand you a false failure.
Keep asserting call ordering only, never awaiting discovery completion in the production-shaped path: the production call is fire-and-forget with errors swallowed (run-qwen-serve.ts:8955-8960), so awaiting it would pin a guarantee the code deliberately does not make. And write the new assertion against this fixture's discoveryState: 'completed'-on-first-read behaviour, not against the coordinator unit test's not_started-then-completed sequence.
An assertion on capabilities.mcp.state === 'ready' (or on queryWorkspaceStatus being called) is the witness: it goes red if ensure({}) rejects or returns before prepareMcp runs in the real boot harness, and it would be the only assertion in this file that observes preparation actually happening. Do not use an initializeWorkspaceMcp assertion — measured 0 calls on healthy code.
中文说明
这个端到端启动测试钉住了调用——ensure 被调用一次、参数为 {}、作用在 primary workspace 的 runtime 上、且没有额外的 keep-alive preheat——但从未钉住效果。它在上方几行装的 initializeWorkspaceMcp 与 queryWorkspaceStatus mock 从未被断言,因此文件中没有任何东西能区分「启动 discovery 完成了」和「启动 discovery 在第一个 await 上就 reject 了」:紧接着的下一个测试把 ensure mock 成抛错,却通过完全相同的断言形状。
ensure 被 spy 时没有 mock 实现,所以真实的 coordinator 会跑在一个真实的 serve app 上,而其 workspaceService 建立在 makeFakeBridge() 之上——后者没有定义 invokeWorkspaceCommand,也没有本测试所赋值那三个之外的 Skills/MCP 方法。如果在这样的 harness 中 Skills/MCP 准备抛错,run-qwen-serve.ts:8955 处 fire-and-forget 的 .catch 会把它吞掉,而这里每一条断言仍然通过,于是套件会证明「启动时开始了 workspace MCP discovery」,而启动调用其实从未到达准备阶段。今天唯一钉住该效果的地方是 coordinator 单测(expect(harness.initializeWorkspaceMcp).toHaveBeenCalledOnce()),用的是另一套 harness,所以没有测试证明这两半是接通的。把范围说准确:这个担忧的强形式今天是不成立的——经插桩,ensure({}) 在该 harness 中确实完成,两个 capability 都到达 ready——所以缺陷在于断言强度,而不是测试当前是空转的。
证据:
对本测试的插桩副本,产品代码未改动:
  PROBE_ENSURE_SETTLED [{"status":"fulfilled","capabilities":{
      "mcp":{"state":"ready","revision":0,"runtimeEpoch":1},
      "skills":{"state":"ready","revision":0,"runtimeEpoch":1}}}]
  PROBE_INIT_MCP_CALLS 0
  PROBE_QUERY_STATUS_CALLS 2
  PROBE_SUGGESTED_ASSERTION red: AssertionError: expected "spy" to be called once, but got 0 times
请断言这个测试已经有 mock 的那个效果,但不要通过 initializeWorkspaceMcp:断言 coordinator 的状态到达 capabilities.mcp.state === 'ready',或 await 被 spy 的 promise,或断言 bridge.queryWorkspaceStatus 被调用过。这里最显眼的那条断言是个陷阱——expect(bridge.initializeWorkspaceMcp).toHaveBeenCalledOnce() 在健康代码上就是红的,上面实测 PROBE_INIT_MCP_CALLS 0,因为本 fixture 的 queryWorkspaceStatus 在第一次读取就返回 discoveryState: 'completed',于是 prepareMcpRevision 在请求初始化之前就跳出了轮询循环(workspace-runtime-coordinator.ts:611-618)。照那样写会交给你一个假失败。
请继续只断言调用时序,绝不要在与生产同形的路径上 await discovery 完成:生产调用是 fire-and-forget 且吞掉错误(run-qwen-serve.ts:8955-8960),await 它会钉住一个代码刻意不提供的保证。并且新断言要针对本 fixture「第一次读取即 discoveryState: 'completed'」的行为来写,而不是针对 coordinator 单测那套 not_started 再 completed 的序列。
对 capabilities.mcp.state === 'ready'(或对 queryWorkspaceStatus 被调用)的断言就是见证:如果在真实启动 harness 中 ensure({}) reject 或在 prepareMcp 运行前返回,它会变红;它也将是本文件中唯一观察到准备工作确实发生的断言。不要使用 initializeWorkspaceMcp 断言——健康代码上实测为 0 次调用。
— qwen3.8-max via Qwen Code /review (v0.23.0)
Boot ensure({}) skipped keep-alive, so default channelIdleTimeoutMs=0
reaped the warm child before initializeWorkspaceMcp. Arm the 10-minute
window and load createDebugLogger from the debugLogger subpath so the
serve fast-path bundle stays closed.

main's QwenLM#10957 and QwenLM#10917 added the same
@qwen-code/qwen-code-core/debugLogger subpath aliases this PR added, so
the union of the two sides is main's version. Auto-merge could not see
that and kept both copies in core's exports map and in the
integration-tests paths block; drop the duplicates so each map names the
subpath once.

cli's vitest alias map moved to an ordered array on main, with the named
core subpaths matched ahead of the core wildcard. debugLogger is one of
those named subpaths and has to stay above the wildcard: the real file is
core/src/utils/debugLogger.ts, which the wildcard cannot derive.

|
Qwen Code resolved the merge conflicts and pushed the branch update. Root cause. Base commits Semantic, not adjacent. Two files conflicted ( Load-bearing. Alias order is precedence in '@qwen-code/qwen-code-core/debugLogger': '../core/src/utils/debugLogger.ts',
{ find: /^@qwen-code\/qwen-code-core\/(.*)$/, replacement: `${CORE_SRC}/$1` },The wildcard derives Not verified. No build, typecheck, lint, or tests were run.
中文说明根因。 基线提交 属于语义冲突。 两个文件文本冲突( 关键约束。 别名顺序即优先级,具名条目须在通配规则之上(代码见上)。通配规则会推导出并不存在的 未能验证。 未运行构建、类型检查、lint 或测试。
|
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Reviewed — no blockers. Suggestions are inline.
Test Plan (not a blocker): 10 passed — this review observed 28865 passed.
Convergence: round 3 posted 5 inline comment(s), 3 of them reported for the first time; the previous round posted 7 (6 new). Findings keep coming back to the same files: packages/cli/src/serve/run-qwen-serve.ts (findings in rounds 1, 2; 3 more now). A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. No Critical finding is open on this round, so merging and moving the remaining Suggestion threads to a follow-up issue is available as an ending — a merged pull request cannot diverge further. (Observation only — nothing was withheld from this review because of this observation.)
中文说明
已审查——无阻断问题。 建议见行内评论。
Test Plan(非阻断):10 passed — this review observed 28865 passed。
收敛情况:第 3 轮发布了 5 条行内评论,其中 3 条是首次提出;上一轮发布了 7 条(其中 6 条首次提出)。发现反复回到同一批文件:packages/cli/src/serve/run-qwen-serve.ts(第 1、2 轮已出过发现,本轮又有 3 条)。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。本轮没有未决的 Critical,因此"合入后把剩余 Suggestion 线程转到后续 issue"是一个可选的结束方式——已合入的 PR 不会继续发散。(仅为观察——本轮评审未因此扣留任何内容。)
— qwen3.8-max via Qwen Code /review (v0.23.0)
| if (shuttingDown) { | ||
| debugLogger.debug( | ||
| 'workspace MCP discovery after preheat skipped: shutting down', | ||
| ); | ||
| return; | ||
| } |
There was a problem hiding this comment.
[Suggestion] R2-3: (fix-induced) The shuttingDown guard added in answer to R2-3 closes R2-3's reported input, but it checks only one of the two terminal states this closure has. failRuntimeStartup never sets shuttingDown — only handle.close() does (:9154, which is also the only place this file calls coordinator beginDrain(), :9168) — so a preheat that resolves after runtime startup was already declared failed still arms a 600 s keep-alive and runs Skills/MCP preparation against an app whose resources were disposed.
startRuntime() calls startBridgePreheat(runtime.bridge, runtime.app) and then await completeRuntimeStartup(runtime.app) (:9029-9030), and the preheat .then() calls this helper at :8993. When completeRuntimeStartup rejects — its opts.channelSelection branch awaits ensureChannelWorkerManager!() / manager.startInitial(...) (:8925-8929) — or the armRuntimeStartupTimer timer fires (:8618-8626), failRuntimeStartup sets runtimeStartupSettled (:8580), calls disposeRuntimeAppResources (:8582; :4606-4670 stops producers, device flow, Local Control, the ACP handle, the rate limiter and the event-loop monitor, and does not drain runtime coordinators or close a generation guard), sets runtimeStartupError (:8585), marks startup.preheat.status = 'failed', prints qwen serve: runtime startup failed (:8596), and then awaits stopChannelWorkerAfterFailedStartup() (:8608) before reaching shutdownBridgeAfterFailedStartup (:8615-8618). A preheat resolving inside that window passes this guard, finds app.locals['workspaceRegistry'] still populated, creates a coordinator that was never drained, and calls bridge.preheat({ keepAliveMs: 600_000 }) on a bridge not yet shut down — arming keepAliveUntil (write-only Math.max, packages/acp-bridge/src/bridge.ts:3025 / :14792-14795, no clearing site anywhere) and driving prepareSkills()/prepareMcp() and possibly initializeWorkspaceMcp(), which starts MCP servers in a child the teardown terminates moments later. The daemon that just logged runtime startup failed spends its shutdown window doing boot discovery and issuing workspace-control traffic into the teardown, while handle.close() deliberately drains coordinators first (:9160-9170) precisely to avoid that. Nothing pins the guard either: all four new tests run with shuttingDown === false and 'skipped: shutting down' appears nowhere in packages/cli/src/serve outside this source line.
This is a Suggestion rather than a Critical because everything downstream fails closed, each gate checked rather than assumed: the bridge's own shuttingDown rejects later control calls, the late-shutdown re-check kills a channel that handshakes mid-teardown (bridge.ts:5061-5066), shutdown() awaits inFlightChannelSpawn and terminates every snapshotted channel (:14716-14748) so no child outlives it, the armed hold feeds only an unref'd timer (:3732, :3753) that dies with the bridge object, and this helper's own .catch keeps the rejection out of unhandledRejection. What survives is wasted work and teardown latency in a failure window, plus a diagnostic that calls a cancellation a failure.
Witness:
Executed probe (scratch tree; internal fake bridge held pending,
resolveOnListen: true, completeRuntimeStartup made to reject, preheat resolved
synchronously at the instant failRuntimeStartup prints):

PR as-is:
PROBE(RA2-1) ensureCalls=1 ensureArgs=[[{"keepAliveMs":600000}]] initMcp=0
  order=["bridge.preheat(null)","stderr:runtime startup failed",
         "bridge.preheat({\"keepAliveMs\":600000})","bridge.shutdown()",
         "bridge.queryWorkspaceStatus()","bridge.queryWorkspaceStatus()"]

with the one-line candidate fix below:
PROBE(RA2-1) ensureCalls=0 ensureArgs=[] initMcp=0
  order=["bridge.preheat(null)","stderr:runtime startup failed","bridge.shutdown()"]
and this PR's four new boot tests stay green with the fix:
  Tests 4 passed | 379 skipped (383)

The decisive ordering: the keep-alive preheat lands BEFORE bridge.shutdown(),
and the real bridge sets its own shuttingDown only inside shutdown()
(bridge.ts:14644, :14605) and rejects preheat only on that flag (:14766-14767)
— so at that instant a real bridge ACCEPTS it.

Fix-constraint validated by measurement — the wrong variable breaks the healthy
path: with `if (shuttingDown || runtimeStartupSettled)` this PR's own tests fail,
  Tests 2 failed | 2 passed (383)
  FAIL starts workspace MCP discovery after ACP preheat succeeds
  FAIL logs when boot MCP discovery skips because primary runtime is gone
  both: expected "ensure" to be called once, but got 0 times

Test-gap mutation (baseline 382/382 green in 27.5 s):
  delete this guard (:8941-8943)                     ->  Tests 382 passed (382)
  comparator-alive: delete the hook call from .then  ->  Tests 4 failed | 378 passed (382)
| if (shuttingDown) { | |
| debugLogger.debug( | |
| 'workspace MCP discovery after preheat skipped: shutting down', | |
| ); | |
| return; | |
| } | |
| if (shuttingDown || runtimeStartupError !== undefined) { | |
| debugLogger.debug( | |
| 'workspace MCP discovery after preheat skipped: ' + | |
| (shuttingDown ? 'shutting down' : 'runtime startup failed'), | |
| ); | |
| return; | |
| } |
This matches the terminal-state idiom the same file already uses at :8806. The fix must not key on runtimeStartupSettled: completeRuntimeStartup sets it true on the success path too (:8934) and in the deferred path preheat normally resolves after that, so such a guard skips boot discovery on every healthy start — measured above. runtimeStartupError is assigned only in failure paths (:8533 in cancelDeferredRuntimeStartup, reached only from handle.close(), which already sets shuttingDown; and :8585). The diagnostic channel itself is R1-2's subject, so write this line wherever R1-2 settles.
Please pin this with a test that fails without it: beside the four cases at run-qwen-serve.test.ts:16531+, hold preheat pending with installInternalBridge(() => preheatPromise) (:16328), spy WorkspaceRuntimeCoordinator.prototype.ensure, drive a startup failure after preheat has started — the deterministic lever is opts.channelSelection with a rejecting channel-worker startup, since startBridgePreheat is called immediately before await completeRuntimeStartup; a deps.runtimeStartupTimeoutMs that survives buildRuntime() but fires before the test resolves preheat also works (:2496-2498) — then resolve preheat and assert the spy was never called and no second bridge.preheat carrying keepAliveMs was issued. Removing the runtimeStartupError clause, or deleting the guard entirely, must turn it red; today both leave 382/382 green.
中文说明
为回应 R2-3 而加入的 shuttingDown 判断,确实闭合了 R2-3 所报告的情形,但它只覆盖了本闭包两个终止状态中的一个。failRuntimeStartup 从不设置 shuttingDown——只有 handle.close() 会设(:9154,那也是本文件唯一调用 coordinator beginDrain() 的地方,:9168)——因此当 runtime startup 已被宣告失败之后 preheat 才 resolve 时,这段代码仍会挂上 600 秒 keep-alive,并在一个资源已被释放的 app 上执行 Skills/MCP 准备工作。
startRuntime() 先调用 startBridgePreheat(runtime.bridge, runtime.app),随后 await completeRuntimeStartup(runtime.app)(:9029-9030),而 preheat 的 .then() 在 :8993 调用本 helper。当 completeRuntimeStartup reject(其 opts.channelSelection 分支会 await ensureChannelWorkerManager!() / manager.startInitial(...),:8925-8929),或 armRuntimeStartupTimer 定时器触发(:8618-8626)时,failRuntimeStartup 会设置 runtimeStartupSettled(:8580)、调用 disposeRuntimeAppResources(:8582;:4606-4670 会停掉 producers、device flow、Local Control、ACP handle、rate limiter 与 event-loop monitor,但不会 drain runtime coordinator,也不会关闭 generation guard)、设置 runtimeStartupError(:8585)、把 startup.preheat.status 标为 'failed'、打印 qwen serve: runtime startup failed(:8596),然后先 await stopChannelWorkerAfterFailedStartup()(:8608),之后才走到 shutdownBridgeAfterFailedStartup(:8615-8618)。在这个窗口内 resolve 的 preheat 会通过本判断,发现 app.locals['workspaceRegistry'] 仍有值,创建一个从未被 drain 的 coordinator,并对一个尚未关闭的 bridge 调用 bridge.preheat({ keepAliveMs: 600_000 })——挂上 keepAliveUntil(只增不减的 Math.max,packages/acp-bridge/src/bridge.ts:3025 / :14792-14795,全仓无清除点),进而驱动 prepareSkills()/prepareMcp(),甚至 initializeWorkspaceMcp()——后者会在一个马上就被 teardown 终止的子进程里启动 MCP server。刚刚打印过 runtime startup failed 的守护进程,把自己的关闭窗口花在了启动期 discovery 上,并向 teardown 中发出 workspace-control 流量;而 handle.close() 恰恰是为了避免这一点才先 drain coordinator(:9160-9170)。这个判断同样没有任何测试钉住:四个新测试都在 shuttingDown === false 下运行,而 'skipped: shutting down' 这个字符串在 packages/cli/src/serve 中除本源码行外没有出现。
定为 Suggestion 而非 Critical,是因为下游每一道关卡都是失败即关闭,且逐条核过而非假定:bridge 自身的 shuttingDown 会拒绝后续 control 调用;late-shutdown 复查会杀掉在 teardown 中握手的 channel(bridge.ts:5061-5066);shutdown() 会 await inFlightChannelSpawn 并终止快照到的每个 channel(:14716-14748),因此没有子进程能活过它;挂上的 hold 只喂给一个 unref 的定时器(:3732、:3753),随 bridge 对象一起消亡;本 helper 自己的 .catch 也让 rejection 不会进入 unhandledRejection。真正剩下的,是失败窗口内的无谓工作与 teardown 延迟,以及一条把「取消」记成「失败」的诊断。
修复不得以 runtimeStartupSettled 为条件:completeRuntimeStartup 在成功路径上也会把它设为 true(:8934),而在 deferred 路径中 preheat 通常在其之后才 resolve,这样的判断会让每一次正常启动都跳过 boot discovery——上面已实测。runtimeStartupError 只在失败路径被赋值(:8533 的 cancelDeferredRuntimeStartup,只能由已经设置 shuttingDown 的 handle.close() 到达;以及 :8585)。诊断通道本身属于 R1-2,因此这行日志应写在 R1-2 最终确定的通道上。
请用一个「去掉修复就会变红」的测试钉住它:在 run-qwen-serve.test.ts:16531+ 的四个用例旁边,用 installInternalBridge(() => preheatPromise)(:16328)把 preheat 挂起,spy WorkspaceRuntimeCoordinator.prototype.ensure,并在 preheat 已开始之后制造一次 startup 失败——确定性的杠杆是让 opts.channelSelection 的 channel-worker 启动 reject,因为 startBridgePreheat 紧接在 await completeRuntimeStartup 之前被调用;一个能通过 buildRuntime() 但在测试 resolve preheat 之前触发的 deps.runtimeStartupTimeoutMs 也可以(:2496-2498)——然后 resolve preheat,断言该 spy 从未被调用,且没有发出第二个携带 keepAliveMs 的 bridge.preheat。移除 runtimeStartupError 这一项、或整个删掉该判断,都必须让它变红;今天两者都留下 382/382 全绿。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| void coordinator | ||
| .ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }) |
There was a problem hiding this comment.
[Suggestion] R3-1: The PR description's Risk & Scope section states the opposite of what this line ships. No code change is being asked for here — the fix is an edit to the description.
Risk & Scope at HEAD reads: "Boot still calls ensure({}) and skips keep-alive when the runtime is already live; that skip is now explicit via EnsureOptions.skipKeepAlivePreheat (object form defaults to skip-when-live; numeric ensure() / ensure(timeoutMs) never skips). HTTP ensure keeps the 10-minute keep-alive window." The Chinese <details> mirror says the same ("因此 boot 调用 ensure({}):ACP preheat 成功后若已 runtimeLive,跳过多余的 bridge.preheat({ keepAliveMs })"), and the mermaid step still reads "skip preheat keepAliveMs". This call passes keepAliveMs, so the options.keepAliveMs === undefined conjunct is false, the skip never fires, and every qwen serve start arms keepAliveUntil = boot + 600_000 (packages/acp-bridge/src/bridge.ts:14792-14795) — monotonic, never-shortened, process-wide state (bridge.ts:3025) feeding Math.max(configured, keepAliveUntil - now, pendingKeepAliveMs) (bridge.ts:3725-3732).
A maintainer reading the section that exists to tell them what merging changes about runtime resource behaviour concludes boot leaves --channel-idle-timeout-ms semantics untouched, when in fact every boot now holds the ACP child, the workspace discovery Config and the MCP subprocesses for ten minutes and reaps them at boot+10min if zero sessions were served. That is precisely the axis which produced two consecutive Critical rounds on this PR, so the stale text sits where it does the most damage. A second sentence in the same section is refuted by measurement too: "!runtime / unsupported lifecycle now emit debug logs" — see R1-2, whose probe found no debug log file is ever created in a daemon-shaped process. One smaller staleness item belongs in the same edit: ensure() also runs prepareSkills(), while "What this PR does" describes the change as MCP-only.
Witness:
This PR's own new boot test falsifies the description, and passes:
  expect(bridge.preheat).toHaveBeenNthCalledWith(2, { keepAliveMs: ENSURE_KEEP_ALIVE_MS })
  (run-qwen-serve.test.ts:16591-16594)

Probe on the unmodified tree, confirming the shipped call form really arms the hold:
  PROBE B ensure({keepAliveMs}) preheat.calls: [[{"keepAliveMs":600000}]]

Description text quoted verbatim from the fetched PR body at HEAD 557f1b13d5.

One sub-claim corrected during verification: a round-1 "acceptance condition"
was asserted for this finding ("If reaping the preheated child at boot+10min
genuinely is the intended behaviour, recording it in Risk & Scope is enough").
It COULD NOT be verified — the fetched R1-1 body (comment 3945050768) contains
no such text and instead says this step "should be dropped rather than left to
fail into an invisible debug line". This finding therefore rests only on the
body being wrong at HEAD, which is verified, not on a breached condition.
Update Risk & Scope and its Chinese mirror to say that boot calls ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }), that this deliberately arms the same daemon-wide 10-minute keep-alive window the HTTP ensure route arms, that a boot serving zero sessions therefore reaps the warm child and its discovery Config at boot+10min, and that boot ensure() also prepares Skills; then correct or drop the "emit debug logs" sentence per R1-2 and update the mermaid step. If the no-hold boot is still the intended design, that is a different change rather than a description edit. Mitigation worth recording: your most recent PR comment already states the shipped behaviour correctly, so a maintainer reading the thread is not left with only the stale body — the description is what lands with the merge.
The new text must not contradict packages/cli/src/commands/serve.ts:585-587 — "Compatibility auto-reap delay for an idle workspace ACP child. 0 or unset = reap after work drains; keepalive windows may extend it (default)." The flag already permits keepalive windows to extend the reap, so the disclosure is that boot now always opens one, not that the flag is violated; and since packages/acp-bridge/src/bridge.ts:3732 takes Math.max(configured, keepAliveUntil - now, pendingKeepAliveMs), the hold can only extend the effective idle timeout, so the description cannot claim the configured --channel-idle-timeout-ms reclaim still applies inside the boot window.
中文说明
PR 描述的 Risk & Scope(风险与范围)一节,说的与这行代码实际发布的行为相反。这里不要求改代码——需要修改的是描述本身。
HEAD 上的 Risk & Scope 写着:「Boot still calls ensure({}) and skips keep-alive when the runtime is already live; that skip is now explicit via EnsureOptions.skipKeepAlivePreheat (object form defaults to skip-when-live; numeric ensure() / ensure(timeoutMs) never skips). HTTP ensure keeps the 10-minute keep-alive window.」中文 <details> 也是同样表述(「因此 boot 调用 ensure({}):ACP preheat 成功后若已 runtimeLive,跳过多余的 bridge.preheat({ keepAliveMs })」),mermaid 图中的步骤仍写着「skip preheat keepAliveMs」。而本调用传入了 keepAliveMs,于是 options.keepAliveMs === undefined 这一项为 false,跳过分支永不触发,每一次 qwen serve 启动都会挂上 keepAliveUntil = boot + 600_000(packages/acp-bridge/src/bridge.ts:14792-14795)——这是进程级、只增不减的状态(bridge.ts:3025),并参与 Math.max(configured, keepAliveUntil - now, pendingKeepAliveMs)(bridge.ts:3725-3732)。
一位阅读「这一节正是为了告诉维护者合并会改变什么运行时资源行为」的维护者,会得出「boot 没有触碰 --channel-idle-timeout-ms 语义」的结论;而事实上每次启动都会持有 ACP 子进程、workspace discovery Config 与 MCP 子进程十分钟,如果这期间一个 session 都没有,就在 boot+10min 把它们回收。这恰好是本 PR 连续两轮 Critical 所在的轴心,因此过期文本正落在伤害最大的位置。同一节中还有第二句被实测否定:「!runtime / unsupported lifecycle now emit debug logs」——见 R1-2,其探针表明在守护进程形态的进程中根本不会创建 debug log 文件。另有一处较小的过期内容应在同一次修改中处理:ensure() 同时会执行 prepareSkills(),而「这个 PR 做了什么」把改动描述为只涉及 MCP。
请把 Risk & Scope 及其中文对照更新为:boot 调用 ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS });这是有意挂上与 HTTP ensure 路由相同的、守护进程级的 10 分钟 keep-alive 窗口;因此一次没有服务任何 session 的启动会在 boot+10min 回收这个热子进程及其 discovery Config;并且 boot 的 ensure() 也会准备 Skills。随后按 R1-2 更正或删去「emit debug logs」那句,并更新 mermaid 步骤。如果「启动时不持有」仍是预期设计,那就是另一处代码改动,而不是一次描述修改。有一点值得记录:你最近一条 PR 评论已经正确描述了实际发布的行为,因此读完整个 thread 的维护者不会只看到过期的正文——但随合并一起留存的是描述本身。
新的表述不得与 packages/cli/src/commands/serve.ts:585-587 冲突——「Compatibility auto-reap delay for an idle workspace ACP child. 0 or unset = reap after work drains; keepalive windows may extend it (default).」该参数本来就允许 keepalive 窗口延长回收,因此需要披露的是「boot 现在总会打开一个窗口」,而不是「违反了该参数」;又因为 packages/acp-bridge/src/bridge.ts:3732 取 Math.max(configured, keepAliveUntil - now, pendingKeepAliveMs),hold 只能延长有效空闲超时,所以描述不能声称配置的 --channel-idle-timeout-ms 回收在 boot 窗口内仍然生效。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| debugLogger.debug( | ||
| `workspace MCP discovery after preheat failed: ${message}` + | ||
| (cause ? ` (${cause})` : ''), | ||
| ); |
There was a problem hiding this comment.
[Suggestion] R1-2: still stands. All four diagnostics this boot step added go through createDebugLogger, which cannot write anything in a qwen serve daemon process, so a boot-time discovery failure or skip leaves no trace in stderr, the daemon log or the debug log — and no test asserts the failure message, because the two tests that exist inject the missing precondition themselves.
debugLogger.debug() resolves a session through getActiveSession() (packages/core/src/utils/debugLogger.ts:51-68) and returns immediately when it is null. None of its three sources exists in the daemon: sessionContext is entered only by runWithDebugLogSession/runWithoutDebugLogSession, which have zero non-test callers in packages/; sessionIdContext.run is called only from packages/cli/src/acp-integration/{acpAgent,session/Session}.ts — the qwen --acp child — with zero hits in packages/cli/src/serve; and globalSession is set only by setDebugLogSession, whose only two non-test callers are the core Config constructor (config.ts:2506, :4507), and the daemon never constructs a Config (commands/serve.ts:763-764: "the daemon hasn't constructed a Config yet — sessions get their own"). Even with a session, writeLog returns early unless QWEN_DEBUG_LOG_FILE is set (debugLogger.ts:122-124), off by default.
So an operator starts qwen serve in a workspace whose MCP server fails to start: boot discovery fails, startup.preheat.status still reads succeeded, GET /workspace/runtime/status reports mcp: not_started (the failure lands before recordMcpError can set error), and every log channel is silent. Nothing retries until a client calls the ensure route or a session starts. The same silence covers all three skip branches, so a boot that never started discovery is indistinguishable from one that did. The two new tests pass only because they call qwenCore.setDebugLogSession(...) and set QWEN_DEBUG_LOG_FILE themselves (run-qwen-serve.test.ts:16657, :16705), so they bless a line production never emits — and this branch's message and (cause) suffix are asserted nowhere, since the test driving it checks only expect(rejections).toEqual([]). daemonLog is already in lexical scope in this same closure (declared :3955, 95 call sites, used at :9040/:9046/:9056/:9062), and the adjacent preheat-failure branch already reports through writeStderrLine (:8996).
Severity stays a Suggestion, not a Critical: feature behaviour is unchanged, nothing incorrect is certified, and createDebugLogger is the pre-existing house pattern across seven other serve modules — this diff adds four more calls inheriting that silence, it does not invent it. Worth knowing for the fix's shape: those seven modules (workspace-remember.ts:32, workspace-providers-status.ts:42, create-sub-session.ts:67, scheduled-task-keepalive.ts:46, live/realtime-startup-context.ts:50, acp-http/dispatch.ts:241, voice/voice-ws.ts:34) carry ~30 further call sites with the same problem, so the durable fix is a daemon-bound debug session or a serve-side logger that writes to daemonLog; routing only these four calls leaves the rest invisible.
Witness:
Probe, two arms differing by one line, same tree — a copy of this PR's own
'logs when boot MCP discovery skips because lifecycle is unsupported' with only
the qwenCore.setDebugLogSession(...) line removed:

ARM 1 (no session bound — the daemon's real state, QWEN_DEBUG_LOG_FILE=1):
PROBE C3: {"bootHelperRan":1,"debugLogFileExists":false,"bootLineWritten":false,"debugDirEntries":["daemon"]}

ARM 2 (session injected, exactly as this PR's own tests do):
PROBE C3: {"bootHelperRan":1,"debugLogFileExists":true,"bootLineWritten":true}

bootHelperRan: 1 in BOTH arms is the control — the helper executed, yet no debug
line was written without the session.

Mutation for the unasserted failure message (scratch tree, full
run-qwen-serve.test.ts, baseline 382/382 green in 27.5 s):
  replace the .catch body with .catch(() => {})      ->  Tests 382 passed (382)
  comparator-alive: delete the hook call from .then  ->  Tests 4 failed | 378 passed (382)

Bundle half, measured against the real esbuild metafile at this commit: the
@qwen-code/qwen-code-core/debugLogger subpath puts 8 core modules in the serve
pre-listen static closure — 82,705 B raw dist / 51,451 B (~50.2 KB) tree-shaken,
~1.4% of the 3,795,633 B closure — none of them a forbidden input or vendor.
| debugLogger.debug( | |
| `workspace MCP discovery after preheat failed: ${message}` + | |
| (cause ? ` (${cause})` : ''), | |
| ); | |
| daemonLog.warn( | |
| `workspace MCP discovery after preheat failed: ${message}` + | |
| (cause ? ` (${cause})` : ''), | |
| ); |
That one-click change covers the failure branch only; the three skip branches want the same rerouting (to daemonLog.info), and the module-scope debugLogger (:272) plus the @qwen-code/qwen-code-core/debugLogger import (:85) can then go if nothing else needs them. Any retained core logger import must stay on a subpath specifier such as '@qwen-code/qwen-code-core/debugLogger', never the bare barrel, because packages/cli/src/serve/fast-path.test.ts:512 adds '@qwen-code/qwen-code-core' to forbiddenExternalImports for this file's static source graph.
Please pin this with a test that fails without it: rewrite logs when boot MCP discovery skips because lifecycle is unsupported and ...because primary runtime is gone to assert the daemon-log sink without calling qwenCore.setDebugLogSession(...) (the daemonLogBaseDir dep already used at run-qwen-serve.test.ts:14710 is the existing seam), and add a failure-branch case reusing the ensure-throws harness that asserts both the message and its (cause) suffix. Removing the rerouted call, or emptying the catch body, must turn them red — today deleting this entire failure log leaves 382/382 green. Write that assertion together with the rerouting: it is worthless while production never emits the line.
中文说明
仍然存在。这个启动步骤新增的四条诊断全部经过 createDebugLogger,而它在 qwen serve 守护进程里写不出任何东西,因此启动期 discovery 的失败或跳过,在 stderr、daemon log 与 debug log 中都不留痕迹——而且没有任何测试断言失败信息,因为现有的两个测试自己把缺失的前提条件注入了进去。
debugLogger.debug() 通过 getActiveSession()(packages/core/src/utils/debugLogger.ts:51-68)解析 session,为 null 时立即返回。它的三个来源在守护进程中全都不存在:sessionContext 只由 runWithDebugLogSession/runWithoutDebugLogSession 进入,而它们在 packages/ 中的非测试调用方为零;sessionIdContext.run 只被 packages/cli/src/acp-integration/{acpAgent,session/Session}.ts 调用,也就是 qwen --acp 子进程,在 packages/cli/src/serve 中零命中;globalSession 只由 setDebugLogSession 设置,而它仅有的两个非测试调用方是 core Config 构造函数(config.ts:2506、:4507)——守护进程从不构造 Config(commands/serve.ts:763-764:「the daemon hasn't constructed a Config yet — sessions get their own」)。即便有 session,writeLog 在未设置 QWEN_DEBUG_LOG_FILE 时也会提前返回(debugLogger.ts:122-124),而该变量默认关闭。
于是运维者在一个 MCP server 启动失败的工作区里运行 qwen serve:boot discovery 失败,startup.preheat.status 仍显示 succeeded,GET /workspace/runtime/status 报告 mcp: not_started(失败发生在 recordMcpError 能设置 error 之前),所有日志通道都静默。在客户端调用 ensure 路由或启动 session 之前不会有任何重试。同样的静默覆盖全部三个跳过分支,因此一次根本没有启动 discovery 的 boot,与一次成功启动的 boot 无法区分。两个新测试之所以通过,只是因为它们自己调用了 qwenCore.setDebugLogSession(...) 并设置了 QWEN_DEBUG_LOG_FILE(run-qwen-serve.test.ts:16657、:16705),于是它们认可了一行生产环境永远不会输出的日志——而本分支的信息与 (cause) 后缀没有任何断言,因为驱动它的测试只检查 expect(rejections).toEqual([])。daemonLog 已经在同一个闭包内可见(声明于 :3955,95 处调用,如 :9040/:9046/:9056/:9062),而紧邻的 preheat 失败分支已经通过 writeStderrLine(:8996)上报。
严重级别保持 Suggestion,不是 Critical:功能行为没有改变,没有任何错误结果被认证为正确,而且 createDebugLogger 是 serve 下另外七个模块既有的通行写法——本 diff 只是新增了四个继承这种静默的调用,并没有发明它。关于修复形态有一点值得知道:那七个模块(workspace-remember.ts:32、workspace-providers-status.ts:42、create-sub-session.ts:67、scheduled-task-keepalive.ts:46、live/realtime-startup-context.ts:50、acp-http/dispatch.ts:241、voice/voice-ws.ts:34)还有约 30 处同样问题的调用点,因此持久的修法是给守护进程绑定一个 debug session,或提供一个写入 daemonLog 的 serve 侧 logger;只改这四处会让其余部分仍然不可见。
上面的一次点击修改只覆盖失败分支;三个跳过分支需要同样改道(到 daemonLog.info),此后若无其他需要,模块级的 debugLogger(:272)与 @qwen-code/qwen-code-core/debugLogger 导入(:85)可以一并去掉。任何保留的 core logger 导入都必须走子路径说明符(如 '@qwen-code/qwen-code-core/debugLogger'),绝不能是裸 barrel,因为 packages/cli/src/serve/fast-path.test.ts:512 已把 '@qwen-code/qwen-code-core' 加入本文件静态源图的 forbiddenExternalImports。
请用一个「去掉修复就会变红」的测试钉住它:把 logs when boot MCP discovery skips because lifecycle is unsupported 与 ...because primary runtime is gone 改写为断言 daemon-log 输出,且不再调用 qwenCore.setDebugLogSession(...)(run-qwen-serve.test.ts:14710 已在用的 daemonLogBaseDir dep 就是现成的接缝),并复用 ensure 抛错的 harness 增加一个失败分支用例,同时断言信息与它的 (cause) 后缀。移除改道后的调用、或清空 catch 体,都必须让它们变红——今天把整条失败日志删掉,仍是 382/382 全绿。这条断言要与改道一起写:在生产环境根本不输出这行日志之前,它没有价值。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| startup.preheat.durationMs = Math.round( | ||
| performance.now() - preheatStartedAt, | ||
| ); | ||
| scheduleWorkspaceMcpDiscoveryAfterPreheat(app); |
There was a problem hiding this comment.
[Suggestion] R3-2: Two central claims of the new boot helper have no test that would go red if they broke — that discovery runs only after a successful preheat, and that it targets the primary workspace only. Both were measured by mutation: each survives a change that breaks it while the whole suite stays green.
(1) Non-execution on preheat failure — this line. The contract is "after a successful ACP preheat", but moving this call out of .then into a finally, or duplicating it in the sibling .catch that sets startup.preheat.status = 'failed', keeps the entire suite green. ensureSpy is installed only in the two success-path tests (run-qwen-serve.test.ts:16559, 16614), and makeFakeBridge() — which installInternalBridge builds (:16329) — defines no getWorkspaceRuntimeLifecycleSnapshot, so any preheat-failure test would silently take the "lifecycle is not supported" skip branch instead of exercising the claim. In production the real bridge does implement it (packages/acp-bridge/src/bridge.ts:9436), so a boot whose preheat already failed — this file's own stderr says "will retry on first session" — would additionally warm an ACP child and arm a 600_000 ms hold during a degraded boot.
(2) Primary-only scope — :8947-8950. expect(ensureSpy).toHaveBeenCalledOnce() plus instances[0].runtime.workspaceCwd === tmpDir (:16583-16589) passes identically if the lookup were widened from primaryEntry.current to every registry entry. Multi-workspace daemons are supported without an injected bridge (only the injected form is rejected, run-qwen-serve.ts:3899-3903), so such a drift would arm ensure({ keepAliveMs: 600_000 }) on every registered workspace at boot — spawning and holding ACP children for workspaces with no session — with nothing going red.
Two related items are deliberately not repeated here: the failure branch's unasserted message is folded into R1-2 (asserting it is worthless until that channel can emit), and this guard's own missing test is folded into R2-3, which owns those lines.
Witness:
Mutations in a scratch tree against the full run-qwen-serve.test.ts,
baseline 382/382 green in 27.5 s:

  also call the hook in the preheat .catch (== moving it to `finally`)
      ->  Tests 382 passed (382)
  widen the lookup to registry.listManaged() (all workspaces, not primary-only)
      ->  Tests 382 passed (382)
  comparator-alive: delete the hook call from .then entirely
      ->  Tests 4 failed | 378 passed (382)

The comparator row is what makes the two green rows evidence: it fails in this
exact code region, reddening precisely the four new boot tests, yet both
mutations pass. Premise for (1) confirmed by reading: installInternalBridge
(:16328) builds makeFakeBridge(), which lacks
getWorkspaceRuntimeLifecycleSnapshot — only :521, :14664 and the two new
success-path Object.assign injections at :16541/:16606 have it. All mutants
reverted.
Add a preheat-failure case whose internal bridge also defines getWorkspaceRuntimeLifecycleSnapshot (as :16606 does), asserting startup.preheat.status === 'failed' and that the ensure spy was not called; and a workspace: [primary, secondary] variant of the success test (the shape already used at :4208) asserting ensureSpy is called exactly once and that ensureSpy.mock.instances[0].runtime.workspaceCwd is the primary.
Both cases must use the internal-bridge helper rather than an injected deps.bridge, because packages/cli/src/serve/run-qwen-serve.ts:3250 sets let shouldPreheat = !deps.bridge && shouldPreheatBridge(deps); — preheat only happens for a daemon-created bridge — and :3901 states "Injected bridge dependencies are only supported with a single workspace;".
Please pin these with tests that fail without them: relocating scheduleWorkspaceMcpDiscoveryAfterPreheat(app) from .then to .finally must redden case (1), and widening the lookup from primaryEntry.current to all registry entries must redden case (2). Both mutations are measured green today, so each new assertion is the only thing standing between the claim and a silent regression.
中文说明
新 boot helper 的两项核心主张没有任何「一旦被破坏就会变红」的测试——即 discovery 只在 preheat 成功之后运行,以及它只针对 primary workspace。两者都经过变异实测:每一次破坏性改动都能在全套测试保持绿色的情况下存活。
(1)preheat 失败时不应执行——本行。 契约是「在 ACP preheat 成功之后」,但把这个调用从 .then 移到 finally,或在设置 startup.preheat.status = 'failed' 的同级 .catch 中再调一次,整个测试套件仍然全绿。ensureSpy 只在两个成功路径测试中安装(run-qwen-serve.test.ts:16559、16614),而 installInternalBridge(:16329)所构造的 makeFakeBridge() 没有定义 getWorkspaceRuntimeLifecycleSnapshot,因此任何 preheat 失败用例都会静默走进「lifecycle is not supported」跳过分支,而不是真正检验这项主张。生产环境中真实 bridge 确实实现了它(packages/acp-bridge/src/bridge.ts:9436),所以一次 preheat 已经失败的启动——本文件自己的 stderr 写着「will retry on first session」——会额外预热一个 ACP 子进程,并在一次降级的启动过程中挂上 600_000 ms 的 hold。
(2)只针对 primary 的作用域——:8947-8950。 expect(ensureSpy).toHaveBeenCalledOnce() 加上 instances[0].runtime.workspaceCwd === tmpDir(:16583-16589),在把查找范围从 primaryEntry.current 扩大到注册表全部条目之后,通过情况完全相同。多工作区守护进程在不注入 bridge 的情况下是受支持的(只有注入形式被拒绝,run-qwen-serve.ts:3899-3903),因此这种漂移会在启动时对每一个已注册工作区挂上 ensure({ keepAliveMs: 600_000 })——为没有 session 的工作区生成并持有 ACP 子进程——而没有任何测试变红。
有两个相关条目刻意不在此重复:失败分支未被断言的信息并入 R1-2(在该通道能真正输出之前断言它没有价值),本判断自身缺失的测试并入 R2-3(那几行归它所有)。
请补充:一个 preheat 失败用例,其 internal bridge 同时定义 getWorkspaceRuntimeLifecycleSnapshot(如 :16606 那样),断言 startup.preheat.status === 'failed' 且 ensure spy 未被调用;以及一个成功测试的 workspace: [primary, secondary] 变体(:4208 已有该形态),断言 ensureSpy 恰好被调用一次,且 ensureSpy.mock.instances[0].runtime.workspaceCwd 是 primary。
两个用例都必须使用 internal-bridge helper 而不是注入的 deps.bridge,因为 packages/cli/src/serve/run-qwen-serve.ts:3250 写着 let shouldPreheat = !deps.bridge && shouldPreheatBridge(deps);——只有守护进程自建的 bridge 才会 preheat——而 :3901 写明「Injected bridge dependencies are only supported with a single workspace;」。
请用「去掉就会变红」的测试钉住它们:把 scheduleWorkspaceMcpDiscoveryAfterPreheat(app) 从 .then 移到 .finally 必须让用例(1)变红,把查找范围从 primaryEntry.current 扩大到全部注册表条目必须让用例(2)变红。这两种变异今天实测都是绿的,因此每条新断言都是这项主张与静默退化之间唯一的屏障。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| const skipKeepAlivePreheat = | ||
| snapshot.runtimeLive && | ||
| options.keepAliveMs === undefined && | ||
| (options.skipKeepAlivePreheat ?? typeof timeoutMsOrOptions !== 'number'); |
There was a problem hiding this comment.
[Suggestion] R2-2: still stands, and widened. EnsureOptions.skipKeepAlivePreheat is set by no production caller, EnsureOptions.timeoutMs is set by nobody at all, the exported type has zero importers outside its own file — and the object-form default makes ensure({ timeoutMs }) behave differently from ensure(timeoutMs) in a way the type does not reveal and this PR's own test proves fails. The previous round filed this against timeoutMs/keepAliveMs; this round gave keepAliveMs a writer and orphaned skipKeepAlivePreheat in exchange.
Repo-wide there are exactly two production callers of coordinator ensure: routes/workspace-runtime.ts:64 calls it bare — and that route hard-rejects any body at :56-62 (workspace_runtime_ensure_takes_no_parameters), so it can never pass options and typeof timeoutMsOrOptions !== 'number' is false; and run-qwen-serve.ts:8967 calls ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }), so the options.keepAliveMs === undefined conjunct is false. The skip branch never fires in shipped code, and ensure() and ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }) are behaviourally identical — both preheat with { keepAliveMs: 600000 }, both use DEFAULT_ENSURE_TIMEOUT_MS.
The live cost is a trap for the next caller. ensure({ timeoutMs: 5_000 }) — the natural object-form spelling of the pre-existing ensure(5_000) — silently takes the skip branch on an already-live runtime, arms no keep-alive hold, and under the documented default channelIdleTimeoutMs = 0 policy the warm child is reaped by the first workspace-control status read inside prepareMcpRevision, before initializeWorkspaceMcp runs, so the call rejects where the numeric form resolves. The error it produces does not name the idle-timeout policy that caused it. The residual cost is dead weight against AGENTS.md Simplicity First ("No 'flexibility' or 'configurability' that wasn't requested", "No abstractions for single-use code", "No error handling for impossible scenarios") and against AGENTS.md § Code Review's dead-switch rule: a skip branch, a distinct error message, two JSDoc blocks and roughly 120-140 lines of new tests document and pin a call convention nothing uses. The new 'Runtime is not live after skipping keep-alive preheat' arm is unreachable even on the skip path, because the :203 snapshot read and the :216 this.status() read are both synchronous with no intervening await — getWorkspaceRuntimeLifecycleSnapshot() is a pure in-memory read (packages/acp-bridge/src/bridge.ts:9436-9470) — so a real bridge cannot report runtimeLive: true then false in one tick; the new test at :965-990 reaches that arm only with a fabricated bridge returning runtimeLive: snapshotCalls === 1, so the suite now reports a boot failure mode as covered when it is not.
Witness:
Four probe arms on the unmodified PR tree:

PROBE A ensure()                  preheat.calls: [[{"keepAliveMs":600000}]]
PROBE B ensure({keepAliveMs})     preheat.calls: [[{"keepAliveMs":600000}]]
                                      <- A == B: behavioural identity
PROBE D ensure(5000)              {"outcome":"resolved",
                                   "preheat":[[{"keepAliveMs":600000}]]}
PROBE C ensure({timeoutMs:5000})  {"outcome":"WorkspaceRuntimeInitializationError:
                                   Workspace runtime failed to initialize /
                                   cause=Workspace runtime stopped during
                                   Skills/MCP preparation","preheat":[]}

C vs D is the trap: the object-form spelling of the pre-existing numeric call
silently skips, arms no hold, and rejects where the numeric form resolves.

Drift-pin measurement for the duplicated constant at run-qwen-serve.ts:269-271
(mutant: coordinator :22 -> `11 * 60_000`, the local copy left at `10 * 60_000`,
then reverted):
  x runQwenServe startup observability > starts workspace MCP discovery after
    ACP preheat succeeds
  -> expected "ensure" to be called with arguments: [ { keepAliveMs: 660000 } ]
     - "keepAliveMs": 660000,
     + "keepAliveMs": 600000,
  Tests 1 failed | 381 skipped (382)

Sweeps: repo-wide `.ensure(` yields exactly the two production coordinator call
sites named above (every other hit is conversationRuntimeManager.ensure() or
DingTalk statusCards.ensure(...) — different classes); `EnsureOptions` has 2
hits, both inside its own file (:26 declaration, :194 parameter); `timeoutMs` is
set by no caller, production or test.
Call bare coordinator.ensure() at run-qwen-serve.ts:8967 and delete the speculative surface: EnsureOptions, this skip computation and its if (!skipKeepAlivePreheat) wrapper (restoring the unconditional preheat), the ternary error message, the local ENSURE_KEEP_ALIVE_MS literal and its comment, the export on the coordinator's constant if nothing else needs it, and the four tests that exist only to pin the unused convention (workspace-runtime-coordinator.test.ts:820-851, :854-866, :868-882, :965-990). Both production callers compile unchanged, and this single edit retires the duplicated constant too. If the object form is genuinely wanted as future surface, the minimum acceptable change is inverting the default to ?? false so ensure({ timeoutMs }) cannot silently skip. Note that calling ensure({ skipKeepAlivePreheat: false }) at the boot site does not fix this — the boot site already forces the non-skip branch via keepAliveMs, so that edit changes nothing observable and leaves ensure({ timeoutMs: 5_000 }) still skipping.
The fix must keep boot's effective hold at or above MCP_PREPARE_TIMEOUT_MS: workspace-runtime-coordinator.ts:23 sets const MCP_PREPARE_TIMEOUT_MS = 2 * 60_000;, the deadline prepareMcpRevision polls against, while keepAliveUntil only grows (packages/acp-bridge/src/bridge.ts:3025, :14792-14795) and :14774 gates the arming on rawKeepAliveMs > 0 — so the collapse must keep boot's 600_000 ms hold and must not turn it into 0. packages/cli/src/serve/routes/workspace-runtime.ts:64 (res.status(200).json(await coordinator.ensure());) is the only other production caller and takes the no-argument path, which must keep always preheating.
Please pin this with tests that fail without the fix: run-qwen-serve.test.ts's starts workspace MCP discovery after ACP preheat succeeds must keep asserting expect(bridge.preheat).toHaveBeenNthCalledWith(2, { keepAliveMs: ENSURE_KEEP_ALIVE_MS }) after the boot call becomes ensure() — that is what proves the hold survives the simplification, and it goes red if the internal keepAliveMs default is removed — while only its ensureSpy argument assertion changes. The coordinator-layer guarantee stays pinned by reaps a live child before MCP init unless ensure arms a keep-alive hold (:902-962).
中文说明
仍然存在,而且范围扩大了。EnsureOptions.skipKeepAlivePreheat 没有任何生产调用方设置,EnsureOptions.timeoutMs 根本没有人设置,导出的类型在自身文件之外零导入方——而对象形式的默认值让 ensure({ timeoutMs }) 与 ensure(timeoutMs) 行为不同,类型上看不出来,且本 PR 自己的测试证明它会失败。上一轮是针对 timeoutMs/keepAliveMs 提出这一点的;本轮给 keepAliveMs 找到了写入方,代价是把 skipKeepAlivePreheat 变成了孤儿。
全仓范围内 coordinator ensure 恰好只有两个生产调用方:routes/workspace-runtime.ts:64 无参调用——而该路由在 :56-62 硬性拒绝任何 body(workspace_runtime_ensure_takes_no_parameters),因此它永远无法传入 options,typeof timeoutMsOrOptions !== 'number' 为 false;run-qwen-serve.ts:8967 调用 ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }),于是 options.keepAliveMs === undefined 这一项为 false。跳过分支在实际发布的代码中永不触发,而 ensure() 与 ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }) 行为完全相同——都以 { keepAliveMs: 600000 } preheat,都使用 DEFAULT_ENSURE_TIMEOUT_MS。
真正的代价是给下一个调用方留下的陷阱。ensure({ timeoutMs: 5_000 })——既有 ensure(5_000) 的自然对象写法——会在已 live 的 runtime 上静默走进跳过分支,不挂 keep-alive hold;在文档写明的默认 channelIdleTimeoutMs = 0 策略下,prepareMcpRevision 内第一次 workspace-control 状态读取就会回收这个热子进程,发生在 initializeWorkspaceMcp 之前,于是数值形式能 resolve 的调用变成 reject。它产生的错误信息也没有点出真正肇因的空闲超时策略。剩余代价是违背 AGENTS.md「Simplicity First」(「No 'flexibility' or 'configurability' that wasn't requested」、「No abstractions for single-use code」、「No error handling for impossible scenarios」)以及 AGENTS.md § Code Review 的 dead-switch 规则的无用面积:一个跳过分支、一条专属错误信息、两段 JSDoc,以及约 120-140 行新测试,在文档化并钉住一个无人使用的调用约定。新增的 'Runtime is not live after skipping keep-alive preheat' 分支即使在跳过路径上也不可达,因为 :203 的快照读取与 :216 的 this.status() 读取都是同步的、之间没有 await——getWorkspaceRuntimeLifecycleSnapshot() 是纯内存读取(packages/acp-bridge/src/bridge.ts:9436-9470)——真实 bridge 不可能在同一个 tick 内先报 runtimeLive: true 再报 false;:965-990 的新测试只能靠一个返回 runtimeLive: snapshotCalls === 1 的伪造 bridge 才能到达该分支,于是测试套件把一个启动失败模式报告为已覆盖,而实际上并没有。
建议在 run-qwen-serve.ts:8967 改为无参调用 coordinator.ensure(),并删掉这些预留面积:EnsureOptions、本跳过计算及其 if (!skipKeepAlivePreheat) 包裹(恢复无条件 preheat)、三元错误信息、run-qwen-serve.ts 中本地的 ENSURE_KEEP_ALIVE_MS 字面量及其注释、coordinator 常量上若无其他需要则可去掉的 export,以及只为钉住这个无人使用的约定而存在的四个测试(workspace-runtime-coordinator.test.ts:820-851、:854-866、:868-882、:965-990)。两个生产调用方都无需改动即可编译,而这一次修改同时消除了那个重复的常量。如果确实想把对象形式作为未来接口保留,最低可接受的改动是把默认值反转为 ?? false,使 ensure({ timeoutMs }) 不会静默跳过。请注意在 boot 处调用 ensure({ skipKeepAlivePreheat: false }) 不能修复本问题——boot 处已经通过 keepAliveMs 强制走非跳过分支,那样改没有任何可观察变化,ensure({ timeoutMs: 5_000 }) 仍会跳过。
修复必须让 boot 的有效 hold 不低于 MCP_PREPARE_TIMEOUT_MS:workspace-runtime-coordinator.ts:23 定义了 const MCP_PREPARE_TIMEOUT_MS = 2 * 60_000;,即 prepareMcpRevision 轮询所用的截止时间;而 keepAliveUntil 只增不减(packages/acp-bridge/src/bridge.ts:3025、:14792-14795),:14774 又以 rawKeepAliveMs > 0 为挂载条件——因此收敛之后 boot 仍须保持 600_000 ms 的 hold,不能变成 0。packages/cli/src/serve/routes/workspace-runtime.ts:64(res.status(200).json(await coordinator.ensure());)是唯一另一个生产调用方,走无参路径,必须继续总是 preheat。
请用「去掉修复就会变红」的测试钉住它:boot 调用改为 ensure() 之后,run-qwen-serve.test.ts 的 starts workspace MCP discovery after ACP preheat succeeds 必须继续断言 expect(bridge.preheat).toHaveBeenNthCalledWith(2, { keepAliveMs: ENSURE_KEEP_ALIVE_MS })——这正是证明 hold 在简化后依然存在的断言,去掉内部的 keepAliveMs 默认值它会变红——只有它的 ensureSpy 参数断言需要随之改变。coordinator 层的保证仍由 reaps a live child before MCP init unless ensure arms a keep-alive hold(:902-962)钉住。
— qwen3.8-max via Qwen Code /review (v0.23.0)
Extend the preheat success guard to skip discovery when runtime startup
already failed, route boot diagnostics through daemonLog (including cause
on failure), and add tests that go red if discovery runs on preheat
failure, targets non-primary workspaces, or races shutdown/startup failure.
|
Addressed round-3 Suggestions on
Local: |
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
1 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- R2-2 dead EnsureOptions switches (packages/cli/src/serve/workspace-runtime-coordinator.ts:207) — still stands, already reported (comment 3946709225)
Not explored to full depth (tool budget reached): "agent 6a": did not confirm the default value of folderTrustEnabled (whether folder trust is off out of the box), which decides how reachable Finding 1 is.; "agent 6a": did not confirm whether the MCP per-server refusal path in packages/core/src/tools/mcp-client-manager.ts has any consent/approval cause beyond 'budget_exhaus…; "agent 6a": did not read PR #11145's existing review comments, so I cannot say whether Finding 1 was already raised and ruled acceptable as the feature's intent.; "agent 1c": child-side handler of the workspaceMcpInitialize ext-method (whether the spawned qwen --acp child applies its own trusted-folder gate before loading workspa…; "agent 1c": whether runQwenServe 's rejected-boot path in the runtime startup fails test releases the preheated bridge (no handle.close() in that case)., and 1 more.
Deferred under the convergence posture (round 4, not a blocker) — recorded, not requested in this round:
packages/cli/src/serve/run-qwen-serve.ts:8965 — [probe] ensure() resolves with a not-ready capability status that the hook discards with void, so a boot whose discovery ran out of budget logs nothingpackages/cli/src/serve/run-qwen-serve.test.ts:16644 — [probe] unhandledRejection listener acquired before an await outside the try is never released when runQwenServe rejects, and vitest then suppresses later tests' genuine leaks
Convergence: round 4 posted 7 inline comment(s), 7 of them reported for the first time; the previous round posted 5 (3 new). Findings keep coming back to the same files: packages/cli/src/serve/run-qwen-serve.ts (findings in rounds 1, 2, 3; 5 more now). The rate of new findings is not falling. A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. Batching the remaining fixes and verifying them before the next push, or dropping this PR's reviews to --severity-floor critical, keeps the loop from re-deriving the same set. (Observation only — nothing was withheld from this review because of this observation.)
中文说明
本轮确认的 1 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未探索到全部深度(达到工具调用预算):"agent 6a":did not confirm the default value of folderTrustEnabled (whether folder trust is off out of the box), which decides how reachable Finding 1 is.;"agent 6a":did not confirm whether the MCP per-server refusal path in packages/core/src/tools/mcp-client-manager.ts has any consent/approval cause beyond 'budget_exhaus…;"agent 6a":did not read PR #11145's existing review comments, so I cannot say whether Finding 1 was already raised and ruled acceptable as the feature's intent.;"agent 1c":child-side handler of the workspaceMcpInitialize ext-method (whether the spawned qwen --acp child applies its own trusted-folder gate before loading workspa…;"agent 1c":whether runQwenServe 's rejected-boot path in the runtime startup fails test releases the preheated bridge (no handle.close() in that case).,另有 1 条。
收敛姿态下延后(第 4 轮,非阻断)——已记录,本轮不要求修改:共 2 条(原文未翻译,列表见上方英文部分)。
收敛情况:第 4 轮发布了 7 条行内评论,其中 7 条是首次提出;上一轮发布了 5 条(其中 3 条首次提出)。发现反复回到同一批文件:packages/cli/src/serve/run-qwen-serve.ts(第 1、2、3 轮已出过发现,本轮又有 5 条)。新发现的产出速度没有下降。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。把剩余修复攒成一批、验证后再推送,或将本 PR 的评审降到 --severity-floor critical,可以避免循环反复推导同一组发现。(仅为观察——本轮评审未因此扣留任何内容。)
— qwen3.8-max via Qwen Code /review (v0.23.0)
| }, | ||
| { | ||
| preheatBridge: true, | ||
| channelWorkerSupervisorFactory: vi.fn(() => worker), |
There was a problem hiding this comment.
[Critical] The channel-worker mock passed here does not typecheck, so packages/cli does not compile. The inline worker literal above declares snapshot: vi.fn(() => ({ enabled: true, state: 'failed', channels: ['telegram'], exitCode: 1 })) with no type annotation, so state widens from the literal 'failed' to string and the returned object no longer satisfies ChannelWorkerSupervisor.snapshot(): ChannelWorkerSnapshot — which makes the factory unassignable to (opts: CreateChannelWorkerSupervisorOptions) => ChannelWorkerSupervisor.
Vitest strips types, so all 386 tests in this file still pass and the test suite shows nothing; the break surfaces only on the next build or typecheck, where npm run build --workspace="packages/cli" exits 1 and every workspace build downstream of it is blocked. A full-profile CI install fails too, because scripts/prepare.js runs npm run build from npm ci unless QWEN_SKIP_PREPARE is set. That is the repository's documented done-gate (npm run build && npm run typecheck) going red.
Witness:
npm run build --workspace="packages/cli" -> exit 1
src/serve/run-qwen-serve.test.ts(16915,9): error TS2322: Type 'Mock<() => { start: ...; snapshot: Mock<...>; ... }>'
  is not assignable to type '(opts: CreateChannelWorkerSupervisorOptions) => ChannelWorkerSupervisor'.
    The types of 'snapshot(...).state' are incompatible between these types.
      Type 'string' is not assignable to type 'ChannelWorkerState'.
npx tsc --noEmit (packages/cli, non-incremental) -> exit 1, exactly one error, the same one
npx vitest run src/serve/run-qwen-serve.test.ts -> 386 passed (types stripped)
Annotate the mock's snapshot return type so state keeps its literal type — ChannelWorkerSnapshot is already imported at line 73:
    snapshot: vi.fn(
      (): ChannelWorkerSnapshot => ({
        enabled: true,
        state: 'failed',
        channels: ['telegram'],
        exitCode: 1,
      }),
    ),
state: 'failed' as const fixes it equally. Both tsc --build and a clean tsc --noEmit report only this one site, so no other error is hiding behind it.
The fix must not violate this: ChannelWorkerSnapshot.state is ChannelWorkerState = 'disabled' | 'starting' | 'running' | 'exited' | 'failed' | 'stopped' (packages/cli/src/serve/channel-worker-supervisor.ts:128-138), and the file's existing typed helper makeWorker(snapshot: ChannelWorkerSnapshot) at line 12421 is declared inside describe('runQwenServe channel worker supervisor') (line 12383), so it is not in scope in describe('runQwenServe startup observability') (line 16217) where this test lives — the fix cannot simply call it without hoisting the helper.
Please pin this with a check that fails without the fix: npm run build --workspace="packages/cli" (and npx tsc --noEmit in packages/cli) must go from exit 1 to exit 0 — that is the gate that is red today. The behaviour itself is already pinned by does not schedule workspace MCP discovery after runtime startup fails, measured green at runtime, so no test content needs to change.
中文说明
传入的 channel-worker mock 无法通过类型检查,因此 packages/cli 无法编译。上方的内联 worker 字面量声明了 snapshot: vi.fn(() => ({ enabled: true, state: 'failed', channels: ['telegram'], exitCode: 1 })),没有类型注解,于是 state 从字面量 'failed' 宽化成了 string,返回的对象不再满足 ChannelWorkerSupervisor.snapshot(): ChannelWorkerSnapshot——这使得该工厂无法赋值给 (opts: CreateChannelWorkerSupervisorOptions) => ChannelWorkerSupervisor。
vitest 会剥除类型,所以本文件的 386 个测试仍然全部通过,测试套件看不出任何问题;这个破坏只会在下一次 build 或 typecheck 时显现:npm run build --workspace="packages/cli" 以 1 退出,并且它下游的每一个 workspace build 都被阻断。完整 profile 的 CI install 也会失败,因为 scripts/prepare.js 会在 npm ci 时运行 npm run build,除非设置了 QWEN_SKIP_PREPARE。这就是仓库自己文档化的完成关口(npm run build && npm run typecheck)变红。
证据:
npm run build --workspace="packages/cli" -> exit 1
src/serve/run-qwen-serve.test.ts(16915,9): error TS2322: Type 'Mock<() => { start: ...; snapshot: Mock<...>; ... }>'
  is not assignable to type '(opts: CreateChannelWorkerSupervisorOptions) => ChannelWorkerSupervisor'.
    The types of 'snapshot(...).state' are incompatible between these types.
      Type 'string' is not assignable to type 'ChannelWorkerState'.
npx tsc --noEmit (packages/cli, non-incremental) -> exit 1, exactly one error, the same one
npx vitest run src/serve/run-qwen-serve.test.ts -> 386 passed (types stripped)
请给 mock 的 snapshot 返回类型加上注解,让 state 保留字面量类型——ChannelWorkerSnapshot 已在第 73 行导入:
    snapshot: vi.fn(
      (): ChannelWorkerSnapshot => ({
        enabled: true,
        state: 'failed',
        channels: ['telegram'],
        exitCode: 1,
      }),
    ),
state: 'failed' as const 同样可以修好。tsc --build 和干净的 tsc --noEmit 都只报告这一处,所以后面没有藏着别的错误。
修复不得违反这一点:ChannelWorkerSnapshot.state 是 ChannelWorkerState = 'disabled' | 'starting' | 'running' | 'exited' | 'failed' | 'stopped'(packages/cli/src/serve/channel-worker-supervisor.ts:128-138);而文件里已有的带类型辅助函数 makeWorker(snapshot: ChannelWorkerSnapshot)(第 12421 行)声明在 describe('runQwenServe channel worker supervisor')(第 12383 行)内部,在本测试所在的 describe('runQwenServe startup observability')(第 16217 行)里不在作用域内——不先把该辅助函数上提,就不能直接调用它。
请用一个「去掉修复就会失败」的检查把它钉住:npm run build --workspace="packages/cli"(以及 packages/cli 下的 npx tsc --noEmit)必须从 exit 1 变成 exit 0——这就是今天变红的那道关口。行为本身已由 does not schedule workspace MCP discovery after runtime startup fails 钉住,实测为绿,因此不需要改动测试内容。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| const ensureSpy = vi | ||
| .spyOn(WorkspaceRuntimeCoordinator.prototype, 'ensure') | ||
| .mockImplementation(async () => { | ||
| throw new WorkspaceRuntimeInitializationError( |
There was a problem hiding this comment.
[Suggestion] This round replaced the cause-less throw new Error('ensure boom') here with a cause-bearing WorkspaceRuntimeInitializationError, and that removed the only execution of the cause === undefined branch of the new failure-log formatter at run-qwen-serve.ts:8968-8976. Cause-less rejections do reach that branch in production: WorkspaceRuntimeStillStartingError sets no cause and is rethrown verbatim by the first withTimeout catch (workspace-runtime-coordinator.ts:218), and assertAcceptingWork() throws WorkspaceDrainingError(cwd, undefined). WorkspaceRuntimeInitializationError always sets a cause (:51-55), so the error this test uses can never exercise the branch.
The cost is that a future edit dropping the ternary guard, or reading err.cause?.message unguarded, writes workspace MCP discovery after preheat failed: Workspace runtime is still starting (undefined) into the daemon log an operator is grepping during a boot-timeout triage — and the suite stays green. Measured: flattening the guard leaves all 386 tests passing.
Witness:
MUTATION (guard -> ` (${cause})`), full file:  MUTATION_EXIT=0  Tests 386 passed (386)
INTACT  (guard restored),   full file:  INTACT_EXIT=0   Tests 386 passed (386)
FLIP - added one cause-less case (mock ensure -> new WorkspaceRuntimeStillStartingError(),
       assert the daemon log does not contain '(undefined)'):
  intact guard:  RUN_A_EXIT=0 -> "...preheat failed: Workspace runtime is still starting"
  mutated guard: RUN_B_EXIT=1 -> "...preheat failed: Workspace runtime is still starting (undefined)"
                   AssertionError: expected '...' not to contain '(undefined)'
Anchor check: git show 557f1b13d5:...test.ts line 16617 is `throw new Error('ensure boom');` (cause-less).
Add a second case (or a sibling it) whose ensure mock rejects with a cause-less error, reusing the existing daemonLogBaseDir + waitForDaemonLog plumbing:
      .mockImplementation(async () => {
        throw new WorkspaceRuntimeStillStartingError();
      });
      // ...
      await waitForDaemonLog(
        logBaseDir,
        'workspace MCP discovery after preheat failed: Workspace runtime is still starting',
      );
and assert the line does not contain (undefined).
The fix must not reach for the deleted debug-log plumbing (QWEN_DEBUG_LOG_FILE, qwenCore.setDebugLogSession, Storage.getDebugLogPath) — this round moved the message from debugLogger.debug to daemonLog.warn (run-qwen-serve.ts:8973) and deleted that global-state setup/teardown, so the only supported observation point is { preheatBridge: true, daemonLogBaseDir: logBaseDir } plus the new waitForDaemonLog helper.
Please pin this with a test that fails without the fix: the new cause-less case must go red when (cause ? (${cause}) : '') at run-qwen-serve.ts:8975 is flattened to ` (${cause})` — today that mutation leaves all 386 tests green, while the added case reddens with expected '...' not to contain '(undefined)'.
中文说明
本轮把这里原本不带 cause 的 throw new Error('ensure boom') 换成了带 cause 的 WorkspaceRuntimeInitializationError,于是 run-qwen-serve.ts:8968-8976 新增的失败日志格式化代码中,cause === undefined 那个分支失去了唯一一次执行。生产代码里确实会有不带 cause 的 rejection 到达该分支:WorkspaceRuntimeStillStartingError 不设 cause,并由第一个 withTimeout 的 catch 原样重新抛出(workspace-runtime-coordinator.ts:218);assertAcceptingWork() 则抛出 WorkspaceDrainingError(cwd, undefined)。而 WorkspaceRuntimeInitializationError 总是设置 cause(:51-55),所以本测试用的错误永远无法触发该分支。
代价是:将来有人去掉三元判断的守卫,或不加守护地读 err.cause?.message,就会把 workspace MCP discovery after preheat failed: Workspace runtime is still starting (undefined) 写进运维人员在启动超时排查时正在 grep 的守护进程日志——而测试套件仍然全绿。实测:把守卫拍平后,386 个测试全部通过。
证据:
MUTATION (guard -> ` (${cause})`), full file:  MUTATION_EXIT=0  Tests 386 passed (386)
INTACT  (guard restored),   full file:  INTACT_EXIT=0   Tests 386 passed (386)
FLIP - added one cause-less case (mock ensure -> new WorkspaceRuntimeStillStartingError(),
       assert the daemon log does not contain '(undefined)'):
  intact guard:  RUN_A_EXIT=0 -> "...preheat failed: Workspace runtime is still starting"
  mutated guard: RUN_B_EXIT=1 -> "...preheat failed: Workspace runtime is still starting (undefined)"
                   AssertionError: expected '...' not to contain '(undefined)'
Anchor check: git show 557f1b13d5:...test.ts line 16617 is `throw new Error('ensure boom');` (cause-less).
请加一个用例(或一个同级 it),其 ensure mock 以不带 cause 的错误 reject,复用现有的 daemonLogBaseDir + waitForDaemonLog 管道:
      .mockImplementation(async () => {
        throw new WorkspaceRuntimeStillStartingError();
      });
      // ...
      await waitForDaemonLog(
        logBaseDir,
        'workspace MCP discovery after preheat failed: Workspace runtime is still starting',
      );
并断言该行不包含 (undefined)。
修复不得去找已被删除的 debug-log 管道(QWEN_DEBUG_LOG_FILE、qwenCore.setDebugLogSession、Storage.getDebugLogPath)——本轮已把该消息从 debugLogger.debug 改为 daemonLog.warn(run-qwen-serve.ts:8973)并删除了那套全局状态的 setup/teardown,因此唯一受支持的观察点是 { preheatBridge: true, daemonLogBaseDir: logBaseDir } 加上新的 waitForDaemonLog 辅助函数。
请用一个「去掉修复就会变红」的测试把它钉住:把 run-qwen-serve.ts:8975 的 (cause ? (${cause}) : '') 拍平成 ` (${cause})` 时,新增的无 cause 用例必须变红——今天这个变异体下 386 个测试全绿,而加上该用例后会以 expected '...' not to contain '(undefined)' 变红。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| const scheduleWorkspaceMcpDiscoveryAfterPreheat = ( | ||
| app: Application, | ||
| ): void => { | ||
| if (shuttingDown || runtimeStartupError !== undefined) { |
There was a problem hiding this comment.
[Suggestion] R2-3: (fix-induced) The runtimeStartupError !== undefined term added in answer to R2-3 does close R2-3's reported input — the guard no longer checks only one of the closure's two terminal states — but the added term ships with no test that goes red without it, and neither arm of the skip-reason ternary below it is asserted anywhere. The test named for it, does not schedule workspace MCP discovery after runtime startup fails, boots without resolveOnListen, so runQwenServe takes the else branch at :9592-9601 where a startup failure calls handle.close() (setting shuttingDown = true at :9153) and only then rejects. By the time resolvePreheat() runs, the guard's first term is already true — that test's own run printed skipped: shutting down, not runtime startup failed.
So deleting the new term leaves the suite green, and swapping the two ternary arms leaves it green while flipping the reason an operator is told. The production mode the test does not cover is the one that ships: fast-path.ts:616-617 boots with resolveOnListen: true. The decisive case there is a runtime failure that does not close the server (the startup timer at :8617-8628, or a publishLiveDiscovery failure) with the preheat resolving afterwards — in that window the new term is the only thing preventing ensure({ keepAliveMs: 10 min }) from firing at a runtime app failRuntimeStartup has already disposed.
Witness:
Mutation A - delete `|| runtimeStartupError !== undefined`:  Tests 386 passed (386)
Mutation B - swap the two ternary arms:                      Tests 386 passed (386)
  baseline line:  ...[INFO] [DAEMON] workspace MCP discovery after preheat skipped: shutting down
  mutated line:   ...[INFO] [DAEMON] workspace MCP discovery after preheat skipped: runtime startup failed  (x2)
Mutation C - `shuttingDown || runtimeStartupSettled` instead:
  x starts workspace MCP discovery after ACP preheat succeeds -> expected "ensure" to be called once, but got 0 times
Probe D - resolveOnListen: true + failing channel worker:
  preheatCalls=1 ensureCalls=0 stderrDiscoveryLines=["...skipped: shutting down"]   (first term fired)
Grep: the only two skip needles asserted anywhere in the file are
  '...lifecycle is not supported' (:16700-16701) and '...no primary runtime' (:16746).
Give the test the production boot mode and pin both arms — add resolveOnListen: true and daemonLogBaseDir, await the reason line, then resolve preheat:
      await waitForDaemonLog(
        logBaseDir,
        'workspace MCP discovery after preheat skipped: runtime startup failed',
      );
      expect(ensureSpy).not.toHaveBeenCalled();
and add await waitForDaemonLog(logBaseDir, 'workspace MCP discovery after preheat skipped: shutting down') to does not schedule workspace MCP discovery when shutting down during preheat, so both arms of the ternary at :8942 are pinned.
The fix must not violate this: const deferRuntimeUntilFirstHealth = deps.resolveOnListen === true && deps.deferRuntimeUntilFirstHealth === true; (run-qwen-serve.ts:4339-4340) — adding resolveOnListen: true alone keeps the eager startRuntime() call site at :9028 that this test must exercise, while adding deferRuntimeUntilFirstHealth: true as well would move the runtime start behind a health probe and change which site preheats. runtimeStartupSettled is also not a viable substitute for runtimeStartupError (measured: it breaks two healthy-path tests), and the new test must land the preheat .then before handle.close() sets shuttingDown (:9153), or the first term short-circuits and it pins nothing.
Please pin this with a test that fails without the fix: the reworked case must go red when || runtimeStartupError !== undefined is removed from run-qwen-serve.ts:8939, and the shutdown case must go red when the ternary arms at :8942 are swapped — both mutations are measured green today.
中文说明
R2-3:(由修复引入)为回应 R2-3 而新增的 runtimeStartupError !== undefined 这一项,确实关闭了 R2-3 报告的问题——守卫不再只检查该闭包两个终态中的一个——但这一新增项发布时没有任何「去掉它就会变红」的测试,而且它下方跳过原因三元表达式的两个分支在任何地方都没有被断言。专为它命名的测试 does not schedule workspace MCP discovery after runtime startup fails 启动时没有传 resolveOnListen,于是 runQwenServe 走 :9592-9601 的 else 分支:启动失败会先调用 handle.close()(在 :9153 把 shuttingDown 置为 true),然后才 reject。等 resolvePreheat() 执行时,守卫的第一项已经为真——该测试自己的运行打出的是 skipped: shutting down,而不是 runtime startup failed。
因此删掉这一新项套件仍然全绿;交换三元表达式的两个分支也仍然全绿,只是把告知运维人员的原因翻了个面。测试没覆盖的那个生产模式恰好就是实际发布的那个:fast-path.ts:616-617 以 resolveOnListen: true 启动。那里真正决定性的情形是:运行时启动失败但不关闭 server(:8617-8628 的启动计时器,或 publishLiveDiscovery 失败),而 preheat 在其之名才 resolve——在这个窗口里,新增项是唯一能阻止 ensure({ keepAliveMs: 10 min }) 打到一个已被 failRuntimeStartup 释放的 runtime app 上的东西。
证据:
Mutation A - delete `|| runtimeStartupError !== undefined`:  Tests 386 passed (386)
Mutation B - swap the two ternary arms:                      Tests 386 passed (386)
  baseline line:  ...[INFO] [DAEMON] workspace MCP discovery after preheat skipped: shutting down
  mutated line:   ...[INFO] [DAEMON] workspace MCP discovery after preheat skipped: runtime startup failed  (x2)
Mutation C - `shuttingDown || runtimeStartupSettled` instead:
  x starts workspace MCP discovery after ACP preheat succeeds -> expected "ensure" to be called once, but got 0 times
Probe D - resolveOnListen: true + failing channel worker:
  preheatCalls=1 ensureCalls=0 stderrDiscoveryLines=["...skipped: shutting down"]   (first term fired)
Grep: the only two skip needles asserted anywhere in the file are
  '...lifecycle is not supported' (:16700-16701) and '...no primary runtime' (:16746).
请给测试换上生产的启动模式并把两个分支都钉住——加上 resolveOnListen: true 与 daemonLogBaseDir,先等到原因行,再 resolve preheat:
      await waitForDaemonLog(
        logBaseDir,
        'workspace MCP discovery after preheat skipped: runtime startup failed',
      );
      expect(ensureSpy).not.toHaveBeenCalled();
并给 does not schedule workspace MCP discovery when shutting down during preheat 加上 await waitForDaemonLog(logBaseDir, 'workspace MCP discovery after preheat skipped: shutting down'),让 :8942 三元表达式的两个分支都被钉住。
修复不得违反这一点:const deferRuntimeUntilFirstHealth = deps.resolveOnListen === true && deps.deferRuntimeUntilFirstHealth === true;(run-qwen-serve.ts:4339-4340)——只加 resolveOnListen: true 会保留本测试必须覆盖的 :9028 那个提前 startRuntime() 调用点;而同时加上 deferRuntimeUntilFirstHealth: true 会把运行时启动挪到健康探针之后,改变到底哪个调用点做 preheat。runtimeStartupSettled 也不能代替 runtimeStartupError(实测会打破两个健康路径测试);而且新测试必须让 preheat 的 .then 在 handle.close() 把 shuttingDown 置为 true(:9153)之前落地,否则第一项会短路,什么也钉不住。
请用一个「去掉修复就会变红」的测试把它钉住:从 run-qwen-serve.ts:8939 删除 || runtimeStartupError !== undefined 时,改造后的用例必须变红;交换 :8942 的三元分支时,关闭用例必须变红——这两个变异体今天实测都是绿的。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| if (!coordinator) { | ||
| daemonLog.info( | ||
| 'workspace MCP discovery after preheat skipped: ' + | ||
| 'workspace runtime lifecycle is not supported', |
There was a problem hiding this comment.
[Suggestion] R3-1: (fix-induced) No code change is requested here — the fix is an edit to the PR description, in both language halves. The Risk & Scope sentence written in answer to R3-1 states the opposite of what the same commit's code does. EN line 51 reads: "Skip paths (shutting down, runtime startup failed, no primary runtime, unsupported lifecycle) log to daemonLog.info; preparation failures log to daemonLog.warn with err.cause when present. Benign skips stay quiet on stderr; only preheat rejection still uses the existing stderr line." — and 中文 line 99 reads: "…写 daemonLog.info;准备失败写 daemonLog.warn 并附带 err.cause(如有)。良性跳过不打 stderr;仅 preheat 拒绝仍走既有 stderr 行。" The bolded clause contradicts its own preceding sentence: daemonLog.info tees to stderr unconditionally, so every skip branch this round moved off debugLogger now prints an operator-visible stderr line at boot.
A daemon whose bridge lacks lifecycle support, or that has no primary runtime, therefore emits an extra stderr line on every start, and a maintainer reading the section R3-1 had just rewritten for accuracy concludes the boot path adds no stderr output. There is no configuration in which the skips are quiet: tee() writes stderr first and unconditionally for every level, the only env gate (QWEN_DAEMON_LOG_FILE) opts out of the file and returns a stderr-ONLY logger, and run-qwen-serve.ts:3953-3956 passes no stderr override.
Witness:
The PR's own passing test, run with the two streams separated (> out.log 2> err.log):
  Tests 1 passed | 385 skipped (386)   # 'logs when boot MCP discovery skips because lifecycle is unsupported'
  STDOUT hits for "workspace MCP discovery after preheat skipped": 0
  STDERR: 2026-09-07T12:50:24.865Z [INFO] [DAEMON] workspace MCP discovery after preheat skipped: workspace runtime lifecycle is not supported
  surrounding STDERR in the same run (same tee):
    qwen serve: /acp WebSocket transport enabled on /acp
    ...[INFO] [DAEMON] route=GET /daemon/status durationMs=8 status=200 request completed
    ...[INFO] [DAEMON] daemon stopped
Description quoted from the live body (gh api repos/QwenLM/qwen-code/pulls/11145 --jq .body).
Edit the description in both halves to state what ships, e.g. EN: "Skip and failure lines go to the daemon log and to stderr through the daemonLog tee, alongside the daemon's existing per-request INFO lines; only preheat rejection uses the dedicated qwen serve: ACP preheat failed … line." 中文: "跳过与失败行会经 daemonLog 的 tee 同时写入守护进程日志和 stderr,与守护进程既有的每请求 INFO 行并列;仅 preheat 拒绝使用专用的 qwen serve: ACP preheat failed … 行。"
The fix must not violate this: daemon-logger.ts:1385-1399 — raw calls submitFileRecord and never tee, so it is the only level-info path that does not reach stderr; and R1-2's round-3 request (comment 3946709217) was specifically that these skip branches reroute to daemonLog.info, so switching them to raw to satisfy this description sentence would undo the fix that made them visible at all. packages/cli/src/commands/serve.ts:747-751 also documents stderr as an intended operator channel ("surface the active policy in stderr (journald / docker logs)"), so the honest resolution is the description edit, not quieter code.
Please pin this with a check that fails without the fix: N/A — the fix is an edit to the PR description, so it adds no guard, branch or behaviour a test can pin. Re-reading the two Risk & Scope sentences against a boot run's captured stderr is the check.
中文说明
R3-1:(由修复引入)这里不要求代码改动——修复是对 PR 描述的一次编辑,两个语言版本都要改。为回应 R3-1 而写入的 Risk & Scope 那句话,说的恰好与同一个 commit 的代码行为相反。英文第 51 行写的是:「跳过路径(shutting down、runtime startup failed、无 primary runtime、lifecycle 不支持)写 daemonLog.info;准备失败写 daemonLog.warn 并在存在时附带 err.cause。良性跳过在 stderr 上保持安静;仅 preheat 拒绝仍使用既有的 stderr 行。」中文第 99 行写的是:「…写 daemonLog.info;准备失败写 daemonLog.warn 并附带 err.cause(如有)。良性跳过不打 stderr;仅 preheat 拒绝仍走既有 stderr 行。」加粗的那一句与它自己的前一句相矛盾:daemonLog.info 会无条件地 tee 到 stderr,所以本轮从 debugLogger 改过来的每一个跳过分支,现在都会在启动时打出一行运维人员可见的 stderr。
因此一个 bridge 不支持 lifecycle、或没有 primary runtime 的守护进程,每次启动都会多打一行 stderr;而一位阅读这个刚被 R3-1 重写以求准确的小节的 maintainer,会得出「启动路径不增加 stderr 输出」的结论。不存在任何一种配置能让这些跳过保持安静:tee() 对每一个级别都会先无条件地写 stderr;唯一的环境变量开关(QWEN_DAEMON_LOG_FILE)退出的是文件,返回的是一个只写 stderr 的 logger;而 run-qwen-serve.ts:3953-3956 也没有传 stderr 覆盖。
证据:
The PR's own passing test, run with the two streams separated (> out.log 2> err.log):
  Tests 1 passed | 385 skipped (386)   # 'logs when boot MCP discovery skips because lifecycle is unsupported'
  STDOUT hits for "workspace MCP discovery after preheat skipped": 0
  STDERR: 2026-09-07T12:50:24.865Z [INFO] [DAEMON] workspace MCP discovery after preheat skipped: workspace runtime lifecycle is not supported
  surrounding STDERR in the same run (same tee):
    qwen serve: /acp WebSocket transport enabled on /acp
    ...[INFO] [DAEMON] route=GET /daemon/status durationMs=8 status=200 request completed
    ...[INFO] [DAEMON] daemon stopped
Description quoted from the live body (gh api repos/QwenLM/qwen-code/pulls/11145 --jq .body).
请把两个语言版本的描述都改成实际发布的行为,例如英文:「跳过与失败行会经 daemonLog 的 tee 同时写入守护进程日志和 stderr,与守护进程既有的每请求 INFO 行并列;仅 preheat 拒绝使用专用的 qwen serve: ACP preheat failed … 行。」
修复不得违反这一点:daemon-logger.ts:1385-1399——raw 只调 submitFileRecord,从不调 tee,因此它是唯一不会到达 stderr 的 info 级路径;而 R1-2 在第三轮的要求(评论 3946709217)恰恰就是让这些跳过分支改走 daemonLog.info,所以为了让这句描述成立而把它们改成 raw,会把当初让它们可见的那个修复撤销掉。packages/cli/src/commands/serve.ts:747-751 也把 stderr 写明为预期的运维通道(「surface the active policy in stderr (journald / docker logs)」),所以诚实的做法是改描述,而不是让代码更安静。
请用一个「去掉修复就会失败」的检查把它钉住:N/A——修复是对 PR 描述的编辑,不会新增任何测试可以钉住的守卫、分支或行为。把两句 Risk & Scope 与一次启动运行捕获的 stderr 对着重读,就是这个检查。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| .catch((err) => { | ||
| const message = err instanceof Error ? err.message : String(err); | ||
| const cause = | ||
| err instanceof Error && err.cause instanceof Error |
There was a problem hiding this comment.
[Suggestion] An MCP-side boot failure loses its real reason here: the cause is wrapped twice and unwrapped once, so the line this round made operator-visible prints the wrapper as its own cause. prepareMcpRevision wraps the underlying error in WorkspaceRuntimeInitializationError at workspace-runtime-coordinator.ts:587, ensure wraps that again at :259, and this read keeps only err.cause.message one level deep. WorkspaceRuntimeInitializationError has a single fixed message (:53), so both levels read identically and the daemon log prints workspace MCP discovery after preheat failed: Workspace runtime failed to initialize (Workspace runtime failed to initialize).
The real reason survives only at err.cause.cause.message, which nothing reads, and capabilities.mcp.error.message records the same wrapper text — ServeWorkspaceRuntimeCapabilityStatus.error is { code: string; message: string } (packages/acp-bridge/src/status.ts:13-18) with no cause or detail field, so no route can expose anything deeper either. The diagnostic this round added for diagnosability therefore carries no reason at all on exactly the path an operator would be triaging. The Skills side does not have this defect: prepareSkillsRevision (:533-541) is structurally identical but does not wrap, which is why the same probe's Skills arm printed the real reason.
Witness:
Real WorkspaceRuntimeCoordinator driven through the boot call form ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }),
two arms, one run, intact PR code:
PROBE MCP: "injectedReason":"ACP child exited during MCP preparation","causeDepth":2,
  "errMessage":"Workspace runtime failed to initialize","causeMessage":"Workspace runtime failed to initialize",
  "causeCauseMessage":"ACP child exited during MCP preparation",
  "operatorVisibleLine":"workspace MCP discovery after preheat failed: Workspace runtime failed to initialize (Workspace runtime failed to initialize)",
  "capabilities":{"mcp":{"state":"error","error":{"code":"mcp_prepare_failed","message":"Workspace runtime failed to initialize"}},"skills":{"state":"ready"}}
PROBE SKILLS: "causeDepth":1,"causeMessage":"ACP child exited during Skills preparation",
  "operatorVisibleLine":"...failed: Workspace runtime failed to initialize (ACP child exited during Skills preparation)"
FLIP (candidate fix = delete the wrap at coordinator:587), MCP arm re-run:
  "causeDepth":1,"causeMessage":"ACP child exited during MCP preparation",
  "operatorVisibleLine":"...failed: Workspace runtime failed to initialize (ACP child exited during MCP preparation)"
  SKILLS arm byte-identical before/after the flip - the flip is MCP-specific, so it isolates the line.
Unwrap to the innermost cause, which is the fix that stays inside this PR's own changed lines:
            let causeError: unknown = err;
            while (causeError instanceof Error && causeError.cause instanceof Error) {
              causeError = causeError.cause;
            }
            const cause =
              causeError instanceof Error && causeError !== err
                ? causeError.message
                : undefined;
Note this repairs the log line only. capabilities.mcp.error.message is written inside the coordinator by recordMcpError, so fixing that sink too means touching workspace-runtime-coordinator.ts:587 (or unwrapping in recordMcpError) — pre-existing code outside this PR's diff, and better as a follow-up than as a widening of this change.
The fix must not violate this: prepareSkillsRevision's counterpart at workspace-runtime-coordinator.ts:533-541 does not wrap, so the two arms are asymmetric by exactly one line (:587) — a fix that instead drops the hook's cause read entirely would silence the Skills arm's real reason too, which the same probe shows is currently correct.
Please pin this with a test that fails without the fix: a boot-discovery failure case whose ensure mock rejects with a doubly-wrapped error (new WorkspaceRuntimeInitializationError(new WorkspaceRuntimeInitializationError(new Error('real reason')))) and asserts waitForDaemonLog(logBaseDir, '...failed: Workspace runtime failed to initialize (real reason)') — removing the unwrap loop must turn it red, since today the emitted line reads (Workspace runtime failed to initialize).
中文说明
MCP 侧的启动失败在这里会丢掉真正的原因:cause 被包了两层,而这里只解开一层,于是本轮刚变成运维人员可见的那一行,把包装器自己当成了原因打出来。prepareMcpRevision 在 workspace-runtime-coordinator.ts:587 把底层错误包进 WorkspaceRuntimeInitializationError,ensure 在 :259 又包一层,而这里的读取只取 err.cause.message 一层。WorkspaceRuntimeInitializationError 只有一个固定消息(:53),所以两层读起来完全一样,守护进程日志最终打出 workspace MCP discovery after preheat failed: Workspace runtime failed to initialize (Workspace runtime failed to initialize)。
真正的原因只存在于 err.cause.cause.message,而没有任何代码读它;capabilities.mcp.error.message 记录的也是同一个包装器文本——ServeWorkspaceRuntimeCapabilityStatus.error 是 { code: string; message: string }(packages/acp-bridge/src/status.ts:13-18),没有 cause 或 detail 字段,所以任何路由也暴露不了更深的原因。于是本轮为了可诊断性而加的这条诊断,恰好在运维人员最需要排查的那条路径上一点原因都不带。Skills 侧没有这个问题:prepareSkillsRevision(:533-541)结构上完全对称但不做包装,这也是同一个探针的 Skills arm 能打出真实原因的原因。
证据:
Real WorkspaceRuntimeCoordinator driven through the boot call form ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }),
two arms, one run, intact PR code:
PROBE MCP: "injectedReason":"ACP child exited during MCP preparation","causeDepth":2,
  "errMessage":"Workspace runtime failed to initialize","causeMessage":"Workspace runtime failed to initialize",
  "causeCauseMessage":"ACP child exited during MCP preparation",
  "operatorVisibleLine":"workspace MCP discovery after preheat failed: Workspace runtime failed to initialize (Workspace runtime failed to initialize)",
  "capabilities":{"mcp":{"state":"error","error":{"code":"mcp_prepare_failed","message":"Workspace runtime failed to initialize"}},"skills":{"state":"ready"}}
PROBE SKILLS: "causeDepth":1,"causeMessage":"ACP child exited during Skills preparation",
  "operatorVisibleLine":"...failed: Workspace runtime failed to initialize (ACP child exited during Skills preparation)"
FLIP (candidate fix = delete the wrap at coordinator:587), MCP arm re-run:
  "causeDepth":1,"causeMessage":"ACP child exited during MCP preparation",
  "operatorVisibleLine":"...failed: Workspace runtime failed to initialize (ACP child exited during MCP preparation)"
  SKILLS arm byte-identical before/after the flip - the flip is MCP-specific, so it isolates the line.
请解包到最内层的 cause——这是能留在本 PR 自己改动行内的修法:
            let causeError: unknown = err;
            while (causeError instanceof Error && causeError.cause instanceof Error) {
              causeError = causeError.cause;
            }
            const cause =
              causeError instanceof Error && causeError !== err
                ? causeError.message
: undefined;注意这只修好日志行。capabilities.mcp.error.message 是由 coordinator 内部的 recordMcpError 写入的,要连它一起修就得动 workspace-runtime-coordinator.ts:587(或在 recordMcpError 里解包)——那是本 PR diff 之外的既有代码,更适合作为后续工作,而不是把本次改动扩大。
修复不得违反这一点:workspace-runtime-coordinator.ts:533-541 的 Skills 对应处不做包装,所以两侧的不对称恰好差一行(:587)——如果改成完全不读 cause,就会连 Skills arm 目前正确的真实原因也一起丢掉(同一个探针已证明它现在是对的)。
请用一个「去掉修复就会变红」的测试把它钉住:一个启动 discovery 失败的用例,其 ensure mock 以双层包装的错误 reject(new WorkspaceRuntimeInitializationError(new WorkspaceRuntimeInitializationError(new Error('real reason')))),并断言 waitForDaemonLog(logBaseDir, '...failed: Workspace runtime failed to initialize (real reason)')——去掉解包循环它必须变红,因为今天打出的是 (Workspace runtime failed to initialize)。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| err instanceof Error && err.cause instanceof Error | ||
| ? err.cause.message | ||
| : undefined; | ||
| daemonLog.warn( |
There was a problem hiding this comment.
[Suggestion] This .catch classifies every rejection as a failure at warn level, including the WorkspaceDrainingError an orderly shutdown produces. The shuttingDown || runtimeStartupError !== undefined guard above is sampled once, synchronously, before ensure() starts — and ensure() then runs for up to a minute — so a terminal state reached inside that window is reported as a discovery failure instead of a cancellation.
An operator starts qwen serve and Ctrl-Cs or SIGTERMs it a second or two later (wrong directory, restarting with different flags). handle.close() sets shuttingDown = true (:9153) and immediately runs beginRuntimeCoordinatorDrains → coordinator.beginDrain() (:9157-9169); the in-flight ensure() then hits assertAcceptingWork() after its keep-alive preheat (workspace-runtime-coordinator.ts:222) and throws WorkspaceDrainingError, whose message is Workspace "/path" is being removed (packages/acp-bridge/src/bridgeErrors.ts:623-632). The daemon emits a WARN — which tee() also writes to stderr — saying a workspace is being removed during a plain shutdown, while exiting 0. The routes layer classifies the identical error as an expected retryable 503 workspace_draining with Retry-After: 5 (server/error-response.ts:472-480), and this same function logs the identical condition at info as skipped: shutting down a few hundred milliseconds earlier. So the severity of the line is decided by where a millisecond race lands, and anyone alerting on daemon-log warnings gets a false alarm on routine restarts during boot. A second ordering reaches the same handler: a runtime startup failure while discovery is in flight, where startup.preheat.status is already 'succeeded' so the rewrite at :8584-8588 does not apply, and the teardown surfaces as Workspace runtime stopped during Skills/MCP preparation.
Witness:
Unmodified PR code, controlled second preheat:
PROBE observed preheatCalls=2
  logLines=["...[WARN] [DAEMON] ... workspace MCP discovery after preheat failed: Workspace \"/tmp/qws-probe-r44-ClYQiP\" is being removed"]
  stderrWarnLines=["...[WARN] [DAEMON] workspace MCP discovery after preheat failed: Workspace \"/tmp/qws-probe-r44-ClYQiP\" is being removed"]
With the catch re-checking the terminal flags:
  logLines=["...[INFO] [DAEMON] ... workspace MCP discovery after preheat cancelled: shutting down"]
Import check: grep for 'WorkspaceDrainingError|bridgeErrors' in run-qwen-serve.ts -> no matches.
Re-check the in-scope terminal flags inside the .catch before choosing the level and the wording, and classify by flag rather than by error type:
          .catch((err) => {
            if (shuttingDown || runtimeStartupError !== undefined) {
              daemonLog.info(
                'workspace MCP discovery after preheat cancelled: daemon is not running',
              );
              return;
            }
            const message = err instanceof Error ? err.message : String(err);
            // ...unchanged warn below
The fix must not violate this: run-qwen-serve.ts has no value import of WorkspaceDrainingError or bridgeErrors (verified by grep) — its only bridge import is import type { AcpSessionBridge } from '@qwen-code/acp-bridge/bridgeTypes' at :63, and ./acp-session-bridge.js is a whole-surface re-export shim of @qwen-code/acp-bridge (acp-session-bridge.ts:7-37). An instanceof classification would therefore put a runtime import into the pre-listen static closure this diff explicitly guards at :83-84, so the fix has to re-check the flags already in scope. The existing test does not leak an unhandled rejection when boot MCP discovery fails also asserts the WARN line for a genuine WorkspaceRuntimeInitializationError, so a real initialization failure must still warn.
Please pin this with a test that fails without the fix: stub WorkspaceRuntimeCoordinator.prototype.ensure to return a deferred, resolve preheat, await handle.close(), then reject the deferred with a draining error, and assert via waitForDaemonLog that the log contains the info cancelled line and never contains workspace MCP discovery after preheat failed — removing the re-check must turn it red, and today nothing covers shutdown after preheat resolved (does not schedule workspace MCP discovery when shutting down during preheat closes the handle before resolving preheat, so the catch never runs).
中文说明
这个 .catch 把每一次 rejection 都归类为 warn 级别的失败,包括一次正常关闭所产生的 WorkspaceDrainingError。上方的 shuttingDown || runtimeStartupError !== undefined 守卫只在 ensure() 开始之前同步采样一次——而 ensure() 接下来会跑长达一分钟——所以在这个窗口内才到达的终态,会被报告成 discovery 失败而不是取消。
运维人员启动 qwen serve,一两秒后 Ctrl-C 或 SIGTERM(目录选错、换参数重启)。handle.close() 把 shuttingDown 置为 true(:9153)并立即运行 beginRuntimeCoordinatorDrains → coordinator.beginDrain()(:9157-9169);此时在飞的 ensure() 在其 keep-alive preheat 之后撞上 assertAcceptingWork()(workspace-runtime-coordinator.ts:222)并抛出 WorkspaceDrainingError,其消息是 Workspace "/path" is being removed(packages/acp-bridge/src/bridgeErrors.ts:623-632)。于是守护进程在一次普通关闭中输出一条 WARN——tee() 同时也会写到 stderr——说某个 workspace 正在被移除,而进程以 0 退出。路由层把完全相同的错误归类为预期内的可重试 503 workspace_draining,带 Retry-After: 5(server/error-response.ts:472-480);而同一个函数在几百毫秒之前还把同样的情形以 info 级别记为 skipped: shutting down。于是这一行的严重级别由一个毫秒级竞态落在哪里决定,任何对守护进程日志 warning 告警的人,都会在启动期的常规重启上收到一次误报。还有第二种时序会到达同一个处理器:discovery 在飞时发生运行时启动失败,此时 startup.preheat.status 已是 'succeeded',所以 :8584-8588 的改写不生效,拆除过程以 Workspace runtime stopped during Skills/MCP preparation 的形式浮出来。
证据:
Unmodified PR code, controlled second preheat:
PROBE observed preheatCalls=2
  logLines=["...[WARN] [DAEMON] ... workspace MCP discovery after preheat failed: Workspace \"/tmp/qws-probe-r44-ClYQiP\" is being removed"]
  stderrWarnLines=["...[WARN] [DAEMON] workspace MCP discovery after preheat failed: Workspace \"/tmp/qws-probe-r44-ClYQiP\" is being removed"]
With the catch re-checking the terminal flags:
  logLines=["...[INFO] [DAEMON] ... workspace MCP discovery after preheat cancelled: shutting down"]
Import check: grep for 'WorkspaceDrainingError|bridgeErrors' in run-qwen-serve.ts -> no matches.
请在 .catch 内重新检查作用域内的终态标志,再决定级别与措辞,并且按标志而不是按错误类型分类:
          .catch((err) => {
            if (shuttingDown || runtimeStartupError !== undefined) {
              daemonLog.info(
                'workspace MCP discovery after preheat cancelled: daemon is not running',
              );
              return;
            }
            const message = err instanceof Error ? err.message : String(err);
// ...unchanged warn below修复不得违反这一点:run-qwen-serve.ts 没有对 WorkspaceDrainingError 或 bridgeErrors 的值导入(已用 grep 验证)——它唯一的 bridge 导入是 :63 的 import type { AcpSessionBridge } from '@qwen-code/acp-bridge/bridgeTypes',而 ./acp-session-bridge.js 是 @qwen-code/acp-bridge 的全面重导出 shim(acp-session-bridge.ts:7-37)。因此用 instanceof 分类会把一个运行时导入放进本 diff 在 :83-84 明确守护的 pre-listen 静态闭包,所以修法只能重新检查已在作用域内的标志。另外现有测试 does not leak an unhandled rejection when boot MCP discovery fails 会对真正的 WorkspaceRuntimeInitializationError 断言那条 WARN 行,所以真实的初始化失败必须仍然走 warn。
请用一个「去掉修复就会变红」的测试把它钉住:把 WorkspaceRuntimeCoordinator.prototype.ensure 桩成返回一个 deferred,resolve preheat,await handle.close(),然后用一个 draining 错误 reject 该 deferred,并用 waitForDaemonLog 断言日志包含 info 的 cancelled 行、且从未包含 workspace MCP discovery after preheat failed——去掉这个重新检查它必须变红。今天没有任何测试覆盖 preheat resolve 之后的关闭(does not schedule workspace MCP discovery when shutting down during preheat 在 resolve preheat 之前就关了 handle,所以那个 catch 根本不会跑)。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| ? err.cause.message | ||
| : undefined; | ||
| daemonLog.warn( | ||
| `workspace MCP discovery after preheat failed: ${message}` + |
There was a problem hiding this comment.
[Suggestion] This hook is named and logged exclusively as "workspace MCP discovery", but coordinator.ensure() unconditionally drives Skills preparation as well — so a Skills-side rejection is attributed to MCP in the operator-visible daemon log. EnsureOptions offers no MCP-only mode (workspace-runtime-coordinator.ts:26-37), and ensure() always builds skillsPrep beside mcpPrep (:244, :248).
prepareSkillsRevision's own await withTimeout(this.bridge.preheat({ keepAliveMs }), ...) at :535-539 sits outside the inner try that only opens at :545, so an ACP child death between this hook's preheat and Skills prep escapes instead of being absorbed by recordSkillsError; ensure's :256-261 rethrows it as WorkspaceRuntimeInitializationError into this MCP-worded .catch. The daemon log then reads workspace MCP discovery after preheat failed: Workspace runtime failed to initialize (ACP child exited during Skills preparation) on a boot where MCP measured ready — sending triage to .qwen/settings.json mcpServers and MCP server binaries when the failing component is the Skills runtime. Both sides' out-of-try preheat is structurally symmetric, so a death during preparation lands on the Skills side about as often as the MCP side. This became operator-visible in this round: the same line went through debugLogger.debug before, which writes nothing in a qwen serve daemon.
Witness:
STAGE 1 - real WorkspaceRuntimeCoordinator, two arms, identical except which side's out-of-try preheat rejects:
  arm=skills -> {"rejected":true,"errorName":"WorkspaceRuntimeInitializationError",
    "causeMessage":"ACP child exited during Skills preparation",
    "capabilities":{"mcp":{"state":"ready"},"skills":{"state":"error","error":{"code":"skills_prepare_failed"}}},
    "preheatCallers":["other","prepareSkillsRevision"]}
  arm=mcp    -> same wrapper, capabilities inverted (mcp:error/mcp_prepare_failed, skills:ready)
STAGE 2 - real boot hook + real daemonLog, fed the error stage 1 produced:
  PROBE-DAEMON-LOG-LINE: ["...[WARN] [DAEMON] ... workspace MCP discovery after preheat failed:
    Workspace runtime failed to initialize (ACP child exited during Skills preparation)"]
  -> MCP measured `ready`, Skills measured `error/skills_prepare_failed`, log line says MCP failed.
Age A/B, same test input both arms:
  BASE (557f1b13d5, debugLogger.debug): Error: daemon log did not contain: workspace MCP discovery after preheat failed
  PR   (HEAD, daemonLog.warn):          [WARN] [DAEMON] ... workspace MCP discovery after preheat failed: ... (1 passed)
Name the step rather than the subsystem in the failure line, and report both capability states on the success path so each side is attributable — e.g. workspace runtime preparation after preheat failed: ${message}, or keep the MCP wording and append the measured split from the resolved status (mcp=${status.capabilities.mcp.state} skills=${status.capabilities.skills.state}). Renaming the helper itself is optional and cosmetic; the log line is the part an operator reads.
The fix must not violate this: ensure() offers no MCP-only mode — EnsureOptions is { timeoutMs?; keepAliveMs?; skipKeepAlivePreheat? } (workspace-runtime-coordinator.ts:26-37) and both skillsPrep and mcpPrep are always built (:244, :248) — so the fix must not claim boot discovery is MCP-scoped by passing an option that does not exist. Note also that the PR description already states "Boot ensure() also runs prepareSkills() — not MCP-only", so the description is not the gap here; the log wording is.
Please pin this with a test that fails without the fix: the two tests that pin the exact string must be updated with the new wording, and the new behaviour needs a case where the Skills side is the failing one and the assertion is that the emitted line does not name MCP — that assertion goes red against today's message. The existing does not leak an unhandled rejection when boot MCP discovery fails needle workspace MCP discovery after preheat failed: Workspace runtime failed to initialize (cause detail) is the string that has to change.
中文说明
这个 hook 的命名与日志全部只提 "workspace MCP discovery",但 coordinator.ensure() 会无条件地同时驱动 Skills 准备——于是 Skills 侧的 rejection 会在运维人员可见的守护进程日志里被归因到 MCP。EnsureOptions 没有提供仅 MCP 的模式(workspace-runtime-coordinator.ts:26-37),而 ensure() 总是在 mcpPrep 旁边构造 skillsPrep(:244、:248)。
prepareSkillsRevision 自己的 await withTimeout(this.bridge.preheat({ keepAliveMs }), ...)(:535-539)位于内层 try 之外(该 try 到 :545 才开始),所以 ACP 子进程在本 hook 的 preheat 与 Skills 准备之间死掉时,错误会逃出而不被 recordSkillsError 吸收;ensure 的 :256-261 会把它包成 WorkspaceRuntimeInitializationError 重新抛进这个措辞为 MCP 的 .catch。于是守护进程日志会在一次 MCP 实测为 ready 的启动上打出 workspace MCP discovery after preheat failed: Workspace runtime failed to initialize (ACP child exited during Skills preparation)——把排查引向 .qwen/settings.json 的 mcpServers 和 MCP server 二进制,而真正失败的是 Skills runtime。两侧的 out-of-try preheat 在结构上对称,所以准备期间的子进程死亡落在 Skills 侧的概率与落在 MCP 侧差不多。这一点在本轮才变成运维可见:同一行之前走的是 debugLogger.debug,而它在 qwen serve 守护进程里什么都不写。
证据:
STAGE 1 - real WorkspaceRuntimeCoordinator, two arms, identical except which side's out-of-try preheat rejects:
  arm=skills -> {"rejected":true,"errorName":"WorkspaceRuntimeInitializationError",
    "causeMessage":"ACP child exited during Skills preparation",
    "capabilities":{"mcp":{"state":"ready"},"skills":{"state":"error","error":{"code":"skills_prepare_failed"}}},
    "preheatCallers":["other","prepareSkillsRevision"]}
  arm=mcp    -> same wrapper, capabilities inverted (mcp:error/mcp_prepare_failed, skills:ready)
STAGE 2 - real boot hook + real daemonLog, fed the error stage 1 produced:
  PROBE-DAEMON-LOG-LINE: ["...[WARN] [DAEMON] ... workspace MCP discovery after preheat failed:
    Workspace runtime failed to initialize (ACP child exited during Skills preparation)"]
  -> MCP measured `ready`, Skills measured `error/skills_prepare_failed`, log line says MCP failed.
Age A/B, same test input both arms:
  BASE (557f1b13d5, debugLogger.debug): Error: daemon log did not contain: workspace MCP discovery after preheat failed
  PR   (HEAD, daemonLog.warn):          [WARN] [DAEMON] ... workspace MCP discovery after preheat failed: ... (1 passed)
请在失败行里命名这个步骤而不是子系统,并在成功路径上上报两侧的 capability 状态,让每一侧都可归因——例如 workspace runtime preparation after preheat failed: ${message},或保留 MCP 措辞并附上从 resolved status 里测得的拆分(mcp=${status.capabilities.mcp.state} skills=${status.capabilities.skills.state})。重命名辅助函数本身是可选的表面工作;运维人员读的是日志行。
修复不得违反这一点:ensure() 没有仅 MCP 的模式——EnsureOptions 就是 { timeoutMs?; keepAliveMs?; skipKeepAlivePreheat? }(workspace-runtime-coordinator.ts:26-37),而 skillsPrep 与 mcpPrep 总是一起构造(:244、:248)——所以不能通过传一个不存在的选项来声称启动期 discovery 是 MCP 范围的。另外请注意 PR 描述已经写明「Boot ensure() also runs prepareSkills() — not MCP-only」,所以这里的缺口不在描述,而在日志措辞。
请用一个「去掉修复就会变红」的测试把它钉住:钉住精确字符串的那两个测试要随新措辞一起更新,而新行为需要一个失败方是 Skills 侧的用例,其断言是打出的行不点名 MCP——该断言在今天的消息下会变红。现有 does not leak an unhandled rejection when boot MCP discovery fails 钉住的 workspace MCP discovery after preheat failed: Workspace runtime failed to initialize (cause detail) 就是必须改的那个字符串。
— qwen3.8-max via Qwen Code /review (v0.23.0)
Annotate the channel-worker snapshot mock for typecheck, split shutdown
vs startup-failure skip guards, unwrap ensure failure causes for daemon
logs, skip warn on WorkspaceDrainingError, rename logs to workspace
runtime ensure, and add tests for cause-less failures and the
runtimeStartupError guard arm.
|
Addressed round-4 on d8e5428: Critical ChannelWorkerSnapshot mock typing; cause-less log test; runtimeStartupError guard test; deepestErrorMessage unwrap; skip warn on WorkspaceDrainingError; rename logs to workspace runtime ensure. Risk & Scope updated (tee to stderr). tsc/build green; startup observability 18 passed. |
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
1 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- round-5 reverse-audit finding at packages/cli/src/serve/run-qwen-serve.ts:8980 (the discarded ensure() outcome) — already reported (round 4 deferral paragraph, review 5132553690)
Not reviewed: build-and-test efficacy probe — the automated mutation / hunk-necessity harness died inside the repo's own vitest prerequisite guard, so its control produced no verdict (harnessValidated: null, 1 mutant and 6 hunk probes skippedForBaseline, 0 run); the ground was covered by hand instead — three verifiers executed real mutations with observed flips.
Not explored to full depth (tool budget reached): "agent reverse-audit (round 2)": did not read workspace-trust-reconciler.ts to confirm the post-revocation replacement generation materializes runtime.trusted === false — inferred from run-qw…; "agent reverse-audit (round 2)": ran 8 of the 9 new tests ( -t 'MCP discovery' ); 'logs cause-less boot runtime ensure failures without an undefined suffix' was not executed; "agent reverse-audit (round 2)": did not verify whether the child-side createWorkspaceMcpDiscoveryConfig (acpAgent.ts:3901-3953) can start any MCP transport before core's NOT_STARTED refusal,….
Not reviewed: reverse audit — stopped before round 8 by the review time budget.
Test Plan (not a blocker): 18 passed — this review observed 28871 passed.
Convergence: round 5 posted 5 inline comment(s), 3 of them reported for the first time; the previous round posted 7 (7 new). Findings keep coming back to the same files: packages/cli/src/serve/run-qwen-serve.ts (findings in rounds 2, 3, 4; 3 more now). A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. (Observation only — nothing was withheld from this review because of this observation.)
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 1 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未审查(原文为英文):build-and-test efficacy probe — the automated mutation / hunk-necessity harness died inside the repo's own vitest prerequisite guard, so its control produced no verdict (harnessValidated: null, 1 mutant and 6 hunk probes skippedForBaseline, 0 run); the ground was covered by hand instead — three verifiers executed real mutations with observed flips.
未探索到全部深度(达到工具调用预算):"agent reverse-audit (round 2)":did not read workspace-trust-reconciler.ts to confirm the post-revocation replacement generation materializes runtime.trusted === false — inferred from run-qw…;"agent reverse-audit (round 2)":ran 8 of the 9 new tests ( -t 'MCP discovery' ); 'logs cause-less boot runtime ensure failures without an undefined suffix' was not executed;"agent reverse-audit (round 2)":did not verify whether the child-side createWorkspaceMcpDiscoveryConfig (acpAgent.ts:3901-3953) can start any MCP transport before core's NOT_STARTED refusal,…。
未审查:反向审计——评审时间预算不足,未能开始第 8 轮。
Test Plan(非阻断):18 passed — this review observed 28871 passed。
收敛情况:第 5 轮发布了 5 条行内评论,其中 3 条是首次提出;上一轮发布了 7 条(其中 7 条首次提出)。发现反复回到同一批文件:packages/cli/src/serve/run-qwen-serve.ts(第 2、3、4 轮已出过发现,本轮又有 3 条)。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。(仅为观察——本轮评审未因此扣留任何内容。)
— qwen3.8-max via Qwen Code /review (v0.23.0)
| resolveWorkspaceInputs, | ||
| } from './workspace-inputs.js'; | ||
| import type { AcpSessionBridge } from '@qwen-code/acp-bridge/bridgeTypes'; | ||
| import { WorkspaceDrainingError } from '@qwen-code/acp-bridge/bridgeErrors'; |
There was a problem hiding this comment.
[Critical] The static value import of @qwen-code/acp-bridge/bridgeErrors added here puts that specifier into the runQwenServe pre-listen static source graph, which this repository's own import-boundary guard forbids, so npm test --workspace="packages/cli" is red at this commit and green on the merge base. fast-path.test.ts:511 already lists that specifier in forbiddenExternalImports — the entry predates this PR, whose only edit to that array is adding '@qwen-code/qwen-code-core' at :512 — and the guard classifies this import as a runtime value because it is used with instanceof at :8983. CI for packages/cli therefore fails on this commit, and every workspace build downstream of it is blocked. Beyond the red gate this is exactly what the guard exists to prevent: an ACP runtime module eagerly loaded into the serve pre-listen closure that fast-path.ts reaches only through await import('./run-qwen-serve.js'), precisely so the daemon can listen() before core loads. The rest of this diff honours that rule deliberately — ENSURE_KEEP_ALIVE_MS is duplicated at :269-271 with the comment "Defined here so the serve pre-listen graph does not statically import that module". Round 4's R4-4 named this consequence before it happened, in its fix constraint: an instanceof classification "would therefore put a runtime import into the pre-listen static closure this diff explicitly guards at :83-84, so the fix has to re-check the flags already in scope."
Witness:
npm test --workspace="packages/cli" -> exit 1
  failingFiles: ["src/config/settings.test.ts", "src/serve/fast-path.test.ts"]
  14 failed | 28871 passed | 72 skipped   (1013 of 1015 files green)

src/serve/fast-path.test.ts > CLI entry import boundary >
  keeps the runQwenServe static source graph free of ACP runtime modules
  AssertionError: Unexpected ACP runtime imports:
    @qwen-code/acp-bridge/bridgeErrors: expected [ Array(1) ] to deeply equal []
      at fast-path.test.ts:520
  isolated rerun: 1 failed | 91 passed

test-delta against the built merge base 7567824d4 (base rerun: exit 1, 13 failed | 28857 passed):
  netNew: ["src/serve/fast-path.test.ts"]   <- the PR's own, by measurement
  shared: ["src/config/settings.test.ts"]   <- fails on base too: pre-existing, not filed

attribution: git show 5799ecf8916c:packages/cli/src/serve/run-qwen-serve.ts | grep -c bridgeErrors -> 0
             same file at HEAD d8e542891b                                          -> 1
build: all 17 workspaces exitCode 0 (packages/cli 55s) - the break is the test gate, not the compiler
The cheapest fix is the one R4-4 already asked for — re-check the terminal flags in scope inside the .catch, which needs no error class at all and closes R4-4 in the same edit. If a drain check is still wanted for the workspace-removal case where neither flag is set, discriminate structurally on the class's own discriminants (readonly code = 'workspace_draining' / this.name, packages/acp-bridge/src/bridgeErrors.ts:623-630) — this file already has that cast shape at :3486 — or thread the class through the lazy loadServeRuntimeModules() bag at :2308-2309 beside getWorkspaceRuntimeCoordinatorIfSupported:
          .catch((err) => {
            if (shuttingDown || runtimeStartupError !== undefined) {
              daemonLog.info(
                'workspace runtime ensure after preheat cancelled: daemon is not running',
              );
              return;
            }
            daemonLog.warn(
              `workspace runtime ensure after preheat failed: ${deepestErrorMessage(err)}`,
            );
          });
The fix must not violate this: fast-path.test.ts:506-513 forbids '@qwen-code/acp-bridge', /bridge, /spawnChannel, /bridgeClient, /bridgeErrors and '@qwen-code/qwen-code-core' as static value imports in the graph rooted at src/serve/run-qwen-serve.ts, and :498-505 also bans the local file src/serve/acp-session-bridge.ts — so re-importing the class through the compatibility shim every other CLI call site uses is not an available escape hatch.
Please pin this with a check that fails without the fix: packages/cli/src/serve/fast-path.test.ts › keeps the runQwenServe static source graph free of ACP runtime modules must go from exit 1 to exit 0 — that is the gate that is red today, so it is already proven live. If the replacement is a structural predicate rather than the flag re-check, the draining branch also needs the test R4-4 asked for, because WorkspaceDrainingError appears nowhere in run-qwen-serve.test.ts today and a mistyped code string would pass every existing test.
中文说明
这里新增的 @qwen-code/acp-bridge/bridgeErrors 静态值导入,把该 specifier 放进了 runQwenServe 的 pre-listen 静态源码图,而仓库自己的导入边界守卫禁止它——因此在本次 commit 上 npm test --workspace="packages/cli" 是红的,而在 merge base 上是绿的。fast-path.test.ts:511 早已把该 specifier 列入 forbiddenExternalImports(这一项早于本 PR;本 PR 对该数组唯一的改动是在 :512 加入 '@qwen-code/qwen-code-core'),而守卫把本导入判定为运行时值导入,因为它在 :8983 被用于 instanceof。于是本 commit 上 packages/cli 的 CI 失败,其下游每一个 workspace build 都被阻断。除关卡变红之外,这正是该守卫要防止的事情:一个 ACP 运行时模块被提前加载进 serve 的 pre-listen 闭包——fast-path.ts 只通过 await import('./run-qwen-serve.js') 到达本文件,目的就是让守护进程能在 core 加载之前 listen()。本 diff 的其余部分是刻意遵守这条规则的——ENSURE_KEEP_ALIVE_MS 在 :269-271 被复制了一份,并附注释「Defined here so the serve pre-listen graph does not statically import that module」。第 4 轮的 R4-4 在其修复约束里已经预言了这个后果:用 instanceof 分类「会把一个运行时导入放进本 diff 在 :83-84 明确守护的 pre-listen 静态闭包,所以修法只能重新检查已在作用域内的标志」。
证据(原文为英文):npm test --workspace="packages/cli" 以 1 退出,failingFiles 含 src/serve/fast-path.test.ts,报 Unexpected ACP runtime imports: @qwen-code/acp-bridge/bridgeErrors(fast-path.test.ts:520);单独重跑 1 failed / 91 passed。与已构建的 merge base 7567824d4 对比的 test-delta 判定 fast-path.test.ts 为 netNew(仅 PR 侧失败),而 src/config/settings.test.ts 为 shared(base 上同样失败,属既有问题,不作为发现提交)。归因精确:git show 5799ecf8916c 时该文件的 bridgeErrors 计数为 0,HEAD d8e542891b 为 1。构建侧 17 个 workspace 全部 exitCode 0——变红的是测试关卡,不是编译器。
最省事的修法就是 R4-4 已经要求的那个——在 .catch 内重新检查作用域内的终态标志,完全不需要错误类,并且同一次改动就关闭 R4-4。如果仍希望为「两个标志都未置位的 workspace 移除」场景保留 drain 判断,可以按该类自己的判别字段做结构化判断(readonly code = 'workspace_draining' / this.name,见 packages/acp-bridge/src/bridgeErrors.ts:623-630;本文件 :3486 已有同样的 cast 写法),或把该类经由 :2308-2309 的惰性 loadServeRuntimeModules() 传入,与 getWorkspaceRuntimeCoordinatorIfSupported 并列。
修复不得违反这一点:fast-path.test.ts:506-513 在以 src/serve/run-qwen-serve.ts 为根的图中禁止 '@qwen-code/acp-bridge'、/bridge、/spawnChannel、/bridgeClient、/bridgeErrors 与 '@qwen-code/qwen-code-core' 作为静态值导入,:498-505 还禁止本地文件 src/serve/acp-session-bridge.ts——因此不能像其他 CLI 调用点那样经由该兼容 shim 重新导入这个类。
请用一个「去掉修复就会失败」的检查把它钉住:packages/cli/src/serve/fast-path.test.ts 的 keeps the runQwenServe static source graph free of ACP runtime modules 必须从 exit 1 变成 exit 0——这就是今天变红的那道关卡,因此它已被证明是有效的。如果改用结构化判断而不是标志重检,draining 分支还需要 R4-4 要求的那个测试,因为今天 run-qwen-serve.test.ts 里完全没有出现 WorkspaceDrainingError,一个写错的 code 字符串会通过所有现有测试。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| void coordinator | ||
| .ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }) | ||
| .catch((err) => { | ||
| if (err instanceof WorkspaceDrainingError) { |
There was a problem hiding this comment.
[Suggestion] R4-4: still stands. Round 4 asked for this .catch to classify by the terminal flags already in scope; this round classified by error type instead, which closes one of the two orderings R4-4 named and leaves the rest open — and the type check is what required the forbidden import filed separately as a Critical. Three things survive. First, the draining branch returns without logging anything at all, so the one outcome that cancels an already-started boot discovery leaves zero trace in the daemon log: not skipped, not failed, not started, which an operator grepping for workspace runtime ensure after preheat cannot distinguish from the hook never having run, while every other branch of this function logs. Second, a routine Ctrl-C or SIGTERM a second or two after qwen serve starts still emits a warn-level failure, because assertAcceptingWork throws a bare WorkspaceDrainingError only for disposed || draining, and the two teardown shapes a shutdown actually produces are not that class — the coordinator's final liveness check (:263-268) throws WorkspaceRuntimeInitializationError('Workspace runtime stopped during Skills/MCP preparation') since prepareMcpRevision's poll loop (:604-620) records 'stale' and returns without throwing, and the keep-alive preheat's own catch (:218) wraps a bridge-shutdown rejection. Neither matches this guard, so the daemon WARNs — teed to stderr — while exiting 0, for the same condition this function logged at INFO as skipped: shutting down a few hundred milliseconds earlier; the severity of the line is decided by where a millisecond race lands. Third, runtimeStartupError is sampled once synchronously at :8955 before ensure() starts, while startBridgePreheat (:9040) runs before await completeRuntimeStartup (:9042), which awaits manager.startInitial (:8936), and the flag is only assigned later in failRuntimeStartup (:8593) — so whenever the channel worker outlasts the ACP warm-up, which is the ordinary case since the worker spawns a process, the guard passes and ensure() does real work (a second keep-alive preheat plus initializeWorkspaceMcp) against a runtime that is about to be torn down, and the teardown then rejects it into the WARN path beside the real qwen serve: runtime startup failed line. Nothing pins the branch either: WorkspaceDrainingError appears nowhere in run-qwen-serve.test.ts, so deleting these three lines leaves the suite green.
One clause rides with this fix, measured on the same probes. Whichever way the classification is fixed, the line has to be emitted before daemonLog.close() or it will not reach the log file. In the channel-worker startup-failure path that is deterministic rather than a narrow race (8 of 8 runs): failRuntimeStartup closes the server (:8605, armed by :8934), the server.on('close') listener in serve-app-lifecycle.ts:81-85 drains the host, and the drain ends with daemon stopped (:9319) plus await daemonLog.close() (:9325) before the hook runs — so an operator diagnosing why boot discovery did not run finds the log ending at daemon stopped with no skip reason of any kind.
Witness:
all arms on unmodified PR code in a scratch tree; the FIXED arm is the flag re-check applied there

(a) draining leaves zero trace
  PROBE-A1 {"ensureCalls":1,"ensureLines":[],"logLineCount":6}   (daemon NOT shutting down, log live)
  PROBE-A2 {"ensureCalls":1,"ensureLines":[],"logGrewDuringClose":true,"logGrewAfterClose":false}
  FIXED  -> ensureLines=["...[INFO] [DAEMON] ... ensure after preheat cancelled: Workspace \"/tmp/...\" is being removed"]

(b) routine shutdown still WARNs
  PROBE-B  stderrWarnLines=["...[WARN] [DAEMON] workspace runtime ensure after preheat failed:
                            Workspace runtime stopped during Skills/MCP preparation"]
  FIXED  -> stderrWarnLines=["...[INFO] [DAEMON] ... cancelled: Workspace runtime stopped during Skills/MCP preparation"]

(c) the flag is sampled before the failure it guards against
  PROBE-C  {"ensureCalls":1,"ensureFiredBeforeWorkerFailure":true,
            "ensureLinesOnStderr":["...[WARN] [DAEMON] ... failed: Workspace runtime stopped during Skills/MCP preparation"],
            "startupFailedLine":["qwen serve: runtime startup failed: worker failed after preheat"]}
  FIXED  -> [INFO] ... cancelled: ...   (ensureCalls:1 in BOTH arms - the fix reclassifies, it does not stop the wasted work)

(d) grep 'WorkspaceDrainingError|beginReplacement|WorkspaceGenerationClosedError' run-qwen-serve.test.ts -> 0 matches

post-close clause: PROBE-F hook-entered shuttingDown=true branch=shutting-down, 8/8 runs; the daemon log file read
  immediately after, after 400ms and after handle.close() was byte-identical, last line "... [INFO] [DAEMON] ... daemon stopped"

constraint held under the fix: the two pinned genuine-failure WARNs ('cause detail', 'Workspace runtime is still starting')
  still fire, 10/10 tests passing
Classify by flag rather than by type, as R4-4 prescribed — this also removes the need for the bridgeErrors value import, so it retires the Critical in the same edit:
          .catch((err) => {
            if (shuttingDown || runtimeStartupError !== undefined) {
              daemonLog.info(
                'workspace runtime ensure after preheat cancelled: daemon is not running',
              );
              return;
            }
            daemonLog.warn(
              `workspace runtime ensure after preheat failed: ${deepestErrorMessage(err)}`,
            );
          });
Keep a drain check only as a second arm for the workspace-removal case where neither flag is set, reached without a static value import; and settle the boot ensure() inside the close drain (track the promise and await it before daemon stopped) so the line is written while the logger still accepts records.
The fix must not violate this: run-qwen-serve.test.ts:16668 pins 'workspace runtime ensure after preheat failed: cause detail' for a genuine WorkspaceRuntimeInitializationError and :16708 pins '…failed: Workspace runtime is still starting', so a real initialization failure must still warn — the flag re-check must not swallow those. And the logger's post-close refusal is itself a deliberate invariant (finalize() releases the family lease, and daemon-logger.ts:1315 returns before markDropped while tee() at :1325-1352 writes stderr unconditionally), so the fix must move the emission earlier rather than write after close.
Please pin this with a test that fails without the fix: stub WorkspaceRuntimeCoordinator.prototype.ensure to return a deferred, resolve preheat, await handle.close(), then reject the deferred, and assert via waitForDaemonLog that the log carries the INFO cancelled line and never contains workspace runtime ensure after preheat failed. Removing the flag re-check must turn it red; today nothing covers shutdown after preheat resolved, because does not schedule workspace MCP discovery when shutting down during preheat closes the handle before resolving preheat, so this .catch never runs there.
中文说明
R4-4:仍然存在。第 4 轮要求这个 .catch 按作用域内已有的终态标志分类;本轮改成按错误类型分类,这只关闭了 R4-4 指出的两种时序中的一种,其余仍然敞开——而这个类型判断正是那条被单独作为 Critical 提交的禁止导入的由来。有三点仍然存在。第一,draining 分支直接 return,完全不写日志,于是唯一会取消「已开始的启动 discovery」的那个结果在守护进程日志里毫无痕迹:既不是 skipped,也不是 failed,也不是 started;运维者 grep workspace runtime ensure after preheat 时无法把它与「hook 根本没跑」区分开,而本函数的其他每个分支都会写日志。第二,在 qwen serve 启动一两秒后正常 Ctrl-C 或 SIGTERM,仍然会输出一条 warn 级失败:assertAcceptingWork 只在 disposed || draining 时抛出裸的 WorkspaceDrainingError,而关闭实际产生的两种拆除形态都不是这个类——coordinator 最终的存活检查(:263-268)抛出 WorkspaceRuntimeInitializationError('Workspace runtime stopped during Skills/MCP preparation'),因为 prepareMcpRevision 的轮询循环(:604-620)会记录 'stale' 并不抛异常地返回;keep-alive preheat 自己的 catch(:218)则会把 bridge 关闭导致的 rejection 包装起来。两者都匹配不上这个守卫,于是守护进程在以 0 退出的同时输出 WARN(并 tee 到 stderr)——而几百毫秒之前,同一个函数还把同样的情形以 INFO 记为 skipped: shutting down;这一行的级别由一个毫秒级竞态落在哪里决定。第三,runtimeStartupError 在 :8955 处、ensure() 开始之前被同步采样一次,而 startBridgePreheat(:9040)在 await completeRuntimeStartup(:9042)之前执行,后者会 await manager.startInitial(:8936),而该标志要到更晚的 failRuntimeStartup(:8593)才被赋值——所以只要 channel worker 比 ACP 预热耗时更长(这是常态,因为 worker 要拉起进程),守卫就会放行,ensure() 会对一个即将被拆除的 runtime 做实际工作(第二次 keep-alive preheat 加上 initializeWorkspaceMcp),随后拆除让它 reject 并落进 WARN 路径,紧挨着真正的 qwen serve: runtime startup failed 行。这个分支也没有任何测试钉住:run-qwen-serve.test.ts 里完全没有出现 WorkspaceDrainingError,因此删掉这三行套件仍然全绿。
有一条条款随本修复一起处理,来自同一批探针的实测。无论分类怎么修,这一行都必须在 daemonLog.close() 之前写出,否则它到不了日志文件。在 channel worker 启动失败这条路径上,这是确定性的而不是窄竞态(8 次运行全部如此):failRuntimeStartup 关闭 server(:8605,由 :8934 置位),serve-app-lifecycle.ts:81-85 的 server.on('close') 监听器排空 host,排空以 daemon stopped(:9319)加 await daemonLog.close()(:9325)结束,全部发生在 hook 运行之前——于是运维者去查「为什么启动 discovery 没跑」时,只会看到日志停在 daemon stopped,完全没有跳过原因。
证据见上方英文代码块(探针输出为固定格式英文):(a) PROBE-A1/A2 的 ensureLines 为 [],修复后变为 [INFO] ... cancelled: Workspace "..." is being removed;(b) PROBE-B 的 stderr 上是 [WARN] ... failed: Workspace runtime stopped during Skills/MCP preparation,修复后同一代码路径变为 [INFO] ... cancelled:;(c) PROBE-C 显示 ensureFiredBeforeWorkerFailure: true 且两个 arm 的 ensureCalls 都是 1——修复只改变归类,不会阻止这次无用的工作;(d) 对测试文件的 grep 为 0 命中;关闭后条款由 PROBE-F 实测,8/8 次 shuttingDown=true、branch=shutting-down,日志文件三次读取字节一致且止于 daemon stopped。修复下约束成立:两条被钉住的真实失败 WARN(cause detail、Workspace runtime is still starting)仍然输出,10/10 测试通过。
请按 R4-4 的要求以标志而非类型分类——这同时去掉了 bridgeErrors 值导入的需要,因此在同一次改动里也解决了那条 Critical。只在「两个标志都未置位的 workspace 移除」场景下保留 drain 判断作为第二条分支,并且不引入静态值导入;同时把启动期的 ensure() 收进关闭排空流程内(跟踪该 promise 并在 daemon stopped 之前 await 它),让这行日志在 logger 仍接受记录时写出。
修复不得违反这一点:run-qwen-serve.test.ts:16668 钉住了真实 WorkspaceRuntimeInitializationError 对应的 'workspace runtime ensure after preheat failed: cause detail',:16708 钉住了 '…failed: Workspace runtime is still starting',所以真实的初始化失败必须仍然走 warn,标志重检不能把它们吞掉。另外 logger 关闭后拒写本身是刻意的不变量(finalize() 会释放 family lease;daemon-logger.ts:1315 在 markDropped 之前就返回,而 :1325-1352 的 tee() 无条件写 stderr),所以修法是把输出时机提前,而不是在关闭之后再写。
请用一个「去掉修复就会变红」的测试把它钉住:把 WorkspaceRuntimeCoordinator.prototype.ensure 桩成返回一个 deferred,resolve preheat,await handle.close(),再 reject 该 deferred,并用 waitForDaemonLog 断言日志包含 INFO 的 cancelled 行、且从未包含 workspace runtime ensure after preheat failed。去掉标志重检它必须变红;今天没有任何测试覆盖 preheat resolve 之后的关闭,因为 does not schedule workspace MCP discovery when shutting down during preheat 在 resolve preheat 之前就关了 handle,这个 .catch 在那里根本不会执行。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| await vi.waitFor(() => { | ||
| const stderr = stderrWrites.join(''); | ||
| if ( | ||
| stderr.includes('qwen serve: runtime startup failed') && |
There was a problem hiding this comment.
[Suggestion] R2-3: still stands. The rework R2-3 asked for was applied — this test now passes resolveOnListen: true and daemonLogBaseDir, and it names the runtime startup failed skip line — but it still cannot fail when the guard it was rewritten to pin is deleted. vi.waitFor retries only when the callback throws; a returned value resolves it immediately, and the first invocation is synchronous. This callback returns stderr.includes(...), a boolean, so it runs exactly once. Two things then compound. The single invocation happens after failRuntimeStartup has already written the banner, so resolvePreheat() does fire — but channelSelection, the trigger this test uses, is precisely what defeats the assertion: failRuntimeStartup sets closeServerAfterChannelWorkerStartupFailure for any channel selection (:8934), server.close() (:8605) fires the server.on('close') listener in serve-app-lifecycle.ts:81-85, which drains the host, sets shuttingDown = true (:9165), writes daemon stopped (:9319) and awaits daemonLog.close() (:9325) — all before the hook runs. So the sibling shuttingDown guard always wins (8 of 8 runs) instead of the runtimeStartupError branch, and the log writer is already closed, which means the needle this test polls for can never be written to the file. Separately, deleting the runtimeStartupError !== undefined block leaves this test green and the whole file green, and a repo-wide grep for that needle returns only three hits: the production line and this test's two poll strings. So the guard this round split into its own separately-logged branch is pinned nowhere, and the daemonLogBaseDir added to this test in the same commit is inert — waitForDaemonLog is called by the four sibling tests and by nothing here. The consequence is that a daemon can ship boot MCP discovery, meaning a second ten-minute keep-alive preheat plus initializeWorkspaceMcp, on a runtime whose startup already failed, with the whole suite green.
Witness:
vitest 3.2.7 as this repo resolves it, node_modules/vitest/dist/chunks/vi.bdSIJ99Y.js:3727-3752:
  const result = callback();
  if (result !== null && typeof result === "object" && typeof result.then === "function") { ...thenable... }
  else { onResolve(result); return true; }        // ANY non-thenable return resolves now
  } catch (error) { lastError = error; }          // only a THROW arms a retry
  if (checkCallback() === true) return;           // first call is synchronous
probe: vi.waitFor(() => { calls += 1; return false; }) -> calls=1 result=false elapsedMs=0
       void return -> calls=1 ;  throwing form -> calls=3 (retries)

PR arm, test instrumented, product source untouched:
  PROBE-E {"waitForCallbackCalls":1,"resolvePreheatCalled":true,"ensureCalls":0,"stderrHasStartupFailedBanner":true}
  PROBE-F hook-entered {"shuttingDown":true,"runtimeStartupError":"worker failed before ready"} -> branch=shutting-down  (8/8)
  daemon log read immediately after, after 400ms, and after handle.close(): byte-identical, ends at
    "...[INFO] [DAEMON] ... daemon stopped" - no 'skipped:' line ever lands

Mutation A  delete the runtimeStartupError block (run-qwen-serve.ts:8955-8960):
              target test GREEN (1 passed | 386 skipped);  whole file GREEN (387 passed)
Mutation C  delete BOTH guard blocks:
              target test RED (expected "ensure" to not be called at all, but actually been called 1 times)
              -> the test is not fully vacuous: it does pin that SOME guard blocks ensure
Base arm 5799ecf8916c (the guard was then one combined condition):
              Mutation A' drop '|| runtimeStartupError !== undefined' -> GREEN ;  Mutation C -> RED
              -> mutation-detection power is IDENTICAL in both arms, so this round failed to
                 strengthen coverage rather than removing any
A polling restructure cannot reach that branch while channelSelection is the trigger, because the channel failure closes the server and the log with it. Drive a runtime-startup failure that does not close the server — the armRuntimeStartupTimer timeout inside startRuntime, or a completeRuntimeStartup / publishLiveDiscovery failure — keep resolveOnListen: true and daemonLogBaseDir, use the throwing form so waitFor actually retries, and only then assert on the daemon log:
      await vi.waitFor(() =>
        expect(stderrWrites.join('')).toContain('qwen serve: runtime startup failed'),
      );
      resolvePreheat();
      await waitForDaemonLog(
        logBaseDir,
        'workspace runtime ensure after preheat skipped: runtime startup failed',
      );
      expect(ensureSpy).not.toHaveBeenCalled();
The fix must not violate this: failRuntimeStartup never sets shuttingDown itself — it is handle.close() (:9165), reached via server.close() (:8605), which :8934 arms only for a channelSelection startup failure. So with resolveOnListen: true and a non-channel trigger the runtimeStartupError branch at :8955 is the one that fires and the daemon-log needle is writable; with channelSelection retained it is not, at any polling shape. Note that R2-3's own round-4 recipe was insufficient for exactly this reason, and the fix as literally proposed there was measured red on pristine source.
Please pin this with a check that fails without the fix: Mutation A must go red — deleting the runtimeStartupError !== undefined block at run-qwen-serve.ts:8955-8960 has to fail the reworked test, both on waitForDaemonLog timing out with daemon log did not contain: workspace runtime ensure after preheat skipped: runtime startup failed and on expect(ensureSpy).not.toHaveBeenCalled(). It is measured green today, in this test and across the whole 387-test file.
中文说明
R2-3:仍然存在。R2-3 要求的改造已经做了——本测试现在传了 resolveOnListen: true 与 daemonLogBaseDir,也写出了 runtime startup failed 这条跳过行——但删掉它被改写来钉住的那个守卫时,它仍然不会失败。vi.waitFor 只在回调抛异常时重试;返回值会让它立即 resolve,而且第一次调用是同步的。本回调返回的是 stderr.includes(...),一个布尔值,因此它只执行一次。接着两件事叠加。这唯一一次调用发生在 failRuntimeStartup 已经写出 banner 之后,所以 resolvePreheat() 确实会触发——但本测试所用的触发条件 channelSelection 恰恰是断言失效的原因:failRuntimeStartup 对任何 channel selection 都会置位 closeServerAfterChannelWorkerStartupFailure(:8934),server.close()(:8605)触发 serve-app-lifecycle.ts:81-85 里的 server.on('close') 监听器,它会排空 host、把 shuttingDown 置为 true(:9165)、写出 daemon stopped(:9319)并 await daemonLog.close()(:9325)——全部发生在 hook 运行之前。于是同胞的 shuttingDown 守卫总是先命中(8 次运行全部如此),而不是 runtimeStartupError 分支;并且日志写入器已经关闭,这意味着本测试轮询的那条 needle 永远写不进文件。另一方面,删掉 runtimeStartupError !== undefined 这个代码块,本测试是绿的、整个文件也是绿的,而对该 needle 的全仓 grep 只有 3 处命中:生产代码那一行,加上本测试轮询用的两个字符串。所以本轮拆成独立分支、独立打日志的这个守卫在任何地方都没有被钉住,而同一次 commit 给本测试加上的 daemonLogBaseDir 是空转的——waitForDaemonLog 被四个同胞测试调用,本测试里一次都没有。后果是:守护进程可能在一个启动已经失败的 runtime 上执行启动期 MCP discovery(也就是第二次十分钟 keep-alive preheat 加上 initializeWorkspaceMcp),而整个套件全绿。
证据见上方英文代码块(vitest 源码引用与探针输出为固定格式英文):vitest 3.2.7 的 waitFor 对任何非 thenable 返回值立即 resolve,只有抛异常才会重试,且首次调用是同步的;探针 calls=1(返回 false)、calls=1(无返回值)、calls=3(抛异常形式)。PR 侧插桩实测 waitForCallbackCalls=1、resolvePreheatCalled=true、ensureCalls=0;hook 进入时 shuttingDown=true、走 shutting-down 分支(8/8);日志文件三次读取字节一致,止于 daemon stopped,从未出现 skipped: 行。变异体 A(删掉 runtimeStartupError 代码块)目标测试与整个文件均为绿;变异体 C(删掉两个守卫代码块)为红,说明该测试并非完全空转,它确实钉住了「有某个守卫会阻止 ensure」。base 侧 5799ecf8916c(当时守卫是一个合并条件)变异体 A' 为绿、C 为红,即两个 arm 的变异检出能力完全相同——所以本轮是未能加强覆盖,而不是削弱了覆盖。
只要触发条件还是 channelSelection,任何轮询结构的改造都到不了那个分支,因为 channel 失败会连同日志一起关掉 server。请改用一个不会关闭 server 的运行时启动失败——startRuntime 里的 armRuntimeStartupTimer 超时,或 completeRuntimeStartup / publishLiveDiscovery 失败——保留 resolveOnListen: true 与 daemonLogBaseDir,使用会抛异常的断言形式让 waitFor 真正重试,然后再对守护进程日志做断言(代码见上方英文部分)。
修复不得违反这一点:failRuntimeStartup 自己从不设置 shuttingDown——设置它的是 handle.close()(:9165),经由 server.close()(:8605)到达,而 :8934 只在 channelSelection 启动失败时置位。因此在 resolveOnListen: true 且使用非 channel 触发条件时,:8955 的 runtimeStartupError 分支才是命中的那个,日志 needle 也才写得进去;保留 channelSelection 则无论轮询写成什么形状都到不了。另请注意:R2-3 在第 4 轮给出的配方正因如此是不够的,而那里字面提出的修法在未改动的源码上实测为红。
请用一个「去掉修复就会变红」的检查把它钉住:变异体 A 必须变红——删掉 run-qwen-serve.ts:8955-8960 的 runtimeStartupError !== undefined 代码块,改造后的测试必须失败,既在 waitForDaemonLog 以 daemon log did not contain: workspace runtime ensure after preheat skipped: runtime startup failed 超时,也在 expect(ensureSpy).not.toHaveBeenCalled() 上失败。今天实测为绿——本测试如此,整个 387 个测试的文件也如此。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| const registry = app.locals?.['workspaceRegistry'] as | ||
| | WorkspaceRegistry | ||
| | undefined; | ||
| const runtime = registry?.primaryEntry.current?.runtime; |
There was a problem hiding this comment.
[Suggestion] This boot read of the primary runtime skips the state === 'active' gate that every other primary-runtime consumer in this codebase applies — activeRuntime (workspace-registry.ts:321-322), requirePrimaryRuntime (:323-333), server.ts:3119-3122, routes/workspace-runtime.ts:87-89, and run-qwen-serve.ts:6456-6459. A primary entry that is transitioning or blocked therefore hands ensure() the outgoing runtime whose generation guard is already closed. When a trust-policy revision is reconciled while the boot ACP preheat is in flight, workspace-trust-reconciler.ts:113/:305 calls registry.beginReplacement(entry, revision), which sets entry.state = 'transitioning' and closes entry.current.guard while leaving entry.current pointing at the old runtime (workspace-registry.ts:405-424); blockReplacement (:467-474) does the same into 'blocked'. Those are the only reachable non-active states for a primary, since beginDrain/commitDrain/completeDrain all bail on runtime.primary (:530-566). Preheat then resolves, this line returns the retired runtime, and ensure()'s first statement assertAcceptingWork() calls generationGuard?.assertOpen() before its disposed || draining check (coordinator :715-719), throwing WorkspaceGenerationClosedError('Workspace runtime generation is no longer active.'). That class extends Error, not WorkspaceDrainingError, so the .catch below does not match it and the daemon logs a warn-level workspace runtime ensure after preheat failed: Workspace runtime generation is no longer active. for an orderly internal transition — whoever is paged after MCP discovery is sent after the trust or topology change that actually happened. The replacement generation then never receives boot discovery: there are exactly two production ensure() call sites, and runtimeActivated → workspaceRuntimeRemoval.runtimeAdded (:7148-7179) restarts scheduled tasks and channel workers but performs no MCP or Skills discovery. There are two independent windows rather than one — preheat resolving inside the guard-closed → bridge.shutdown() window, which is not a microtask because disposeRuntime first runs coordinator.dispose(), workspaceVoiceCoordinator.disposeRuntime() and, when channels are configured, channelWorkerManager.removeWorkspace() plus refreshWorkspaces() (:7300-7347) before bridge.shutdown() (:7390-7394); and preheat resolving before beginReplacement, so the guard closes mid-ensure, where queueMcpWork/queueSkillsWork re-run assertAcceptingWork() (:502, :520) and ensure's outer catch (:255-262) calls this.assertAcceptingWork(error) first, re-throwing the generation error bare into the same .catch. ensure can be in flight for 60-120 s while the trust monitor polls every 1000 ms (daemon-trust-policy-monitor.ts:41) and is started inside buildRuntime (:7896), before startBridgePreheat (:9040).
Witness:
probe on unmodified PR code: real runQwenServe, real ensure(), fake bridge,
registry.beginReplacement(entry, 'probe-revision') driven while the boot preheat is pending, then preheat resolved

INTACT  PROBE-R52 {"begun":true,"stateAfterBegin":"transitioning","guardClosed":true,"currentStillRetired":true,
                   "ensureCalls":1,"ensureGotRetiredRuntime":true,
                   "ensureLines":["...[WARN] [DAEMON] ... workspace runtime ensure after preheat failed:
                                   Workspace runtime generation is no longer active."],
                   "skippedLines":[]}
FIXED   PROBE-R52 {"ensureCalls":0,"ensureGotRetiredRuntime":false,
                   "ensureLines":["...[INFO] [DAEMON] ... workspace runtime ensure after preheat skipped: no primary runtime"]}

guard identity settled empirically, not only by reading: guardClosed=true after beginReplacement and ensure throwing the
  generation error on that same runtime. The primary literal carries generationGuard: primaryGenerationGuard
  (run-qwen-serve.ts:5778, created :5079), and createEntry (workspace-registry.ts:286) / activateReplacement (:451) both
  use `guard: runtime.generationGuard ?? createWorkspaceGenerationGuard()` - the same object beginReplacement closes.
sweep: rg '\.ensure\(' over non-test packages/cli/src -> 2 production call sites, 1 gated (HTTP route), 1 ungated (this one)

declaration: the mid-replacement state was driven through registry.beginReplacement - the exact call the reconciler makes -
  not through a real edit of the trust-policy file; everything downstream is the product's own unmodified code.
Gate the lookup the way the registry's own accessors do, which keeps the non-throwing behaviour this PR wants and needs no new import:
| const runtime = registry?.primaryEntry.current?.runtime; | |
| const entry = registry?.primaryEntry; | |
| const runtime = | |
| entry?.state === 'active' ? entry.current?.runtime : undefined; |
so a non-active primary falls into the existing no primary runtime INFO skip rather than into ensure(). registry?.resolveWorkspaceCwd(undefined) is an equivalent one-liner that already encapsulates the gate.
The fix must not violate this: export type WorkspaceEntryState = | 'active' | 'draining' | 'transitioning' | 'blocked' | 'removed'; (workspace-registry.ts:56-61) — the gate must skip on every non-active state, not just 'transitioning', and the pattern to match is activeRuntime at :321-322 (entry?.state === 'active' ? entry.current?.runtime : undefined), not a current !== undefined test, which would re-admit the closed generation. Only 'transitioning' and 'blocked' are reachable for a primary, so the fix must not add handling that assumes a 'draining' or 'removed' primary is possible. And ./workspace-registry.js is imported type-only in this file (:152-157), so the alternative of catching WorkspaceGenerationClosedError in the .catch must not add a static value import.
Please pin this with a test that fails without the fix: a new case beside logs when boot MCP discovery skips because primary runtime is gone, reusing the createServeApp spy that test already installs to capture the registry — hold preheat pending, set workspaceRegistry!.primaryEntry.state = 'transitioning' (restoring it in a finally, as that test restores current), resolve preheat, then assert waitForDaemonLog(logBaseDir, 'workspace runtime ensure after preheat skipped:') succeeds, the log does not contain workspace runtime ensure after preheat failed, and expect(ensureSpy).not.toHaveBeenCalled(). Dropping the state === 'active' gate must turn it red; today it produces the WARN instead.
中文说明
这处对 primary runtime 的启动期读取,跳过了本代码库中其他每一个 primary runtime 消费方都会加的 state === 'active' 判断——见 activeRuntime(workspace-registry.ts:321-322)、requirePrimaryRuntime(:323-333)、server.ts:3119-3122、routes/workspace-runtime.ts:87-89,以及 run-qwen-serve.ts:6456-6459。因此处于 transitioning 或 blocked 状态的 primary entry 会把「即将被替换、其 generation guard 已关闭」的 runtime 交给 ensure()。当一次信任策略变更在启动期 ACP preheat 在飞时被 reconcile,workspace-trust-reconciler.ts:113/:305 会调用 registry.beginReplacement(entry, revision),它把 entry.state 置为 'transitioning' 并关闭 entry.current.guard,同时让 entry.current 仍指向旧 runtime(workspace-registry.ts:405-424);blockReplacement(:467-474)对 'blocked' 做同样的事。对 primary 而言这就是唯一可达的非 active 状态,因为 beginDrain/commitDrain/completeDrain 都会在 runtime.primary 上提前返回(:530-566)。随后 preheat resolve,本行返回那个已退役的 runtime,ensure() 的第一句 assertAcceptingWork() 会在 disposed || draining 检查之前调用 generationGuard?.assertOpen()(coordinator :715-719),抛出 WorkspaceGenerationClosedError('Workspace runtime generation is no longer active.')。该类继承自 Error 而不是 WorkspaceDrainingError,所以下面的 .catch 匹配不上,守护进程会为一次有序的内部替换输出 warn 级的 workspace runtime ensure after preheat failed: Workspace runtime generation is no longer active.——被叫醒来查 MCP discovery 的人,会被指向实际发生的信任/拓扑变更之外的方向。接着替换后的 generation 永远不会获得启动期 discovery:生产代码里只有两个 ensure() 调用点,而 runtimeActivated → workspaceRuntimeRemoval.runtimeAdded(:7148-7179)只重启计划任务与 channel worker,不做任何 MCP 或 Skills discovery。窗口有两个而不是一个——preheat 在「guard 已关闭 → bridge.shutdown()」这个窗口内 resolve,而这不是一个 microtask 级的间隙,因为 disposeRuntime 会先执行 coordinator.dispose()、workspaceVoiceCoordinator.disposeRuntime(),并且在配置了 channel 时执行 channelWorkerManager.removeWorkspace() 与 refreshWorkspaces()(:7300-7347),才轮到 bridge.shutdown()(:7390-7394);以及 preheat 在 beginReplacement 之前 resolve,于是 guard 在 ensure 执行途中关闭——queueMcpWork/queueSkillsWork 会重跑 assertAcceptingWork()(:502、:520),而 ensure 外层 catch(:255-262)会先调用 this.assertAcceptingWork(error),把 generation 错误原样重新抛进同一个 .catch。ensure 可以在飞 60-120 秒,而信任监视器每 1000 毫秒轮询一次(daemon-trust-policy-monitor.ts:41),并且是在 buildRuntime(:7896)内启动的,早于 startBridgePreheat(:9040)。
证据见上方英文代码块:在未改动的 PR 代码上,用真实的 runQwenServe、真实的 ensure()、fake bridge,在启动 preheat 挂起期间驱动 registry.beginReplacement(entry, 'probe-revision'),然后 resolve preheat。未修复侧 ensureCalls=1、ensureGotRetiredRuntime=true,日志出现 [WARN] ... failed: Workspace runtime generation is no longer active.;加上一行 active 判断后 ensureCalls=0,日志变为 [INFO] ... skipped: no primary runtime。guard 同一性是实测而非仅靠阅读:beginReplacement 后 guardClosed=true,且 ensure 在同一 runtime 上抛出 generation 错误。全仓扫描 rg '\.ensure\('(排除测试)得到 2 个生产调用点,1 个有关信任/状态把关(HTTP 路由),1 个没有——就是本处。声明:替换中途的状态是通过 registry.beginReplacement 驱动的(正是 reconciler 发出的那个调用),而不是真的去改信任策略文件;其下游全部是产品自己未改动的代码。
请按 registry 自己的访问器的写法把关,这样既保留本 PR 想要的不抛异常行为,也不需要新增导入(代码见上方 suggestion 块),使非 active 的 primary 落进已有的 no primary runtime INFO 跳过分支,而不是进入 ensure()。registry?.resolveWorkspaceCwd(undefined) 是等价的一行写法,已经把这个判断封装好了。
修复不得违反这一点:export type WorkspaceEntryState = | 'active' | 'draining' | 'transitioning' | 'blocked' | 'removed';(workspace-registry.ts:56-61)——判断必须对每一个非 active 状态都跳过,而不只是 'transitioning';要对齐的写法是 :321-322 的 activeRuntime(entry?.state === 'active' ? entry.current?.runtime : undefined),而不是 current !== undefined 这种判断,后者会把已关闭的 generation 重新放进来。对 primary 只有 'transitioning' 与 'blocked' 可达,所以修复不要加入假定 primary 可能处于 'draining'/'removed' 的处理。另外本文件对 ./workspace-registry.js 是 type-only 导入(:152-157),所以「改在 .catch 里捕获 WorkspaceGenerationClosedError」这个替代方案不得引入静态值导入。
请用一个「去掉修复就会变红」的测试把它钉住:在 logs when boot MCP discovery skips because primary runtime is gone 旁边新增一个用例,复用它已经装好的 createServeApp spy 来拿到 registry——让 preheat 挂起,把 workspaceRegistry!.primaryEntry.state 设为 'transitioning'(并在 finally 中恢复,就像那个测试恢复 current 一样),resolve preheat,然后断言 waitForDaemonLog(logBaseDir, 'workspace runtime ensure after preheat skipped:') 成功、日志中不含 workspace runtime ensure after preheat failed、且 expect(ensureSpy).not.toHaveBeenCalled()。去掉 state === 'active' 判断它必须变红;今天它会产出那条 WARN。
— qwen3.8-max via Qwen Code /review (v0.23.0)
| function deepestErrorMessage(err: unknown): string { | ||
| if (!(err instanceof Error)) return String(err); | ||
| let deepest: Error = err; | ||
| while (deepest.cause instanceof Error) { |
There was a problem hiding this comment.
[Suggestion] Nothing pins this loop's iteration, or the String(err) fallback above it. Both new failure tests feed deepestErrorMessage a zero- or one-hop chain: does not leak an unhandled rejection when boot MCP discovery fails throws WorkspaceRuntimeInitializationError(new Error('cause detail')), one hop, which produces identical output under while or if; and logs cause-less boot runtime ensure failures without an undefined suffix throws WorkspaceRuntimeStillStartingError(), no cause at all. A grep for 'ensure after preheat' across packages/cli/src/**/*.test.ts returns six hits, all in run-qwen-serve.test.ts, and the two failed: assertions are exactly those two cases — so a full run of that file is the entire detecting population. Real boot chains are deeper than either: prepareMcpRevision re-wraps a failed inner preheat at coordinator :587, outside its own try, so it propagates, and ensure() wraps that again at :258 in the Promise.all catch, giving a three-node chain whose two outer messages are both the generic 'Workspace runtime failed to initialize'. That inner preheat runs whenever !snapshot.runtimeLive at MCP-prepare time, which is the child having died after boot preheat. Under if the daemon log names that wrapper instead of the root failure — precisely what this loop exists to prevent — and the operator loses the only diagnostic for a boot MCP failure. The same holds for the fallback: no test rejects with a non-Error, so replacing String(err) with a constant is invisible.
Witness:
executed in a scratch tree at d8e542891b; the review worktree was never edited

baseline (intact, full file):                    Test Files 1 passed (1) / Tests 387 passed (387)
Mutant A  while -> if at :276, full file:        Tests 1 failed | 387 passed (388)
            the single failure is the probe test added for this check - EVERY one of the PR's 387 tests
            passes, and the daemon log still emits both asserted lines unchanged
            ('...failed: cause detail', 1 hop; '...failed: Workspace runtime is still starting', 0 hops)
            -> the mutation SURVIVES the suite
Mutant B  return String(err) -> 'unknown error':  exit=0, Tests 388 passed (388)  -> the fallback is unpinned too

the mutant is not equivalent - the probe flips:
  throwing WorkspaceRuntimeInitializationError(WorkspaceRuntimeInitializationError(new Error('root detail')))
  through the real boot path:
    INTACT  [WARN] [DAEMON] workspace runtime ensure after preheat failed: root detail
    MUTANT  [WARN] [DAEMON] workspace runtime ensure after preheat failed: Workspace runtime failed to initialize

population check: grep 'ensure after preheat' packages/cli/src/**/*.test.ts -> 6 hits, all in run-qwen-serve.test.ts
Add one case that rejects with a depth-2 chain and asserts the log names the innermost message, plus one non-Error rejection:
      vi.spyOn(
        WorkspaceRuntimeCoordinator.prototype,
        'ensure',
      ).mockImplementation(async () => {
        throw new WorkspaceRuntimeInitializationError(
          new WorkspaceRuntimeInitializationError(new Error('root detail')),
        );
      });
      // ...
      await waitForDaemonLog(
        logBaseDir,
        'workspace runtime ensure after preheat failed: root detail',
      );
and a sibling rejecting with a bare string, asserting the log contains that string. This is a Suggestion rather than a Critical on the project's own rule — the shipped code is correct, nothing asserts the opposite, nothing was weakened in this diff, and no incorrect behaviour ships.
The fix must not violate this: the two existing assertions bound it from below — run-qwen-serve.test.ts:16668 pins 'workspace runtime ensure after preheat failed: cause detail' at depth 1 and :16708 pins '…failed: Workspace runtime is still starting' together with expect(logContent).not.toContain('(undefined)') at depth 0. So any bound added to the walk must stay at or above those depths and must not append an undefined suffix.
Please pin this with a check that fails without the fix: the depth-2 case is itself the witness, and it was measured — under while → if the log reads failed: Workspace runtime failed to initialize instead of failed: root detail, so that assertion goes red while all 387 existing tests stay green. The non-Error case goes red if return String(err) is replaced.
中文说明
没有任何测试钉住这个循环的迭代,也没有钉住它上面那个 String(err) 兜底分支。两个新的失败测试都只给 deepestErrorMessage 喂了 0 跳或 1 跳的链:does not leak an unhandled rejection when boot MCP discovery fails 抛出 WorkspaceRuntimeInitializationError(new Error('cause detail')),1 跳,在 while 与 if 下输出完全相同;logs cause-less boot runtime ensure failures without an undefined suffix 抛出 WorkspaceRuntimeStillStartingError(),完全没有 cause。对 packages/cli/src/**/*.test.ts grep 'ensure after preheat' 得到 6 处命中,全部在 run-qwen-serve.test.ts 内,而其中两处 failed: 断言正好就是这两个用例——所以跑完整个文件就是全部的检出population。真实的启动链比这两者都深:prepareMcpRevision 会在 coordinator :587 处重新包装一次失败的内层 preheat,且该行在它自己的 try 之外,因此会向上传播;ensure() 又在 :258 的 Promise.all catch 里再包一层,得到一个三节点链,其外侧两条消息都是通用的 'Workspace runtime failed to initialize'。而那个内层 preheat 会在 MCP 准备阶段 !snapshot.runtimeLive 时执行,也就是子进程在启动预热之后死掉的情形。在 if 下,守护进程日志会写出那个包装层的消息而不是根因——这恰恰是本循环存在的意义——运维者因此失去启动期 MCP 失败唯一的诊断信息。兜底分支同理:没有测试用非 Error 值 reject,所以把 String(err) 换成一个常量是完全不可见的。
证据见上方英文代码块:在 d8e542891b 的 scratch tree 中执行(评审 worktree 从未被修改)。基线整文件 387 passed;变异体 A(:276 处 while 改 if)整文件 1 failed | 387 passed,唯一失败的是为本检查新增的探针测试——PR 自己的 387 个测试全部通过,日志中两条被断言的行也原样输出,即该变异体在套件中存活;变异体 B(return String(err) 改为 'unknown error')exit=0、388 passed,兜底分支同样未被钉住。变异体并非等价变异——探针会翻转:用真实启动路径抛出双层包装的 new Error('root detail') 时,未修改侧日志为 failed: root detail,变异侧为 failed: Workspace runtime failed to initialize。
请新增一个用 2 跳链 reject 的用例,断言日志写出最内层消息,再加一个非 Error 的 rejection(代码见上方英文部分):一个 sibling 用例用裸字符串 reject,断言日志包含该字符串。按项目自己的规则这是 Suggestion 而不是 Critical——已发布的代码是正确的,没有测试断言了相反的行为,本 diff 没有削弱任何断言,也没有错误行为被发布。
修复不得违反这一点:现有两条断言从下方给出了下界——run-qwen-serve.test.ts:16668 钉住深度 1 的 'workspace runtime ensure after preheat failed: cause detail',:16708 钉住深度 0 的 '…failed: Workspace runtime is still starting' 并附带 expect(logContent).not.toContain('(undefined)')。因此给这个遍历加任何上限都不得低于这些深度,也不得追加 undefined 后缀。
请用一个「去掉修复就会变红」的检查把它钉住:那个 2 跳用例本身就是证据,并且已经实测——在 while 改 if 之后,日志会读作 failed: Workspace runtime failed to initialize 而不是 failed: root detail,因此该断言变红,而现有 387 个测试仍全绿。非 Error 用例则在 return String(err) 被替换时变红。
— qwen3.8-max via Qwen Code /review (v0.23.0)

🩺 serve daemon A/BBuilt the PR base vs this PR head
|
| field | PR base (before) | this PR (after) |
|---|---|---|
activeWorkStaleMs |
6 |
5 |
— Qwen Code · serve A/B
Remove the forbidden bridgeErrors static import and classify ensure
.catch failures via shuttingDown/runtimeStartupError. Check startup
failure before shutdown when skipping post-preheat ensure, gate primary
runtime on active state, and add tests for deepestErrorMessage,
inactive primary, and the runtimeStartupError guard.
|
Addressed round-5 on :
Local: fast-path import-boundary green; / green; → 21 passed. |
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
1 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- R6-11 boot success test pins the ensure() call but never the discovery effect (packages/cli/src/serve/run-qwen-serve.test.ts:16613) — already reported as R2-5 (comment 3945050787), whose own thread forbids the assertion this proposes agains…
Not reviewed: build-and-test efficacy probe — the mutation / hunk-necessity harness died inside the repo's own vitest prerequisite guard, so its control produced no verdict (harnessValidated: null; 2 mutants and 5 hunk probes skippedForBaseline, 0 run); the build and the test suites themselves ran and are reported separately.
Not reviewed: issue-fidelity closing-issue enumeration — the platform CLI on this machine is older than gh 2.72.0, so closing-issue references could not be resolved; the issue named in the PR description was fetched from its own repository and evaluated directly.
Not explored to full depth (tool budget reached): "agent reverse-audit (round 5)": did not execute the new tests — packages/cli vitest needs a full npm run build in this worktree and gh pr checks 11145 reported only review-infrastructure…; "agent reverse-audit (round 4)": did not execute the full 390-test run-qwen-serve.test.ts (only the 21-test runQwenServe startup observability describe plus the 12 new tests), so cross-*des…; "agent reverse-audit (round 1)": did not execute the ten new tests (no unit-test job appears in gh pr checks 11145 , and this worktree's build state is unverified), so two assertions remain un…; "agent reverse-audit (round 1)": dropped a candidate claiming the boot hook's keepAliveMs: ENSURE_KEEP_ALIVE_MS newly holds the ACP child for 10 minutes on every boot — I could not resolve th…; "agent reverse-audit (round 6)": did not execute the new tests or npm run typecheck — all conclusions above are from reading source in this worktree, not from a run..
Not reviewed: reverse audit — stopped before round 8 by the review time budget.
Test Plan (not a blocker): 18 passed — this review observed 28874 passed.
Deferred under the convergence posture (round 6, not a blocker) — recorded, not requested in this round:
packages/cli/src/serve/run-qwen-serve.ts:270 — [review] Keep-alive duration re-declared when the callee already…packages/cli/src/serve/run-qwen-serve.ts:8966 — [review] Boot ensure omits the runtime.trusted gate the HTTP path…packages/cli/src/serve/run-qwen-serve.ts:8970 — [review] Three structurally different skip states share one…packages/cli/src/serve/run-qwen-serve.ts:8984 — [review] The resolved ensure() status is discarded, so a real MCP…packages/cli/src/serve/run-qwen-serve.ts:8984 — [review] 60s ensure budget is half the 120s prepare deadline it…packages/cli/src/serve/run-qwen-serve.ts:8986 — [review] The in-catch suppression guard has no test; deleting it…packages/cli/src/serve/run-qwen-serve.ts:8987 — [review] R4-4 (fix-induced): orderly drain now logged as a WARN…packages/cli/src/serve/run-qwen-serve.ts:8990 — [review] Retryable StillStartingError logged as a terminal failure,…
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 1 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未审查(原文为英文):build-and-test efficacy probe — the mutation / hunk-necessity harness died inside the repo's own vitest prerequisite guard, so its control produced no verdict (harnessValidated: null; 2 mutants and 5 hunk probes skippedForBaseline, 0 run); the build and the test suites themselves ran and are reported separately.
未审查(原文为英文):issue-fidelity closing-issue enumeration — the platform CLI on this machine is older than gh 2.72.0, so closing-issue references could not be resolved; the issue named in the PR description was fetched from its own repository and evaluated directly.
未探索到全部深度(达到工具调用预算):"agent reverse-audit (round 5)":did not execute the new tests — packages/cli vitest needs a full npm run build in this worktree and gh pr checks 11145 reported only review-infrastructure…;"agent reverse-audit (round 4)":did not execute the full 390-test run-qwen-serve.test.ts (only the 21-test runQwenServe startup observability describe plus the 12 new tests), so cross-*des…;"agent reverse-audit (round 1)":did not execute the ten new tests (no unit-test job appears in gh pr checks 11145 , and this worktree's build state is unverified), so two assertions remain un…;"agent reverse-audit (round 1)":dropped a candidate claiming the boot hook's keepAliveMs: ENSURE_KEEP_ALIVE_MS newly holds the ACP child for 10 minutes on every boot — I could not resolve th…;"agent reverse-audit (round 6)":did not execute the new tests or npm run typecheck — all conclusions above are from reading source in this worktree, not from a run.。
未审查:反向审计——评审时间预算不足,未能开始第 8 轮。
Test Plan(非阻断):18 passed — this review observed 28874 passed。
收敛姿态下延后(第 6 轮,非阻断)——已记录,本轮不要求修改:共 8 条(原文未翻译,列表见上方英文部分)。
— qwen3.8-max via Qwen Code /review (v0.23.1)

Maintainer verification — real
|
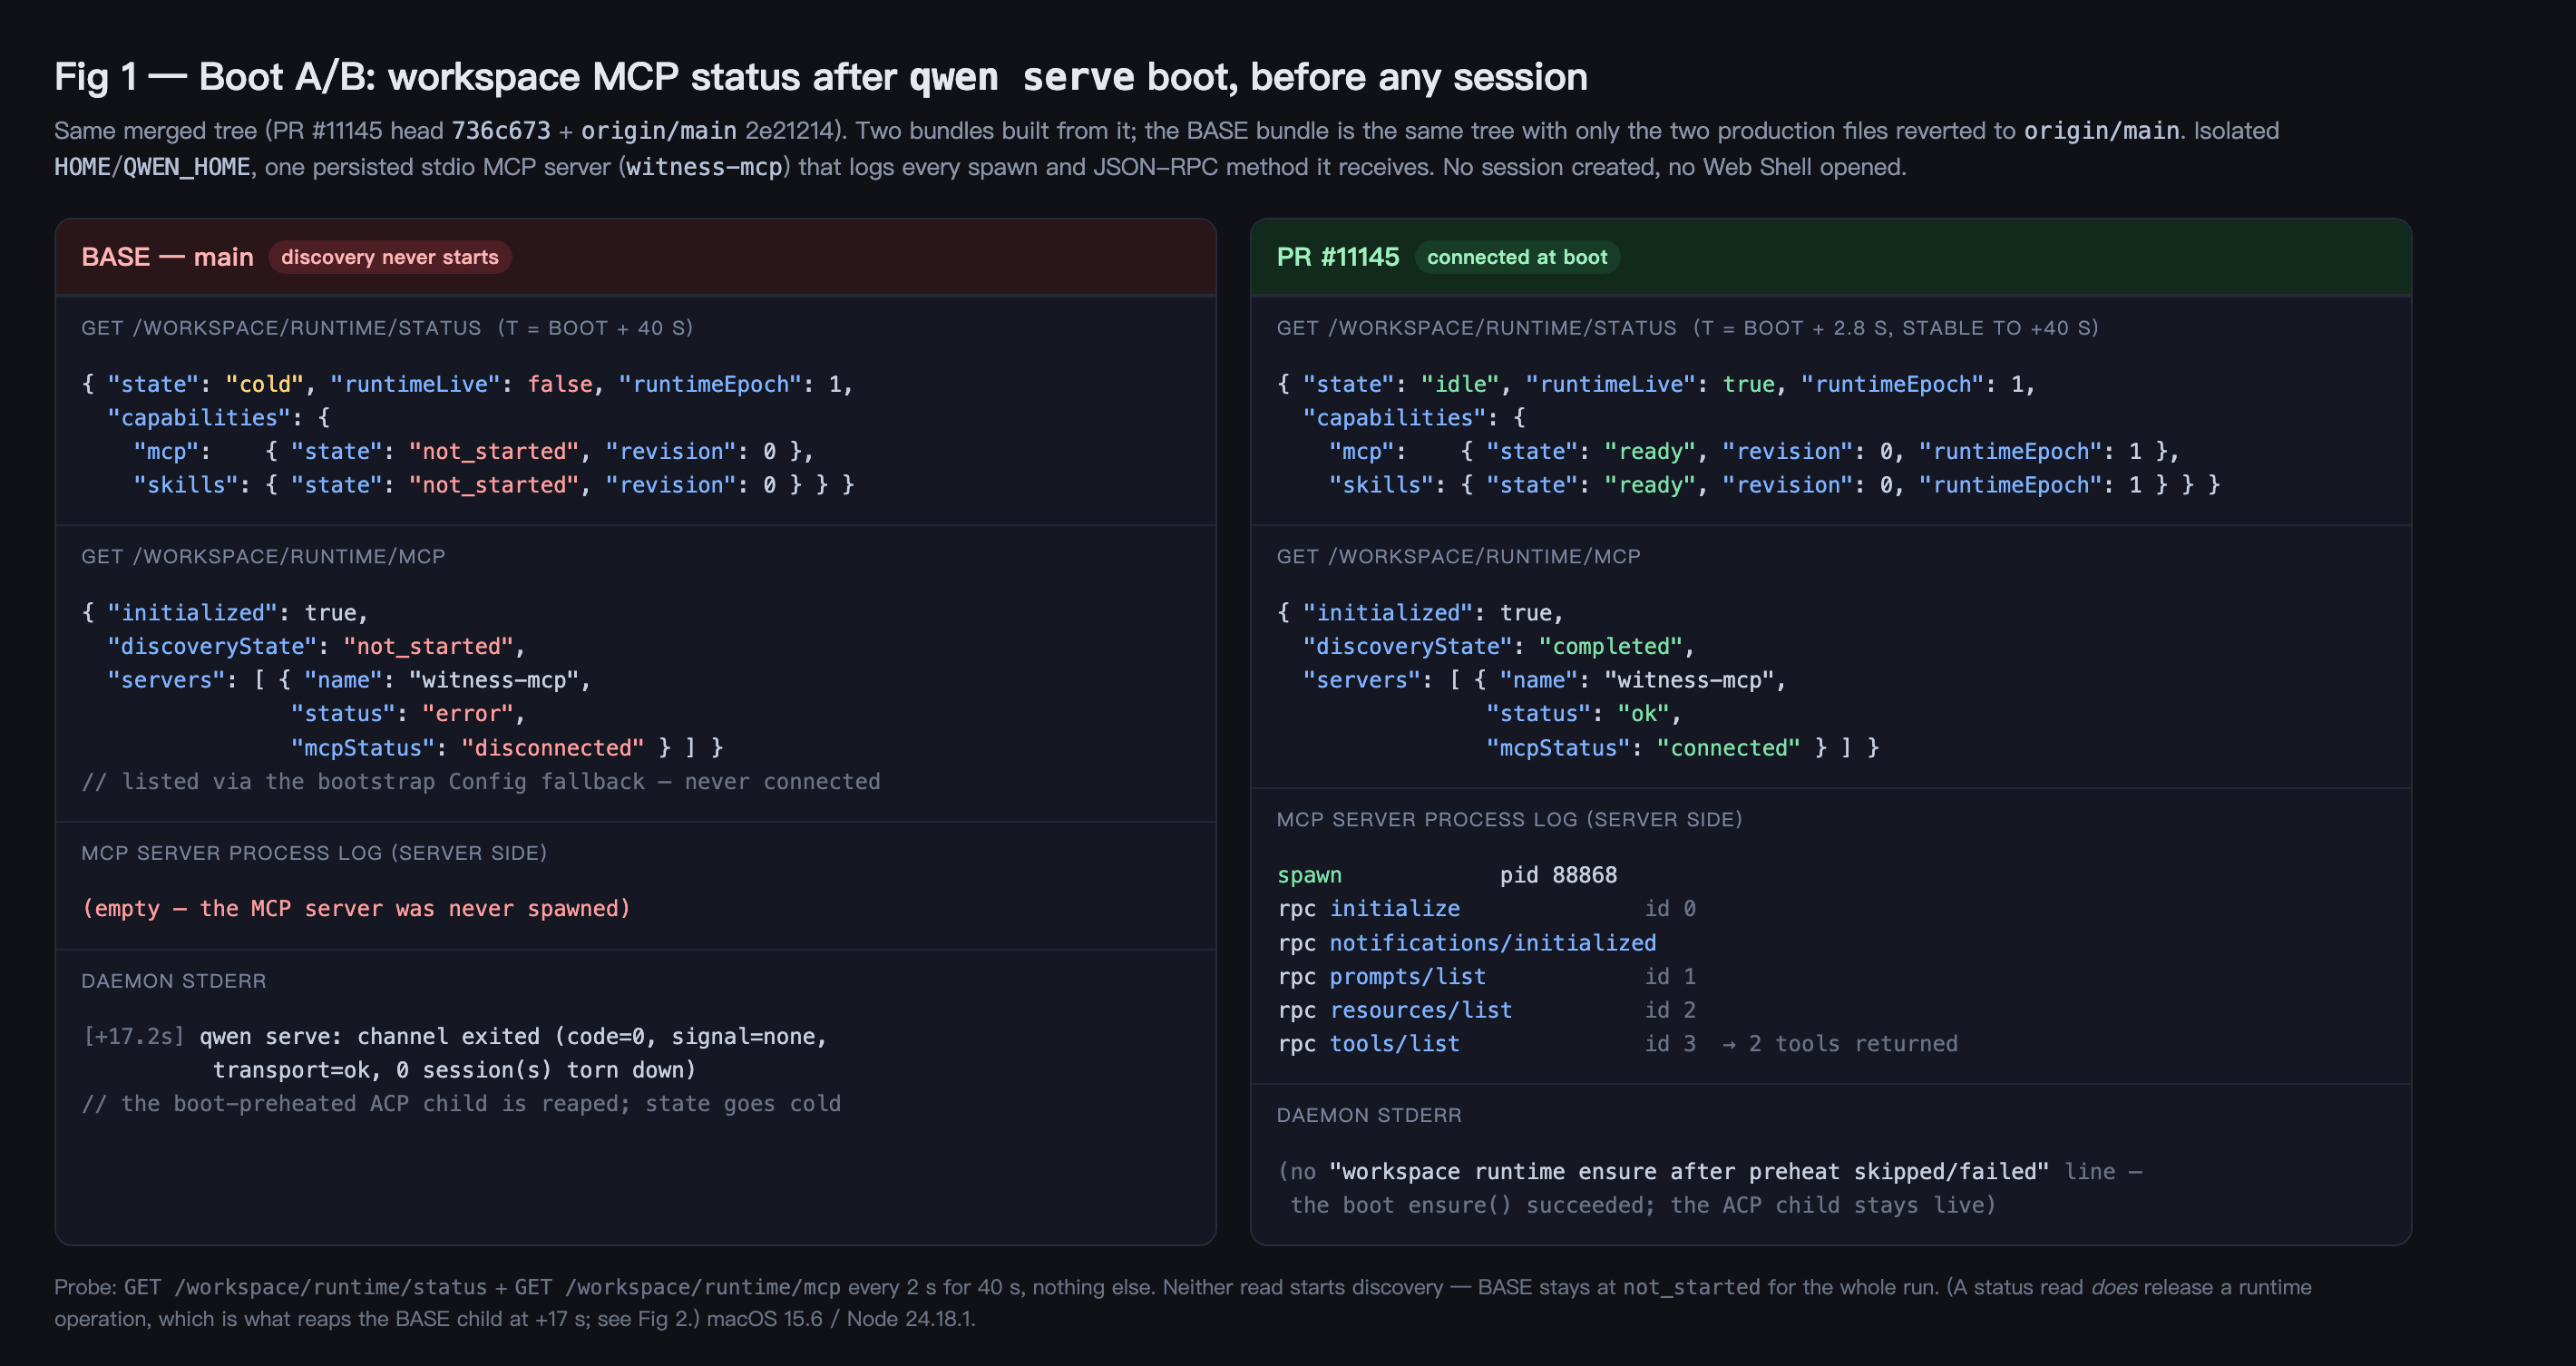
| after boot, no session | BASE (main) |
PR #11145 |
|---|---|---|
capabilities.mcp.state |
not_started (whole run) |
ready at t+2.8 s |
GET /workspace/runtime/mcp → discoveryState |
not_started |
completed |
| server entry | witness-mcp status: error, mcpStatus: disconnected |
status: ok, mcpStatus: connected |
| MCP server process | never spawned (server log empty) | spawned; answered initialize, tools/list |
The description's clarification is accurate: on main the server is still listed through the bootstrap-Config fallback — what is missing is discovery and connection state.
2. The cost, measured
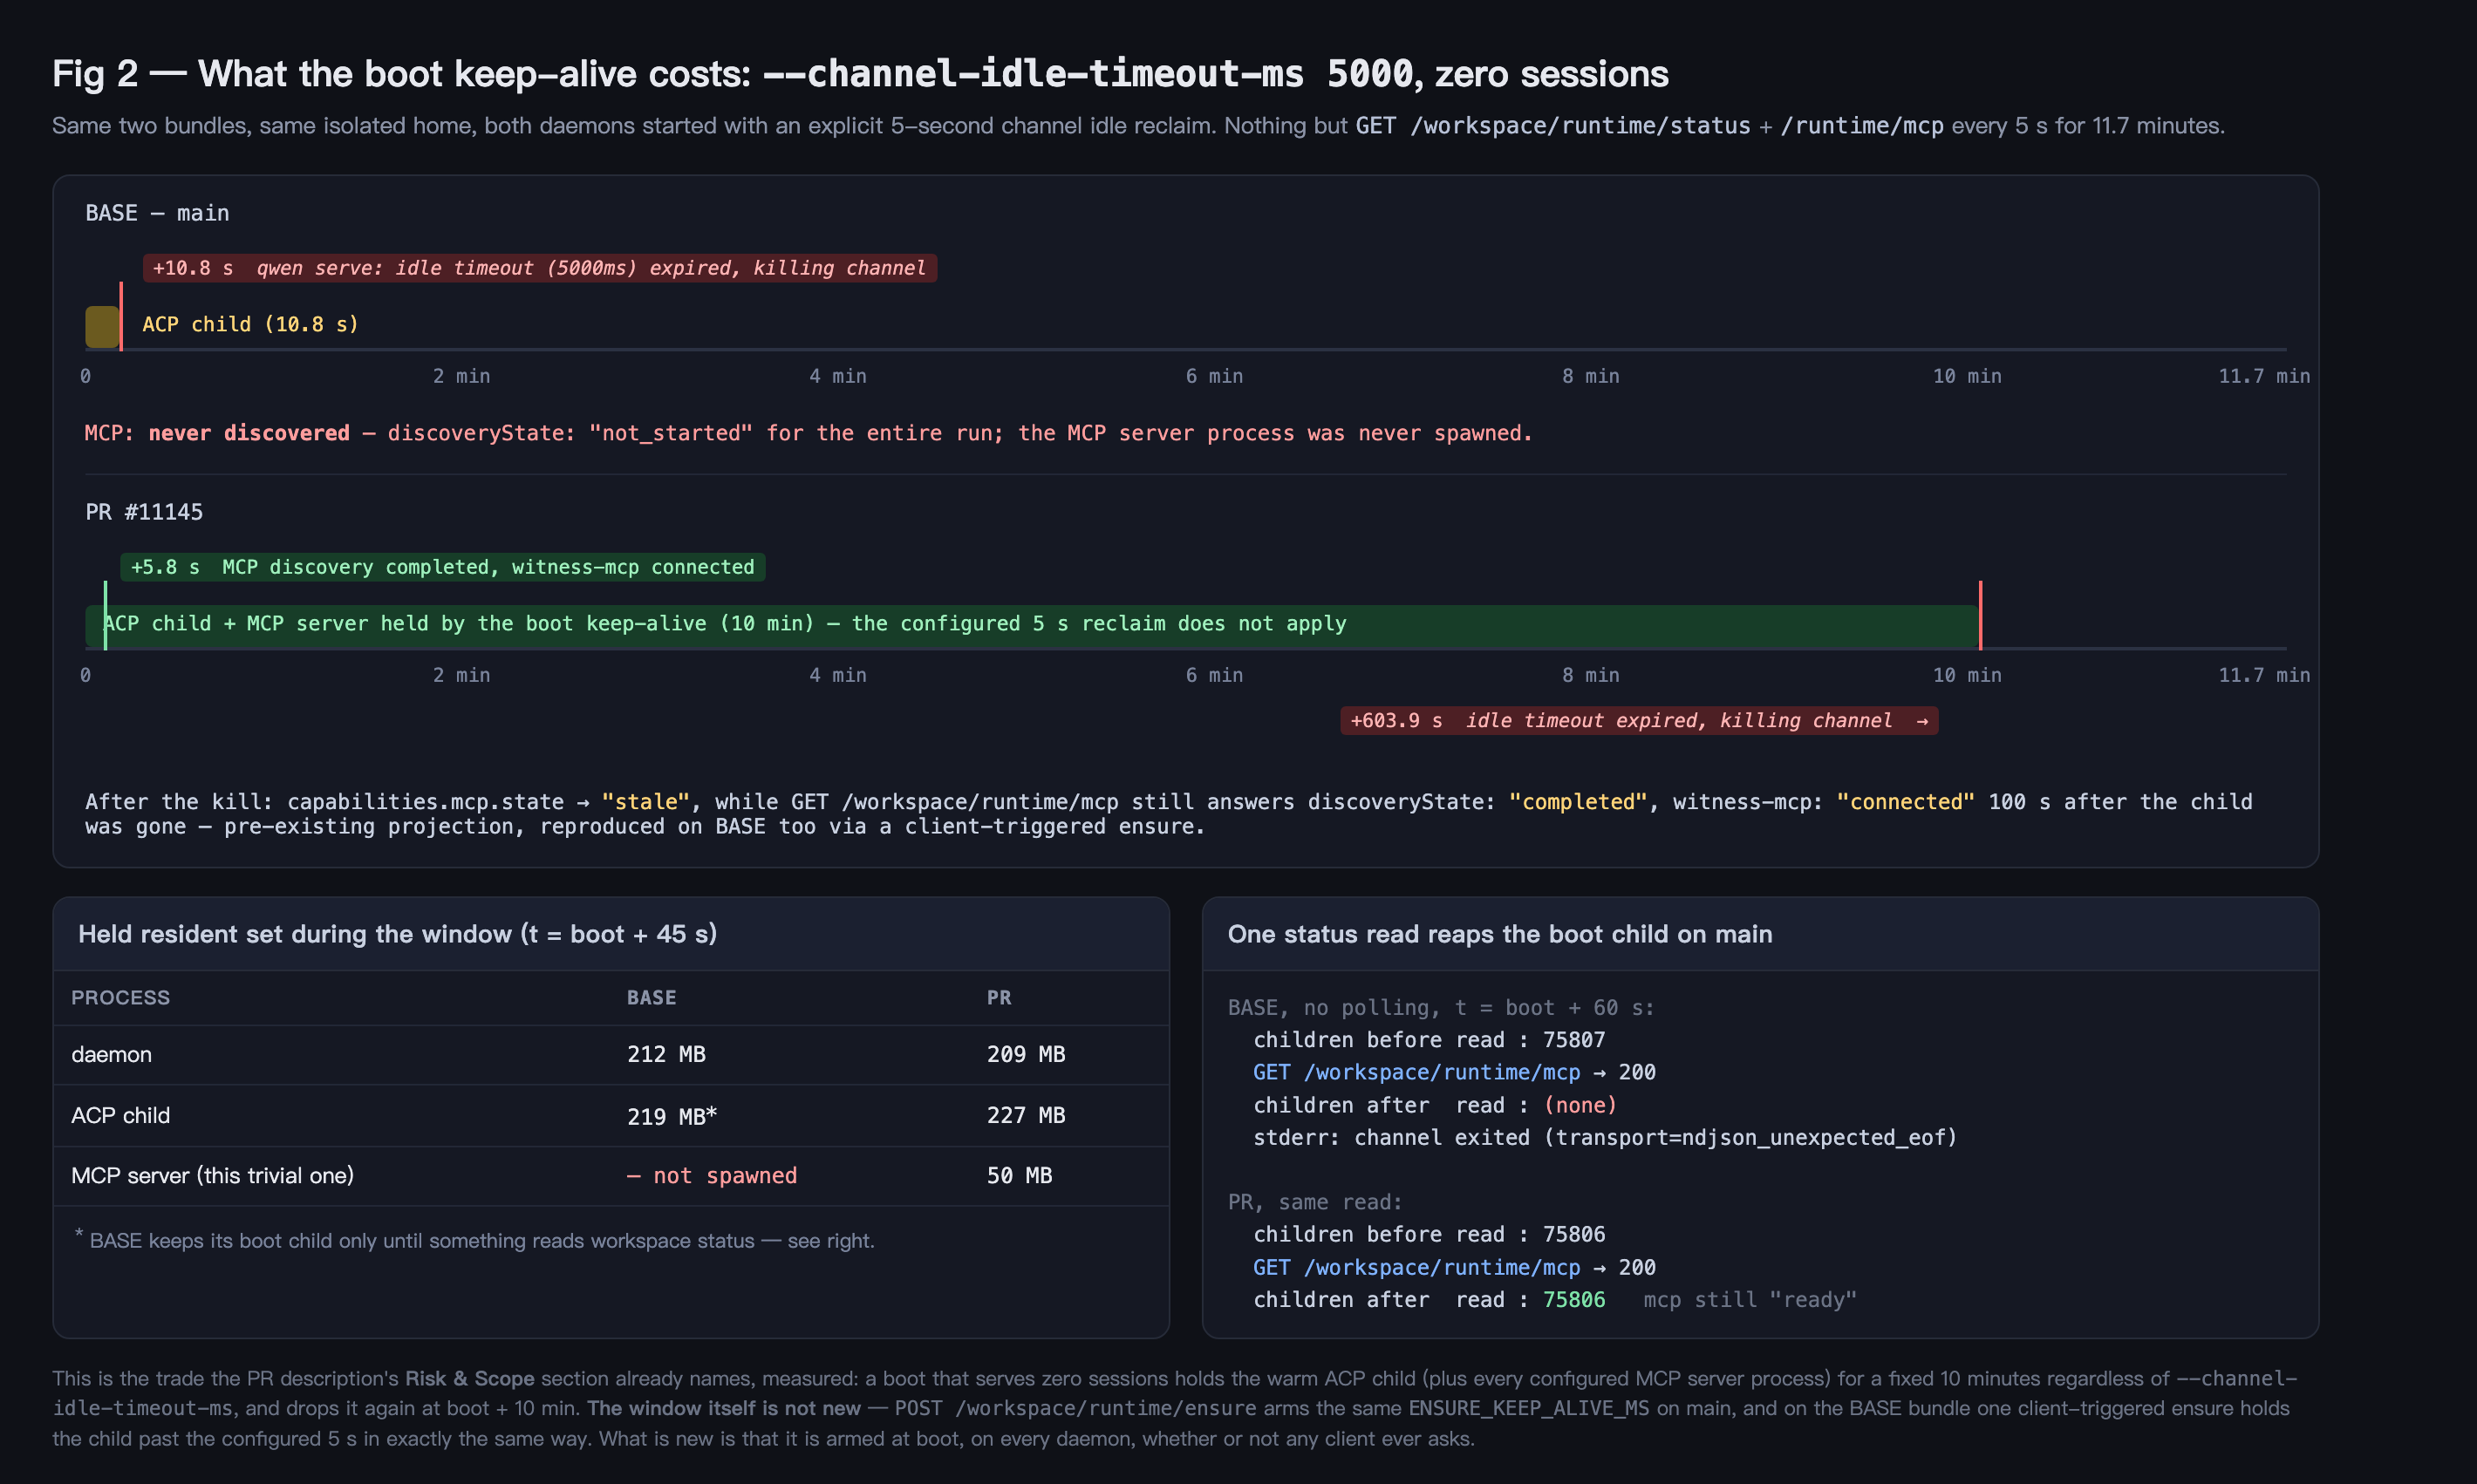
Both daemons started with --channel-idle-timeout-ms 5000, zero sessions, 11.7 min:
- BASE kills the channel at +10.8 s (
idle timeout (5000ms) expired) and never discovers MCP. - PR holds the ACP child to +603.9 s — the configured 5 s reclaim does not apply inside the boot keep-alive window — then kills it;
capabilities.mcp.stateflips tostale. - Held during the window: ACP child ≈ 227 MB plus one process per configured MCP server (≈ 50 MB for this trivial stdio one).
- Fairness note: the 10-minute window is not new.
POST /workspace/runtime/ensurearms the sameENSURE_KEEP_ALIVE_MSonmain, and I reproduced that on the BASE bundle. What is new is that every boot arms it unconditionally, including boots that serve nothing.
One thing this made visible that is worth knowing either way: on main, a single GET /workspace/runtime/mcp reaps the boot-preheated child (default idle timeout 0 → immediate kill when the runtime operation releases). So on main the boot warm-up is discarded the first time anything asks for status. Preventing that is the substantive part of what the boot keep-alive buys.
3. What a client actually gains
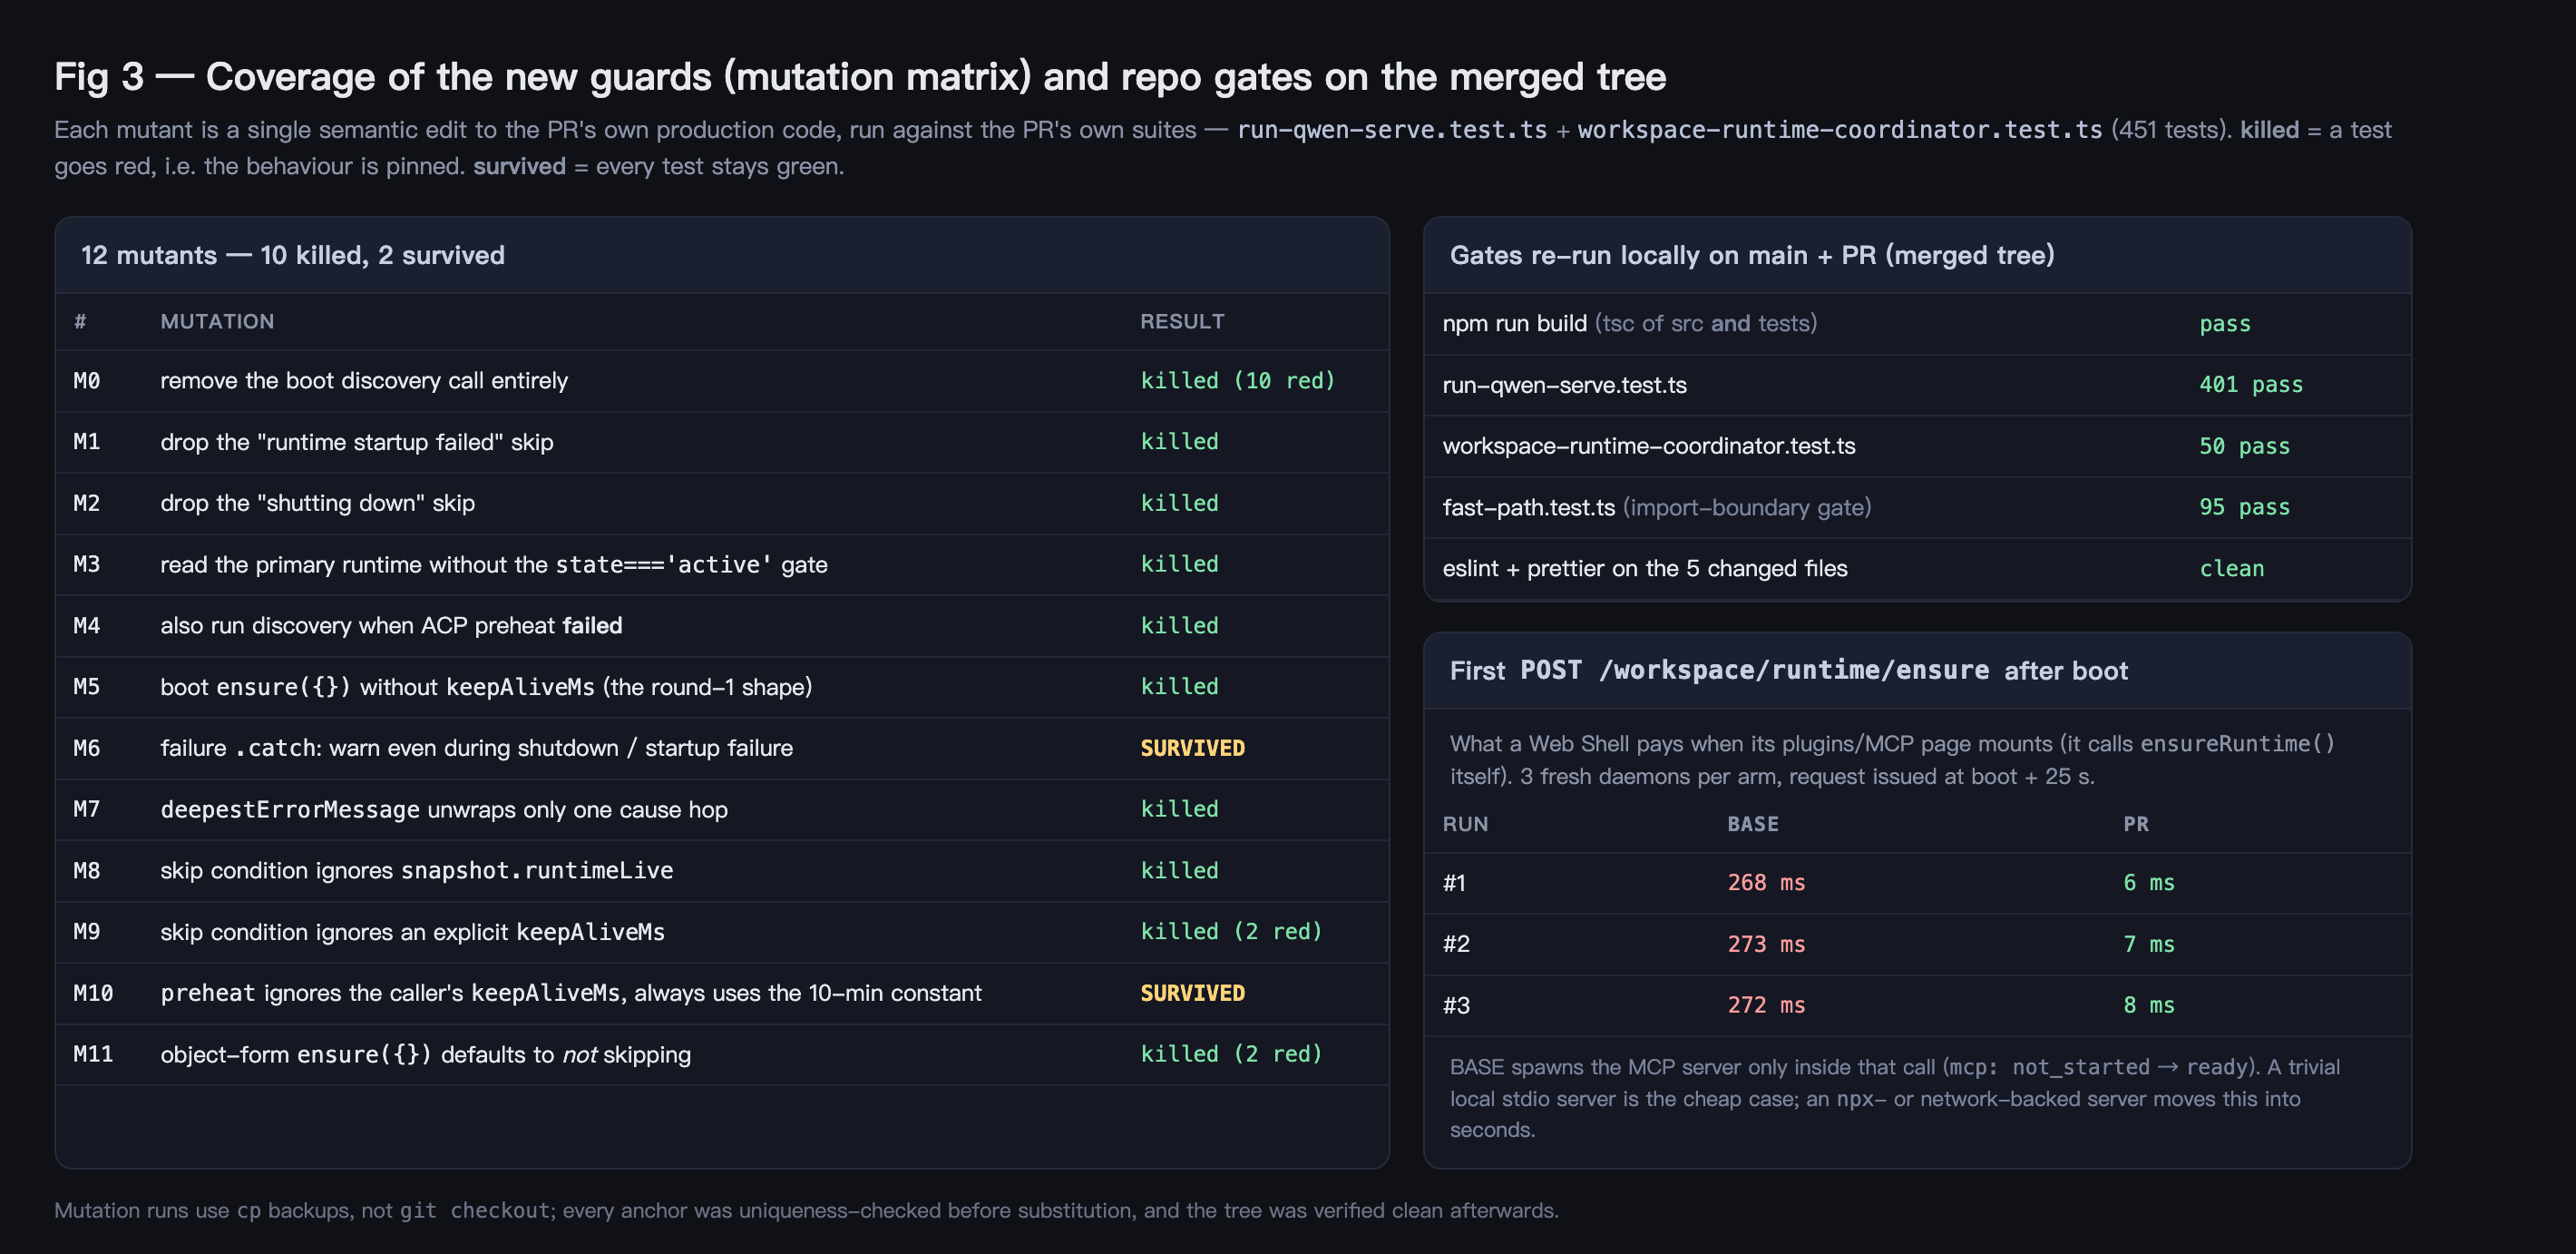
First POST /workspace/runtime/ensure at boot+25 s, 3 fresh daemons per arm: BASE 268 / 273 / 272 ms → PR 6 / 7 / 8 ms. BASE spawns the MCP server inside that call; a trivial local stdio server is the cheap case, an npx- or network-backed one moves this into seconds.
Worth setting expectations on, though: the Web Shell plugins/MCP page calls ensureRuntime() itself on mount, so its MCP panel ends up showing connected on both arms — I confirmed that in a real browser against both daemons. This PR changes who pays for discovery and when, not what that page eventually shows. The readers that genuinely see the gap are the non-ensuring ones: GET /workspace/runtime/{status,mcp}, daemon status, and anything polling before the first session.
4. Scope
With --workspace A --workspace B, at boot+30 s the secondary is still state: cold, mcp: not_started, discoveryState: not_started, and no MCP process was spawned for it. Primary-only, as described and as the unit test asserts.
5. Coverage of the new guards — 12 mutants, 10 killed
Each mutant is one semantic edit to the PR's own production code, run against run-qwen-serve.test.ts + workspace-runtime-coordinator.test.ts (451 tests). Pinned at this head: discovery only after a successful preheat (M4), primary-only via the state === 'active' gate (M3), both skip guards (M1/M2), the boot keepAliveMs (M5), the deepestErrorMessage unwrap loop (M7), and all three terms of the new skip condition (M8/M9/M11). Several standing review threads about exactly these being unpinned no longer reproduce at 736c673.
Two survivors, both minor:
- M6 — deleting
if (shuttingDown || runtimeStartupError !== undefined) return;from the failure.catchleaves all 451 tests green. It only gates a log line, so the exposure is a spurious warn during an orderly shutdown. - M10 — making
preheatignore the caller'skeepAliveMsand always use the constant is also invisible to the suites, because boot is the only caller and it passes exactly that constant. That is the concrete cost ofEnsureOptionsbeing wider than its use:timeoutMsandskipKeepAlivePreheathave no production caller at all, and the HTTP route still takes the numeric path (coordinator.ensure()), so the object-form skip branch is unreachable in production today.
I also checked the operator-visibility question: daemonLog tees every INFO/WARN to stderr and the daemon log file, and I see those lines in my captured daemon stderr — so the round-5 diagnostics do reach an operator (unlike the earlier debugLogger rounds). Reaching the skip branches in a live daemon is another matter: in shutdown races the preheat itself fails first (so nothing is scheduled) and the daemon exits ~100 ms after SIGTERM. Those branches are defensive, not observable in practice.
6. Gates
npm run buildon the merged tree: pass — this compiles the test files too, so the earlierChannelWorkerSnapshotmock typing Critical is gone at this head.fast-path.test.tsincluding "keeps the runQwenServe static source graph free of ACP runtime modules": 95 pass — the forbidden-import Critical is resolved.run-qwen-serve.test.ts401 pass,workspace-runtime-coordinator.test.ts50 pass, eslint + prettier on the 5 changed files: clean.- The red
Lint & Staticis not this PR. The job, evaluated from the merge ref, runs.github/scripts/check-lint-gate-freshness.mjs, whichmaingained in ci: fail Lint & Static when the base moved the lint gate #11383 and this branch does not have →MODULE_NOT_FOUNDafter 14 s. Mergingorigin/maininto the branch clears it — please merge, not rebase, so the inline review threads stay attached. - One caveat on the bot's
serve daemon A/B"no response changes": its scenario set is/health,/capabilitiesand/session/*— it never reads/workspace/runtime/statusor/workspace/runtime/mcp, which is precisely where this PR's difference lives. It is not evidence of no behaviour change.
Verdict
Behaviour matches the description on every claim I could drive, the scope is honest, and the trade is disclosed in Risk & Scope. From my side this is mergeable; the open question is a product call, not a correctness one. Non-blocking follow-ups, in the order I'd rank them:
- Size the keep-alive to the work. Release it when the boot
ensure()resolves, or pass a window sized to the preparation, so a daemon that serves nothing does not hold an ACP child plus every configured MCP server for a flat 10 minutes and does not override a configured--channel-idle-timeout-ms. - Trim
EnsureOptionsto what boot uses (or add the second caller that justifies the shape); ifkeepAliveMsstays a parameter, pin the?? ENSURE_KEEP_ALIVE_MSfallback — M10 shows nothing tests it. - Optional: a test for the failure-
.catchguard (M6).
中文说明
结论
以维护者身份在本地用真实 qwen serve daemon 做了同树 A/B 验证:main 上的问题确实复现,本 PR 确实修好了,代价与描述里 Risk & Scope 写的完全一致。没有发现阻塞性缺陷;唯一的红 CI 是分支落后 main 导致的,与本 PR 无关。
装置
PR head 736c673 与 origin/main 2e21214 合并(无冲突)后,用同一棵树打两个包:PR 臂原样;BASE 臂只把 run-qwen-serve.ts 和 workspace-runtime-coordinator.ts(外加三个测试文件,否则 tsc 过不了)回退到 origin/main。臂身份在产物里核过:workspace runtime ensure after preheat 在 PR 包出现 5 次、BASE 包 0 次。隔离 HOME/QWEN_HOME,持久化一个会把每次被拉起和每条 JSON-RPC 都记流水账的 stdio MCP server,这样"discovery 到底有没有真连上"由服务端来判,而不是看 daemon 自己的状态字段。全程不建 session、不开 Web Shell。
1. 缺口复现 & 修复生效(图 1)
BASE:mcp.state 全程 not_started、discoveryState: not_started、server 是 error/disconnected、MCP 进程根本没被拉起。PR:t+2.8 s 就 ready / completed / connected,MCP server 被拉起并回了 initialize、tools/list。描述里那句澄清是准确的——main 上 server 仍会经 bootstrap 回落列出来,缺的是 discovery/连接状态。
2. 代价(图 2)
两臂都带 --channel-idle-timeout-ms 5000、零 session 跑 11.7 分钟:BASE 在 +10.8 s 就把 channel 杀了且从未 discovery;PR 把 ACP 子进程一直留到 +603.9 s(配置的 5 秒回收在 keep-alive 窗口内不生效),之后被杀、mcp.state 变 stale。窗口期内常驻:ACP 子进程约 227 MB,外加每个配置的 MCP server 一个进程(这个极简的约 50 MB)。
需要公平地说明:10 分钟窗口本身不是本 PR 引入的——POST /workspace/runtime/ensure 在 main 上就 arm 同一个 ENSURE_KEEP_ALIVE_MS,我在 BASE 包上复现了。新的是每次启动都无条件 arm 它,包括一个 session 都不服务的启动。
另外一个顺带查明、无论如何都值得知道的事实:在 main 上,只要有人 GET /workspace/runtime/mcp 一次,启动时预热的子进程就会被回收(默认 idle timeout 为 0,运行时操作一释放就立刻杀)。也就是说 main 的启动预热在"第一次有人问状态"时就作废了——挡住这件事才是这个 keep-alive 真正买到的东西。
3. 客户端实际得到什么(图 3)
启动后 25 秒发第一次 POST /workspace/runtime/ensure,每臂 3 次全新 daemon:BASE 268 / 273 / 272 ms → PR 6 / 7 / 8 ms。BASE 是在这次调用里才拉起 MCP server;本地极简 stdio 是最便宜的情况,npx 或走网络的 server 会把这个数量级抬到秒。
但期望值要说清楚:Web Shell 的插件/MCP 页面自己会在挂载时调 ensureRuntime(),所以两臂的 MCP 面板最终都显示"已连接"(我用真浏览器对两个 daemon 都看过)。本 PR 改的是谁在什么时候为 discovery 买单,不是那个页面最终显示什么。真正看得见缺口的是不会主动 ensure 的读取方:GET /workspace/runtime/{status,mcp}、daemon status,以及第一次 prompt 之前的各种轮询。
4. 作用域
--workspace A --workspace B 时,boot+30 s 的 secondary 仍是 cold / not_started / not_started,也没为它拉起 MCP 进程。只覆盖 primary,与描述和单测一致。
5. 新守卫的覆盖度 —— 12 个变异体杀 10
已被钉住的:只在 preheat 成功后才 discovery(M4)、state === 'active' 的 primary 门(M3)、两个 skip 守卫(M1/M2)、boot 的 keepAliveMs(M5)、deepestErrorMessage 的展开循环(M7),以及新 skip 条件的全部三个项(M8/M9/M11)。若干条说这些"没有测试钉住"的历史评审线程,在 736c673 上已经复现不出来了。
两个存活的都不严重:
- M6 —— 把失败
.catch里的if (shuttingDown || runtimeStartupError !== undefined) return;删掉,451 个测试全绿。它只挡一条日志,风险是有序关停时多打一条 warn。 - M10 —— 让
preheat忽略调用方传的keepAliveMs、永远用常量,同样全绿:因为 boot 是唯一调用方且传的正是那个常量。这正是EnsureOptions比实际用法更宽的代价:timeoutMs和skipKeepAlivePreheat没有任何生产调用方,HTTP 路由仍走数字重载(coordinator.ensure()),所以对象形态的 skip 分支在生产里目前不可达。
关于"诊断能不能被运维看到":daemonLog 的每条 INFO/WARN 都会同时 tee 到 stderr 和日志文件,我抓到的 daemon stderr 里确实有这些行——第 5 轮的诊断是能到达运维的(早几轮的 debugLogger 则不能)。但这些 skip 分支在真 daemon 里几乎跑不到:关停竞态下先失败的是 preheat 本身(于是根本不会调度),而且 daemon 收到 SIGTERM 后约 100 ms 就退出了。它们是防御性的,不是可观测的。
6. 门禁
合并树 npm run build 通过(会一起编译测试文件,所以上一轮那条 ChannelWorkerSnapshot mock 类型 Critical 在这个 head 上已经不存在);fast-path.test.ts 的 import 边界用例 95 个全过(禁止导入那条 Critical 已解决);run-qwen-serve.test.ts 401 过、workspace-runtime-coordinator.test.ts 50 过;改动的 5 个文件 eslint + prettier 干净。
红着的 Lint & Static 不是本 PR 的问题:该 job 从 merge ref 求值,要跑 .github/scripts/check-lint-gate-freshness.mjs,这个脚本是 main 在 #11383 才加的、本分支没有,于是 14 秒就 MODULE_NOT_FOUND。把 origin/main merge(不要 rebase,否则行内评审线程会失效)进分支即可清掉。
还有一点提醒:机器人那条 serve daemon A/B 的"no response changes"不能当作"没有行为变化"的证据——它的场景集是 /health、/capabilities 和 /session/*,从不读 /workspace/runtime/status 或 /workspace/runtime/mcp,而差异恰恰全在那里。
建议(都不阻塞合并)
- 让 keep-alive 与实际工作等长:boot 的
ensure()一 resolve 就释放,或传一个与准备工作等长的窗口;避免"零 session 的 daemon 白白占着 ACP 子进程 + 所有 MCP server 十分钟",也避免盖过运维配置的--channel-idle-timeout-ms。 - 把
EnsureOptions收敛到 boot 真正用到的形状(或补上能证明这个形状的第二个调用方);若keepAliveMs保留为参数,就把?? ENSURE_KEEP_ALIVE_MS这条回退钉住——M10 说明目前没有任何测试覆盖它。 - 可选:给失败
.catch的守卫补一个测试(M6)。
|
Thanks @wenshao for the thorough real-daemon A/B verification — really helpful measurements on the keep-alive cost and the readers that actually see the gap. I will merge into this branch (not rebase) so the Lint & Static freshness gate clears and the inline review threads stay attached. Happy to follow up separately on sizing the boot keep-alive to the ensure work and trimming unused fields if you want those as a follow-up PR. |
|
Correction: I will merge |
|
Merged into this branch at (merge, not rebase) so the Lint & Static freshness script from #11383 is present and inline review threads stay attached. |
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Reviewed.
1 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- R7-9 in-catch suppression guard has no test that reddens on deletion (packages/cli/src/serve/run-qwen-serve.ts:9028) — already reported (round 6 deferral paragraph, review 5151900796)
Not explored to full depth (tool budget reached): "agent 1e": none — I did not run the vitest suites ( run-qwen-serve.test.ts , workspace-runtime-coordinator.test.ts ), so the reachability conclusion for skipKeepAlivePre…; "agent 6a": did not trace the trust hot-reload reconciler ( run-qwen-serve.ts:7749-7790 , :7912-7932 ) far enough to rule out a window where trust is revoked while the boo….
Test Plan (not a blocker): 18 passed — this review observed 29674 passed.
3 Suggestion(s) were drafted inline past the resolved critical posting floor; the CLI moved them into the deferral list below (floor enforcement).
Deferred under the convergence posture (round 7, not a blocker) — recorded, not requested in this round:
packages/cli/src/serve/fast-path.test.ts:517 — [review] The core-barrel entry this diff adds lands in a test whose title and failure message both say "ACP runtime". The enclosing test is keeps the runQwenServe static source graph free of A…packages/cli/src/serve/fast-path.test.ts:520 — [review] This filter matches by exact specifier equality, so the entry added just above it is escapable by one legal spelling of the same barrel. packages/core/package.json publishes "./*": …packages/cli/src/serve/workspace-runtime-coordinator.ts:212 — [review] keepAliveMs is documented as a duration but is only ever pinned with its own default: every assertion that exercises it feeds in ENSURE_KEEP_ALIVE_MS and expects EN…
中文说明
已审查。
本轮确认的 1 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未探索到全部深度(达到工具调用预算):"agent 1e":none — I did not run the vitest suites ( run-qwen-serve.test.ts , workspace-runtime-coordinator.test.ts ), so the reachability conclusion for skipKeepAlivePre…;"agent 6a":did not trace the trust hot-reload reconciler ( run-qwen-serve.ts:7749-7790 , :7912-7932 ) far enough to rule out a window where trust is revoked while the boo…。
Test Plan(非阻断):18 passed — this review observed 29674 passed。
3 条 Suggestion 在已解析的 critical 发布下限之外被起草为行内评论;CLI 已将其移入下方延后清单(下限强制执行)。
收敛姿态下延后(第 7 轮,非阻断)——已记录,本轮不要求修改:共 3 条(原文未翻译,列表见上方英文部分)。
— qwen3.8-max via Qwen Code /review (v0.23.2)
Maintainer verification, second pass — current head
|
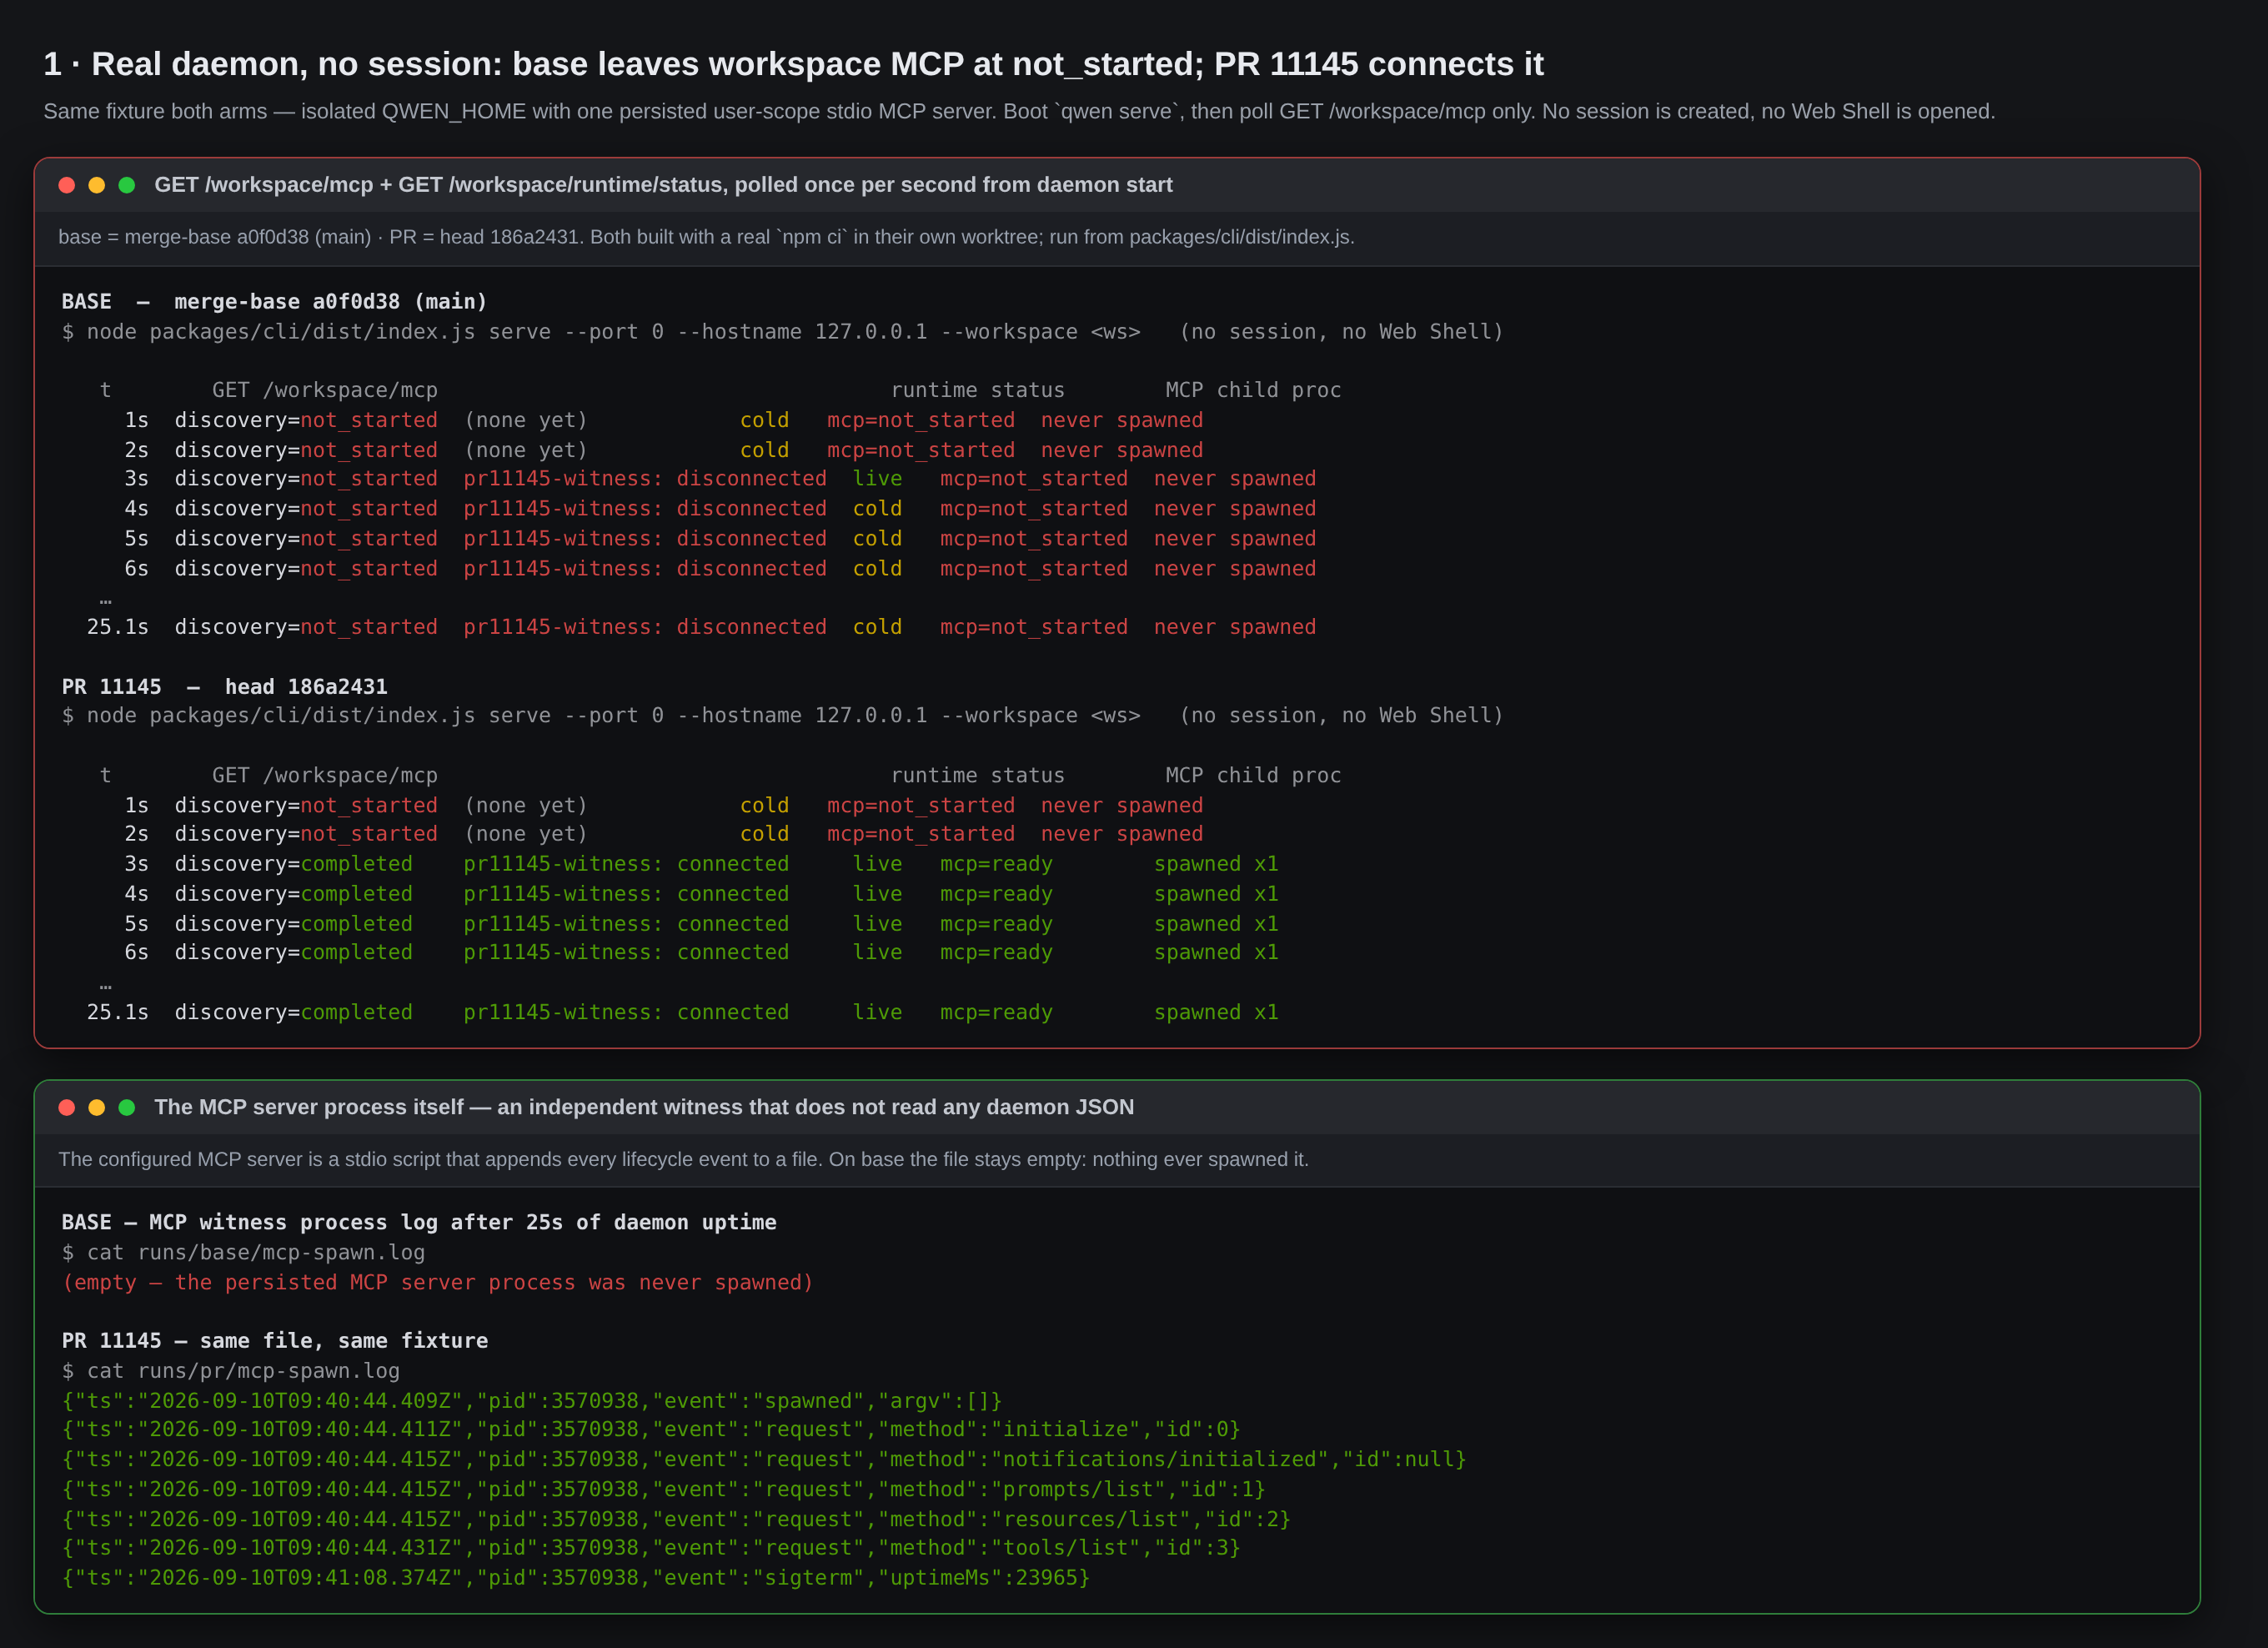
| after boot, no session | base a0f0d38 |
PR 186a2431 |
|---|---|---|
discoveryState |
not_started for the whole 25 s |
completed at t≈3.0 s |
| server entry | status: error, mcpStatus: disconnected |
status: ok, mcpStatus: connected |
capabilities.mcp.state |
not_started |
ready |
| MCP server process | never spawned (log file empty) | spawned; answered initialize, prompts/list, resources/list, tools/list |
Same result as pass 1, on a different OS and Node major. processToListenMs is unchanged (702 ms base / 750 ms PR) — the boot ensure is fire-and-forget after preheat and does not sit in the listen path.
2. New — with a session running, base's workspace-scope status is still not_started
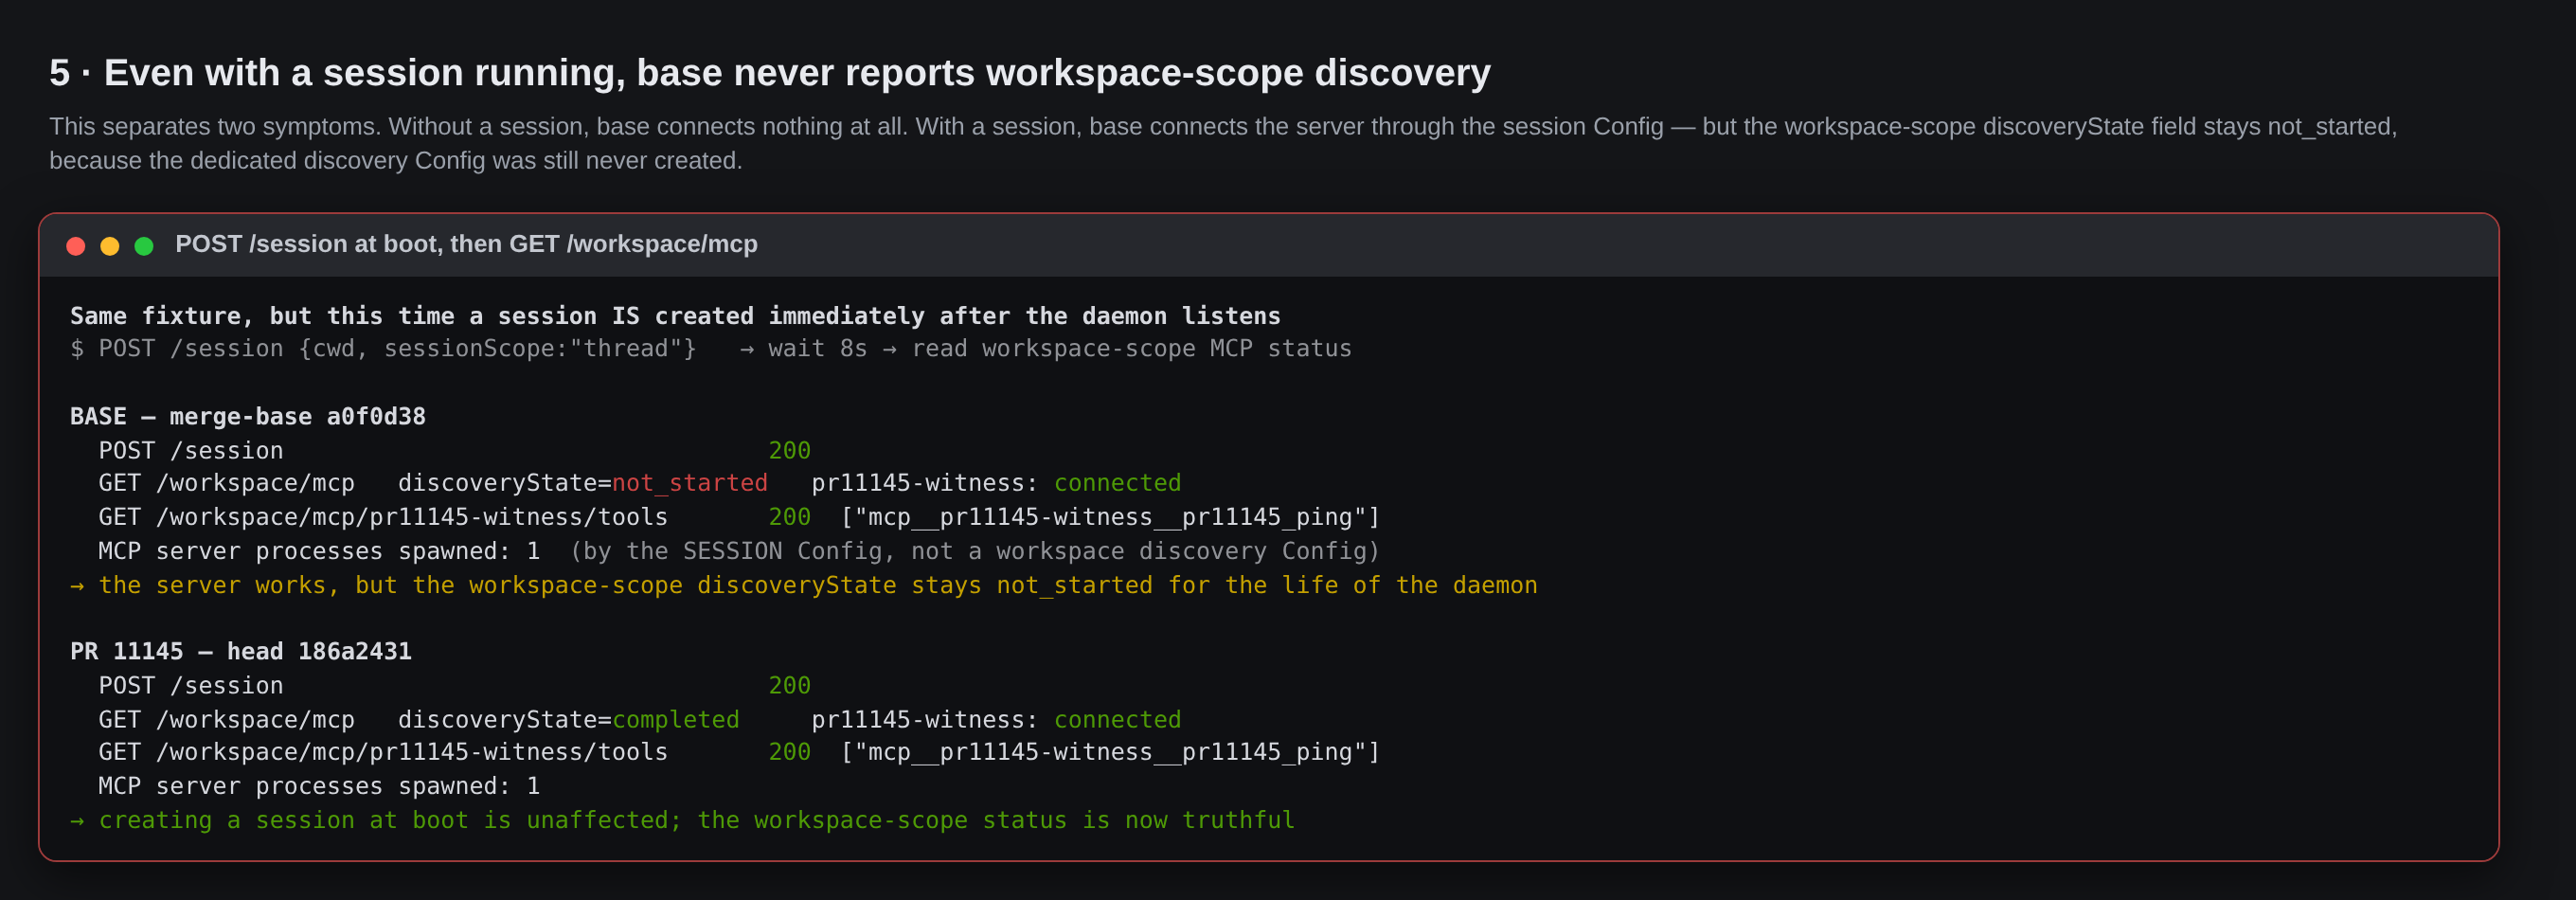
Pass 1 only covered the no-session window. Repeating with POST /session {cwd, sessionScope:"thread"} fired immediately after listen separates two symptoms:
- On base, the session Config does spawn and connect the server —
GET /workspace/mcp/<name>/toolsreturns["mcp__pr11145-witness__pr11145_ping"]. But the workspace-scopediscoveryStateis stillnot_started, because the dedicated discovery Config was never created. - On PR, the same request returns the same tool, and
discoveryStateiscompleted.
This sharpens the "who actually sees the gap" point from pass 1: on main the field is not merely late, it is wrong for as long as no HTTP ensure/reconcile path runs — even while MCP tools are demonstrably working inside sessions. Creating a session at boot is otherwise unaffected by the change (200 on both arms).
3. Re-measured cost, this time from the MCP server's own clock
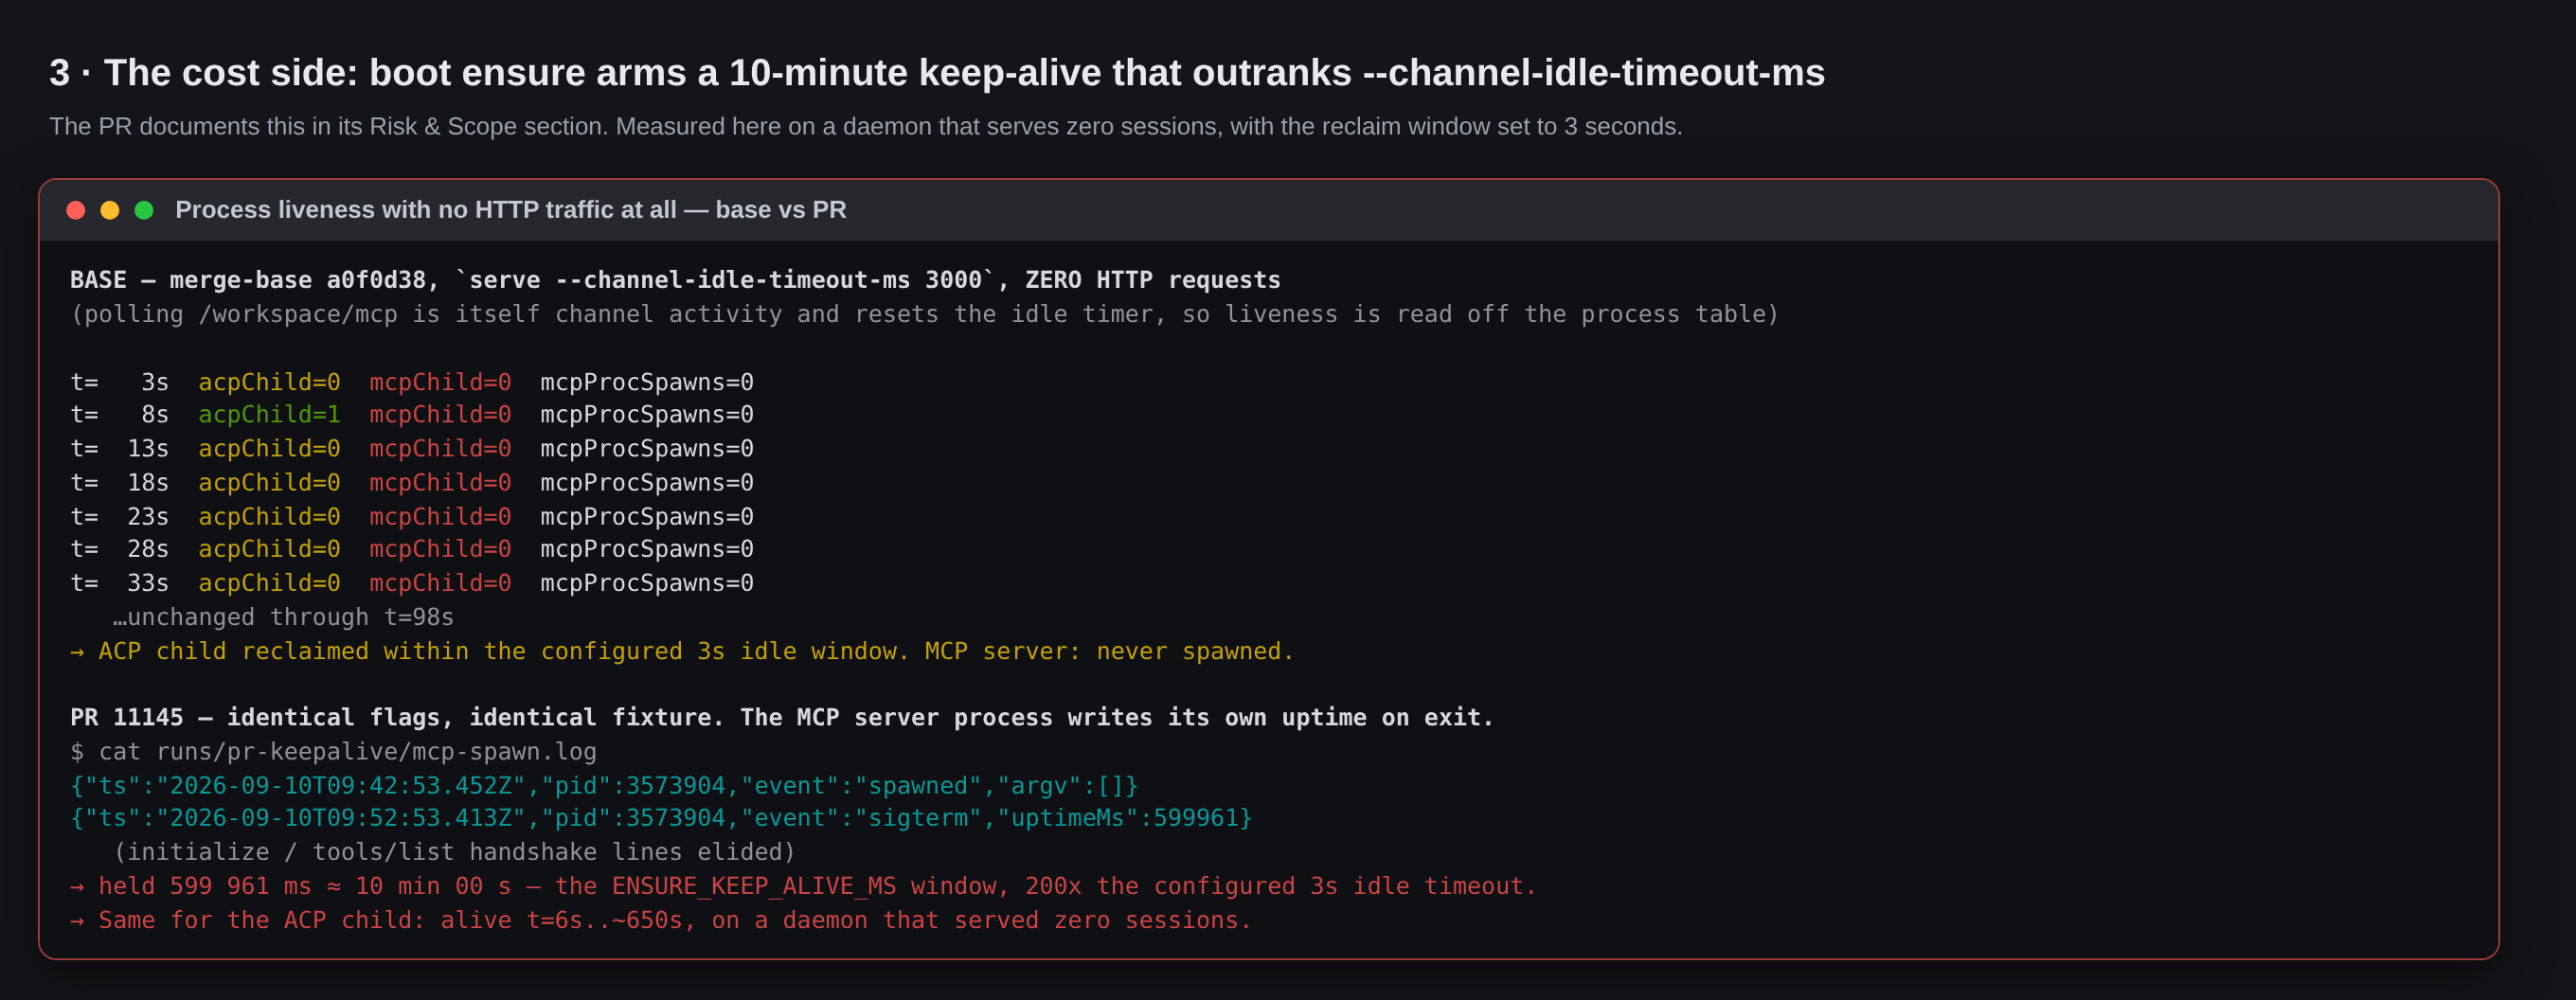
Both arms started with --channel-idle-timeout-ms 3000, zero sessions, and zero HTTP requests — polling /workspace/mcp is itself channel activity and resets the idle timer, which silently masks the reclaim behaviour, so liveness is read off the process table instead.
- base: ACP child alive at t=8 s, gone by t=13 s — reclaimed inside the configured 3 s window. MCP server never spawned.
- PR: the MCP server process records its own lifetime on exit — spawned
09:42:53.452Z,SIGTERM09:52:53.413Z,uptimeMs: 599961. Held for 10 min 00 s, i.e. 200× the configured idle timeout, on a daemon that served nothing.
That corroborates pass 1's +603.9 s ACP-child figure from the other side of the pipe, and confirms the hold covers every configured MCP server process, not just the ACP child. The trade is the one Risk & Scope already discloses.
4. New — a broken MCP server does not stall boot or take the daemon down
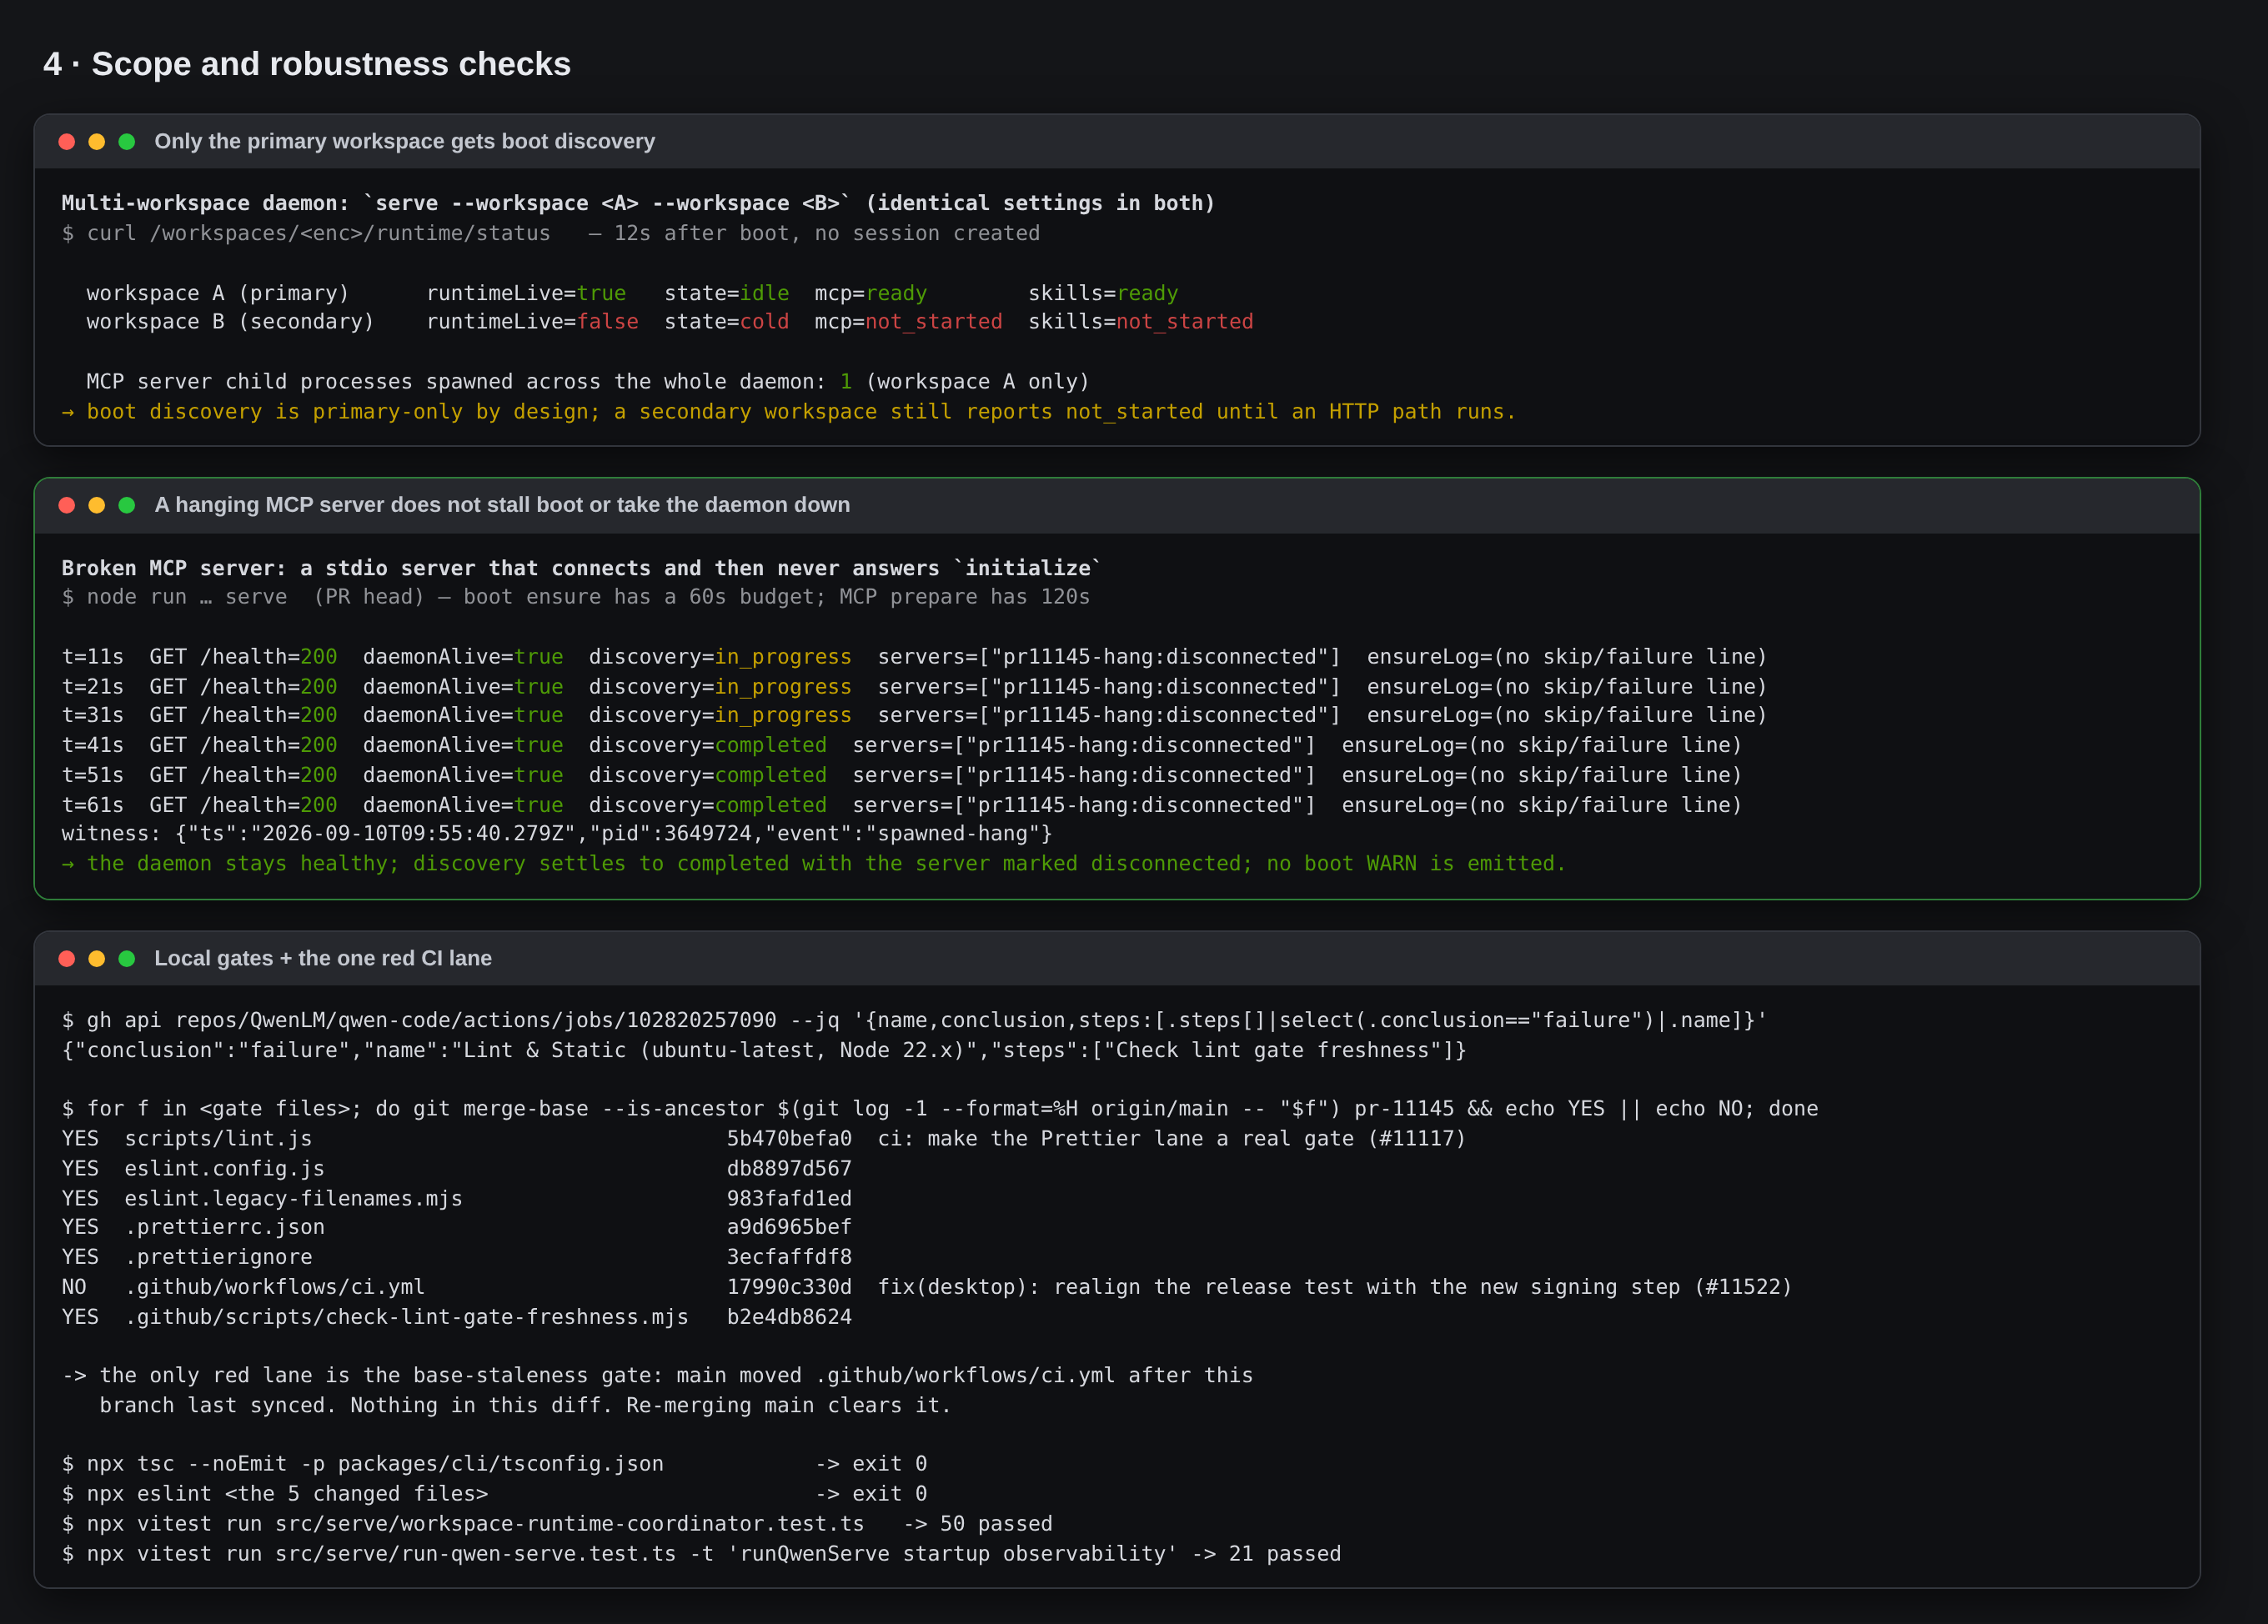
Swapped the witness for a stdio server that connects and then never answers initialize — the case that would expose boot ensure's 60 s budget as an operator-visible failure:
GET /healthstays200throughout; the daemon process never exits.discoveryStatesits atin_progressfor ~35 s, then settles tocompletedwith the serverdisconnected.- No
workspace runtime ensure after preheat failed/skippedline is emitted — boot ensure resolves inside its budget rather than logging a spurious warning.
The same figure re-confirms scope: with --workspace A --workspace B, at boot+12 s the secondary is state: cold, mcp: not_started, skills: not_started, and exactly 1 MCP process exists daemon-wide. Primary-only, as described.
5. Test A/B and two mutations pass 1 did not run
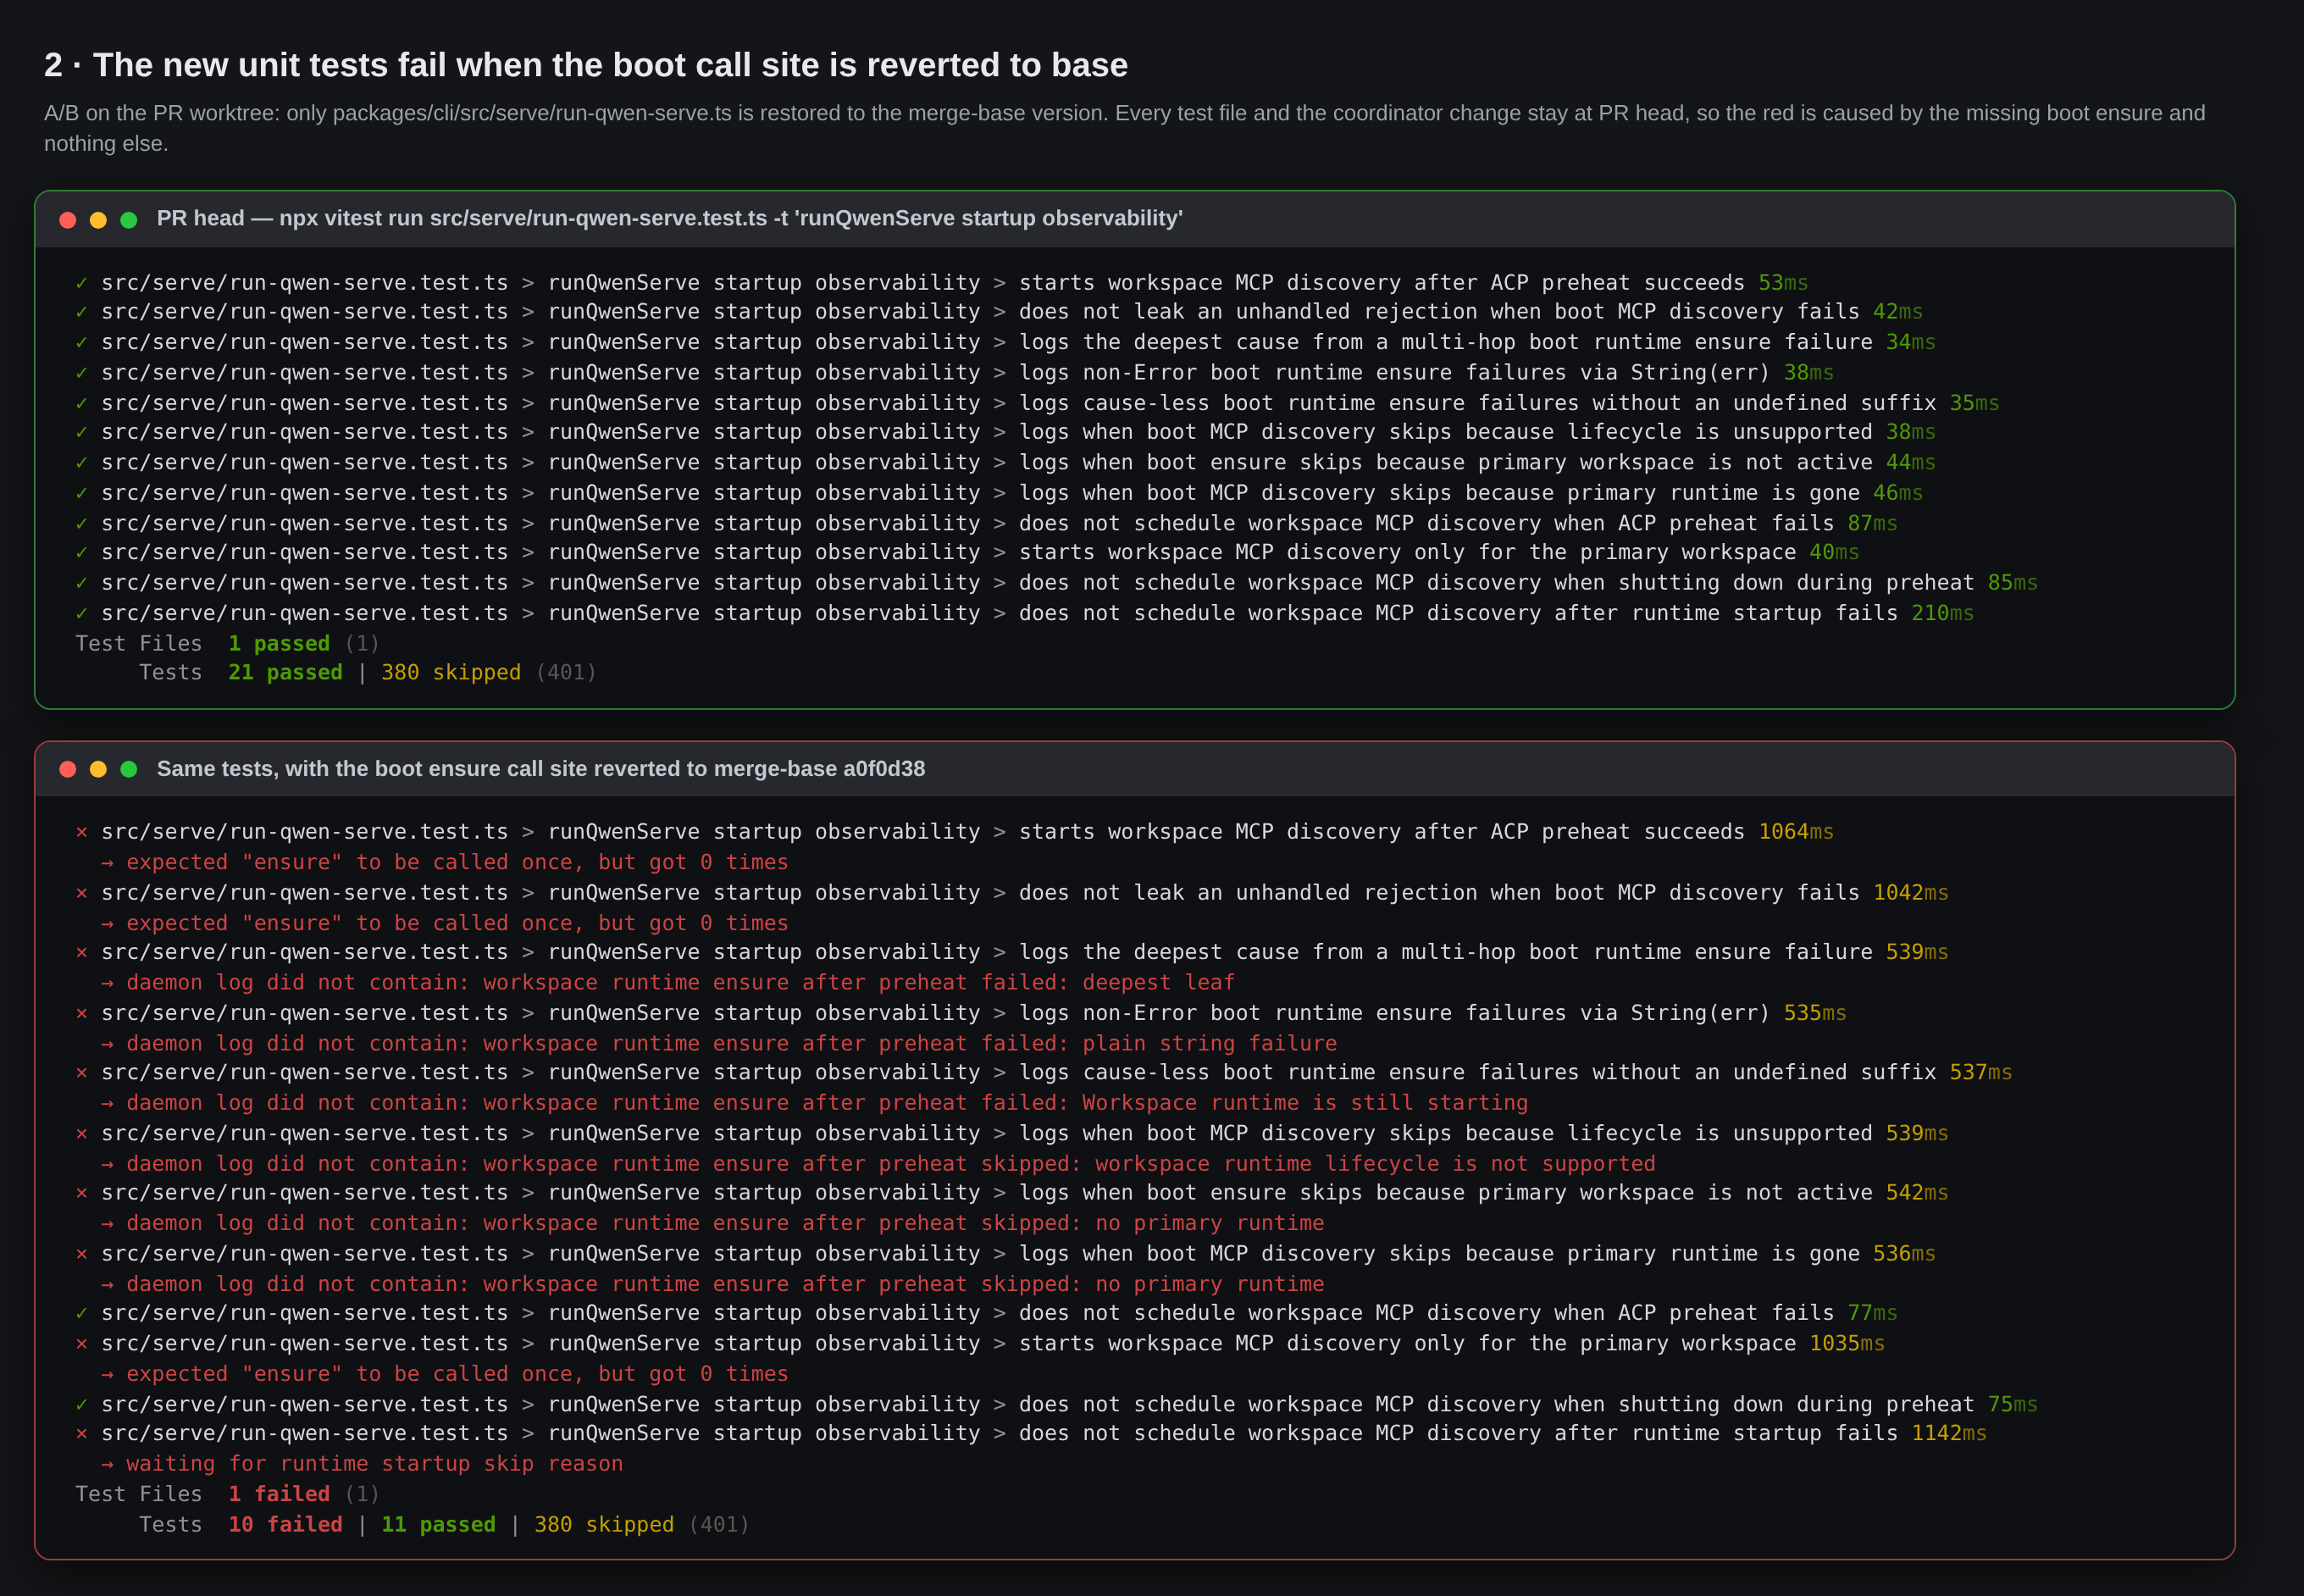
Reverting only packages/cli/src/serve/run-qwen-serve.ts to a0f0d38 (all test files and the coordinator change stay at PR head): 10 of the 12 new run-qwen-serve.test.ts cases go red. The two that stay green are the negative guards (does not schedule … when ACP preheat fails, … when shutting down during preheat) — expected, they cannot fail in the absence of the feature. Forcing skipKeepAlivePreheat = false in the coordinator reddens 4 of the 6 new coordinator cases.
Two mutations aimed at the design decisions in this diff, both pinned:
- Duplicated constant.
run-qwen-serve.tsredeclaresENSURE_KEEP_ALIVE_MS = 10 * 60_000locally rather than importing it, with a "must match" comment. Changing the local literal to9 * 60_000failsstarts workspace MCP discovery after ACP preheat succeedswithexpected "ensure" to be called with [ { keepAliveMs: 600000 } ]— because the test imports the coordinator's exported constant. Drift between the two is caught. - Import boundary. Adding a static
import { ENSURE_KEEP_ALIVE_MS } from './workspace-runtime-coordinator.js'torun-qwen-serve.tsfailsfast-path.test.ts > keeps the runQwenServe static source graph free of ACP runtime modules. The reason the constant is duplicated is enforced by a test, not just by a comment.
Local gates on this head: tsc --noEmit -p packages/cli exit 0; eslint on the 5 changed files exit 0; workspace-runtime-coordinator.test.ts 50 pass; run-qwen-serve.test.ts -t 'runQwenServe startup observability' 21 pass (the PR body's Environment block still says 18 — worth refreshing).
6. The red lane — different cause than last time
Last pass, Lint & Static died with MODULE_NOT_FOUND because the branch predated #11383. That cause is gone — .github/scripts/check-lint-gate-freshness.mjs is present at 186a2431, so the step can no longer fail on a missing module. The job's step list confirms steps 1–7 pass and step 8 Check lint gate freshness is the only failure. (The workflow run was still in progress, so its log is not retrievable yet.) Running the script's own containment check locally identifies the stale file — main moved a gate-defining file after the branch's last sync:
NO .github/workflows/ci.yml 17990c330d fix(desktop): realign the release test with the new signing step (#11522)
All six other gate files are contained in the branch. Nothing in this diff. Re-merging main clears it — but note this will keep re-reddening on a repo merging at this rate; it is worth landing this soon after a sync rather than treating the red as actionable. (Test (ubuntu-latest, Node 22.x) was still in progress when I wrote this.)
Standing follow-ups — still open, still non-blocking
Re-confirmed at this head: there are exactly two coordinator.ensure() call sites in production — routes/workspace-runtime.ts:64 (ensure(), numeric path) and the new boot call (ensure({ keepAliveMs })). Neither can reach the object-form skip branch, so EnsureOptions.skipKeepAlivePreheat and timeoutMs remain unreachable in the shipped daemon, exactly as pass 1's M10 found. My ranking is unchanged:
- Size the keep-alive to the work — release it when the boot
ensure()resolves, so a daemon that serves nothing does not hold an ACP child plus one process per configured MCP server for a flat 10 minutes, and does not override a configured--channel-idle-timeout-ms. - Trim
EnsureOptionsto what boot actually uses, or add the second caller that justifies the shape. - Optional: a test for the failure-
.catchguard (pass 1's surviving M6).
Verdict
Every claim in the description that I could drive holds on Linux/Node 22 as it did on macOS/Node 24, the new evidence in §2 makes the case slightly stronger than the description does, and §4 closes the "what if an MCP server misbehaves at boot" question. Mergeable from my side; the keep-alive sizing is a product call, not a correctness one.
中文版(合并参考)
维护者验证 · 第二轮 —— 当前 head 186a2431,Linux / Node 22
接上一轮(macOS 15.6 / Node 24,head 736c673)。本 PR 对这五个文件的实际改动在两个 head 之间逐字节相同(各自对自己的 merge-base 取 diff,两份补丁完全一致)——186a2431 只是 merge 了 main——所以这一轮是跨平台复核 + 上一轮没跑的四项新检查。结论不变:merge-base 上问题确实复现,本 PR 确实修好,没有阻塞缺陷,唯一红的是分支落后。
装置(与上一轮的差异)
- 两个独立 worktree,各自真实
npm ci:base = 本分支自己的 merge-basea0f0d38,PR = head186a2431;都用packages/cli/dist/index.js起 daemon。臂身份在产物里核过:workspace runtime ensure after preheat在 PRdist出现 5 次、base 0 次。 - Linux 6.12 / Node 22.22.2(上一轮是 macOS / Node 24)。
- 持久化一个会把每次被拉起、每条 JSON-RPC 都记流水账的 stdio MCP server,"discovery 到底连上没有"由服务端进程判定,而不是看 daemon 自己的状态字段。
- 一条值得记下的装置坑:我最初把 server 放在 workspace 的
.qwen/settings.json。这个 scope 在 Add project-scoped .mcp.json support with pending approval semantics #4615 的审批门后面,于是两臂都返回approvalState: "pending"/mcpStatus: "disconnected",进程根本不会被拉起——这会把本 PR 的效果整个掩盖成假阴性。必须放在用户级(不受门控),连接才能成为可观测量。
1. 复核:缺口与修复(图 1)
启动后每秒拉一次 GET /workspace/mcp,不建 session、不开 Web Shell:base 全程 discoveryState: not_started、server 是 error/disconnected、capabilities.mcp.state: not_started、MCP 进程从未被拉起;PR 在 t≈3.0 s 变为 completed / connected / ready,MCP 进程被拉起并完整回了 initialize、prompts/list、resources/list、tools/list。与上一轮在不同 OS 和 Node 大版本上结果一致。processToListenMs 无变化(base 702 ms / PR 750 ms)——boot ensure 是 preheat 之后 fire-and-forget,不在 listen 路径上。
2. 新增:即使有 session 在跑,base 的 workspace 级状态依然是 not_started(图 5)
上一轮只覆盖了"无 session"窗口。这次在 daemon listen 后立刻 POST /session {cwd, sessionScope:"thread"},把两个症状分开了:
- base:session Config 确实会把 server 拉起并连上——
GET /workspace/mcp/<name>/tools返回["mcp__pr11145-witness__pr11145_ping"]。但 workspace 级discoveryState仍是not_started,因为专用 discovery Config 从未被创建。 - PR:同一个请求返回同一个工具,且
discoveryState为completed。
这把上一轮"谁真正看得见缺口"的结论收得更紧:在 main 上这个字段不只是"晚",而是只要没有 HTTP ensure/reconcile 跑过就一直是错的——哪怕 session 里的 MCP 工具明明在正常工作。除此之外,启动即建 session 不受本改动影响(两臂都 200)。
3. 代价复测,这次从 MCP server 自己的时钟读(图 3)
两臂都带 --channel-idle-timeout-ms 3000、零 session、零 HTTP 请求——轮询 /workspace/mcp 本身就是 channel 活动、会重置 idle 计时器,从而悄悄掩盖回收行为,所以改用进程表读存活。
- base:ACP 子进程 t=8 s 在、t=13 s 已消失——在配置的 3 秒窗口内被回收;MCP server 从未被拉起。
- PR:MCP server 进程在退出时记下自己的寿命——
09:42:53.452Z拉起,09:52:53.413Z收到SIGTERM,uptimeMs: 599961。整整 10 分 00 秒,是配置 idle 超时的 200 倍,而这个 daemon 一个 session 都没服务。
这从管道另一端印证了上一轮 +603.9 s 的 ACP 子进程数字,并确认这个 hold 覆盖的是每一个配置的 MCP server 进程,不只是 ACP 子进程。这个取舍 Risk & Scope 已经如实披露。
4. 新增:坏掉的 MCP server 不会卡住启动,也不会拖垮 daemon(图 4)
把 witness 换成一个"连上之后永不回应 initialize"的 stdio server——这正是最可能把 boot ensure 的 60 秒预算暴露成运维可见故障的场景:
GET /health全程200,daemon 进程从未退出。discoveryState在in_progress停留约 35 s,随后落到completed,server 标记disconnected。- 没有任何
workspace runtime ensure after preheat failed/skipped日志——boot ensure 在预算内正常返回,不会打出吓人的告警。
同一张图复核了作用域:--workspace A --workspace B 时,boot+12 s 的 secondary 仍是 cold / not_started / not_started,全 daemon 只有 1 个 MCP 进程。只覆盖 primary,与描述一致。
5. 测试 A/B,以及上一轮没做的两个变异(图 2)
只把 packages/cli/src/serve/run-qwen-serve.ts 回退到 a0f0d38(所有测试文件和 coordinator 改动都留在 PR head):12 个新增用例里 10 个变红。保持绿的两个是否定式守卫(does not schedule … when ACP preheat fails、… when shutting down during preheat)——符合预期,没有该特性时它们本来就不可能失败。把 coordinator 的 skipKeepAlivePreheat 强制为 false,6 个新增 coordinator 用例红 4 个。
针对本 diff 两个设计决策的变异,都被钉住了:
- 重复常量:
run-qwen-serve.ts本地重新声明了ENSURE_KEEP_ALIVE_MS = 10 * 60_000(带 "must match" 注释)而不是 import。把本地字面量改成9 * 60_000,starts workspace MCP discovery after ACP preheat succeeds会以expected "ensure" to be called with [ { keepAliveMs: 600000 } ]失败——因为测试 import 的是 coordinator 导出的那个常量。两处漂移能被抓到。 - 导入边界:在
run-qwen-serve.ts里加一条静态import { ENSURE_KEEP_ALIVE_MS } from './workspace-runtime-coordinator.js',fast-path.test.ts > keeps the runQwenServe static source graph free of ACP runtime modules会失败。"为什么要复制常量而不是 import"是被测试强制的,不只是注释。
本地门禁:tsc --noEmit -p packages/cli exit 0;改动的 5 个文件 eslint exit 0;workspace-runtime-coordinator.test.ts 50 过;run-qwen-serve.test.ts -t 'runQwenServe startup observability' 21 过(PR 描述的 Environment 段还写着 18,可以顺手更新)。
6. 红着的那条 lane —— 与上次原因不同
上一轮 Lint & Static 是因为分支早于 #11383 而 MODULE_NOT_FOUND。这个原因已经消失——.github/scripts/check-lint-gate-freshness.mjs 在 186a2431 上已存在,该步骤不可能再因缺模块而失败。job 的 step 列表显示第 1–7 步全过、第 8 步 Check lint gate freshness 是唯一失败项。(该 workflow run 当时仍在进行中,日志还取不到。)在本地跑一遍该脚本的包含性判定,可以定位到落后的那个文件——分支上次同步之后 main 又动了一个 gate 文件:
NO .github/workflows/ci.yml 17990c330d fix(desktop): realign the release test with the new signing step (#11522)
其余六个 gate 文件分支都已包含。与本 diff 无关。再 merge 一次 main 即可清掉——但请注意在这个合并速率下它会反复变红,与其把这条红当作待办,不如同步完就尽快合。(写这条评论时 Test (ubuntu-latest, Node 22.x) 仍在跑。)
仍然开着的后续项(都不阻塞)
在这个 head 上复核过:生产里 coordinator.ensure() 只有两个调用点——routes/workspace-runtime.ts:64(ensure(),走数字重载)和新增的 boot 调用(ensure({ keepAliveMs }))。两者都到不了对象形态的 skip 分支,所以 EnsureOptions.skipKeepAlivePreheat 和 timeoutMs 在已发布的 daemon 里不可达,与上一轮 M10 的结论一致。排序不变:
- 让 keep-alive 与实际工作等长——boot 的
ensure()一 resolve 就释放,避免零 session 的 daemon 白占一个 ACP 子进程外加每个配置的 MCP server 一个进程整整十分钟,也避免盖过运维配置的--channel-idle-timeout-ms。 - 把
EnsureOptions收敛到 boot 真正用到的形状,或补上能证明这个形状的第二个调用方。 - 可选:给失败
.catch的守卫补测试(上一轮存活的 M6)。
结论
描述里我能驱动到的每一条,在 Linux/Node 22 上与 macOS/Node 24 表现一致;§2 的新证据让理由比描述本身还更强一点;§4 关掉了"启动时 MCP server 行为异常怎么办"这个问题。从我这边可以合并;keep-alive 的窗口大小是产品取舍,不是正确性问题。


 doudouOUC
left a comment
doudouOUC
left a comment
There was a problem hiding this comment.
Reviewed at d515b9a. This is an approval, so I want to show the work rather than just assert it — there are four Criticals still marked unresolved on this PR, and I checked each one against the code as it actually stands at this commit.
All four are fixed; three of them are stale anchors rather than live findings.
- The
createDebugLoggermisuse and thebridgeErrorshandling are both simply gone fromrun-qwen-serve.tsat this SHA — I grepped the whole file, neither symbol appears. WorkspaceDrainingErroris likewise absent. Note that this also makes the corresponding claim in the PR description stale; worth trimming the body so a future reader is not sent looking for it.- The typecheck failure in
run-qwen-serve.test.tsis fixed: thesnapshotmock is now annotatedvi.fn((): ChannelWorkerSnapshot => ({ enabled: true, ... })).
Both security concerns raised earlier provably do not occur.
The one that mattered most was whether workspace MCP discovery could mutate or leak into the bootstrap Config. It cannot: createWorkspaceMcpDiscoveryConfig in acpAgent.ts builds a separate Config via loadCliConfig, attaches the transport pool to that instance, initializes it with skipMcpDiscovery: true, and runs incremental discovery against it. The bootstrap Config is never touched.
The trust gate also holds at boot — run-qwen-serve.ts clears shouldPreheat when the workspace is untrusted, before anything preheats, and the discovery helper throws rather than proceeding when discovery does not start ("The workspace may not be trusted.").
The reordering itself is coherent. Boot passes an explicit keepAliveMs into .ensure(...), and the skipKeepAlivePreheat computation in workspace-runtime-coordinator.ts only takes the skip branch when keepAliveMs === undefined, so the boot path still arms preheat as intended.
One Suggestion, non-blocking: EnsureOptions.skipKeepAlivePreheat has no importer anywhere outside this file — every caller reaches it through the ?? typeof timeoutMsOrOptions !== 'number' default. It is a dead switch today. Benign because the default reproduces the previous behavior exactly, but if nothing is going to set it, dropping the option would be simpler than keeping a knob nobody turns.
On the core gate: it does not apply. All five changed files are under packages/cli/src/serve/** plus the ACP integration in the same package — no packages/core and no cross-package surface.
CI is green on d515b9a. Note on method: I could not run tests locally (the worktree lacks node_modules/packages/cli's built dependencies, and the vitest globalSetup guard stops runs until npm run build from the repo root), so the above is read-verified against this exact commit plus CI on the same SHA.
LGTM — approving. Please squash the stale WorkspaceDrainingError sentence out of the description before merge.

Independent e2e verification at
|
head d515b9a (this PR) |
base 424e40cc1f (revert control) |
|
|---|---|---|
| source in tree, witnessed before start | matches head, new symbol ×2 | matches base, new symbol ×0 |
| process executing the PR tree | yes | yes |
/health 200 |
2.0 s | 2.0 s |
runtimeLive at window end |
true | true |
| probe MCP server spawned inside the window | 10.7 s | never |
| probe log lines at window end | 12 — initialize → notifications/initialized → prompts/list → resources/list → tools/list |
0 |
capabilities.mcp.state at window end |
ready | not_started |
the same, after an explicit POST /workspace/runtime/ensure |
ready (unchanged) | ready, probe then spawns with the identical 12-message handshake |
What this establishes:
- The fix executes on the real boot path. MCP discovery completes ~10 s after the daemon starts serving, with no client asking for it. The spawn is downstream of
scheduleWorkspaceMcpDiscoveryAfterPreheat, which is only reachable from preheat's.then()— so it is positive evidence that preheat succeeded, not merely an absence of theACP preheat failedline. - The control excludes the two alternative explanations. A live runtime is not sufficient (control:
runtimeLive=true,mcp=not_started, zero probe traffic), and my status polling is not the trigger (identical polling, identical unchanged route code, no discovery in the control). - The control's empty window is not a broken MCP config. The same config loads on demand in the control and produces a byte-comparable handshake, so the measured difference is when discovery happens — precisely what this PR claims to change. A control that could not differ would have proved nothing; this one differed on the axis under test and on no other.
- No skip branch fired: zero
workspace runtime ensure after preheat skippedlines and zero… ensure after preheat failedlines in the head arm.
Code review at this head — no Critical found
Production coverage is file-complete (2 of 2 production files, read from head bytes, all hunks accounted for against the API's own +913/-15). The three test files are not covered by that claim beyond the roles named below.
- The new object-form default cannot silently change an existing caller. Every
.ensure(site was enumerated: the only coordinator caller isroutes/workspace-runtime.ts:64,await coordinator.ensure()— no argument, sotypeof timeoutMsOrOptions === 'number'holds and the skip branch is unreachable, i.e. its behavior is unchanged. This PR's boot call is the sole object-form caller and it passeskeepAliveMs, which also forces the preheat. This independently corroborates the dead-switch observation already filed here as a non-blocking Suggestion:skipKeepAlivePreheathas no setter and its default reproduces prior behavior exactly, so it is inert rather than wrong, and I am not raising it. - The ordering the fix depends on holds.
workspaceRegistryis constructed insidebuildRuntime()from the already-built runtime list (run-qwen-serve.ts:6425), andcreateEntrysetsstate: 'active'together withcurrent.runtimeat creation (workspace-registry.ts:281), so when preheat resolves theprimaryEntry.state === 'active'read at:9007does find a runtime. The access pattern matches the pre-existing one at:6506. - Preheat failure leaves MCP undiscovered at boot, which is the pre-existing behavior, is pinned by
does not schedule workspace MCP discovery when ACP preheat fails, and still tells the user it retries on first session. Not a regression. deepestErrorMessageonly fails to terminate on a self-referentialcausechain, which nothing on this path constructs; the three shapes that do occur (multi-hop, non-Error, cause-less) are each pinned by a test.- The duplicated
ENSURE_KEEP_ALIVE_MS(re-declared in serve with a comment naming the static-import boundary, now exported from the coordinator) is a divergence risk for a future edit, not a defect at this head.
Scope and CI
Exercised: serve-mode boot, trusted single primary workspace, one stdio MCP server, both arms in the same environment. Not exercised: untrusted workspaces (shouldPreheat is cleared at :4768 before anything preheats, so the code under test is unreachable there by design), secondary/multi-workspace runtimes, HTTP-transport MCP servers, the four skip branches and the keep-alive/reap interaction (each is unit-tested instead, including reaps a live child before MCP init unless ensure arms a keep-alive hold). CI at this head: 19 product lanes success, 0 failure, 0 unfinished, with Test (macos-latest, Node 22.x), Test (windows-latest, Node 22.x) and Integration Tests (CLI, No Sandbox) skipped by event type.
Verdict, as of the state read immediately before posting: at d515b9a I found no Critical, the change demonstrably does what it says on a live daemon, and CI is green — from my side this is merge-ready. This comment carries no approval; the approval at this head is doudouOUC's, and any approval of my own would be a separate later act.
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
6 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- D8-3 dead EnsureOptions switches (skipKeepAlivePreheat and timeoutMs have no production setter; the exported type has zero importers) at packages/cli/src/serve/workspace-runtime-coordinator.ts:206 — already reported as R2-2 (comments 394505…
- D8-4 the resolved ensure() status is discarded, so a boot MCP or Skills failure logs nothing, at packages/cli/src/serve/run-qwen-serve.ts:9025 — already reported (round-4 deferral paragraph in review 5126399623, round-6 deferral paragraph i…
- D8-5 the in-catch suppression guard has no test that reddens on deletion at packages/cli/src/serve/run-qwen-serve.ts:9027 — already reported (round-6 deferral paragraph in review 5151900796, and re-noted as a duplicate in round 7, review 51…
- D8-6 one skip string flattens five distinct WorkspaceEntryState cases at packages/cli/src/serve/run-qwen-serve.ts:9010 — already reported (round-6 deferral paragraph in review 5151900796)
- D8-7 an orderly runtime teardown is logged as a boot failure on a healthy daemon at packages/cli/src/serve/run-qwen-serve.ts:9028 — already reported as R4-4 (comments 3950209763 and 3956559726, and the round-6 deferral paragraph in review 5…
- D8-8 the core-barrel blocklist entry is escapable by exact specifier equality at packages/cli/src/serve/fast-path.test.ts:517 — already reported (round-7 deferral paragraph in review 5162133331)
Not reviewed: build-and-test efficacy probe — the automated mutation / hunk-necessity harness died inside the repo's own vitest prerequisite guard (scripts/vitest-global-setup.js), so its control never ran and produced no verdict (harnessValidated: null; 3 mutants and 6 hunk probes skippedForBaseline, 0 run). The build, the unit suites, typecheck and lint all ran and are reported separately, and the gating ground was covered by a hand-run base-tree measurement instead: the three changed test files copied over the built merge base went 16 failed / 531 passed, so the new boot-discovery and keep-alive behaviour is genuinely gated.
Not explored to full depth (tool budget reached): "agent 5": none — but two verdicts are reading-based, not executed: I did not run the vitest suites, so every mutation outcome above is reasoned from the assertions and th…; "agent reverse-audit (round 2)": executed verification — every mutation verdict above is reading-based; I ran no test and no mutation, so "turns a named assertion red" is traced, not observed.; "agent reverse-audit (round 2)": publishLiveDiscovery / live/discovery.js — I confirmed it runs concurrently with the preheat chain inside completeRuntimeStartup ( run-qwen-serve.ts:8964-…; "agent reverse-audit (round 2)": sendBridgeError 's status/code mapping — not read, so I did not determine how an unwrapped throw out of ensure() renders to HTTP clients versus a wrapped Wo…; "agent reverse-audit (round 2)": docs/developers/daemon/08-session-lifecycle.md — not read (R8-11 owns it); I only confirmed via glob that docs/developers/daemon/ has no .zh-CN.md sibling….
Test Plan (not a blocker): 18 passed — this review observed 30158 passed.
1 Suggestion(s) were drafted inline past the resolved critical posting floor; the CLI moved them into the deferral list below (floor enforcement).
Deferred under the convergence posture (round 8, not a blocker) — recorded, not requested in this round:
packages/cli/src/serve/run-qwen-serve.ts:282 — [review] instanceof Error is the only type test in this walk, so a non- Error root cause stops it on the first iteration and the boot log prints the wrapper's generic constant instead of the…packages/cli/src/serve/run-qwen-serve.ts:9026 — [review] The daemon session-lifecycle doc still attributes the boot ten-minute lease to a client ensure call, so it now states the opposite of what shipspackages/cli/src/serve/run-qwen-serve.ts:9026 — [review] The published reproduction names no MCP config scope, and the scope a reviewer is likeliest to pick is behind the #4615 approval gate, so the before/after reads inert
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 6 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未审查(原文为英文):build-and-test efficacy probe — the automated mutation / hunk-necessity harness died inside the repo's own vitest prerequisite guard (scripts/vitest-global-setup.js), so its control never ran and produced no verdict (harnessValidated: null; 3 mutants and 6 hunk probes skippedForBaseline, 0 run). The build, the unit suites, typecheck and lint all ran and are reported separately, and the gating ground was covered by a hand-run base-tree measurement instead: the three changed test files copied over the built merge base went 16 failed / 531 passed, so the new boot-discovery and keep-alive behaviour is genuinely gated.
未探索到全部深度(达到工具调用预算):"agent 5":none — but two verdicts are reading-based, not executed: I did not run the vitest suites, so every mutation outcome above is reasoned from the assertions and th…;"agent reverse-audit (round 2)":executed verification — every mutation verdict above is reading-based; I ran no test and no mutation, so "turns a named assertion red" is traced, not observed.;"agent reverse-audit (round 2)":publishLiveDiscovery / live/discovery.js — I confirmed it runs concurrently with the preheat chain inside completeRuntimeStartup ( run-qwen-serve.ts:8964-…;"agent reverse-audit (round 2)":sendBridgeError 's status/code mapping — not read, so I did not determine how an unwrapped throw out of ensure() renders to HTTP clients versus a wrapped Wo…;"agent reverse-audit (round 2)":docs/developers/daemon/08-session-lifecycle.md — not read (R8-11 owns it); I only confirmed via glob that docs/developers/daemon/ has no .zh-CN.md sibling…。
Test Plan(非阻断):18 passed — this review observed 30158 passed。
1 条 Suggestion 在已解析的 critical 发布下限之外被起草为行内评论;CLI 已将其移入下方延后清单(下限强制执行)。
收敛姿态下延后(第 8 轮,非阻断)——已记录,本轮不要求修改:共 3 条(原文未翻译,列表见上方英文部分)。
— qwen3.8-max via Qwen Code /review (v0.23.2)

 qqqys
left a comment
qqqys
left a comment
There was a problem hiding this comment.
Independent verification — approval at d515b9a.
My full report is in the comment above (posted 2026-09-10T14:30:51Z at this same head). It concluded merge-ready and deliberately carried no approval; this row is that separate later act.
Re-verified from primary sources immediately before submitting, at head d515b9a7103c5316c2967c58eae8ade0f0025c3c (unmoved since the report):
- Lifecycle:
state=open,merged=false,draft=false. - CI at this head, measured in this same read: 31 check runs — 23 green, 0 failure, 0 unfinished, 8 skipped by event type (
skippedcounted as completed, not pending). Green product lanes includeTest (ubuntu-latest, Node 22.x),Lint & Static (ubuntu-latest, Node 22.x),Integration Tests (no-AK, No Sandbox),Serve A/B,web-shell E2E Smoke,TUI parity snapshots (ink vs opentui),OpenTUI no-flicker gateand bothDesktop Shelllanes. (My report 46 minutes earlier quoted a product-lane subset with a different denominator; the polarity is identical — nothing failing, nothing still running.) doudouOUC's approval is live at this head: id5167178644, submitted2026-09-10T12:40:50Z, which is after the head commit's own committer date2026-09-10T10:07:50Z— so it is genuinely anchored tod515b9aand not re-anchored onto it by a server-side base merge. That approval is read-verified against this SHA and walks all four previously-unresolved Criticals.qwen-code-ci-botround 8 (id5168585669,COMMENTED,2026-09-10T14:47:05Z, landed after my report) carries zero Criticals — its own machine ledger reads{"round":8,"findings":[],"posted":0,"floor":"c","fresh":0}, and its prose states "Advisory only: this does not affect the verdict, and nothing here is a blocker." The six findings it lists are all Suggestion-level and all already reported on this PR.
What my own report contributed beyond the existing approvals: an executed two-arm daemon A/B on a live qwen serve (fix arm vs. revert control under identical polling), which is what established that persisted MCP config is actually discovered at boot rather than only on first session — the behaviour this PR exists to change.
Scope of this approval, stated so it does not over-claim: it covers the code at d515b9a and the paths my report exercised (serve-mode boot, a trusted single primary workspace, one stdio MCP server). It does not cover untrusted workspaces (unreachable by design — shouldPreheat is cleared before anything preheats), secondary/multi-workspace runtimes, HTTP-transport MCP servers, or the four skip branches, each of which is unit-tested instead.
The bot's non-blocking Suggestions and deferred items (the dead EnsureOptions.skipKeepAlivePreheat switch, the discarded ensure() status, the one skip string flattening five WorkspaceEntryState cases, and the stale WorkspaceDrainingError sentence in the PR description) are all real and all below a merge blocker; I agree with doudouOUC that they can land as follow-ups.

8 participants


What this PR does
After ACP preheat in
qwen serve, fire-and-forgetcoordinator.ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS })on the primary workspace runtime so workspace-scope MCP discovery can start at daemon boot viaprepareMcpRevision()/initializeWorkspaceMcp(), on the separate workspace discovery Config.Primary runtime is resolved with the non-throwing
registry?.primaryEntry.current?.runtimelookup so a closed generation cannot flip a successful preheat tofailed.Why it's needed
On
main, nothing starts workspace-scope MCP discovery at daemon boot. The ACP bootstrap Config is initialized withskipMcpDiscovery: true, and the dedicated workspace discovery Config is only created from HTTP control paths /prepareMcpRevision(). Right after preheat,discoveryStatestaysnot_started.Clarification vs an earlier draft of this description: persisted MCP servers are still listed after preheat, because workspace status falls back to the bootstrap Config's
getMcpServers(). What is missing is discovery and connection state (discoveryState: 'not_started'), not an empty server list.This is not the Qwen Desktop bug in #7771 (Electron IPC /
settings.json). It only addresses the analogous boot gap in the CLIqwen servedaemon.Reviewer Test Plan
How to verify
mcpServersentry the serve daemon should know about.qwen serveand, before creating a session or opening Web Shell, fetch workspace MCP status.discoveryStateremainsnot_started(no workspace discovery Config yet).ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS })drives workspace discovery initialization on the separate discovery Config (bootstrap Config stays on the W119 skip-discovery path).Unit coverage:
packages/cli/src/serve/run-qwen-serve.test.tsassertsensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS })after successful preheat, and goes red if discovery runs on preheat failure, non-primary workspaces, shutdown, or runtime startup failure.Evidence (Before & After)
Before: successful ACP preheat left workspace MCP discovery at
not_starteduntil an HTTP ensure/reconcile path ran.After:
ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS })is scheduled after preheat using a non-throwing primary lookup; unit test asserts that call. No live daemon JSON capture in this pass (fork CI still oftenaction_requiredfor first-time contributors). N/A for TUI screenshots.Tested on
Environment (optional)
(18 passed in that describe block)
Risk & Scope
Boot calls
ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS })after a successful ACP preheat. That deliberately arms the same daemon-wide 10-minute keep-alive window the HTTPPOST /workspace/runtime/ensureroute uses, so the already-warm ACP child stays held through Skills/MCP preparation under the defaultchannelIdleTimeoutMs=0policy. A boot that serves zero sessions therefore reaps the warm child and its discovery Config at boot+10min unless a session or another keep-alive extends it; the configured--channel-idle-timeout-msreclaim does not apply inside that window becausekeepAliveUntilonly extends the effective idle timeout.Boot
ensure()also runsprepareSkills()— not MCP-only. Skip paths (shutting down,runtime startup failed, no primary runtime, unsupported lifecycle) log viadaemonLog.infoand are also teed to stderr for operator visibility. Preparation failures log viadaemonLog.warn(with deepesterr.causewhen present) and are teed to stderr. OrderlyWorkspaceDrainingErroris not treated as a discovery failure.EnsureOptions.skipKeepAlivePreheatremains for callers that pass the object form withoutkeepAliveMs; boot always passeskeepAliveMsso the skip path is not taken at startup.Linked Issues
Relates to #7771 (Desktop issue; this PR does not close it — serve-daemon analogue only)
中文说明
这个 PR 做了什么
在
qwen serve的 ACP preheat 成功后,对 primary workspace runtime fire-and-forget 调用coordinator.ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }),通过prepareMcpRevision()/initializeWorkspaceMcp()在独立的 workspace discovery Config 上启动 discovery。primary 用不会抛错的
registry?.primaryEntry.current?.runtime解析,避免 generation 已关闭时把成功的 preheat 改写成failed。为什么需要
main上守护进程启动时不会启动 workspace 级 MCP discovery:bootstrap Config 带skipMcpDiscovery: true,专用 discovery Config 只从 HTTP /prepareMcpRevision()创建。preheat 之后discoveryState仍是not_started。相对更早一版描述的澄清:持久化的 MCP server 仍会经 bootstrap Config 回落出现在列表里;缺的是 discovery/连接状态,不是空列表。
这与 #7771(Qwen Desktop)不是同一条产品路径;本 PR 只覆盖 CLI
qwen serve。评审人验证计划
如何验证
mcpServers。qwen serve,在建 session / 开 Web Shell 前拉 workspace MCP 状态。discoveryState为not_started。ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS })推动 workspace discovery 初始化;bootstrap 仍走 W119 跳过 discovery。单测断言 preheat 后调用
ensure(),mock 仅挂在本用例。证据(前后对比)
前:preheat 后 discovery 停在
not_started。后:ensure()+ 安全 primary 查找;本轮为本地单测,无真实守护进程 JSON。非 TUI。测试平台
Linux ✅;macOS/Windows N/A。
风险与范围
ensure({ keepAliveMs: ENSURE_KEEP_ALIVE_MS }),有意挂上与 HTTP ensure 相同的守护进程级 10 分钟 keep-alive。ensure()也会跑prepareSkills(),不只是 MCP。跳过路径(关闭中、runtime 启动已失败、无 primary、不支持 lifecycle)经daemonLog.info记录,并 tee 到 stderr;准备失败经daemonLog.warn(展开最深层 cause)并 tee 到 stderr。有序WorkspaceDrainingError不当作 discovery 失败告警。EnsureOptions.skipKeepAlivePreheat保留给未传keepAliveMs的对象形式调用方;boot 始终传keepAliveMs。关联 Issue
Relates to #7771(不自动关闭 Desktop issue)