Repository navigation
Update FSDP, AC, Compile ordering - #923
Merged
Merged
Conversation


mikasenghaas
force-pushed
the
sami/update_fsdp_orderring
branch
from
September 16, 2025 08:46
bd290d4 to
7d38a16
Compare
mikasenghaas
changed the title
mikasenghaas
marked this pull request as ready for review
September 16, 2025 12:43

mikasenghaas
approved these changes
Sep 16, 2025


This reverts commit 330048a.
samsja
force-pushed
the
sami/update_fsdp_orderring
branch
from
September 16, 2025 17:41
79b52a9 to
a4628dc
Compare

garrett361
added a commit
that referenced
this pull request
Oct 7, 2026

… and activation checkpointing (#3925) With `moe_router_dtype="float32"` (the RL default) and activation checkpointing on, every MoE block ran eager under `torch.compile`. Two things combine to cause it: - The fp32 router is its own FSDP2 unit, and FSDP2 hooks are dynamo-disabled, so the router always breaks the graph. - Under `compile(AC(block))` the checkpoint compiles as a higher-order op, which forbids breaks, so Dynamo ran the whole block eagerly. This PR compiles inside the checkpoint instead: for any checkpointed block that holds a nested FSDP unit (today, the fp32 router), an eager checkpoint now wraps the compiled block (`AC(compile(block))`), so the nested unit's break only splits the block into compiled graphs. To see those units, compile now runs after FSDP. Compiling in place keeps the same module object, so the order changes nothing at runtime. The reorder is safe. The old `AC -> Compile -> FSDP` comment was ported from TorchTitan in #923, when `apply_compile` still wrapped each block with `torch.compile(block)`. #957 switched to in-place `.compile()` two days later without revisiting it. With in-place compile, both orders trace the same frames: graph breaks, loss and step time match on both workloads, and `fullgraph=True` (with a bf16 router) still compiles with zero graph breaks. | Workload (8x H200, EP 8, full AC) | before (s/step) | after (s/step) | MFU | |---|---|---|---| | GLM-4.5-Air, 16 layers, real data | 6.21, 6.17 | 5.22, 5.21 | 35% to 42% | | Qwen3-30B-A3B, fake data | 5.96, 5.96 | 4.51, 4.51 | 32% to 42% | Two runs per arm, each the median `time/step` over steps 5 to 20, no offloading. Peak memory is unchanged, and loss and grad norm track the baseline within run-to-run noise. 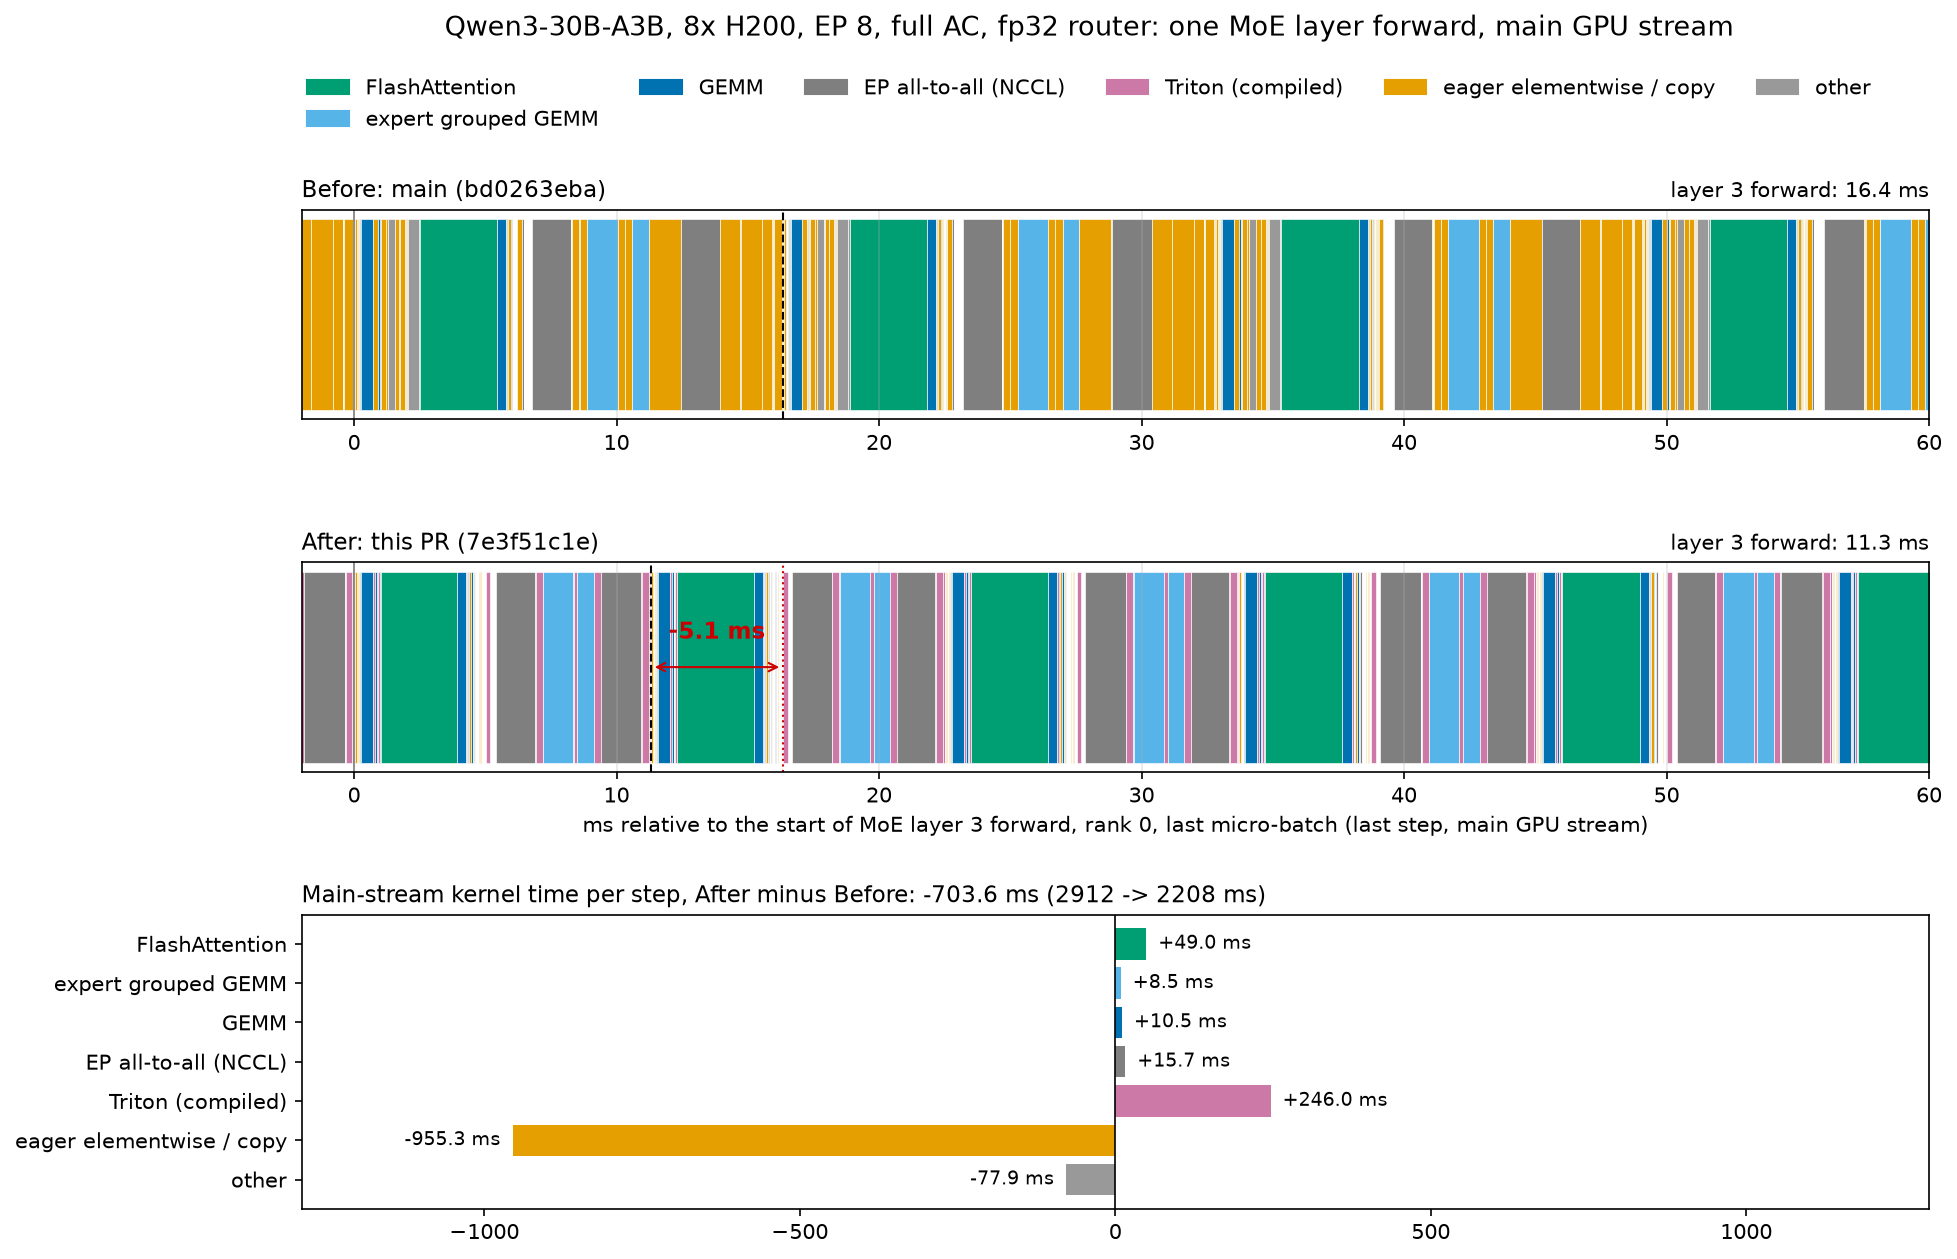 **Figure:** one MoE layer's forward on Qwen3-30B-A3B, before and after this PR. The orange eager elementwise kernels collapse into a few pink compiled Triton kernels, so the layer's forward drops from 16.4 to 11.3 ms. <details><summary>Same view on GLM-4.5-Air</summary> 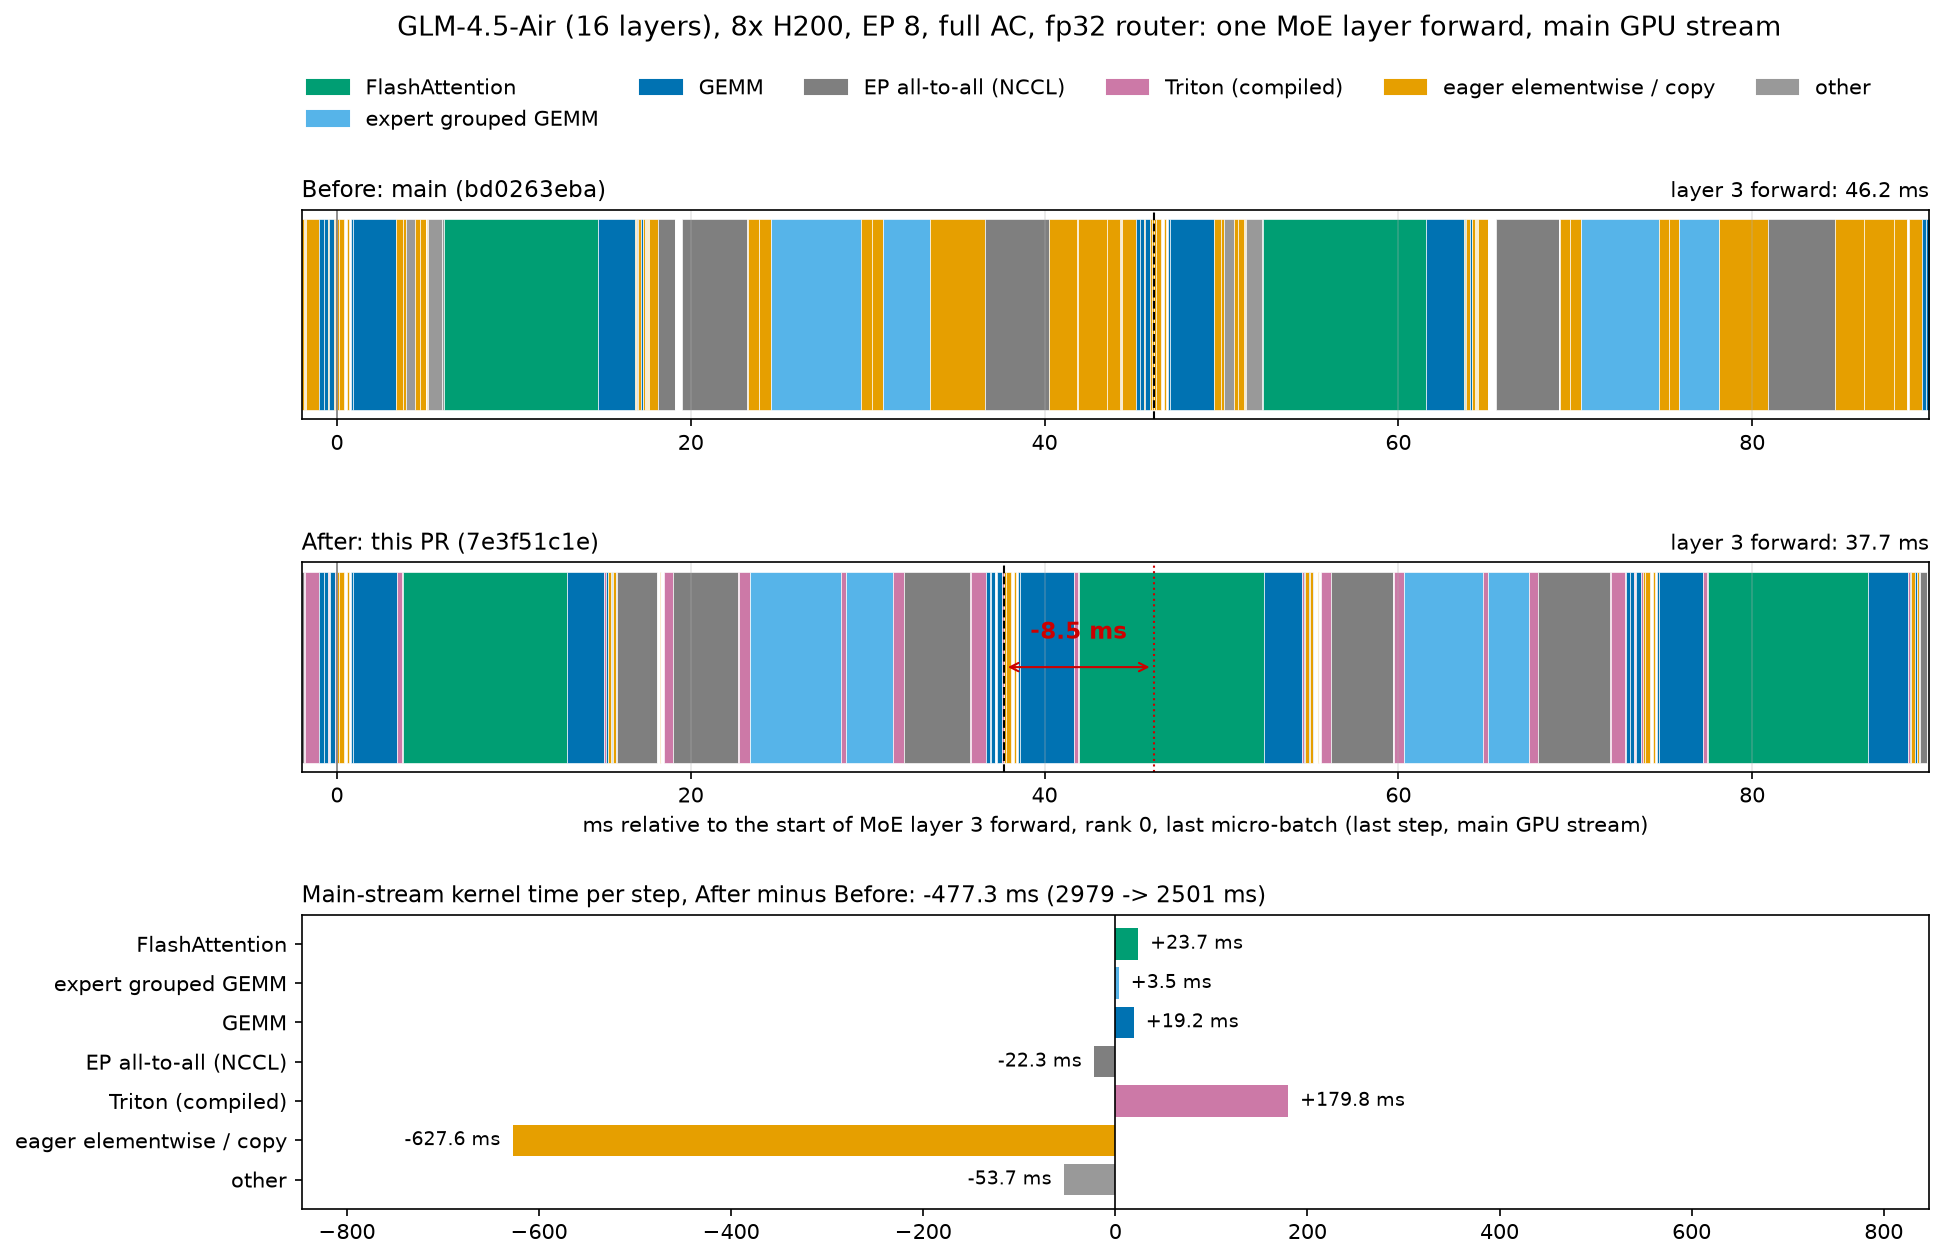 </details> ## Alternative considered Keeping recompute inside the compiler: drop the block-level checkpoint and instead checkpoint two compiled regions that exclude the router, the attention module and the post-router MoE work. It beat the baseline but was slower than this PR (Qwen3-30B 5.50 vs 4.51 s/step, GLM-4.5-Air 5.85 vs 5.22 s/step) and used more memory, because the norms and the router's fp32 activations stay outside any checkpoint. ## North star: fullgraph fp32 router support Fullgraph compile with an fp32 router stays unsupported, and `model.compile.fullgraph=true` still raises for it. The blocker is the router's FSDP unit itself: FSDP2 applies one mixed-precision policy per unit, so the fp32 router cannot share the block's bf16 unit, and its dynamo-disabled hooks are the graph break above. PyTorch [#196626](pytorch/pytorch#196626) adds per-parameter mixed precision, which lets the router stay in the block's unit. That removes the break, enables fullgraph, and makes this PR's compile-inside-AC path unnecessary, so it should be reverted then. #196626 is on PyTorch `main` but not yet in a release. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Co-authored-by: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
Sign up for free
to join this conversation on GitHub.
Already have an account?
Sign in to comment




Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.
couple of thing that I noticed are different between us and torchtitan:
they do torch compile with full graph on each transformer block https://github.com/pytorch/torchtitan/blob/40a87254ff15dbabebcfe8f70828a872cc6fa009/torchtitan/models/llama3/infra/parallelize.py#L243
they do ac - > compile -> fsdp wheras we do ac-> fsdp -> compile which could create graph break https://github.com/pytorch/torchtitan/blob/40a87254ff15dbabebcfe8f70828a872cc6fa009/torchtitan/models/llama3/infra/parallelize.py#L106
They shard explicitly the lm head and embedding, we don't, potentially meaning we don't shard this layers ? https://github.com/pytorch/torchtitan/blob/40a87254ff15dbabebcfe8f70828a872cc6fa009/torchtitan/models/llama3/infra/parallelize.py#L308
They don't to the "do not reshard after forward for the last layer" trick, which they used to do (bc we stole it from there) My guess is that it breaks full graph for torchtitan https://github.com/pytorch/torchtitan/blob/40a87254ff15dbabebcfe8f70828a872cc6fa009/torchtitan/models/llama3/infra/parallelize.py#L301
branch sami/update_fsdp_orderring
reproduce with